Score: a workload specification that describes requirements instead of platforms
The Score Specification provides a developer-centric and platform-agnostic Workload specification to improve developer productivity and experience. It eliminates configuration inconsistencies between environments.
At a glance
- What is it?
- Score is an open-source, vendor-neutral specification for stating what a workload requires, so one score.yaml can be rendered to Docker Compose or Kubernetes by separate implementations. It produces no output on its own, it deliberately does not replace a platform's own YAML, and environment-specific configuration still lives somewhere else.
- Who is it for?
- Adopt Score when the same application has to run under more than one orchestration platform and the cost you are actually paying is keeping those configurations in sync. Do not adopt it expecting one file to cover everything, since the specification is deliberately scoped to workload-level properties and leaves platform constructs to the implementation.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 70 days ago.
- What is it written in?
- Mainly Makefile, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
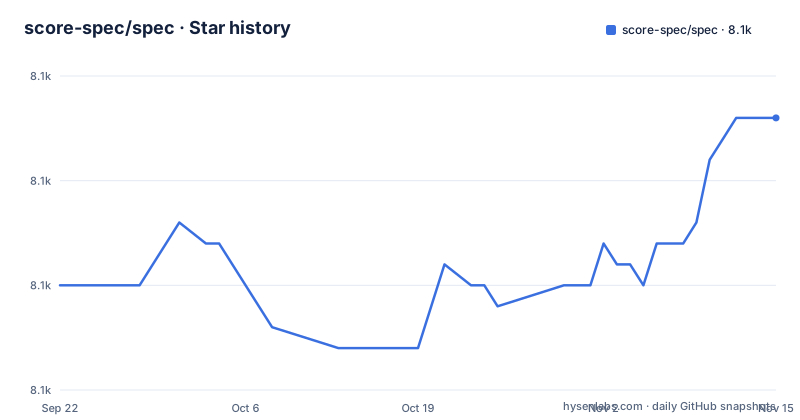
Star history
- score-spec/spec8,103 ★ · +8
| Repository | 2026-09-22 | 2026-11-15 |
|---|---|---|
| score-spec/spec | 8.1k | 8.1k |
8 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One file that states requirements instead of platform syntax
Score is an open-source workload specification, and the problem it names is a duplication problem. The same application gets a compose file for a laptop and manifests for a cluster, and somebody has to keep the two honest. Score's answer is to describe the workload once, in a vendor-neutral way, and leave the tooling-specific syntax of Docker Compose and Kubernetes out of it entirely.
The framing the project gives is deliberately plain: describing a workload's configuration becomes as simple as stating that you want a database of type X and an event queue of type Y to accompany your workload. Here is the example file, which describes a web server that queries a Postgres database on each request.
# The version string helps identify the Score file syntax
apiVersion: score.dev/v1b1
metadata:
  name: sample

# A set of containers deployed together for this Workload.
containers:
  main:
    # The "default" image for our service. When deploying, we may override this with a particular tag.
    image: ghcr.io/score-spec/sample-app-gif:sha-2533037
    variables:
      # Pass the resource outputs to our container as environment variables. The Score implementation takes care of securing any secret access as needed.
      PG_CONNECTION_STRING: "postgresql://${resources.db.username}:${reso
Two details in that file matter. The version string is `score.dev/v1b1`, which is how the syntax is identified, and the comment on the image says the default image may be overridden with a particular tag at deploy time. The file itself is saved alongside the workload's own source in version control, which is what puts it in the same pull request as the code that depends on it.
The contract ends where the declared requirements end
Two stated properties set expectations before you write a line. The first is that Score is declarative: developers declare what the workload requires to run, and the platform in the target environment is responsible for resolving individual runtime requirements. The second is that it is tightly scoped, describing workload-level properties, and does not intend to be a fully featured YAML replacement for any platform.
The contract those two produce is stated as a conditional. If the requirements listed in the spec are honoured, the workload will run as intended. That is the whole promise, and it is narrower than it first sounds. Score does not choose your Postgres version, your replica count, or your ingress class. It says a database is needed, and the implementation resolves it.
For a reader, the practical consequence is that adopting Score relocates your platform knowledge rather than removing it. The constructs you already use to shape a deployment have nowhere to live inside a workload-level specification, so you still need somewhere to keep them. The stated aim is shielding developers from the complexity of container orchestration tools like Kubernetes, and whether that lands for you depends on how much of your configuration was orchestration complexity to begin with.
The database reference in the sample resolves per environment
The environment-agnostic half of the design shows up in a single line of the example file.
PG_CONNECTION_STRING: "postgresql://${resources.db.username}:${resoThat value is a template, not a credential and not a working URL. The placeholders reference resources that the target environment is expected to supply, and the comment above the line says resource outputs are passed to the container as environment variables, with the Score implementation taking care of securing any secret access as needed. The line stays identical across every environment, and each one resolves it with its own appropriate credentials.
That separation is the point of the environment-agnostic label. Nothing environment-specific goes into the committed file, so there is no local connection string to leak and no per-environment copy to drift out of sync. The cost is that the syntax belongs to Score: `${resources.db.username}` means nothing outside an implementation that understands it, and anyone reading your score.yaml without that context sees a broken URL rather than a template.
The schema file is the contract, and the Makefile tests it
The specification is published as a JSON Schema, and the repository treats that file as something to be tested rather than merely announced. `score-v1b1.json` sits at the top level, and both validation targets depend on a validator binary that the Makefile installs for you.
${GOPATH}/bin/jv:
ifeq ($(GOPATH),)
	$(error GOPATH must be set)
endif
go install github.com/santhosh-tekuri/jsonschema/cmd/jv@latesttest-examples: ${GOPATH}/bin/jv
ifeq ($(SCORE_EXAMPLES_DIR),)
$(error SCORE_EXAMPLES_DIR must be set)
endif
for f in $$(find ${SCORE_EXAMPLES_DIR} -name 'score*.yaml' -print); do ${GOPATH}/bin/jv --assert-format --assert-content ./score-v1b1.json $$f; done
@echo "Schema matches all samples"The aggregate target runs both halves, schema first and samples second.
.PHONY: test
test: test-schema test-examples
`SCORE_EXAMPLES_DIR ?= ./samples` is overridable, so the sample check can be pointed at a directory of your own. What this buys you is a usable pre-commit gate: write `score.yaml`, place it where the glob will find it, and validate it against the exact schema your consumers will read. What it does not do is render anything. The documented target list is help, test-schema, test-examples and test, so validation is everything the Makefile does.
A deprecated sample is still a schema test
The samples directory holds two files, and one of their names carries information on its own: `samples/score-full.yaml` and `samples/score-deprecated-files-and-volumes.yaml`. The second name tells you that files and volumes exist as keys in a form the project has moved away from.
What makes that interesting is the glob in the test target. It finds every file matching `score*.yaml` under the examples directory and asserts each one against `./score-v1b1.json`. There is no exclusion list and no separate directory for deprecated material, so that sample is validated by exactly the same code path as the full one.
The consequence is narrow and worth knowing before you copy anything out of the samples directory. Whatever state those keys are in, the project's own test suite requires them to satisfy the current schema file. If you are unsure whether a construct you need is current or on the way out, comparing your file against these two samples is the fastest check available, and the specification reference at docs.score.dev is the authority when the samples are ambiguous.
Two reference implementations and a long private tail
A Score specification on its own produces nothing. What turns it into a deployable artifact is an implementation, and two reference ones are named: score-compose, which converts a Score specification into a `docker-compose.yaml` file, and score-k8s, which generates `manifests.yaml` files for deployment to a Kubernetes cluster.
Both are described as suitable for practical use and as blueprints for writing custom implementations. The more interesting detail is how third-party implementations are governed. Community-built ones are hosted and maintained by their creators, and they may either be referenced in the Score documentation or kept entirely private. If a contributor wants to donate theirs, the project states it is open to exploring that option.
Two consequences follow for anyone adopting this. First, an implementation is separate software with its own release cycle and its own defects, so pinning the schema version does not pin the thing that renders it. Second, the private option means there is no completeness guarantee. If nobody has written an implementation for the platform you run, nobody has told you, and the specification will not tell you either.
Where the specification stops and platform knowledge resumes
The limits are worth stating together, because together they decide where this fits. Score is a specification, not a program. It emits no compose file and no Kubernetes manifests by itself, and the repository reflects that plainly: its primary language is a Makefile whose documented jobs are schema validation. To get output you need score-compose, score-k8s, or your own implementation, all of which live in other repositories.
It also does not intend to be a fully featured YAML replacement for any platform. That is given as a design goal rather than a gap, and it means the constructs you rely on to shape a real deployment, Helm values, Kustomize overlays, ingress and storage class choices, have no home in a workload-level file.
The single-file promise is scoped the same way. Environment-specific configuration is separated out by design and resolved per target environment, so the set of files you maintain shrinks rather than collapsing to one. And nothing in the specification replaces knowing your platform: Docker, Kubernetes and Helm are named as platforms Score stays independent of, not as platforms it configures on your behalf.
Three releases with a year between the first two
The release record is short enough to read at a glance: 0.3.0 on 2025-04-14, 0.4.0 on 2026-04-17, and 0.4.1 on 2026-05-25. The gap between the first two is a year, and two releases landed about five weeks apart in the middle of 2026. The repository is not archived, and the last push was 2026-09-07.
The version inside your file is what to check. The example uses `score.dev/v1b1`, and the schema file in this repository is named for that same version, so the apiVersion string in your `score.yaml` and the schema your consumers validate against are two halves of one contract. A new schema version means a new apiVersion string, and nothing inside the file will change it for you.
The surrounding files give the project a settled shape: GOVERNANCE.md, MAINTAINERS.md, CODEOWNERS, ADOPTERS.md, SECURITY.md, CONTRIBUTING.md and CODE_OF_CONDUCT.md, under an Apache-2.0 licence. The roadmap lives in roadmap.md, and ideas go through the issue tracker at any time. Before pinning a version, read roadmap.md to see what is planned, and check the commit date of the schema file you copied.
Editorial conclusion
Adopt Score when the same application has to run under more than one orchestration platform and the cost you are actually paying is keeping those configurations in sync. Do not adopt it expecting one file to cover everything, since the specification is deliberately scoped to workload-level properties and leaves platform constructs to the implementation. Before you commit, check the apiVersion string in your file against the schema in this repository, read roadmap.md to see what is planned, and confirm that the implementation you intend to use is one of the two reference implementations or a project you are willing to track yourself.
Frequently asked questions
What does the Score specification actually describe?
It describes a workload's requirements in a vendor-neutral way rather than in the syntax of a particular platform. The example file sets apiVersion to score.dev/v1b1, names the workload under metadata, and lists containers with an image and a set of variables.
How do I check that my score.yaml is valid?
Run make test-examples in this repository. It installs the jv validator with go install and asserts every score*.yaml file found under SCORE_EXAMPLES_DIR against ./score-v1b1.json, and SCORE_EXAMPLES_DIR defaults to ./samples but can be overridden.
Which tools turn a Score file into something deployable?
The project names two reference implementations: score-compose converts a Score specification into a docker-compose.yaml file, and score-k8s generates manifests.yaml files to deploy to a Kubernetes cluster. Community-built implementations are hosted and maintained by their creators.
Does Score replace my Kubernetes or Helm configuration?
No, and the project presents that as a design goal rather than a limitation. The specification describes workload-level properties and does not intend to be a fully featured YAML replacement for any platform, staying independent of Docker, Kubernetes, Helm and other orchestration platforms.
Where is the Score schema and how do schema versions work?
The current schema is stored at ./score-v1b1.json, and the syntax version is identified by the apiVersion string score.dev/v1b1 inside the file itself. Published releases have been 0.3.0, 0.4.0 and 0.4.1, with 0.4.1 published on 2026-05-25.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/score-spec-spec)Star history chart for your README
[](https://hysenlabs.com/projects/score-spec-spec)Was this useful?