Scrapy 2.19: a Twisted-based crawling framework with a Python 3.11 floor and 26 dependencies
Scrapy, a fast high-level web crawling & scraping framework for Python.
At a glance
- What is it?
- scrapy/scrapy is the BSD-licensed Python framework for crawling websites and extracting structured data, maintained by Zyte and outside contributors. Installing it is one pip command; what that command pulls in, and where the actual instructions live, is the part worth understanding first.
- Who is it for?
- Scrapy suits Python developers who need to crawl many pages and turn them into structured records, can run Python 3.11 or newer on CPython, and are comfortable carrying Twisted and 25 other packages into their environment. It is the wrong choice for a project stuck on Python 3.10 or one that needs to execute page JavaScript with nothing extra installed.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
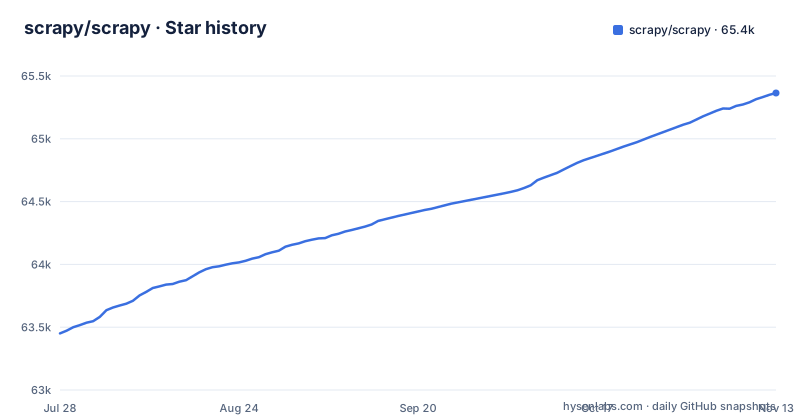
- scrapy/scrapy65,365 ★ · +1,914
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| scrapy/scrapy | 63.5k | 65.4k |
1,914 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One pip command, but only on Python 3.11 and newer
Scrapy describes itself as a web scraping framework to extract structured data from websites. It is cross-platform, and the install instruction is a single line:
pip install scrapyThe catch is the interpreter floor. pyproject.toml sets requires-python to >=3.11, and the classifiers list Python 3.11, 3.12, 3.13, 3.14 and 3.15. A server or CI image still on Python 3.10 cannot install current releases, so the first check before adding Scrapy to an existing project is the interpreter version, not the operating system. The only implementation classifier is CPython. For conda users there is a conda-forge package, shown by the conda version badge, and the repository also carries an INSTALL.md file at the top level. On Windows, macOS and Linux the documented route is the same pip command; there is no separate installer or desktop download.
Twisted sits underneath every crawl
Scrapy is not a thin wrapper over an HTTP client. Its first-listed runtime dependencies are PyDispatcher>=2.0.5 and Twisted>=23.8.0, with zope.interface>=5.1.0 further down, and those three tell you how the framework is built: on Twisted's event-driven networking, with a signal dispatcher on top. Alongside Twisted, the dependency list now includes asyncio-side libraries as well: aiohttp>=3.13.3, aiodns>=3.3.0 and aioftp>=0.26.1. The consequence for a reader is architectural. Code written for Scrapy runs inside the framework's engine rather than as a plain script that fetches one page and exits. If all you need is to parse an HTML file you already have on disk, installing Scrapy brings an event-driven networking stack you will never use, and a smaller parsing library from its own dependency list will do that job with less to carry.
Twenty-six dependencies, two of them tied to your Python version
pyproject.toml lists 26 runtime dependencies, and two are conditional. backports.zstd>=1.3.0 installs only below Python 3.14, and typing-extensions>=4.6.0 only below Python 3.13. On Python 3.14 or 3.15 both drop out. The rest fall into recognisable groups by name. Compression: brotli>=1.2.0 and the zstd backport. TLS and certificates: cryptography>=41.0.5, pyOpenSSL>=24.3.0 and service_identity>=24.2.0. Text and markup: charset-normalizer>=3.4.0, lxml>=4.9.4, cssselect>=1.2.0, parsel>=1.8.1, defusedxml>=0.7.1 and w3lib>=2.1.1. Crawl bookkeeping: queuelib>=1.8.0, protego>=0.2.0, tldextract and platformdirs>=2.0.0. Every constraint is a floor written with >=, and packaging and tldextract carry no version at all. Two machines installing the same Scrapy release on different days can therefore end up with different lxml, parsel or Twisted versions. Reproducible crawlers need their own lockfile.
Selectors and items live in separate packages
Several pieces a Scrapy user touches every day are maintained as their own distributions rather than inside the scrapy/ package. Data extraction goes through parsel>=1.8.1, which builds on lxml and cssselect. Scraped records pass through itemadapter>=0.1.0 and itemloaders>=1.0.5. URL and web helpers come from w3lib>=2.1.1. The split has a practical side. When a selector or item-loading behaviour changes, the version that matters may be the parsel or itemloaders version in your environment, not the Scrapy version in your requirements file. Because the constraints are floors, upgrading Scrapy does not necessarily upgrade those packages, and upgrading those packages alone can change behaviour without any Scrapy release. When a crawl that worked yesterday starts returning different results after a fresh install, compare the parsel, lxml and itemloaders versions between the two environments before blaming Scrapy itself.
The README stops at install and sends everything else to docs.scrapy.org
The repository README is about 140 words. After the badges, it gives the one-line description, the Python 3.11+ requirement, the maintainers, the pip command, and a link to the documentation at docs.scrapy.org/en/latest. There is no example spider, no project layout and no command reference on the GitHub front page. Contribution guidance is on a separate docs page under docs.scrapy.org/en/master/contributing.html, with CONTRIBUTING.md in the repository as well. For someone arriving from GitHub, the practical effect is that learning how to use Scrapy, including its interactive shell or how to structure a crawler, happens entirely on the documentation site. The repository itself holds that documentation source under docs/, release notes in NEWS, a sep/ directory, and an AGENTS.md file for coding agents working on the codebase.
Releases land every few weeks on the master branch
Scrapy is under active development. Version 2.17.0 was released on July 7, 2026, 2.18.0 on August 20, 2026, and 2.19.0 on September 10, 2026, and the most recent push to the repository was on November 2, 2026. The default branch is master, not main, which matters if you install from a Git URL or script against branch names. The project carries the Development Status :: 5 - Production/Stable classifier, and the README shows badges for test runs on master, Codecov coverage, the PyPI version and the conda-forge version. The repository also has tox.ini for running tests across environments, a tests_typing/ directory for type checks, and a .pre-commit-config.yaml. Maintenance is led by Zyte, the company formerly called Scrapinghub, together with outside contributors listed on the GitHub contributors graph.
BSD-3-Clause licensing, with AUTHORS shipped alongside LICENSE
Scrapy is released under BSD-3-Clause, a permissive license, and pyproject.toml declares two license files: LICENSE and AUTHORS. Anyone redistributing Scrapy in a product ships both. The permissive license covers the framework's code only. It says nothing about the websites a crawler visits, so whether a particular crawl is allowed depends on those sites and on local law, not on Scrapy's license. The dependency list does include protego>=0.2.0 in the crawl bookkeeping group, next to queuelib and tldextract. The repository also provides CITATION.cff for anyone citing Scrapy in academic work, a SECURITY.md for reporting vulnerabilities, and a CODE_OF_CONDUCT.md. For companies the licensing question is simple compared with copyleft projects: there is no obligation to publish crawler code built on top of it.
No browser engine appears in the dependency list
Scrapy is classified as Environment :: Console, and its 26 runtime dependencies are networking, TLS, compression and parsing libraries. None of them is a browser or a JavaScript engine. That defines what a plain install can do: it fetches responses and parses what the server sends. Pages whose content only appears after scripts run in a browser are outside what pip install scrapy gives you, and handling them means adding separate tooling to your project and keeping it compatible with the Scrapy version you run. The same console orientation means there is no graphical interface in the package. Crawlers are written as Python code and run from the command line, and Android or other mobile platforms do not appear among the classifiers, which list OS Independent with CPython as the only implementation.
Editorial conclusion
Scrapy suits Python developers who need to crawl many pages and turn them into structured records, can run Python 3.11 or newer on CPython, and are comfortable carrying Twisted and 25 other packages into their environment. It is the wrong choice for a project stuck on Python 3.10 or one that needs to execute page JavaScript with nothing extra installed. Before adopting it, confirm your interpreter version, pin parsel, lxml and Twisted in your own lockfile, and read the tutorial on docs.scrapy.org, because the repository README stops at the install command.
Frequently asked questions
What is Scrapy used for?
Scrapy is a web crawling and scraping framework for Python used to extract structured data from websites. It is maintained by Zyte and many other contributors.
How to install Scrapy?
Run pip install scrapy on Python 3.11 or newer. A conda-forge package is also available.
How to install Scrapy on Windows?
Scrapy is cross-platform, so the same pip install scrapy command applies on Windows. Your Python must be version 3.11 or newer.
How to install Scrapy on Mac?
Use pip install scrapy with Python 3.11 or newer, the same command as on other platforms. The repository also includes an INSTALL.md file.
How to use Scrapy?
After installing, follow the Scrapy documentation at docs.scrapy.org/en/latest, which covers usage. The repository README itself stops at the install command.
Official sources
Where this project is recommended
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/scrapy-scrapy)Star history chart for your README
[](https://hysenlabs.com/projects/scrapy-scrapy)Was this useful?