Scanpy's newest tag is an alpha published after the last patch of the line below it
Single-cell analysis in Python. Scales to >100M cells.
At a glance
- What is it?
- The single-cell analysis library built jointly with anndata, part of the scverse project and fiscally sponsored by NumFOCUS. Its out-of-core path is marked experimental, its internal API is documented as unsupported while acknowledging that many people depend on it, and it now requires Python 3.13.
- Who is it for?
- Scanpy is a reasonable choice for a team doing single-cell work in Python that wants one library covering preprocessing through clustering and differential expression, and it is a poor choice for a pipeline pinned to an old interpreter or to undocumented internals. Four things to check before committing.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
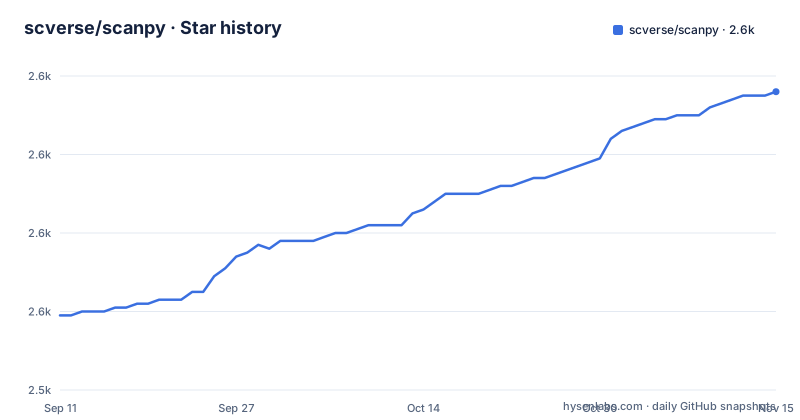
- scverse/scanpy2,616 ★ · +57
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| scverse/scanpy | 2.6k | 2.6k |
57 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The newest tag is a prerelease and it is not the newest release
Three releases are on record, and they are not in version order by date. The first alpha of the next minor line, 1.13.0a1, was published on 2026-07-24. A maintenance release on the older line, 1.12.4, followed on 2026-08-27. The second alpha, 1.13.0a2, landed the next day on 2026-08-28.
So the maintenance branch got a release in the middle of the next branch's alpha cycle, which is normal practice and easy to misread from a tag list, since the sort order by date puts a patch release above an alpha of a higher minor.
The consequence is for anyone installing without pinning. The newest tag is a prerelease, so a plain install picks up the newest stable release, which here is 1.12.4, published a day before the alpha that supersedes it. A user who reads the release page and a user who installs the package are looking at different code, and nothing in the file tells them which one they got.
The repository's last commit is dated 2026-10-02, two days before this writing, so the tree is ahead of every tag on the list as well.
The description says a hundred million cells and the text says one million
Two scale claims sit in the same project, and they differ by two orders of magnitude. The one-line project description says it scales to more than a hundred million cells. The introduction to the readme says the implementation efficiently deals with datasets of more than one million cells.
There is a third sentence that reconciles them in principle and not in practice. For datasets too large to fit into memory, many functions are now compatible with an out-of-core array library, and that sentence carries a warning that the support is experimental.
So the honest reading is that in-memory analysis is the supported path at the million-cell scale, the hundred-million figure describes what the project aims at with the experimental path, and the file does not say which specific functions work out of core. The link it points to for that list is an issue tracker entry rather than a page in the documentation, which is what you would expect from work that is not finished.
For anyone planning a large analysis, that distinction decides the architecture: the out-of-core path is the difference between a single machine and a cluster, and it is the part of the design that carries an experimental label.
An undocumented module with a public-looking name is officially unsupported
The API section is unusually direct, and it is the most useful paragraph in the file. The public API is documented in one section of the documentation. Everything else, the file says, cannot be guaranteed stable, whether that means where a function lives or what arguments it takes.
The example given is telling. Importing a debug helper from the logging module is named as something the project does not officially support and does not encourage users to do, and the reason is subtle: that module is not documented even though it does not start with an underscore. The usual Python convention would have made the private or public question obvious, and here it is not.
Then comes the sentence that makes the whole section a real admission rather than boilerplate. The project is aware that many users do use these internal APIs, and it encourages them either to open an issue asking for the missing thing to be exported, or to migrate to the public API.
That leaves three things unsaid: how long the internals will keep working, what a deprecation would look like, and what happens to the many analyses already built on them. A project that knows its users depend on internals and offers no timeline is telling you to migrate without telling you when it matters.
The interpreter floor is 3.13 and the classifiers stop at 3.15
The package manifest requires Python 3.13 or newer and carries classifiers for 3.13, 3.14 and 3.15, along with a development status of production or stable. It is built with a version-agnostic build backend that derives the version from version control, which is why the release numbers above track tags exactly.
A floor of 3.13 is high for a scientific library, and it is a moving target rather than a fixed one: each release that raises the floor strands anyone on an older interpreter, and the file gives no policy for how long a version is supported or how far back compatibility goes.
The status classifier says the opposite of what a rising floor implies. Production or stable describes the library's maturity, and it is true by any reasonable measure for a tool with a 2018 paper and a large user base. It does not mean the install will work on the machine you have, and nothing in the readme connects the two.
For a cluster or a teaching environment pinned to a distribution Python, this is the field to read before anything else, because the answer is no rather than a version conflict you can work around.
Two chat systems, one governance page and a fiscal sponsor
The badge row points at a Discourse forum and, separately, at a Zulip chat. Both are linked from the same short header, which means the project runs two separate real-time conversation systems at once and does not say which one is which.
The readme's own guidance is to discuss usage on the Discourse forum, so the other one is presumably for something narrower, chat rather than threaded questions. Nothing states that, and a newcomer has no way to tell from the file whether asking in the wrong place will simply go unread.
Structurally, the package is one component of a larger project. It is described as part of scverse, with links to the project website and to a governance page describing roles, and it is fiscally sponsored by NumFOCUS, which is also where the donation request points. The sponsor arrangement is spelled out in unusual detail, naming what donations pay for: developer time, professional services, travel and workshops.
That is a well-run project by any measure. The cost of a federated ecosystem is that support, governance and funding each live on a different domain, so answering a simple question about where to ask something means following three links.
The version comes from tags and part of the repository is tracked against a template
The build configuration declares the version as dynamic and pulls it from version control through a plugin designed for that, so there is no version string in the manifest to fall out of step with a tag. That is the right arrangement for a library whose releases come from tags, and it is why an alpha and a patch release can be published a day apart without anyone editing a file.
The repository also carries a file whose entire job is to track how much of this codebase came from an external template, which is how a project that starts from a shared scaffold knows what it may overwrite on the next update. That implies a two-source repository: hand-written code and generated scaffolding, with a record of which is which.
Around those sit the ordinary maintenance files, and there are more formatter configurations than a Python library usually needs: an editor config, a TOML formatter config, a pre-commit configuration, a coverage configuration and a documentation build config. One of them configures a formatter whose usual territory is JavaScript and TypeScript, which suggests a small front-end somewhere in the documentation.
There are also directories for benchmarks, for continuous integration and for tests. The presence of a benchmarks directory is worth noticing in a project whose headline claim is about scale.
Three maintainers, fifteen credited authors, and a paper from 2018
The manifest splits people into two lists. Three are named as maintainers, each with an email address, two of them at the same institutional domain and one at the project's own domain. Fifteen more are listed as authors with names only.
That is a small release surface by any open source standard, and it is the kind of fact worth knowing before you depend on a project for a long analysis: three people decide what ships, and the file offers no statement about how that changes.
Then there is the citation request. Users are asked to cite the original paper, published in Genome Biology in 2018, and may alternatively cite a 2023 paper describing the wider project. The original is the one requested by default.
Eight years separate that paper from the code described here, and in between the package changed its interpreter floor twice over, introduced an experimental out-of-core path, and drew an explicit line between a documented API and everything else. None of that makes the citation wrong, since the paper describes the method rather than the version, but a reader who follows the request and then installs the package is holding an artefact that the cited work never described.
The readme contains no install command at all
Look for the one line everyone copies and it is not there. The badge row links a package index and a conda channel, and the text links the documentation site, a discourse forum and a chat. No pip invocation, no conda command, no environment file, no version constraint.
For a library distributed through two channels, that is a deliberate choice rather than an oversight, since the package index page is the canonical install instruction and duplicating it in a readme only creates a second thing to keep current. It does mean the answer to an installation question lives one domain away from the question.
The same applies to usage. The readme names the tasks the library covers, preprocessing, visualization, clustering, trajectory inference and differential expression, and then points at the documentation. Every function name, every parameter and every workflow example is on the site rather than here.
So this file is short by design. What it does carry, and what a reader skimming search results will not find elsewhere, is the API stability statement, the experimental label on out-of-core support, the two community chat systems and the citation request. Those four things are the reason to read it before installing anything.
Editorial conclusion
Scanpy is a reasonable choice for a team doing single-cell work in Python that wants one library covering preprocessing through clustering and differential expression, and it is a poor choice for a pipeline pinned to an old interpreter or to undocumented internals. Four things to check before committing. Confirm your interpreter, because the floor is Python 3.13 and the file says nothing about which versions earlier releases supported. Confirm which functions you actually need are in the documented API, since the project explicitly declines to guarantee anything outside it and knows that many users depend on it anyway. Read the scale claim carefully, because the project description and the readme state different cell counts and the route past memory is labelled experimental. And pin a version deliberately: the newest tag is a prerelease of the next minor, so an unpinned install and a release install are not the same code.
Frequently asked questions
How do I install scanpy?
The readme gives no install command. Its badges link the package on PyPI and the conda-forge channel, and the text points at the documentation site for anything more. What the manifest does state is the floor: Python 3.13 or newer, with classifiers for 3.13, 3.14 and 3.15.
what is scanpy used for
Analyzing single-cell gene expression data in Python. The readme lists preprocessing, visualization, clustering, trajectory inference and differential expression testing, says the implementation handles datasets of more than one million cells efficiently, and says many functions are now compatible with dask for data too large for memory, with that support marked experimental.
is scanpy a package
Yes, published on PyPI and on the conda-forge channel, built with the hatchling backend, and licensed BSD-3-clause. It is part of the scverse project, built jointly with anndata, and is fiscally sponsored by NumFOCUS.
How can I remove doublets in Scanpy?
The top-level readme does not name a doublet removal step. It lists preprocessing among the tasks the library covers and points at the documentation site and the scverse discourse forum for usage questions, so the function to call has to be looked up in the API section rather than here.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/scverse-scanpy)Star history chart for your README
[](https://hysenlabs.com/projects/scverse-scanpy)Was this useful?