scvi-tools: the CUDA line in its Dockerfile is discarded, and torch carries no version bound
Deep probabilistic analysis of single-cell and spatial omics data
At a glance
- What is it?
- scvi-tools is a PyTorch and AnnData package for probabilistic analysis of single-cell and spatial omics data, published on PyPI and conda-forge. Reading its Dockerfile, its pyproject and its documentation links closely shows a CUDA base image that contributes nothing, an unbounded torch dependency, and two documentation hosts that do not match.
- Who is it for?
- scvi-tools suits a bioinformatics group that already works in PyTorch and AnnData, wants the same probabilistic machinery for integration, doublet detection, annotation and spatial deconvolution rather than four separate tools, and is willing to pin versions itself. It suits less well a group that wants the install command to choose a working PyTorch build for their GPU, because the dependency list leaves torch unbounded and the install note hands that decision over.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
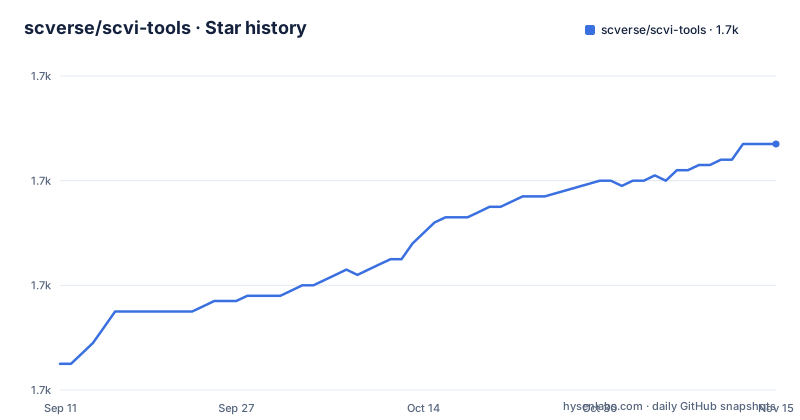
- scverse/scvi-tools1,727 ★ · +42
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| scverse/scvi-tools | 1.7k | 1.7k |
42 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Dockerfile's CUDA base line contributes nothing at all
The container file opens like this:
FROM nvidia/cuda:12.4.0-runtime-ubuntu22.04
FROM python:3.13 AS base

RUN pip install --no-cache-dir uv

RUN uv pip install --system --no-cache torch torchvision torchaudio

CMD ["/bin/bash"]
The first line declares a stage and the second declares another, so the CUDA image is left with no instructions of its own and nothing is built on top of it. Every `RUN` in the file belongs to the `base` stage, which is plain `python:3.13` with no accelerator runtime in it at all. The pinned version 12.4.0 and the ubuntu22.04 base read like a deliberate CUDA choice, and then the next line throws it away. The rest of the file continues from `base` with a `build` stage that sets `SCVI_PATH` to the python3.13 site-packages directory, copies the repository into it, and installs from that path with `uv`, choosing an extras set at build time through a `DEPENDENCIES` build argument that defaults to the empty string. Nothing in the visible file brings a CUDA runtime back in.
The last stage ends at a shell prompt, with no entrypoint
The `build` stage is the final one in the file, and it sets no `ENTRYPOINT` and no `CMD` of its own. Docker carries the command forward from the stage it inherits, which here is `CMD ["/bin/bash"]` on `base`. So the image this produces is a shell with scvi-tools installed inside it, not an application you run. That can be the intent for a development or CI image, and the `ARG DEPENDENCIES=""` plus the conditional install makes it easy to build the same base with an extras set appended, so `cuda` or `cuda13` can be selected at build time rather than baked in. Two details are worth holding onto. The `COPY . ${SCVI_PATH}` step copies the entire build context into site-packages and then installs from there, so anything in the context, including a local `.env` or an editor directory, travels into the image unless a `.dockerignore` excludes it. And the base stage installs torch, torchvision and torchaudio with no version and no index URL, which is a separate decision from the extras the project defines.
Twenty dependencies, and the biggest one has no version at all
The dependency list in pyproject names twenty packages: anndata, docrep, joblib, lightning, ml-collections, mudata, numba, numpy, pandas, pyro-ppl, rich, scanpy with the skmisc extra, scikit-learn, scipy, sparse, tensorboard, torch, torchmetrics, tqdm and xarray. Five of them carry a lower bound, `docrep>=0.3.2`, `lightning>=2`, `numba>=0.60`, `scanpy[skmisc]>=1.10` and `sparse>=0.14`. The remaining fifteen are written bare, and the ones that decide whether your analysis runs are among them. `torch` appears with no constraint at all, as do `numpy`, `pandas`, `scipy` and `scikit-learn`. There is no upper bound anywhere in the list. That is a defensible choice for a research library that wants to absorb new releases, and it is also the reason the install note exists, since the resolved torch is whatever your resolver picks at the moment you install.
Neither install command chooses a PyTorch build for your GPU
The two documented install paths are:
conda install scvi-tools -c conda-forgepip install scvi-toolsBoth take the same unconstrained `torch` from the previous section, and the instruction that follows them is the whole of the GPU guidance: be sure to install a version of PyTorch that is compatible with your GPU, if applicable. So the accelerator decision is handed to the reader, and the two extras that would make it are not part of either command. The `cuda` extra adds `cupy-cuda12x`, `nvidia-nccl-cu12` restricted to Linux, plus torchaudio and torchvision, and a `cuda13` extra repeats the pattern with `cupy-cuda13x` and `nvidia-nccl-cu13`. The visible portion of that second list ends partway through the platform marker on its last entry. There is also an `autotune` extra carrying hyperopt, muon, scib-metrics and `ray[tune]`, where the marker excludes ray on Windows, and the comment beside it records that the new autotune is not supported on Windows yet.
The docs badge and every documentation link point at different hosts
Two documentation hosts appear in the same file. The badge in the header resolves to readthedocs.org for a project named scvi, and the link behind it is `scvi.readthedocs.io`. Every prose link points somewhere else: the documentation index, the user guide, the codebase overview and the contributing guide are all under `docs.scvi-tools.org`, with the codebase overview one level deeper at `user_guide/background/` and the contributing guide under `developer/`. The repository root holds a `.readthedocs.yaml`, so the older host is still configured for a build. The practical consequence is that the two are separate deployments, that the readthedocs project name still carries the pre-rename `scvi` spelling while the canonical site uses the package name, and that a link checked on one host tells you nothing about the other. If you are pinning documentation in an internal runbook, pick the `docs.scvi-tools.org` URLs, since those are the ones the page actually sends you to for guidance.
Two releases nine hours apart on one day, then nothing for ten weeks
Three tags are recent: 1.5.1 published 2026-09-10, then 1.5.0.post1 at 17:34 on 2026-07-09 and 1.5.0 at 08:06 the same morning. The pair is the interesting part. A post release exists because the release before it was wrong in a way that needed fixing quickly, and here both landed on the same date under half a day apart, which is what that looks like in practice. The pyproject version field reads 1.5.1, so the manifest and the newest tag agree, which is not always true and is worth noting as the absence of a mismatch rather than as a defect. The last commit to the repository is dated 2026-09-28, about two and a half weeks after the 1.5.1 tag and ten weeks after the 1.5.0 pair, so the branch is ahead of every published version. Version 1.5.1 sits under a classifier of Development Status 4, Beta, and the package declares `requires-python` of 3.12 or later while listing classifiers for 3.12 through 3.15.
The reference it asks you to cite is from 2022
The citation block names the paper as A Python library for probabilistic analysis of single-cell omics data, published in Nature Biotechnology on 2022 Feb 07 with the doi 10.1038/s41587-021-01206-w. The package asking for that citation is at version 1.5.1. Between the paper and this manifest sit four years and a long list of releases, and the page adds the instruction that you should also cite the publication describing the model you used, which means a single citation is never the whole answer. A second block asks you to cite the scverse project paper from Nature Biotechnology, 2023 Apr 10, doi 10.1038/s41587-023-01733-8. Both blocks are formatted as blockquotes with author lists that run past twenty names each, including the scverse community as a collective. The copyright line at the foot reads 2026 and names the Yosef Lab at the Weizmann Institute of Science, while the maintainer entry in pyproject gives a single address at that institute.
A JavaScript linter config sits in a Python repository
The root of an otherwise conventional Python project contains `biome.jsonc`, which is the configuration file for Biome, a JavaScript and TypeScript linter and formatter. Alongside it sit `.pre-commit-config.yaml` and `.editorconfig` for the checks that do apply, and `.codecov.yaml` matching the coverage badge in the header. The layout is otherwise standard: `src/` for the package, `tests/` beside it, `conftest.py` at the root, `docs/` for the documentation sources and a hatchling build backend declared in pyproject. Two entries are less common. `.cruft.json` records that the project was generated from a template and tracks how far it has drifted since, which is how a project keeps upstream scaffolding changes coming back down. `.gitmodules` means the checkout contains git submodules, so a plain clone leaves those directories empty until they are initialised, and any file listed there is absent from the tree you see on the hosting site. The license is declared in pyproject as a reference to the LICENSE file rather than as an SPDX identifier, even though the project is BSD-3-Clause.
Editorial conclusion
scvi-tools suits a bioinformatics group that already works in PyTorch and AnnData, wants the same probabilistic machinery for integration, doublet detection, annotation and spatial deconvolution rather than four separate tools, and is willing to pin versions itself. It suits less well a group that wants the install command to choose a working PyTorch build for their GPU, because the dependency list leaves torch unbounded and the install note hands that decision over. Before adopting it, install a PyTorch build matched to your own accelerator rather than taking the default, read the CUDA extras for your toolkit version, and note that the container file is not a working CUDA environment as written. If you intend to cite it, cite the model you actually used as well as the library, since the reference it asks for is the 2022 paper.
Frequently asked questions
how to install scvi tools
Two commands are given, conda install scvi-tools -c conda-forge for conda and pip install scvi-tools for pip. Both leave PyTorch unpinned in the dependency list, so the page adds the instruction that you be sure to install a PyTorch version compatible with your GPU, and points at cuda and cuda13 extras for the accelerator builds.
what is scvi tools
It stands for single-cell variational inference tools, a package for probabilistic modeling and analysis of single-cell omics data built on PyTorch and AnnData. Its models cover dimensionality reduction, data integration, automated annotation, factor analysis, doublet detection and spatial deconvolution, and it is part of the scverse project, fiscally sponsored by NumFOCUS.
Which Python versions does scvi-tools support?
The manifest requires Python 3.12 or later and lists classifiers for 3.12, 3.13, 3.14 and 3.15. The container file builds on a python:3.13 base and sets its install path into the python3.13 site-packages directory.
How do I write a new model for scvi-tools?
The package is positioned as a set of building blocks for developing and deploying new probabilistic models, powered by PyTorch Lightning and Pyro. The page recommends the scverse/simple-scvi skeleton repository as a starting point and points to a codebase overview page for how the package is structured.
How should I cite scvi-tools in a paper?
Cite A Python library for probabilistic analysis of single-cell omics data, Nature Biotechnology, 2022 Feb 07, doi 10.1038/s41587-021-01206-w, and also cite the publication describing the model you used. The scverse project paper in Nature Biotechnology, 2023 Apr 10, doi 10.1038/s41587-023-01733-8, is a separate citation.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/scverse-scvi-tools)Star history chart for your README
[](https://hysenlabs.com/projects/scverse-scvi-tools)Was this useful?