ksuid: time-ordered identifiers in 20 bytes and 27 base62 characters
K-Sortable Globally Unique IDs
At a glance
- What is it?
- ksuid is the Go reference implementation of the K-Sortable Unique IDentifier, a 20 byte value that sorts by creation time with no type-aware logic and no coordination. Its design spends bytes on entropy in one documented place, and the maintainer names exactly where that trade turns dangerous.
- Who is it for?
- Use ksuid when your identifiers need to sort by creation time in the database, in a log file, or in any store that never heard of the format, and when you can live with 20 bytes per row and a one second ordering resolution. Think twice before switching a unique ID into a security boundary, because FastRander makes issued IDs predictable and the payload half is what the collision argument rests on.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 142 days ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
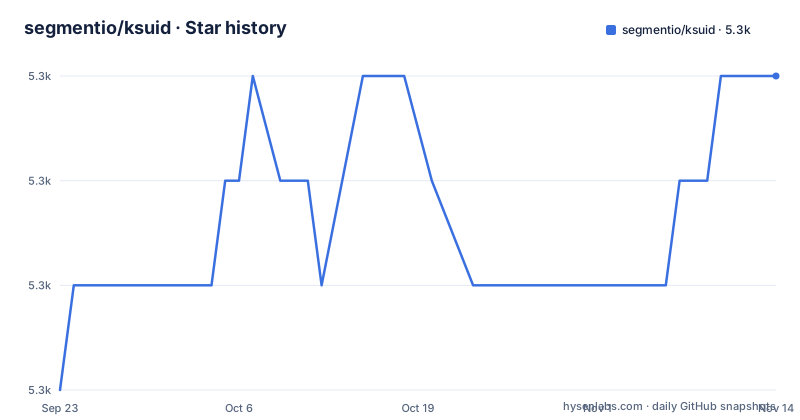
- segmentio/ksuid5,273 ★ · +3
| Repository | 2026-09-23 | 2026-11-14 |
|---|---|---|
| segmentio/ksuid | 5.3k | 5.3k |
3 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
go get pulls master, because the repository has no releases
The library installs as an ordinary Go module.
go get -u github.com/segmentio/ksuidThe module path is github.com/segmentio/ksuid, and go.mod declares go 1.12. The repository publishes no GitHub releases. The last push to master is dated 2026-06-25. The license is MIT. The repository root is flat Go source rather than a large tree: base62.go, rand.go, sequence.go, set.go, uint128.go, and ksuid.go sit beside cmd/, and every one of those files except rand.go has a matching _test.go next to it.
Twenty bytes and 27 characters for one value
A KSUID has two representations of the same value. The binary form is 20 bytes: a 32 bit unsigned integer UTC timestamp followed by a 128 bit randomly generated payload. The timestamp is stored big-endian so that byte order matches numeric order, its epoch is adjusted to May 13th, 2014, and that adjustment is what provides the over 100 years of life claimed for the format. The payload is produced by a cryptographically-strong pseudorandom number generator. The text form is always 27 characters, an alphanumeric base62 encoding arranged so that lexicographic order follows the timestamp again. Running the bundled command against one value prints both views, with the raw 20 bytes in hex beside the string, then breaks the timestamp into a readable date, a plain number, and a payload block. What that layout gives up is resolution. The clock field is a single 32 bit counter measured in seconds, so two identifiers minted inside the same second are ordered by their random payload rather than by anything finer.
Base62 with no delimiters survives being pasted
The text encoding is deliberately plain: alphanumeric base62, no delimiters, always 27 characters. The missing separators are the design decision. The project argues that stringified KSUIDs will not be inadvertently truncated or tokenized by software built for human-readable text, which it names as a common failure for the text form of RFC 4122 UUIDs. Both the binary and text representations are lexicographically sortable, so an identifier can be dropped into a system that has never heard of KSUID and still arrive in time order, which is what lets UNIX sort on the text output produce a list ordered by generation time. What portability does not buy is readability. There is no grouping inside the 27 characters, so nobody can tell the timestamp half from the payload half by looking, and the alphabet mixes upper and lower case, so the exact casing has to survive storage and transport for the value to survive. Sorting is the operation this format exists for, and it works on representations rather than on pieces: an identifier that has been split at a delimiter, trimmed, or re-encoded no longer compares in time order, so any pipeline treating these values as loose text risks breaking the property that made them worth having.
128 bits of payload is what removes the coordination requirement
The entropy argument carries the whole design. A KSUID holds 128 bits of pseudorandom data, a number space 64 times larger than the 122 bits used by RFC 4122 UUIDv4, and the timestamp counts as bonus entropy on top of that, which pushes collisions to the point of physical infeasibility in any practical implementation. RFC 4122 UUIDv1 does carry a time component, but not enough random bytes to give strong protection against duplicates, so a malicious party can feasibly guess generated identifiers, a problem for systems whose security depends on an adversary not guessing them. Snowflake IDs and their derivatives fit into a 64 bit number space only by requiring coordination to avoid collisions, and that coordination raises deployment complexity and operational burden. KSUID accepts 20 bytes instead and stays coordination-free and dependency-free. Read the claim precisely: nothing coordinates with a server, but the collision argument holds only while that payload really is random, which is the assumption the FastRander type can weaken.
One global mutex guards every pure function
Concurrency is described in one sentence: all public package level pure functions are concurrency-safe, protected by a global mutex. There is exactly one lock in that sentence and it is process-wide, so two goroutines generating KSUIDs at the same moment serialize against each other even when they share nothing else. For hot loops that produce a large number of KSUIDs from a single goroutine, the Sequence type exists to elide the potential contention: draw from one Sequence instead of calling the package functions on every iteration. The value you store is derived from a fixed-size array, which removes the reference chasing and allocation a variable-width type would cost, and that shape also makes copies cheap, since a KSUID passed to another function is 20 bytes of array rather than a pointer. The Append method completes the picture: it parses the text representation and replaces the contents of a KSUID value without additional heap allocation, which is the path to take in code that is sensitive to allocation.
FastRander trades unpredictability for speed on purpose
By default the random bits of a new KSUID come from a cryptographically-secure PRNG, which the project frames as an abundance of caution. For extremely performance-critical code there is a second path, the FastRander type, which uses the standard library PRNG with a seed generated once by the cryptographically-secure generator. The accompanying note cuts both ways: there is no evidence that FastRander increases the probability of a collision, but it should not be used in scenarios where uniqueness is important to security, since there is an increased chance the generated IDs can be predicted by an adversary. That is the whole tradeoff in plain language, and it is the one place in this library where picking the fast path changes what an identifier means rather than how fast it arrives. Nothing else in the value changes: the timestamp half is untouched, and only the 16 random bytes become guessable, so a database ordered by time still works and a security check built on guessing does not. Both paths emit the same layout, which means nothing in the finished identifier records which one produced it, so a table filled by a fast generator is indistinguishable from one filled by the secure default until you go looking at the generating code.
Scanner, Valuer, and the marshal pairs for SQL and JSON
The KSUID type is built to land in storage and on the wire through interfaces it already satisfies. It implements Stringer, database/sql.Scanner together with database/sql/driver.Valuer, the binary and text marshal and unmarshal pairs from the encoding package, with the text pair called out as encoding/json friendly. The consequence is concrete for a Go service: a KSUID column can be scanned out of a query result and written back through the driver without a parallel string type in your code, and a struct field holding one serializes as its 27 character form rather than as a nested object, which keeps an API payload readable and keeps a database column inside the text type most schemas already have. The list stops at those conversions. Nothing here negotiates the 20 byte binary form between two services or specifies a column type, so a schema design still has to choose where the bytes go.
The ksuid command generates and inspects, nothing else
The package ships a command line tool for the two things a person does by hand: make identifiers and take one apart. Installing it needs a Go build environment.
$ go install github.com/segmentio/ksuid/cmd/ksuidRun bare, it prints one identifier.
$ ksuid
0ujsswThIGTUYm2K8FjOOfXtY1K
The `-n` flag prints a batch, one per line.
$ ksuid -n 4
0ujsszwN8NRY24YaXiTIE2VWDTS
0ujsswThIGTUYm2K8FjOOfXtY1K
0ujssxh0cECutqzMgbtXSGnjorm
0ujsszgFvbiEr7CDgE3z8MAUPFt
`-f inspect` is the interesting mode: it takes an identifier and prints both representations plus the decoded components.
$ ksuid -f inspect 0ujtsYcgvSTl8PAuAdqWYSMnLOv

REPRESENTATION:

  String: 0ujtsYcgvSTl8PAuAdqWYSMnLOv
     Raw: 0669F7EFB5A1CD34B5F99D1154FB6853345C9735

COMPONENTS:

       Time: 2017-10-09 21:00:47 -0700 PDT
  Timestamp: 107608047
    Payload: B5A1CD34B5F99D1154FB6853345C9735
Output is machine-friendly for scripting, and the structure shows it: fields sit under REPRESENTATION and COMPONENTS headings with fixed labels, so a shell script can pick out the timestamp line without parsing a sentence.
Editorial conclusion
Use ksuid when your identifiers need to sort by creation time in the database, in a log file, or in any store that never heard of the format, and when you can live with 20 bytes per row and a one second ordering resolution. Think twice before switching a unique ID into a security boundary, because FastRander makes issued IDs predictable and the payload half is what the collision argument rests on. Before you build on it, check go.mod for the Go version your module already declares against the go 1.12 here, confirm the library's single global mutex is acceptable for your goroutine count, and pin a commit rather than a release, since the repository publishes none.
Frequently asked questions
What is the difference between a KSUID and a UUID in ksuid?
A KSUID is 20 bytes: a 32 bit unsigned UTC timestamp in big-endian order plus a 128 bit pseudorandom payload, rendered as 27 base62 characters. A UUIDv4 carries 122 bits of randomness and no timestamp, while a UUIDv1 has a time component but too few random bytes to stop an adversary guessing identifiers. KSUID sorts by generation time with no type-aware logic.
How can I generate a unique ID with ksuid?
Add the library with go get -u github.com/segmentio/ksuid, or install the bundled command with go install github.com/segmentio/ksuid/cmd/ksuid. Running ksuid prints one identifier, ksuid -n 4 prints four, and ksuid -f inspect takes an identifier apart into string, raw hex, time, timestamp, and payload. The random payload comes from a cryptographically-strong pseudorandom number generator by default.
Are UUIDs sortable compared with ksuid?
KSUIDs are, in both representations, because the timestamp is big-endian and the base62 text is laid out to match. UNIX sort over the text output returns a list ordered by generation time. The project's own limit applies: ordering depends on wall clocks, so it is not a mathematical invariant, and it is a property KSUID adds on top rather than one UUIDv4 provides.
What is the ksuid alternative?
The project positions itself against RFC 4122 UUIDv4, RFC 4122 UUIDv1, and Snowflake IDs. UUIDv4 gives 122 bits and no time component, UUIDv1 has a time component but too little randomness to resist guessing, and Snowflake IDs need coordination to fit in 64 bits. KSUID spends 128 bits of payload to stay coordination-free and dependency-free.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/segmentio-ksuid)Star history chart for your README
[](https://hysenlabs.com/projects/segmentio-ksuid)Was this useful?