Semgrep's skill build has two loops that test different things
A collection of skills for AI coding agents from Semgrep
At a glance
- What is it?
- Three agent skills covering application security, language-model security, and writing Semgrep rules, installed with a single command. The interesting part is the build system: validation and packaging each loop over the skill set with a different condition, so one of the three skills ships unvalidated.
- Who is it for?
- This is a sensible thing to install if you use an agent for security review and want the guidance to come from a vendor that maintains a static analyser rather than from a prompt someone wrote. Two skills are guidance documents and the third is a workflow for authoring detection rules, which is the more useful of the three if your rules are a bottleneck.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
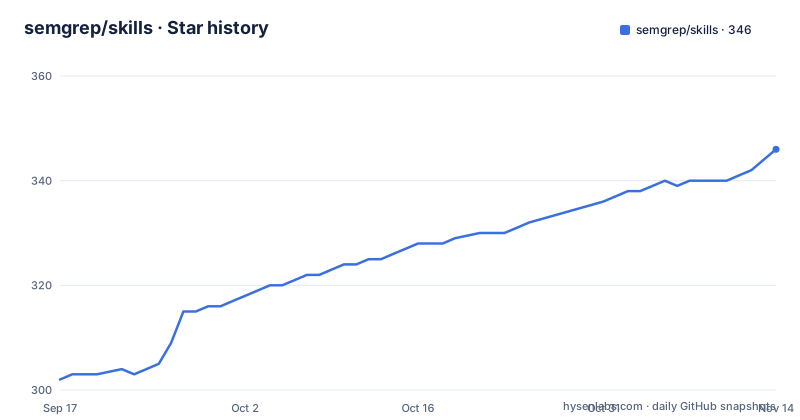
- semgrep/skills346 ★ · +44
| Repository | 2026-09-17 | 2026-11-14 |
|---|---|---|
| semgrep/skills | 302 | 346 |
44 Stars in the last 58 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The skills are generated from rules, and the readme says so in the second line
The second sentence of the readme is the most important one in it. The collection should be treated as beta-level software, and it is primarily generated by transforming open-source Semgrep rules into skill format.
That single sentence explains most of what follows. A skill here is not a hand-written essay; it is a rendering of an existing rule set into the shape an agent can read. The rules are Semgrep's, which means they have a maintenance process behind them, and the skill format is a projection of that.
It also explains the shape of the repository. There is a build system that validates skills and then generates a file for each one, and a packaging step that zips them. If the content were prose you would edit, none of that machinery would be necessary.
The format itself is not Semgrep's. Skills follow the Agent Skills format, published at a separate site, so the same skill directory is portable to any agent that implements that specification rather than being tied to one tool.
Installation is correspondingly simple, because the tooling does the work:
npx skills add semgrep/skillsThere is no clone step, no configuration file, and no key. After that, the skills are available to the agent and it decides when to use them.
Two loops over the skill set with two different conditions
The build is a makefile with five targets, and the default runs three of them in sequence:
make install     # Install dependencies
make validate    # Validate all skills
make build       # Build AGENTS.md for all skills
make zip         # Create distribution packages
make             # All of the above
Validation and building share one loop. It walks the skill directories and, for each one that contains a rules directory, changes into the build package and runs validation, then runs the agent-file build and the test-case extraction. Skills without a rules directory are skipped silently.
Packaging is a separate loop with a different condition. It walks the same directories and requires a skill description file instead, which every skill has.
So the two loops do not agree on what a skill is. A skill with rules gets validated and gets its generated agent file. A skill without rules gets zipped and shipped.
There is a third path, which is the single-skill operations pair, and it takes the skill name as a variable:
make validate-skill SKILL=code-security
make build-skill SKILL=llm-security
That pair is the escape hatch for working on one skill without paying for the whole loop, and it is also how you would validate the skills the loop skips, if you noticed.
The one skill with no rules directory is the one that gets no validation
Three skills ship. Two of them are large guidance documents with category tables covering dozens of vulnerability classes. The third is different in kind: it is a workflow for running Semgrep and for writing Semgrep rules, with a capability table, a six-step rule creation procedure, and a list of vulnerability classes where taint mode is the right tool.
By the description of the skill structure, each skill may contain a description file, a rules directory, an optional scripts directory, and an optional references directory. The two guidance skills are the ones with rule files, because they are derived from rule sets.
The rule-writing skill has no rule set behind it, so under the build's own condition it is the one that is packaged and never validated, and the one that never gets a generated agent file built.
That is defensible as a design. A skill with no generated rules has nothing for the validator to check, since the validator's job is to check the rules. But it means the packaging step's guarantee and the validation step's guarantee cover different subsets, and the readme does not draw attention to it.
The clean target is also worth noting. It removes the generated archives and the generated test-case files, and nothing else, so anything else that a build produces stays in the tree.
Twenty eight categories, six of them named after a platform
The code security skill carries a table of vulnerability classes with an impact rating, a category, and a one-line description of the remediation direction.
Count the rows by rating. Nine are critical: injection through SQL, through the shell, and through code evaluation, then cross-site scripting, external entity resolution, path traversal, unsafe deserialization, hardcoded secrets, and memory safety in C and C++. Thirteen are high, and of those thirteen, six are not vulnerability classes at all. They are named after platforms: three separate rows for the three major clouds, one for Kubernetes, one for Docker, and one for a CI system.
That leaves seven genuine high-severity classes: weak cryptography, cleartext transport, server-side request forgery, token authentication, cross-site request forgery, prototype pollution, and use of dangerous functions.
Three are medium and three are low. The medium ones are catastrophic regex backtracking, check-then-act races, and ordinary correctness bugs, which is an interesting admission to find inside a security document. The low ones are code quality, performance, and organisation, which are not vulnerabilities.
So the table mixes three different taxonomies in one grid: vulnerability classes, platform hardening checklists, and general code quality advice, distinguished only by the impact column. Useful as a checklist, awkward as a severity model.
Fifteen languages claimed, thirteen listed
The code security skill says it covers secure coding best practices across more than fifteen languages, and then lists them: Python, JavaScript and TypeScript, Java, Go, Ruby, PHP, C and C++, C#, Scala, Kotlin, Rust, one infrastructure-as-code language, and one configuration language for Kubernetes manifests.
Counting the way the line is written gives thirteen entries. Whether TypeScript counts separately from JavaScript, and whether the two infrastructure languages count, is where the extra two or three live.
The languages are also not weighted. The list is alphabetical by ecosystem convention rather than by coverage, and the memory safety row is explicitly scoped to C and C++ even though the vulnerable pattern is not language-specific in the way the row implies.
For a rule-derived skill this is expected. Each language gets whatever its rule set contains, and a language with a thin rule set still appears in the list. The claim to make is about the languages represented, not about the depth in each.
The language-model security skill is the opposite shape. It has ten categories, five critical and five high, and it is built on a named external standard rather than on rules. No language list at all, because the risks are about architecture rather than about syntax.
The rule workflow demands tests before the rule exists
The third skill is the procedural one, and its rule creation workflow is the part worth copying regardless of whether you use anything else in this collection.
Six steps. Analyse the vulnerability pattern. Create the test cases first. Analyse the structure of the code with the AST dump command. Write the rule, choosing taint mode for injection and pattern matching for syntax. Iterate until every test passes. Then optimise the patterns.
The second step is the load-bearing one, and it is also encoded in the skill structure rather than just described. Test-driven development here means the rule carries two kinds of annotation, one that marks code as a finding and one that marks code as clean, so the scanner is its own test suite. Iterate until one hundred percent of the tests pass is the acceptance criterion, not a guideline.
The taint-mode rule of thumb is stated as a list: injection through SQL, through the shell, cross-site scripting, path traversal, and server-side request forgery, on the grounds that these are the cases where untrusted data flows to a dangerous sink. Pattern matching is for everything else, which is syntax rather than flow.
The rest of the skill is oriented to running the analyser rather than writing for it: an automatic configuration mode, four named rulesets including a third-party vendor's, and a CI integration that scans only the diff.
A generated agent file at the root and a competing one beside it
The repository root contains an agent instruction file and a competing instruction file for a specific tool. It also contains a make target whose job is to build an agent instruction file for every skill.
So the same filename appears twice in different roles: once as a hand-maintained root file that describes the repository to a coding agent working in it, and once as a generated output inside each skill directory.
That is not a conflict, but it does mean the word carries two meanings in one repository, which is worth knowing before you read either one.
The install path sidesteps all of it. Nothing in this repository is cloned into your project. The command fetches the skills and installs them wherever your agent looks, and the readme's usage section is three example prompts with no code: review a component for security issues, help implement input validation for a language-model endpoint, create a rule to detect hardcoded keys in a language.
There is nothing to configure after that. The agent decides when a skill is relevant, which is the design assumption underneath the whole collection and also its main limitation: relevance detection is the agent's judgement, not a rule.
The provenance note at the end credits a single engineer at the company as the original author and names a large vendor's public React guidance as the main inspiration, which is a useful signal about the intended shape of the guidance skills.
Editorial conclusion
This is a sensible thing to install if you use an agent for security review and want the guidance to come from a vendor that maintains a static analyser rather than from a prompt someone wrote. Two skills are guidance documents and the third is a workflow for authoring detection rules, which is the more useful of the three if your rules are a bottleneck. Two things to know. The skills are described as generated by transforming open-source Semgrep rules, so they track a ruleset rather than being hand-written prose, and the readme labels the whole collection beta. And in the build system, validation and packaging test different conditions: a skill without a rules directory is packaged but never validated and never gets its generated agent file built. That affects one of the three skills here, so if you fork this, check that skill yourself.
Frequently asked questions
How do I install the Semgrep skills?
One command: `npx skills add semgrep/skills`. There is no clone, no configuration file, and no key. Once installed, the skills are available to your agent automatically and it uses them when it detects a relevant task.
How do I use skills in Claude Code once Semgrep's are installed?
You do not invoke them by name. The readme says skills become available once installed and the agent uses them when relevant tasks are detected, so you ask for the work rather than for the skill. The examples given are requests like reviewing a component for security issues or getting help implementing input validation.
Which skills does the Semgrep collection contain?
Three. One covers application and infrastructure security with a table of vulnerability classes across thirteen listed languages. One covers security for language-model applications based on an external standard for large language model applications. The third covers running the analyser and writing custom detection rules.
How do the Semgrep skills get updated?
The readme states the collection is primarily generated by transforming open-source Semgrep rules into skill format, so the content tracks the underlying rule set rather than being hand-maintained prose. The collection is labelled beta-level software, and the repository publishes no releases.
How do I write a Semgrep rule using the workflow in these skills?
Six steps: analyse the vulnerability pattern, write the test cases first, dump the abstract syntax tree to understand the structure, write the rule using taint mode for injection classes and pattern matching for syntax, iterate until one hundred percent of the tests pass, then optimise the patterns.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/semgrep-skills)Star history chart for your README
[](https://hysenlabs.com/projects/semgrep-skills)Was this useful?