IPED: open source since 2012, published in 2019, and one hash gated to law enforcement
IPED Digital Forensic Tool. It is an open source software that can be used to process and analyze digital evidence, often seized at crime scenes by law enforcement or in a corporate investigation by private examiners.
At a glance
- What is it?
- IPED is a Java digital forensics tool for processing seized evidence, written and still developed by forensic experts from Brazil's federal police, with a feature list that runs to forty items and a support for four hundred gigabytes an hour. What makes it worth reading closely is the history paragraph, the build instructions that warn you the branch you just cloned is unstable, and the three features that send evidence to somebody else's server.
- Who is it for?
- Use IPED if you are an examiner who needs to process a large case reproducibly and wants the tool to stay out of the way once processing starts: file system decoding runs out of process so a crashing parser cannot take the case down, processing can be resumed or restarted after an abort, a whole case can reach a hundred and thirty-five million items, and the case directory is portable enough to run from a removable drive. Three things to decide before you start.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
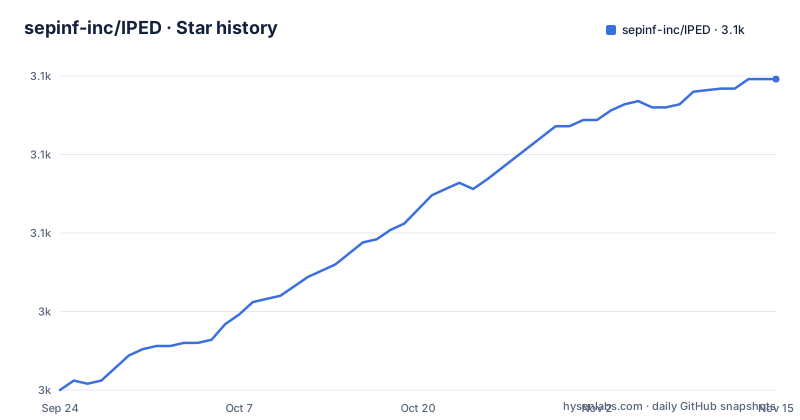
- sepinf-inc/IPED3,099 ★ · +99
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| sepinf-inc/IPED | 3k | 3.1k |
99 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Open source since 2012, published in 2019
The history paragraph is the most informative thing on the page and it is easy to skim past. The tool was implemented in Java and has been developed, originally and still, by digital forensic experts from Brazil's federal police since 2012. And although it was always open source, its code was only officially published in 2019. That is a seven-year gap between being open in principle and being readable in practice, and it means the repository you are looking at is seven years younger than the tool. The name is an expansion translated from Portuguese, which tells you it was named in one language and documented in another from the start, a pattern that continues in the tree today. Set that against the current state: releases through 2026, a release history maintained as a plain text file at the root rather than as release descriptions, and a default branch pushed on the day this was written. The shape is a public-sector tool whose first seven years were internal expertise, followed by a long public life.
Three of the documentation links point somewhere other than the project
There are three questions a new user asks in order, and the page links all three to what looks like the canonical answer. How do I start: a beginner's guide, which resolves to a wiki under a personal account rather than under the project's own organisation. How do I build on Linux: a section in the same wiki, because on that platform you also have to build the disk image and file system decoding library and its dependencies. How do I contribute: a third page in the same wiki. So all three links lead to somebody else's copy of the documentation, and nothing on the page tells the reader that. For a general library this would be an annoyance. For a forensic tool it is more than that, because the difference between the right build procedure and a subtly wrong one can matter to a case, and because a wiki under a personal account can be edited by someone who is not the project. The repository's own structure is legible by comparison, with nine modules named after what they do, which at least tells you where the code lives.
The page tells you the branch you just cloned is the unstable one
An attention line interrupts the build instructions to say that the default branch is the development branch and is unstable, and that if you want something stable you should check out one of the release tags after cloning. That is unusually direct and it has a consequence the instructions do not spell out. The three commands above, clone, change directory, install, produce a snapshot version in the release folder, and a snapshot is exactly what an unstable branch should produce. So both assumptions a reader is likely to make are false in the same way: that cloning gives you the current product, and that a successful build gives you something releasable. The release tags are named with three numbers and the release descriptions attached to them are generic, one saying a minor release, one a major release and one a fix release, so the tags themselves are the only real signal about which build you want. The changelog that would tell you what changed lives in a plain text file at the root of the tree.
The build needs a full JDK because the interface toolkit is no longer bundled
The stated requirements are git, Maven and Java 11 with the interface toolkit included, and the page names a specific full distribution build as the example rather than just saying a version. The reason is structural. The analysis interface is a desktop application, and the toolkit it is built on stopped shipping inside the JDK after version 10, so a standard Java 11 install does not contain what the project needs to compile. With the toolchain in place, the build is three commands:
git clone https://github.com/sepinf-inc/IPED.git
cd IPED
mvn clean install
That single fact is why the requirements look heavier than they are and why the example distribution matters. On Linux there is a further step: the disk image and file system decoding library has to be built too, along with its own dependencies, and that step is documented only in the wiki rather than on the page. So the build has a platform fork in it before you have configured anything, which is why the wiki link is load-bearing and why it is unfortunate that it resolves elsewhere.
One perceptual hash is available to law enforcement on request
The hash list is otherwise a plain technical list: four standard digests, plus the hashing algorithm used for peer-to-peer file sharing, which is what lets the tool deduplicate identical files across an entire case rather than inside one folder. Then one entry is different. A perceptual hash for photographs, which works on visually similar images rather than identical bytes, is available for law enforcement, and the instruction is to contact the project at an address written in an obfuscated form so that automated scrapers do not collect it. That is a capability gate decided by the requester class, enforced by the project rather than by statute, and it is stated inside the feature list rather than hidden in a policy document. For a tool otherwise published for anyone handling seized evidence, from police cases to corporate investigations, it is the single place where the scope narrows, and it is worth reading as a deliberate decision rather than as an oversight.
Three features send evidence to somebody else's server
Most of this feature list is local, and several entries are about not falling over. File system decoding and file parsing run out of process, so a parser that crashes on one file cannot take a case down. Processing can be resumed or restarted after it is stopped or aborted, through two named options. The carving engine takes under a tenth of the total processing time and scans well beyond unallocated space across more than forty formats. Similar-image and similar-face search are both optimised to run without a graphics processor, both with a configurable threshold. A case can hold a hundred and thirty-five million items. Three entries are different because they reach outward. Georeferencing resolves coordinates through two commercial map services or an open one. Audio transcription has local and remote implementations, and the remote ones use two commercial cloud speech services. Named entity recognition needs its language models downloaded from a university project rather than bundled. The page does not warn you about any of this; it names the services and leaves the choice to you, which is honest but easy to miss in a forty-item list.
The headline benchmark says its own age, and the screenshot section is captions
Two presentational details are worth knowing before you read the rest of the page as marketing. The performance claim in the key characteristics states its own vintage. A processing rate of up to four hundred gigabytes an hour on modern hardware, together with a hundred and thirty-five million items in a case, is qualified as of a date in December 2019, which is exactly what you want from a benchmark in a forensic tool and rather more than you usually get. The screenshot section is the other one. It is eleven labelled headings, covering processing, analysis, carving and video thumbnails, regular expression results, mapping, communication links, face search, audio transcription, a timeline, a time chart and a correlation of two suspects' actions, and in the page source no images are attached to any of them. For a tool whose listed strength is an integrated analysis interface, the section that would demonstrate it is a list of captions.
Editorial conclusion
Use IPED if you are an examiner who needs to process a large case reproducibly and wants the tool to stay out of the way once processing starts: file system decoding runs out of process so a crashing parser cannot take the case down, processing can be resumed or restarted after an abort, a whole case can reach a hundred and thirty-five million items, and the case directory is portable enough to run from a removable drive. Three things to decide before you start. Whether you can work from a release tag rather than the default branch, because the page says the default branch is the development one and unstable. Which network-dependent features you will enable, since georeferencing and remote audio transcription reach commercial services and named entity recognition needs models downloaded from a university project. And whether the perceptual hash matters for your workflow, because it is available to law enforcement on request and the contact address on the page is deliberately obfuscated against scrapers. The last recorded push is 2026-10-04.
Frequently asked questions
Is Cellebrite available to the public?
This repository says nothing about Cellebrite's own product or its pricing, and it does not claim to provide that vendor's software. What it does say is that the tool can read one of Cellebrite's export formats, UFDR, alongside the formats supported by the disk image and file system library it uses and several vendor formats it handles itself. So the answer it can give is about interoperability with an export, not about access to the vendor.
How much does a digital forensic investigation cost?
No cost information appears anywhere in this repository, which is software rather than a service. What it does contain is a tool that runs on your own hardware and a claim about throughput on modern hardware that is explicitly dated December 2019, together with a list of three features that will reach commercial cloud services if you enable them, which is where a running cost could appear in practice.
What are the top 5 digital forensic tools?
The page offers no comparison and names no competitors; it describes one tool. What it does give you is the shape of that tool: forty-odd listed capabilities covering hashing and deduplication, signature analysis, container and embedded disk expansion, carving, optical character recognition, timeline and event correlation, communication graphs, similar document, image and face search, audio transcription, and an HTML or CSV reporting step, with a browser and web interface for searching a case.
What is a digital forensic report?
Not defined here. The reporting entry in the feature list is brief: HTML and CSV reports, plus portable case directories that carry their own tagged data, alongside bookmarks and tags you create for interesting items. There is also a web interface for searching a case remotely, fetching metadata, raw content, decoded text and thumbnails, and posting bookmarks. The structure of a report, and what an examiner is expected to include, is not something this repository documents.
Is IPED stable enough to run on a case?
The page says the opposite about its default branch, in as many words: the branch you get by cloning is the development one and is unstable, and you should check out a release tag if you want something stable. The processing side is built for stability in other ways, with out-of-process decoding and parsing so a crashing parser cannot take a case down, and options to resume or restart processing after it is stopped or aborted. Pin a tag and keep the processing options in mind.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/sepinf-inc-iped)Star history chart for your README
[](https://hysenlabs.com/projects/sepinf-inc-iped)Was this useful?