Cup checks container image updates and refuses to fire your webhooks
🥤Docker container updates made easy
At a glance
- What is it?
- A small Rust binary that diffs your running images against their registries, exposed through a CLI, a JSON API and an embedded web interface. Its own documentation is unusually blunt about what it will not do: it cannot trigger integrations, and the author points you at a different tool if that matters to you.
- Who is it for?
- Cup fits someone who wants to know what changed and then decide, since pulling the update decision back to a cronjob is exactly the behaviour most small tools get wrong by trying to be clever. Two things to check before you rely on it.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Yes. The repository last received commits 10 days ago.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 16, 2026, and from our analysis. They are not legal advice.
Star history
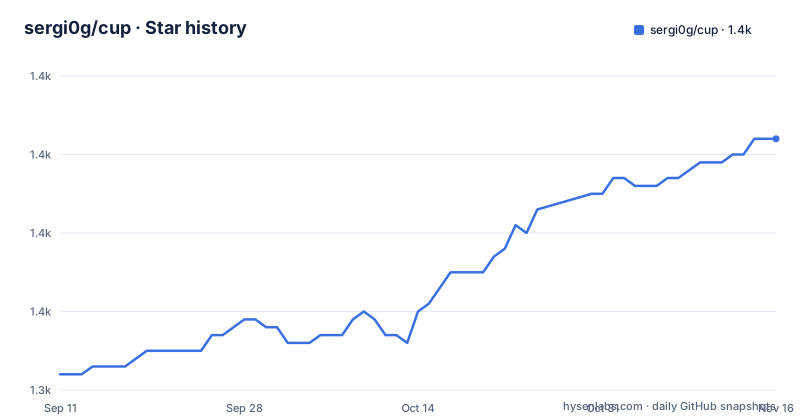
- sergi0g/cup1,372 ★ · +30
| Repository | 2026-09-11 | 2026-11-16 |
|---|---|---|
| sergi0g/cup | 1.3k | 1.4k |
30 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Checking for updates is the whole product
Cup is described as the easiest way to check for container image updates, and that narrowness is the design. It reads the images you are running, asks each registry what the current digest is, and tells you what moved. It does not pull anything, and, as the documentation says plainly, it does not trigger anything either.
The registry coverage is broad for a tool this size. Docker Hub, ghcr.io, Quay, lscr.io and Gitea are all named, with Gitea described as including derivatives. Supporting Gitea matters more than it sounds, because self-hosted forges are exactly where people run private images that no hosted registry knows about.
Two output paths are offered. There is a CLI and there is a web interface, and both emit JSON, which the README frames as the point rather than an afterthought: it is easy to parse and it makes webhooks and dashboards simple to set up. There is also a JSON Schema file at the repository root, which tells you the output is meant to be consumed by something other than a human.
The remaining features are about resource use. The author claims speed from taking full advantage of the CPU, with a stated measurement of 3.7 seconds for 58 images on a Raspberry Pi 5. The binary size is given as 5.4 MB, contrasted with pulling a 100 MB or larger image for a simple program.
The release list puts nightly above a newer version
There are three releases and their dates do not sort the way you would expect. A release named nightly is dated 2025-03-25. v3.5.0 is dated 2025-11-20 and v3.5.1 the following day, 2025-11-21.
So the rolling channel carries a date roughly eight months older than the tagged releases it is listed above. That is the signature of a tag whose creation date is recorded once and never updated, and it means sorting releases by date to find the current one picks the least informative entry. The versioned tags are the ones whose dates mean something.
The gap between the last release and the last commit is the more practical number. v3.5.1 is from November 2025 and the last push to main is 2026-07-22, so the branch carries roughly eight months of work that is not in any published tag. The manifest version is 3.5.1, which matches the newest tag rather than drifting from it, so the version you would read is the version that was released.
There is a separate question of whether you want a stable tag or the nightly channel at all. For a tool that only reports, the risk of a nightly build is lower than for one that acts, but the date field on that release is not a reliable way to tell what you got.
Cup will not trigger your integrations, and says so
The limitations section is the most useful part of the README, and it starts with an unusually direct statement: the project is a work in progress, it might not have as many features as other alternatives, and if one of those features is really important to you, please consider using another tool.
Then it names the specific gap. Cup cannot directly trigger your integrations, and if you want that to happen automatically the documentation points you at What's up Docker instead. The stated reason is that Cup was created to be simple: the data is there, and retrieving it is your job.
Two concrete ways to do that retrieval are given. Run the check command with a report flag from a cronjob, or periodically request the JSON endpoint at /api/v3/json from the running server. Both are one line of shell, which is the point: the responsibility moves to you without the work becoming complicated.
The acknowledgements section credits the same project, What's up Docker, with inspiring Cup in the first place. So the tool that inspired this one is also the recommendation for the feature it lacks, which is a candid way to handle a gap that many projects would paper over.
For a checker whose job is reporting, this is a defensible boundary. For a pipeline that needs to act, it is the wrong tool and the documentation says so before you install it.
The release profile optimizes for size, not speed
The headline feature is speed, and the release profile says otherwise. The manifest sets the optimisation level for release builds to the smallest size rather than the fastest, along with symbol stripping, abort on panic, fat link-time optimisation and a single codegen unit.
Those settings are internally consistent with one claim and inconsistent with the other. A 5.4 MB binary that ships no operating system around it is exactly what you get from optimising for size, and fat LTO with one codegen unit is expensive to build precisely because it squeezes. So the size claim is the one the build configuration supports.
The speed claim is not necessarily wrong, since a small binary also loads fast and the tool is dominated by network waits rather than arithmetic, but it is measured on the author's hardware rather than yours, and the 3.7 second figure for 58 images comes with the caveat of being one machine.
The feature flags explain part of the size story too. The default feature set includes both the server and the CLI, and the server pulls in a web framework, a templating engine, a timezone-aware date library and a cron scheduler, while the CLI adds a progress bar and a terminal size helper. The progress bar is the reason a progress bar exists in a program whose selling point is speed.
The final image is built FROM scratch
The Dockerfile is a three-stage build and the last stage has no operating system in it at all. The frontend is built first with a Bun image, the Rust binary is compiled next with a Rust image on Alpine after adding the musl development headers, and the runtime stage starts from the empty base:
### Main ###
FROM scratch

# Copy binary
COPY --from=build /cup/target/release/cup /cup

EXPOSE 8000
ENTRYPOINT ["/cup"]
The compiled frontend is copied into the source tree as a static directory before the Rust build, which is why the web interface needs no separate assets and why one binary serves both the API and the pages.
Two consequences follow from a scratch base, and both are deliberate rather than accidental. There is no shell, so you cannot exec into the container to inspect a running instance, and a problem has to be diagnosed from outside. And there is no certificate bundle, which matters for a tool whose job is making HTTPS requests to a dozen registries. Since the manifest compiles with a TLS stack that does not use the system trust store, the certificate roots must be coming from inside the binary rather than from the image, but the empty base is worth knowing about before you put this behind a private registry using a corporate certificate.
The exposed port is 8000 and the binary is the entrypoint, so there is no supervisor or init process to configure.
Retry middleware, rustls, and rate limits as the motive
The dependency list explains several of the README's claims. HTTP requests go through a retry library layered under a middleware crate, which is how the tool survives a registry returning a transient error without reporting a false negative as a real update. HTTP authentication is a direct dependency, which is what allows private registries to be checked.
The TLS stack is chosen rather than defaulted. The HTTP client is configured with default features disabled and the rustls backend enabled, so the binary does not link the system OpenSSL. That is a deliberate consequence of the scratch base image: there is no system library to link against, so a pure-Rust TLS implementation is what makes the empty runtime possible.
The stated origin story is rate limits. The author says not exhausting rate limits was the original reason for creating Cup, and links to Docker Hub's documentation about reducing pull limits for unauthenticated users. That reframes the project: it is a tool for learning what changed without consuming the quota you would spend by pulling everything speculatively.
That also explains the architecture. Checking digests is cheap compared to pulling layers, and the output is JSON so the expensive action, updating, happens in your own pipeline on your own schedule.
Both base image tags float
The Dockerfile pins the manifest and the lockfile into the build stage, copying them before the source, which is the right order for caching and keeps dependency resolution locked. The base images, however, are both on floating major tags rather than pinned digests: a Bun image on the 1-alpine tag for the frontend and a Rust image on 1-alpine for the backend.
That means two builds of the same commit can resolve to different toolchains, which is the standard reproducibility gap in a Docker build and the reason the ecosystem has moved toward digest pinning. For a utility binary the consequence is a build that might fail or produce different output over time rather than a silently different program, which is a milder version of the problem.
The Alpine base for the Rust stage is paired with an explicit install of the musl development headers, which is the correct fix for linking against a musl target rather than glibc. The frontend stage copies its own package manifest and lockfile before running the install, so the JavaScript dependencies are cached the same way.
The repository is small and conventional otherwise. A source directory, a web directory, a documentation directory, a screenshots directory, a build script, a licence, and the JSON Schema at the root. There is one binary crate with the server and CLI as feature flags rather than separate crates, which is a reasonable size for a tool this focused.
Editorial conclusion
Cup fits someone who wants to know what changed and then decide, since pulling the update decision back to a cronjob is exactly the behaviour most small tools get wrong by trying to be clever. Two things to check before you rely on it. Cup will not trigger your integrations, so you need a scheduled job calling the CLI or the JSON endpoint, and the author names the alternative to use if you want that handled for you. And note the newest release is from November 2025 while main was last touched in July 2026, so what you build against is whichever build you pin, not the tip of the branch.
Frequently asked questions
Which registries does Cup check?
Cup supports most registries, naming Docker Hub, ghcr.io, Quay, lscr.io and Gitea, with the note that Gitea derivatives are covered as well.
Can Cup update my containers automatically?
No. The documentation states that Cup cannot directly trigger your integrations and recommends What's up Docker if you need that. You retrieve the data yourself, for example with a cronjob running the check command with a report flag, or by requesting the /api/v3/json endpoint from the server.
How does Cup avoid Docker Hub rate limits?
Not exhausting rate limits is described as the original reason the project was created. Cup checks image digests rather than pulling layers, and the author links to Docker Hub's documentation on reduced pull limits for unauthenticated users.
Does Cup have a web interface?
Yes, alongside the CLI, and both emit JSON output so Cup can feed integrations. The frontend is built with Bun during the image build and compiled into the binary as static assets, and the runtime image starts from scratch with only the binary inside.
What is the newest Cup release?
The versioned releases are v3.5.0 from 2025-11-20 and v3.5.1 from 2025-11-21. A rolling release named nightly carries a date of 2025-03-25, which is older than both, so sorting releases by date does not identify the current build.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/sergi0g-cup)Star history chart for your README
[](https://hysenlabs.com/projects/sergi0g-cup)Was this useful?