The concept table is a version ledger, and its memory row is scoped per user rather than per project
from vibe coding to agentic engineering - practice makes codex perfect
At a glance
- What is it?
- A reference repository for a command line coding agent, built as one table pairing each feature with the file that configures it. The rows carry their own version requirements rather than a single minimum, and the memory row states in a parenthetical that its scope is the user, not the project.
- Who is it for?
- This is an index with local examples, and both halves are worth using differently. The definitions are the vendor's, so a reader who wants to know what a feature does should read the documentation it links to.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 164 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
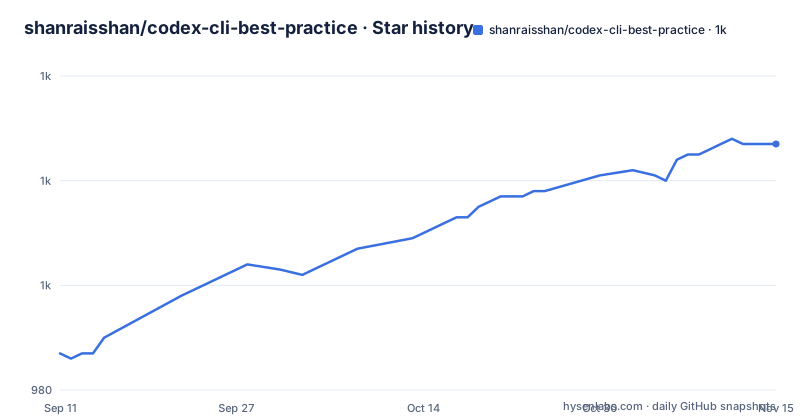
- shanraisshan/codex-cli-best-practice1,027 ★ · +40
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| shanraisshan/codex-cli-best-practice | 987 | 1k |
40 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Each row carries its own version, and no row states a minimum
The table has three columns: a feature, the location that configures it, and a description. The versions live inside the descriptions, one per row, and they do not agree with each other.
Cross-session memory is marked as arriving in one release and needing a feature flag in a configuration block before it does anything. The plugin marketplace is marked as arriving in a later one. An option on the model context protocol side, per-server parallel tool calls, is marked as later again. A later row marks protection of archived threads from being resumed as later still, and another marks searching your local conversation history as arriving before that.
So the table spans a range of releases rather than describing one. The consequence is that it cannot answer the question a new reader arrives with, which is which version do I need. Nothing in the table states a floor, and nothing in the table says which rows will fail silently on an older build.
There are also two feature flags alongside the version numbers. Memories need one flag enabled, and hooks need another. Both are described as switches rather than as defaults, which means both are off until you turn them on, and both change what the tool can do rather than only what it shows.
The last line in the table is a pointer to a report on agentic engineering, context engineering and vibe coding that lives in a different repository by the same author. So even the conceptual framing is maintained elsewhere.
Memory is scoped to the user, so one project teaches the next
One row contains the most consequential fact in the table, and it is in parentheses at the end of the description.
Memory is stored in a directory under the user's own configuration home, not in the project. The scope is described as per-user, not per-project.
That is a blast-radius statement, and the direction of the leak matters. If you spend an afternoon teaching a session the conventions of one codebase, those corrections are in a directory that the next project reads. Projects with different clients, different data handling rules, or different owners of the code all share one memory store, and nothing in the row suggests any partitioning.
The controls that are named are three verbs on a control in the interface: use, generate, and reset. So the model for correcting a bad memory is to clear it, not to scope it.
Two more details from the same row. There is a per-thread toggle whose state is kept in a state database, which means the on or off setting is remembered outside the conversation that made it. And enabling the feature needs both a feature flag and a configuration block, so there are two things to set rather than one.
For a tool that keeps prose permanently and acts on it, the scope is the thing to decide before turning it on, not after.
Fast mode is one and a half times the speed for twice the credits
The performance row is a pricing row, and the table is unusually straightforward about it.
Fast mode is described as giving about one and a half times the speed for twice the credits, on a named model version, toggled with a slash command that takes on, off, or status. The ratio is the point. A reader could easily take the speed number as a free improvement, and the row is careful to put the credit multiplier next to it in the same phrase.
The second half of the row names a different model for near-instant iteration and attaches a subscription requirement to it. So there are two separate fast paths with two separate conditions: one costs more credits on an existing model, and the other requires a particular subscription tier.
Neither is described in terms of what the speed is for, and neither comes with a measurement. A table of this kind could easily have claimed a throughput figure, and did not, which makes the credit multiplier the only number in the row and therefore the number a reader will actually use.
Worth pairing with the review row, which mentions a configurable review model in the configuration file and custom review instructions. A separate model for review is the same idea as a separate model for speed, and the table treats both as configuration rather than as defaults.
Two governance mechanisms with different failure modes: a context cap and a command policy
Two rows control what the tool may do, and they fail in opposite ways.
The command policy lives in a rules directory and is written in a Python-like configuration language, not in a data format. A prefix rule function produces one of three decisions for a command, allow, prompt, or forbidden, and matching is on the exact prefix. There is a command to check a policy file, which means the policy can be tested without running an agent against it. The row notes that these rules work alongside the granular approval settings and the approvals a user manages, so the two are additive rather than alternatives.
The project context file works differently. It is discovered hierarchically from the current directory up to the repository root, and it is capped: a configuration value limits how much of it is read, in the low tens of kilobytes. There is also a separate override file for personal settings, so a person can add instructions without editing a file the repository tracks.
The failure modes are opposite. A command policy that is too broad admits something; one that is too narrow blocks ordinary work, and the exact-prefix matching means a command that differs by one argument is a different command. A context file that exceeds its cap is truncated, silently, and a truncated instruction file is a set of instructions that stop halfway.
Neither of those failure modes is reported in the table, so the two rows are best read as a pair: one bounds what can run, the other bounds what can be read, and both bounds are invisible from the outside.
Hooks are arbitrary shell in the loop, and they sit behind a flag
The hooks row describes the largest privilege in the table.
A hook is a shell script you write, placed in a JSON file, and it is injected into the agentic loop. The listed uses are logging, security scanning, validation, and custom automation. Every one of those is reasonable. Together they mean the mechanism has no restriction of its own: whatever a shell script can do on the machine, a hook can do at every step of a session.
Two things shape that. The feature is behind a flag, so it is off until enabled, which means a fresh install is not running anyone's scripts. And the row links out to a separate repository by the same author containing the hook implementations, so the examples are readable before you copy them.
The pattern is standard for tools that want an extension point, and the risk is the standard one: a hook that is a logging call today can be a network call tomorrow, and the file that changed is a JSON entry rather than a dependency bump, so it does not show up in a review of what was installed.
Placed next to the command policy row, the picture is coherent. Policy decides which commands may run; hooks are the trusted code that observes and mediates. The assumption is that the person writing the hooks is you, which is true and is the whole of the security model.
Almost every row is a link to the vendor's own documentation
The honest characterisation of this repository is a curated index with local examples attached.
Look at where the links in the table go. Commands, subagents, skills, plugins, marketplaces, memories, workflows, the model context protocol, configuration, rules, project instruction files, hooks, speed, review, sessions, and best practices: seventeen rows, and essentially all of them point at the vendor's documentation site. The local links are the exceptions. They are the example agent files, the example configuration file, the skills directory, the plugin manifest path, the project instruction file, and the practice notes this repository writes itself.
So the value proposition has two parts and they are not equally strong. Reading what a feature does, the documentation is better and will be more current. Knowing which file turns it on, and having a working example of that file, is what this repository adds, and that is the part you would otherwise assemble by hand across a dozen documentation pages.
Three small signals in the file are worth noting because they suggest it is assembled quickly rather than carefully. The badge row at the top renders as broken text, because the image URLs lost their prefix and only the query string survived. The declared homepage is a personal professional profile rather than a site for the project. And the row labelled for conceptual framing points to a report in a different repository entirely.
The root holds a directory for the competing tool and an entry named with punctuation
The tree is short and two entries in it are informative.
There is a directory for one coding agent's configuration and a directory for another's, sitting side by side at the root, along with a shared directory that holds the skills. So the same material is maintained twice, once per tool, and the practice notes exist in parallel with it. That is a maintenance cost the repository has chosen to carry, and it is a reasonable one if you use both, and a waste if you use either.
The second entry is a directory whose name is a punctuation mark and a slash. There is no plausible reading of that as a directory a person created, and it is almost certainly something that expanded in a shell and got committed. It sits at the top level of a repository whose other nineteen entries are all deliberate, which means whatever produced it ran in a context where nobody was looking at the output.
One more metadata observation, since it bears on what you can expect to find. The platform records this repository's primary language as Python. The visible contents are configuration files, Markdown, JSON, hooks in shell, and examples for continuous integration and for profiles. There may be tooling in the repository that the listing does not show, but nothing in the visible tree explains that language tag.
And the release history is empty. There are no tagged releases at all, and the default branch was last pushed in early June 2026, four months before the newest tool version referenced in the table was current.
Editorial conclusion
This is an index with local examples, and both halves are worth using differently. The definitions are the vendor's, so a reader who wants to know what a feature does should read the documentation it links to. What the repository adds is the pairing between feature and file, which is genuinely hard to reconstruct from documentation, plus example configurations you can copy. One line in that pairing deserves more attention than the rest. Cross-session memory is scoped to the user rather than the project, so a correction you teach a session in one repository is available in another, and the only controls named are the commands that use, generate and reset it. If your work spans repositories with different clients or data handling, read that before enabling the flag. The other thing to hold onto is that the rows carry version requirements individually across many releases of a fast-moving tool, so treat the table as current to the date of its newest row and not as a description of whatever build you have installed.
Frequently asked questions
What is codex-cli-best-practice?
A reference repository for the OpenAI Codex command line tool, built as a table pairing each feature with the location that configures it, plus local example configurations, practice notes and an orchestration workflow. Almost every row links to the vendor's own documentation, so the repository's own contribution is the feature-to-file mapping and the working examples.
What is the difference between a Codex skill and a Codex subagent?
A subagent is a TOML file registered under an agents section with a dedicated role configuration, and the global settings cover maximum threads, maximum depth, and a per-job runtime cap; three are built in, named default, worker and explorer. A skill is a directory whose SKILL.md carries required name and description metadata, with optional scripts, references and assets, invoked either explicitly by name or implicitly by description match.
Where does Codex store memory, and is it shared between projects?
In a directory under the user's Codex home, and the table states its scope is per-user rather than per-project. It is enabled with a feature flag and a configuration block, controlled in the interface with use, generate and reset, and has a per-thread toggle persisted in a state database. Because the scope is the user, memory learned in one repository is available in another.
How does Codex enforce command execution policy?
With rules files written in a Python-like configuration language that use a prefix rule function to return allow, prompt or forbidden for a command, matched on exact prefixes. There is a command to check a policy file without running an agent, and these rules work alongside the granular approval policy settings rather than replacing them.
Is Fast Mode in Codex free?
No. The table states Fast Mode gives about 1.5 times the speed for twice the credits, toggled with a slash command, on a named model version. A separate model is listed for near-instant iteration and carries a subscription requirement, so the two fast paths have two different conditions.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/shanraisshan-codex-cli-best-practice)Star history chart for your README
[](https://hysenlabs.com/projects/shanraisshan-codex-cli-best-practice)Was this useful?