Kronos turns K-line bars into discrete tokens, then samples a price path from them
Kronos: A Foundation Model for the Language of Financial Markets
At a glance
- What is it?
- Kronos is a MIT-licensed, decoder-only foundation model for financial candlestick sequences, released as a Hugging Face tokenizer and checkpoint pair. It is a forecasting library with a two-stage design and some sharp edges around context length and sampling.
- Who is it for?
- Kronos suits researchers who already hold clean OHLCV frames and want a forecast to study, and the tokenizer plus checkpoint pairing is the first thing to understand. It is the wrong tool for execution: the predictor emits prices rather than orders, the 512 token ceiling applies on the small and base checkpoints, with longer input truncated automatically, and the 499.2M model is not published.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 7 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
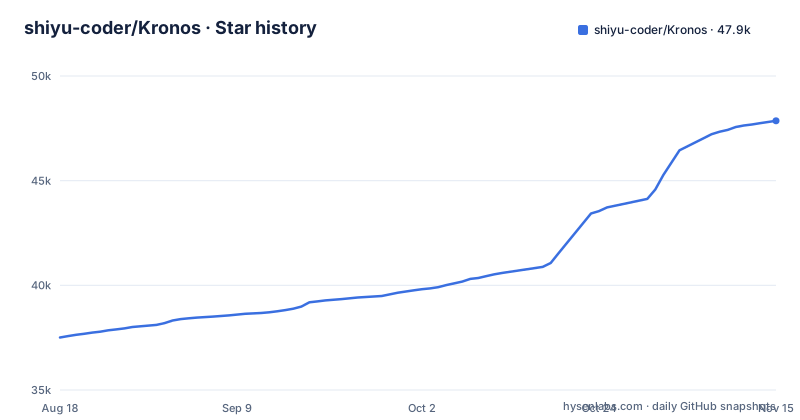
- shiyu-coder/Kronos47,862 ★ · +10,355
| Repository | 2026-08-18 | 2026-11-15 |
|---|---|---|
| shiyu-coder/Kronos | 37.5k | 47.9k |
10,355 Stars in the last 89 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
A tokenizer absorbs the noise before any learning happens
The pipeline runs in two stages and the first one is not optional. A specialized tokenizer quantizes continuous, multi-dimensional K-line data, meaning the OHLCV values, into hierarchical discrete tokens, and a large autoregressive Transformer is then pre-trained on those token sequences. The architecture is decoder-only, and the stated difference from general-purpose time series foundation models is the data itself: Kronos is designed to handle the high-noise characteristics of financial data, and the tokenizer quantizes the bars before the Transformer is pre-trained. For you this means the model never ingests a raw float the way a regression would. Every price on the forecasting path has already been quantized, and the tokenizer is a separate artifact you load by name rather than a layer inside the model, so the two are versioned independently.
Every checkpoint is welded to one named tokenizer
The Model Zoo table binds each checkpoint to one tokenizer repository and one context length. Kronos-mini pairs a 2k tokenizer with a 2048 context at 4.1M parameters. Kronos-small and Kronos-base both use the base tokenizer with a 512 context, at 24.7M and 102.3M parameters. Kronos-large reaches 499.2M parameters but its open-source cell is empty, so the largest model listed is not released. Any plan that assumed starting small and scaling up stops at base. The pairing also removes a degree of freedom you might expect to have: the tokenizer name in your loading code is fixed by the checkpoint you picked.
from model import Kronos, KronosTokenizer, KronosPredictor

# Load from Hugging Face Hub
tokenizer = KronosTokenizer.from_pretrained("NeoQuasar/Kronos-Tokenizer-base")
model = Kronos.from_pretrained("NeoQuasar/Kronos-small")

# Initialize the predictor
predictor = KronosPredictor(model, tokenizer, max_context=512)
Longer lookbacks get cut without anything in the result saying so
The README puts max_context for Kronos-small and Kronos-base at 512, calls it the maximum sequence length the model can process, and recommends that your input data length, meaning the lookback, not exceed that limit. It also states that KronosPredictor will handle truncation automatically for longer contexts. That automatic behavior is the part to plan around. The worked example feeds 400 bars, but a longer history is shortened automatically. If your edge depends on long memory, a multi-session pattern or a slow regime shift, the count of surviving bars is the first number to measure rather than assume.
sample_count of one means there is no distribution to read
predict accepts three sampling controls: T for temperature, top_p for nucleus sampling probability, and sample_count for the number of forecast paths to generate and average. The example runs T=1.0, top_p=0.9, and sample_count=1, and a count of one means there is nothing to average, so the frame you get is a single stochastic draw rather than a central tendency. Temperature is left at the value the example chose, so two calls on identical inputs need not agree with each other. To see spread you must raise sample_count yourself and compute the average and the dispersion downstream, because the method returns prices and not a distribution over them.
# Generate predictions
pred_df = predictor.predict(
    df=x_df,
    x_timestamp=x_timestamp,
    y_timestamp=y_timestamp,
    pred_len=pred_len,
    T=1.0,          # Temperature for sampling
    top_p=0.9,      # Nucleus sampling probability
    sample_count=1  # Number of forecast paths to generate and average
)
Four columns are mandatory and the failure mode is undocumented
predict takes three inputs: a pandas DataFrame named df, a Series named x_timestamp aligned to that history, and a Series named y_timestamp covering the future periods you want. The DataFrame must include the columns ['open', 'high', 'low', 'close']. volume and amount are optional, and the repository ships examples/prediction_wo_vol_example.py, which, going by its name, runs without volume. Because those columns are optional, two runs over the same instrument can differ in what the model was permitted to see.
The output is a price frame, never a position
Read what the example actually does with the result: it assigns the return of predict to pred_df and prints the head. There is no order placement, no position sizing, no fee or slippage model, and no broker integration on that path. The repository does ship examples/run_backtest_kronos.py, so some form of evaluation harness exists, but the predictor itself stops at a price frame. The horizon is whatever you put into y_timestamp: the bundled walkthrough reads ./data/XSHG_5min_600977.csv, sets lookback to 400 and pred_len to 120, and slices the future timestamps out of that same frame. Turning the forecast into a real fill is code you write yourself.
requirements.txt names pandas twice and leaves torch open ended
The dependency file names pandas on one line and then pins pandas==2.2.2 further down, so pip resolves the duplicate to 2.2.2 and the loose line tells you nothing you can act on. numpy carries no version at all, and torch is bounded only from below by 2.0.0, which is the loosest edge in the file since a new torch release can move underneath a hub client pinned to an exact release. The hard pins are einops==0.8.1, huggingface_hub==0.33.1, matplotlib==3.9.3, tqdm==4.67.1, and safetensors==0.6.2. Installation is Python 3.10 or newer followed by a clone, and the repository publishes no GitHub releases. A script written against a newer hub feature will not run in this environment without editing the pin.
pip install -r requirements.txtTwo fine-tuning directories, and a news log that stops early
The news entry dated 2025.08.17 announces that scripts for fine-tuning have been released, and the repository tree carries two sibling directories for that work, finetune/ and finetune_csv/, alongside a webui/ directory and a tests/ directory. Two directories for one task means the names alone do not tell you which to pick, and the news entry says nothing about the data format either one expects. The examples/ directory holds ten scripts and a yuce/ subdirectory, among them a matched pair for Chinese data, get_akshare_date_2024-2025_x.py and prediction_akshare_2024-2025.py, plus several prediction variants. The last push to master is dated 2026-04-13 while the newest news entry is dated 2025.11.10, so whatever landed in between is not described in the log.
Editorial conclusion
Kronos suits researchers who already hold clean OHLCV frames and want a forecast to study, and the tokenizer plus checkpoint pairing is the first thing to understand. It is the wrong tool for execution: the predictor emits prices rather than orders, the 512 token ceiling applies on the small and base checkpoints, with longer input truncated automatically, and the 499.2M model is not published. Before trusting one run, count how many bars survived truncation, raise sample_count above one to see spread, and confirm which tokenizer the checkpoint was trained with.
Frequently asked questions
What is Kronos software used for?
Kronos is a family of decoder-only foundation models pre-trained on K-line sequences from over 45 global exchanges. A tokenizer quantizes OHLCV data into hierarchical discrete tokens, and an autoregressive Transformer is then trained on those tokens for quantitative forecasting tasks. Released checkpoints range from 4.1M to 102.3M parameters; the 499.2M Kronos-large is not open-sourced.
how to install kronos
Install Python 3.10 or newer, then install the dependencies from the repository requirements file. The repository publishes no GitHub releases, so setup is cloning and installing from requirements.txt. Model weights are pulled separately from the Hugging Face Hub.
how to use kronos
Load a tokenizer and a checkpoint with KronosTokenizer.from_pretrained and Kronos.from_pretrained, then pass both to KronosPredictor with a max_context value. Call predict with your bar DataFrame, an x_timestamp Series, and a y_timestamp Series covering the horizon you want. The class handles preprocessing, normalization, and the inverse step.
how to use kronos ai
The worked example uses lookback of 400 bars and pred_len of 120, and calls predict with T=1.0, top_p=0.9, and sample_count=1. Your DataFrame must include the columns ['open', 'high', 'low', 'close'], with volume and amount optional. The result is a DataFrame of predicted values.
how to install kronos ai
requirements.txt pins pandas at 2.2.2, einops at 0.8.1, huggingface_hub at 0.33.1, matplotlib at 3.9.3, tqdm at 4.67.1, and safetensors at 0.6.2, while numpy is unversioned and torch requires 2.0.0 or newer. Weights are not distributed through a package index; the checkpoints and tokenizers live on the Hugging Face Hub under the NeoQuasar organisation.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/shiyu-coder-kronos)Star history chart for your README
[](https://hysenlabs.com/projects/shiyu-coder-kronos)Was this useful?