R8 metadata recovery, and a PowerShell port that is still experimental
Claude Code skill to support Android app's reverse engineering
At a glance
- What is it?
- This repository is a Claude Code plugin, distributed through a one-entry marketplace, that turns an Android APK, XAPK, JAR or AAR into a decompiled tree and then extracts the HTTP APIs from it. Its distinctive claim is Kotlin name recovery: R8 renames the JVM symbols but leaves the Kotlin metadata strings behind, so the original class names can be rebuilt. Its Windows scripts arrived as a community contribution and are labelled experimental.
- Who is it for?
- Take this skill when you hold an Android build artefact and no source, and you need its endpoints, auth headers and call flows documented rather than guessed. Leave it if you have the source, and leave it if you want a general purpose decompiler, because this is a workflow around jadx, Fernflower and Vineflower rather than a decompiler of its own.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 33 days ago.
- What is it written in?
- Mainly Shell, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
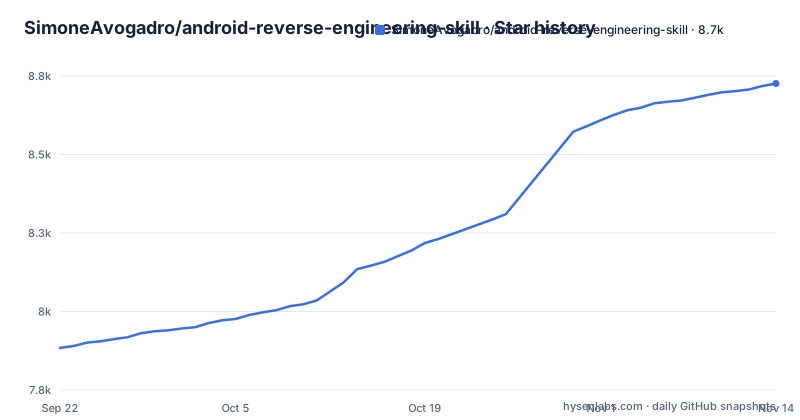
Star history
- SimoneAvogadro/android-reverse-engineering-skill8,718 ★ · +834
| Repository | 2026-09-22 | 2026-11-13 |
|---|---|---|
| SimoneAvogadro/android-reverse-engineering-skill | 7.9k | 8.7k |
834 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
It is a Claude Code plugin, and a decompiler is not in this repository
The first thing to establish is what this codebase is. It is not a decompiler and it contains no decompiler.
It is a Claude Code skill: a packaged workflow that the agent loads and follows. The top level of the repository is .claude-plugin/, LICENSE, PRIVACY.md, README.md, THIRD_PARTY_NOTICES.md, plugins/ and a .gitattributes, so the whole thing is a plugin marketplace with one entry in it rather than a tool with an executable.
The decompilers are external and named in the Requirements section. jadx is required, listed as a CLI. Vineflower or Fernflower are optional and recommended, with the stated reason that they produce better output on complex Java code. And dex2jar is optional, needed specifically to use Fernflower on APK and DEX files, which is the step people usually discover by failing.
So the division of labour is: jadx gets you from DEX to Java, Fernflower or Vineflower gives you a second opinion on the Java, and dex2jar is the bridge that lets the second opinion see the original DEX. The skill supplies the workflow, the triage and the extraction around them.
That is a narrower claim than a decompiler makes, and it is the claim the README actually supports.
Phase 0 fingerprints the APK before anything is decompiled
The first capability in the What it does table is called Fingerprint first and is marked Phase 0, which tells you it runs before the real work.
Its description is triage an APK or XAPK in seconds: detect the framework, which is listed as Flutter, React Native, Cordova, Xamarin or native-Kotlin, then the HTTP stack, then the obfuscation level and native libs, all before spending time on a full decompile.
That ordering is the useful part and it is a practical one. A Flutter build decompiled as Java gives you a Dart-shaped stub library. A React Native build gives you a bridge. Knowing which of those you have before you read a single decompiled file is the difference between five minutes and an afternoon.
The native libs in that list are the other half, because a build with a large .so payload is telling you that the interesting logic is not in the DEX at all, and no amount of Kotlin name recovery will find it.
The repository structure calls the core file SKILL.md and annotates it as the core workflow spanning Phase 0 to Phase 5. So the fingerprint is phase zero of six.
R8 cannot strip Kotlin metadata, and that is the whole Kotlin story
There is a dedicated section explaining one mechanism, and it is the reason this skill exists rather than being a wrapper around jadx.
Most real-world Kotlin and KMP apps ship through R8, so the decompiled classes come out as a.b.c. R8 renames the JVM symbols but cannot strip the Kotlin metadata strings, because the Kotlin runtime, through reflection and coroutines, needs the original fully-qualified names at runtime. This skill mines the @DebugMetadata and @Metadata annotations to rebuild an obfuscated-to-real class name map.
The recovery claim is specific: on a typical app it recovers around 100 percent of the *Repository, *ViewModel, *UseCase and *Impl classes that you actually want to read. Note that the claim is scoped by suffix. R8 keeps the class names it has to keep and renames the rest, so the patterns you care about are the ones that survive or the ones the metadata can restore.
The output is three artefacts under a directory you name: mapping.tsv, mapping.json and a by_package/ subdirectory. Two scripts do the work, one builds the mapping from the decompiled sources and one queries it, and the query script takes a real class name so you can go the other way from a name you remember to the obfuscated symbol in the code.
The API list covers Ktor, Apollo and Koin, not just Retrofit
The extraction row in the capability table has an unusual emphasis on what it includes, with the modern stack set in bold.
It covers Retrofit, OkHttp and Volley, and then it says and modern Kotlin and KMP stacks: Ktor, Apollo for GraphQL, and Koin dependency injection. The output is listed as endpoints, hardcoded URLs, auth headers, tokens and HMAC request-signing schemes.
That last item is the one that changes the value of the exercise. Finding the base URL of an API tells you where to send a request. Finding that requests are signed with an HMAC over specific fields tells you whether a request you captured can be replayed, and which fields you cannot change.
The call-flow row is the other half of the output. Tracing call flows means going from Activities and Fragments through ViewModels and repositories down to the HTTP call, so the report is a path rather than a list of strings. And there is a row for handling obfuscation, described as R8-resistant path and URL extraction plus strategies for navigating ProGuard and R8 output.
The table also has rows for analysing structure, covering the manifest, packages and architecture patterns, and for decompiling, which names jadx and Fernflower or Vineflower with the option of a single engine or a side-by-side comparison.
Windows support arrived as a community contribution and is labelled experimental
The second callout at the top of the README is about platform coverage and it is unusually explicit.
The PowerShell support is marked experimental. The *.ps1 scripts alongside the bash ones are described as a recent community contribution that is still being stabilised. For any issues you are asked to open an issue on this repository rather than on the contributors' upstream forks, and the PowerShell scripts are maintained here by the repository owner.
That last clause is the whole point of the callout. A community contribution that arrived with its own fork usually keeps living in that fork, and a bug report filed against the wrong repository goes nowhere. Naming the canonical repository in the README is the difference between a contribution being adopted and a contribution being stranded.
It also tells you where the maintenance burden sits. The bash scripts and the skill workflow are the original author's; the Windows path is somebody else's code that this repository now carries.
For a user, the practical reading is that the bash scripts are the supported path and the PowerShell ones are usable but not yet something to depend on in a pipeline.
Six phases, per-tool reference docs, and a marketplace with one entry
The repository structure is short enough to read in full and it explains the packaging.
At the top there is .claude-plugin/ containing marketplace.json, described as the marketplace catalog. Under plugins/ there is android-reverse-engineering/, which has its own .claude-plugin/plugin.json as the plugin manifest, and under that skills/android-reverse-engineering/ where SKILL.md sits as the core workflow covering Phase 0 to Phase 5, beside a references/ directory.
So there are two manifest files and one skill document. Installation is two slash commands rather than a package manager.
The references directory is where the real documentation lives, and the visible names include setup-guide.md, jadx-usage.md, fernflower-usage.md and an api-extraction file. That is a sensible split for a skill that wraps three external tools, because each of those tools has its own options and its own version differences, and duplicating them into the skill body would make the skill wrong the moment any of them moved.
The setup-guide is also the installation reference the Requirements section points to for detailed instructions.
One release, and two slash commands to install it
Installation from GitHub is the recommended route and it is two lines typed into Claude Code:
/plugin marketplace add SimoneAvogadro/android-reverse-engineering-skill
/plugin install android-reverse-engineering@android-reverse-engineering-skill
The README states one consequence of doing that: the skill will be permanently available in all future sessions. There is no per-invocation install.
The alternative is a local clone:
git clone https://github.com/SimoneAvogadro/android-reverse-engineering-skill.gitafter which the marketplace add takes a filesystem path instead of the repository name, and the plugin install line is identical. That route exists for people who want to read or edit the skill, and it is the only one that lets you change the workflow rather than use it.
Once installed there are three ways to invoke it. A slash command takes a path:
/decompile path/to/app.apkwhich runs the dependency check, the decompilation and the initial structure analysis. Or it activates on plain language, with examples given as Decompile this APK, Reverse engineer this Android app, Extract API endpoints from this app, Follow the call flow from LoginActivity and Analyze this AAR library. Or the shell scripts run standalone, which is how you would use this in CI or from another tool:
bash plugins/android-reverse-engineering/skills/android-reverse-engineering/scripts/check-deps.shwith an install-dep.sh script beside it that auto-detects the OS and package manager and will install jadx or vineflower for you.
The repository has a single release, v1.1.0 from 2026-04-27, and the last push to master was on 2026-10-12.
Editorial conclusion
Take this skill when you hold an Android build artefact and no source, and you need its endpoints, auth headers and call flows documented rather than guessed. Leave it if you have the source, and leave it if you want a general purpose decompiler, because this is a workflow around jadx, Fernflower and Vineflower rather than a decompiler of its own. Verify three things. Run the dependency check script before anything else, since a Java JDK of 17 or later and the jadx CLI are required, and dex2jar is needed before Fernflower can read a DEX file at all. Expect two decompilers in play, because the skill runs jadx and Fernflower or Vineflower either singly or side by side for comparison. And check the platform before you plan the work, because the PowerShell scripts are marked experimental and issues for them are asked to go to this repository rather than to the contributors' upstream forks.
Frequently asked questions
What is reverse engineering in Android?
In this project's framing it is decompiling a built artefact and reading what the app does with the network. The skill decompiles APK, XAPK, JAR and AAR files with jadx and Fernflower or Vineflower, then extracts Retrofit, OkHttp, Volley, Ktor, Apollo and Koin endpoints along with hardcoded URLs, auth headers, tokens and HMAC request-signing schemes, and traces call flows from Activities through ViewModels down to the HTTP call.
What are reverse engineering skills?
A Claude Code skill is a packaged workflow an agent loads and follows. This one is installed with two slash commands, /plugin marketplace add and /plugin install, and once installed the README says it is permanently available in all future sessions. It activates on plain phrases such as Decompile this APK or Extract API endpoints from this app, or on the /decompile slash command with a file path.
Is it illegal to reverse engineer an app?
The README includes a Disclaimer section, which is the place to check. What it does state is the purpose: to document and reproduce the HTTP APIs an app uses without the original source code. The code is Apache-2.0 licensed.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/simoneavogadro-android-reverse-engineering-skill)Star history chart for your README
[](https://hysenlabs.com/projects/simoneavogadro-android-reverse-engineering-skill)Was this useful?