skfolio: a reStructuredText readme that is half an include for the docs site
Python library for portfolio optimization built on top of scikit-learn
At a glance
- What is it?
- skfolio is a portfolio optimisation library that presents itself as a scikit-learn estimator, with sixteen example directories, a machine-readable documentation convention and a commercial entity behind the maintainers. The readme is written in reStructuredText and partly generated into the site.
- Who is it for?
- skfolio is worth a look if you build portfolio models inside a machine-learning pipeline, because the fit, transform and cross-validation interface means you get model selection and parameter tuning from the ecosystem you already use, and the prior estimators cover the shrinkage and factor-model territory that plain mean-variance gets wrong. Two things to weigh.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
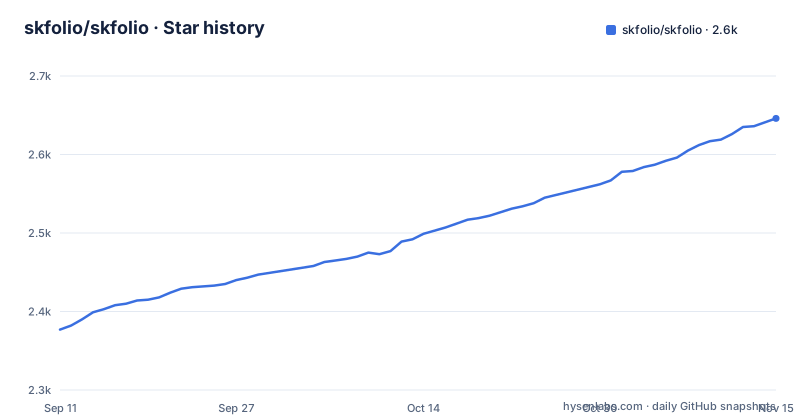
- skfolio/skfolio2,646 ★ · +269
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| skfolio/skfolio | 2.4k | 2.6k |
269 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The readme is reStructuredText and half of it is an include
The file at the root is not Markdown, and the choice is not incidental. It is reStructuredText, which is what scikit-learn itself uses, and the first comment in it is an instruction to maintainers: regions delimited by paired start and end markers are included verbatim in the documentation index, those markers must not be renamed or removed, and anything placed outside them stays in the readme alone. So parts of the file you read on the repository host are generated into the site, and a careless edit can silently do nothing or break the site build. The naming convention for those markers is project-prefixed, which is what stops a documentation tool from mistaking them for anything else.
Thirteen badges, and two of them depend on somebody else's server
The badge row is thirteen entries long and mostly static, but three are worth naming. The coverage badge carries a token in its query string, which is the usual shape for a coverage service's read-only credential and is committed in a public URL. The project website badge is not an image at all: it asks a third-party uptime service to check the documentation site and return an up or down marker, so the badge is only as reliable as that service. And the linter badge fetches a JSON file out of the linter's own repository at render time. The rest are ordinary: licence, supported Python versions from 3.10 to 3.14, package index, release workflow, download count, contributions welcome, a hosted notebook environment, a chat invite and a DOI.
The documented install command is an upgrade command
The installation section is four lines. It states a minimum Python version through a substitution marker rather than typing the number, gives one command, and points at a guide for everything else. The command carries an upgrade flag, which tells you the project expects people to be reinstalling over an existing copy rather than installing once. What the short version deliberately leaves out is more interesting than what it says: the full dependency list, the conda-forge route, and the mixed-integer solvers. That last one matters, because an optimiser that has to choose between real continuous weights and a discrete allocation needs a solver, and whether your install actually got one is the first thing to check when a model fails to converge.
You can read one documentation page at a time by appending a suffix
The readme has a section aimed at automated readers, and the mechanism is worth copying. It follows a published convention with an index file listing the pages, a full single-file dump for when you genuinely need everything, and then the trick that makes partial reading possible: append a suffix to any documentation page's address to get the Markdown source of just that page. The example given turns a page ending in an HTML extension into one ending in the HTML extension plus a Markdown one. So an agent or a script can locate a page through the index, fetch only that page as text, and never load the other four hundred pages to answer a question about covariance estimation.
Sixteen example directories, three of them about the estimator API
The examples tree is the clearest statement of what this library thinks it is. Fifteen directories plus a readme, and the first seven are portfolio models a finance reader would expect: mean-risk, risk budgeting, maximum diversification, a tail-risk variant built to be robust to distribution shift, clustering, ensembles and entropy pooling. Then there are directories for factor models, data preparation, model selection, synthetic data for stress testing, and three that are not finance concepts at all: one for the estimator metadata-routing feature, one for online learning, and one for pre-selection. Those three exist because the library is meant to drop into a machine-learning pipeline, and the examples double as documentation for that integration.
Forty-six descriptors across seventeen families, and a prior you can choose
The distinguishing feature is the prior estimator, because the library's whole argument starts from mean-variance optimisation's known weaknesses: sensitivity to the expected returns and covariance you feed it, weight concentration, high turnover, and poor performance out of sample, to the point that naive allocations often beat it. So the library offers alternatives at every layer rather than one model. The portfolio models are grouped as naive, convex, clustering and ensemble. The priors run from the plain empirical estimate through a cross-sectional factor model built on 46 descriptors spanning 17 families, value, size, momentum and profitability among them, through a time-series factor model, the Black-Litterman view, entropy pooling and opinion pooling, plus a synthetic-data generator for stress tests.
Three maintainers, one commercial entity, nineteen classifiers
The manifest is where the shape of the project shows. Three people are listed as maintainers and one as author, and the first maintainer's email is at the commercial entity rather than at a personal domain, which tells you who is employed by whom. That entity is named in the readme too, offering enterprise support and service-level agreements for institutions, while the library itself is under a three-clause BSD licence, so the paid part is support and not features. The classifier list runs to nineteen entries, including an intended audience for the financial and insurance industry, five explicit Python minor versions, three operating systems and a development status of production-stable, and the keyword list deliberately carries both the American and British spellings of optimisation.
Editorial conclusion
skfolio is worth a look if you build portfolio models inside a machine-learning pipeline, because the fit, transform and cross-validation interface means you get model selection and parameter tuning from the ecosystem you already use, and the prior estimators cover the shrinkage and factor-model territory that plain mean-variance gets wrong. Two things to weigh. The library is a fast-moving 1.4 line with three patch releases in five days, so pin a version before you depend on it. And the documentation is deliberately offered in a token-efficient form for automated readers as well as humans, which is a sign of where its maintainers expect it to be used from.
Frequently asked questions
How do I install skfolio?
With a single pip command carrying an upgrade flag, and Python 3.10 or newer. The full installation guide covers the dependency list, a conda-forge route, and the mixed-integer solvers, which is where you confirm that your install actually got an optimiser capable of a discrete allocation.
What can skfolio optimise?
Portfolio models grouped as naive, such as equal-weighted and inverse-volatility, convex, such as mean-risk and risk budgeting, clustering approaches including hierarchical risk parity, and an ensemble method. On the input side it takes an empirical prior, a cross-sectional factor model built on 46 descriptors across 17 families, a time-series factor model, Black-Litterman, entropy pooling, opinion pooling, or synthetic data for stress tests.
Is skfolio compatible with scikit-learn?
It is built on that library's interface and presents its estimators as compatible, so model fitting, fine-tuning, cross-validation and stress testing come from the same ecosystem. Three of its sixteen example directories exist to demonstrate that integration rather than a finance concept: metadata routing, online learning and pre-selection.
What license is skfolio under and who supports it?
A three-clause BSD licence, stated in the readme and declared in the manifest as a file reference. Behind it is a separate company offering enterprise support and service-level agreements for institutions, and one of the three maintainers is listed with an email address at that company.
Does skfolio provide documentation for automated readers?
Yes. It follows a published convention with a page index and a single-file dump, and any documentation page can be fetched as Markdown by appending a suffix to its address, so a script can read one page instead of the whole set.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/skfolio-skfolio)Star history chart for your README
[](https://hysenlabs.com/projects/skfolio-skfolio)Was this useful?