skforecast puts the estimator in one slot and everything else in your hands
Python library for time series forecasting using scikit-learn compatible models, statistical methods, and foundation models
At a glance
- What is it?
- skforecast is a Python forecasting library whose moving part is a scikit-learn compatible estimator you pass into a recursive forecaster. The packaging and release hygiene are good, while the README's quick example prints an incomplete result and its documentation links all follow the current release.
- Who is it for?
- Treat skforecast as a layer you still have to configure, since the estimator, the lag window and the horizon are all your choices and the library does not pick a model for you. It earns its place when your data is tabular and the estimator you already use exposes a scikit-learn compatible interface.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
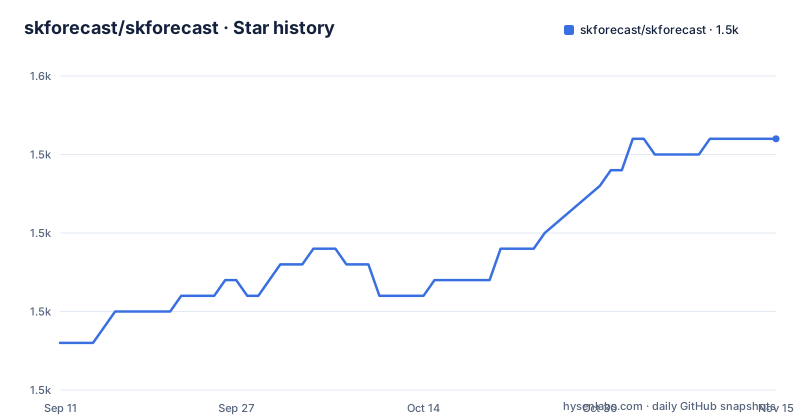
Star history
- skforecast/skforecast1,546 ★ · +13
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| skforecast/skforecast | 1.5k | 1.5k |
13 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One estimator slot, one lag window, one horizon
The public shape of the library is visible in the quick example. You load a demo series, hand a scikit-learn style estimator to a forecaster, say how many past observations become features, and then ask for a horizon:
import pandas as pd
from lightgbm import LGBMRegressor
from skforecast.recursive import ForecasterRecursive
from skforecast.datasets import load_demo_dataset

# Download demo dataset
y = load_demo_dataset()

# Create and fit the forecaster using the last 15 observations as features
forecaster = ForecasterRecursive(
                 estimator = LGBMRegressor(random_state=123, verbose=-1),
                 lags      = 15
             )
forecaster.fit(y=y)

# Predict the next 12 months
predictions = forecaster.predict(steps=12)
predictions.head()
# 2008-07-01    0.976355
# 2008-08-01
Four arguments carry the design. The estimator is a constructor argument, so LightGBM, XGBoost, CatBoost, Keras and any other estimator with a scikit-learn compatible interface occupy the same position. `lags = 15` sets the feature window to the last 15 observations, which is what the comment above it says. `steps=12` is the requested horizon. `random_state=123` and `verbose=-1` belong to LightGBM and are passed straight through, which is why a forecasting example ends up configuring a gradient boosting library twice.
The forecaster class itself lives in `skforecast.recursive`, and the data loader in `skforecast.datasets`. Those two imports are the entire surface the visible documentation demonstrates.
The demo prints two of twelve rows and the second has no value
`predictions.head()` is the final line of the example, and what it prints falls short of what it generated. `steps=12` asks for twelve values. `head()` returns five rows by default, so even at full length the example would display fewer rows than it produced.
What the document shows is fewer still. Two lines appear, and the second carries a date with no number beside it:
# 2008-07-01    0.976355
# 2008-08-01
A reader copying this block gets one value and a date for the following month, then nothing. No explanation accompanies the gap, and no error is shown either, because the output is presented as comment lines under the call rather than as the recorded result of a run. The second value is simply absent from the published example, and it sits directly above the install section in a document whose package version reads 0.25.0 in pyproject.toml.
One smaller leftover in the same block: `import pandas as pd` appears at the top although nothing in the visible code indexes `y` by position or builds a DataFrame directly. The import belongs to a longer version of the snippet.
Every documentation link follows the word latest
The documentation table in the README routes every entry through a versioned path that ends in `latest`. The introduction points at `/latest/introduction-forecasting/introduction-forecasting.html`, the quick start at `/latest/quick-start/quick-start-skforecast.html`, the user guides at `/latest/user_guides/table-of-contents.html`, the FAQ at `/latest/faq/table-of-contents.html`, and the API reference at `/latest/api/forecasterrecursive.html`. Examples, releases and the about page carry the same prefix.
That choice has a cost worth naming. An installed copy of skforecast is a fixed version, pinned by whatever you asked pip for, while every link you follow out of the README resolves against the current documentation. Reading the API reference for the class present in your own environment can show a signature that does not match the one you have, with nothing in the README warning you that this is how it works.
The project also ships machine-readable entry points next to the human site: `llms.txt` and `llms-full.txt` sit at the top level of the repository, and the README header table links the full text version in its Meta row, beside the license link and a Zenodo DOI.
Six sections named in the navigation never appear
The README opens with a table of contents of ten entries. Everything from About The Project through Installation and Dependencies is present. The What is new section opens with one sentence saying that all significant changes are documented in the release file, and the bullet beneath it points at the release notes for the latest stable version. That link stops partway through its target.
The sections the navigation lists after that point do not appear in the document: Forecasters, Examples and tutorials, How to contribute, Citation, Donating and License. Six entries in the project's own table of contents have no text behind them.
The gap matters more here than it would in a smaller project, because the missing Forecasters section is the one that would enumerate what the library actually offers. What the visible document demonstrates is the recursive module and the demo dataset loader, `skforecast.recursive` and `skforecast.datasets`, named in a single import block. Everything else about the class inventory has to come from the documentation site rather than from the README, which routes you to a `latest` page that may describe a newer release than the one in your environment.
Four entries at the repository root target assistants, not users
The top level of the tree shows how the project expects to be used. Alongside the ordinary library directories, `skforecast/`, `tests/`, `docs/`, `benchmarks/`, `dev/`, `tools/` and `images/`, four entries are aimed at tooling rather than at people running forecasts: `AGENTS.md`, `CLAUDE.md`, `skills/` and `context7.json`. A `CLAUDE.md` sitting next to an `AGENTS.md` is the usual sign of a project that expects to be driven by more than one assistant.
None of the four is mentioned in the README. The only machine-readable entry point the document actually reaches is `llms-full.txt`, linked in the header table. `skills/`, `AGENTS.md`, `CLAUDE.md` and `context7.json` appear nowhere in the visible text, so a reader cannot tell from the README whether `skills/` ships reusable prompt material for a coding assistant or something else.
The remainder of the root follows ordinary conventions for a scientific Python package: `.codecov.yml` for coverage reporting, `CONTRIBUTING.md`, `CODE_OF_CONDUCT.md`, `CONTRIBUTOR_LICENSE_AGREEMENT.md`, `changelog.md`, `CITATION.cff`, `CNAME`, `funding.json`, `mkdocs.yml` and `pyproject.toml`. The `benchmarks/` directory is present in that list and equally unmentioned by the README.
The core install is one line, and the AI layer is a different package
Installing the library itself takes a single command:
pip install skforecastThat gets the base version with core dependencies. Everything else the README advertises arrives through a different door. The AI assistant is published separately as `skforecast-ai` on PyPI with its own site at ai.skforecast.org, described as a deterministic engine powered by skforecast paired with an LLM reasoning layer. The visual builder is a separate interactive application at studio.skforecast.org that constructs forecasting models without code and generates production-ready Python code using skforecast as its output. Neither is installed by the command above.
Packaging details in pyproject.toml are worth reading before you depend on the package. The license is BSD-3-Clause, and the `license-files` list contains both `LICENSE` and `CITATION.cff`, so the citation metadata ships inside the license payload rather than alongside the documentation. The classifiers declare Python 3.10, 3.11, 3.12, 3.13 and 3.14, with MacOS, Microsoft Windows, POSIX and Unix as the declared operating systems. The project labels itself `Development Status :: 5 - Production/Stable`, and the header table lists it as a NumFOCUS affiliated project alongside a LinkedIn page, a Discord invite and a Spanish-language community site.
Three tags in ten weeks, and pyproject sits exactly on the newest one
Version alignment is clean right now. The three most recent releases are v0.23.0 on 2026-07-08, v0.24.0 on 2026-08-24 and v0.25.0 on 2026-09-11, which is three tagged releases across about ten weeks. The `version` field in pyproject.toml reads 0.25.0, matching the newest tag rather than trailing it or running ahead of it. The default branch was pushed to on 2026-10-02, so the tree sits ahead of the last tag in the ordinary way for a project that keeps a changelog.
What a reader cannot settle from the README is the content of that gap. There is no statement anywhere in the visible text of what changed between v0.24.0 and v0.25.0, because the release notes bullet is the one that stops mid-link. The document's own answer to where changes are recorded points at a release file and a release notes page, and the second of those two is the one you cannot reach from the README.
The same applies to `benchmarks/`. Its presence in the tree tells you a comparison suite exists; its absence from the README means the project makes no claim about what is measured there, against what baseline, or at what cadence.
Editorial conclusion
Treat skforecast as a layer you still have to configure, since the estimator, the lag window and the horizon are all your choices and the library does not pick a model for you. It earns its place when your data is tabular and the estimator you already use exposes a scikit-learn compatible interface. Before depending on it, pin your version and read the documentation for that tag instead of the `latest` pages, because every link in the README follows the current release, and read the release notes between the newest tag and your install, since the README's own release notes link stops in the middle.
Frequently asked questions
how to install skforecast
The base install is `pip install skforecast`, which brings the library with its core dependencies. Other installation paths, including extra dependencies and additional features, are covered by the project's Installation Guide.
Which models can skforecast use for forecasting?
Any estimator compatible with the scikit-learn API, passed in as a constructor argument. The README names LightGBM, XGBoost, CatBoost and Keras among the options.
Does skforecast build features for me, or do I engineer them?
The quick example sets lags = 15, with a comment stating that the last 15 observations become the features, and the estimator learns the mapping from there. The project also offers separate tooling for feature engineering, model selection and hyperparameter tuning.
Is skforecast-ai part of the main skforecast package?
No. It is a separate assistant published as `skforecast-ai` on PyPI with its own site at ai.skforecast.org, described as a deterministic engine powered by skforecast paired with an LLM reasoning layer.
Does skforecast have a visual builder instead of code?
Skforecast Studio is a separate interactive application at studio.skforecast.org. It builds forecasting models visually and automatically generates production-ready Python code that uses skforecast.
Which Python versions does skforecast support?
The project classifiers declare Python 3.10, 3.11, 3.12, 3.13 and 3.14, with MacOS, Microsoft Windows, POSIX and Unix listed as the declared operating systems.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/skforecast-skforecast)Star history chart for your README
[](https://hysenlabs.com/projects/skforecast-skforecast)Was this useful?