sktime wraps several time series tasks in one estimator interface, and marks some of them as still maturing
A unified framework for machine learning with time series
At a glance
- What is it?
- sktime is a BSD-licensed Python framework that puts forecasting, classification, regression, transformation and detection behind one estimator interface, with pipelines, tuning and reduction to compose them. Its own status table calls forecasting and classification stable and detection maturing, which tells you where the churn will be.
- Who is it for?
- Use sktime when your problem spans more than one time series task, or when you want scikit-learn style tooling for pipelines, tuning and cross-validation on temporal data, and accept detection as the module that may still move under you. Stay on scikit-learn or statsmodels when the task is a single forecasting run.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
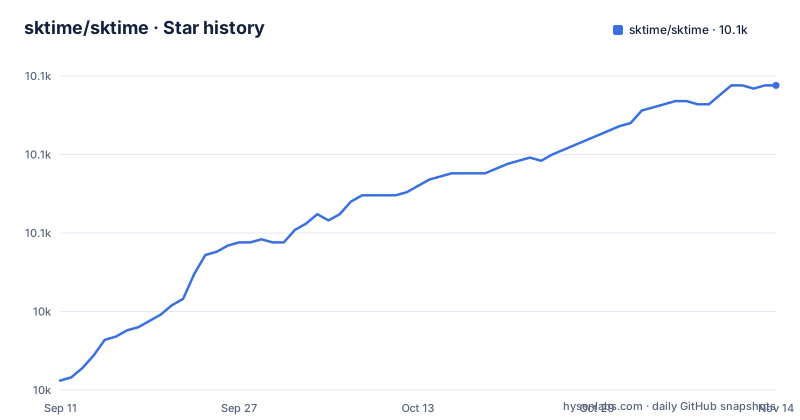
- sktime/sktime10,097 ★ · +94
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| sktime/sktime | 10k | 10.1k |
94 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Four modules are marked stable, two are not
The most useful thing in the README is a status column. Forecasting is marked stable. So are Time Series Classification, Time Series Regression and Transformations. Detection tasks and Parameter fitting are marked maturing, and each of those rows carries an extension template rather than a tutorial and an API reference together. That split is a roadmap for your own risk: a pipeline whose weakest link is anomaly or changepoint detection sits on the two rows the project itself hedges. Extension templates are shipped per task, at extension_templates/forecasting.py, classification.py, transformer.py and detection.py, so the shape of a custom estimator is a file you copy rather than a class you reverse engineer. One detail in that table is worth knowing before you follow it: the Parameter fitting row links the transformer template.
Reduction is how a classifier reaches a forecasting pipeline
The claim that distinguishes sktime from a forecasting library is cross-task reuse, and the mechanism named for it is reduction, alongside pipelining, ensembling and tuning. The stated purpose is to let users apply algorithms designed for one task to another. That is the sentence to test your own use case against: a classifier inside a forecasting workflow is possible because the task boundaries are objects you can wrap, not because the estimator speaks a common protocol for free. The same reach extends outward. sktime ships interfaces to related libraries including scikit-learn, statsmodels, tsfresh, PyOD and fbprophet, so an existing statsmodels or Prophet model can sit inside the same pipeline object as a native estimator. The cost is that those libraries stay your dependencies and their version compatibility becomes your problem. Optional backends are treated as soft dependencies, and the Makefile keeps a dedicated test_softdeps target for checking that an estimator handles a missing optional library, which is the same situation you will meet at runtime.
Python 3.10 to 3.14, and a core dependency set kept small on purpose
The manifest states its support window and its philosophy in two adjacent places. requires-python is >=3.10,<3.16, and the classifiers enumerate 3.10 through 3.15 on MacOS, Windows, POSIX and Unix. Read the two together and the boundary is sharp: Python 3.9 users are outside the window, and so is anything from 3.16 on until the project widens it. A comment above the dependency list marks it as sktime's core dependencies; the Makefile's soft dependency tests indicate that estimators wrapping other libraries, such as a statsmodels estimator or a PyOD detector, rely on optional installs. Licence is declared as a file reference, LICENSE, and the classifiers carry the BSD line, which matches the repository license field.
make install drops an editable install into your own user site
The Makefile is the contributor entry point and it is unusually explicit. Its default goal is help, and the self-documenting comment lines mean make with no arguments prints every target with its description. The install target runs an editable install into the active Python environment of the user:
python3 -m pip install -e . --userThe --user flag is the part that bites. It puts an editable link in your user site-packages, so the importable sktime is your checkout rather than a published copy. The release target, by contrast, calls a script in build_tools, python3 $(BUILD_TOOLS)/make_release.py, which is how a version gets cut. For ordinary users none of this is required: the README's badge row points at the PyPI project and the conda-forge channel, so a plain pip or conda install of the released package is the normal route. The Makefile recipe is for people who intend to change the source.
TestAll and test_all_estimators are the bar for a custom estimator
Writing your own estimator is a supported activity, and the repository tells you how it is checked. Several targets isolate slices of the suite rather than running everything. test_without_datasets skips the datasets package entirely, test_check_suite keeps only the estimator contract tests in TestAll classes, and full_test turns off the changed-modules filter so the whole suite runs:
python -m pytest --ignore sktime/datasets
python -m pytest -k 'TestAll' $(PYTESTOPTIONS)
test_softdeps goes further and reaches into the package by import path, running test_all_estimators against sktime.registry and test_check_estimator_does_not_raise against sktime.utils.tests with -n auto for parallel workers. Those names are the acceptance criteria in practice. If your estimator satisfies the TestAll contract and the soft dependency checks, it behaves like the built-in ones. Discoverability is a separate problem: ESTIMATOR_OVERVIEW.md at the repository root and the estimator overview page are what make an estimator findable.
The video tutorial is from 2021, the notebooks are current
The documentation table mixes material of very different ages, and the ages are stated. The video tutorial is identified as coming from the 2021 PyData Global event. The example notebooks are where the current shape of the library is taught: 01a_forecasting_sklearn covers using scikit-learn tools inside forecasting, 01c_forecasting_hierarchical_global covers hierarchical and global models, 03a_transformers_cheat_sheet is a transformer lookup, 03b_forecasting_transformers_pipelines_tuning walks the composition tools, 05_graphical_pipelines shows the visual form of the same idea, and 07_detection_anomaly_changepoints covers the module the status table calls maturing. AA_datatypes_and_datasets.ipynb is the one to read first if your data does not fit, because a unified interface only helps once your arrays are in the datatypes it expects. Binder is wired to the examples directory of the main branch, so the browser notebooks run the code in the repository rather than a pinned release.
Support runs through public channels, governance through a council
Where to take a problem is spelled out, and the split matters for what you can expect. Bug reports and feature requests both go to the GitHub issue tracker, which makes them public and searchable. Usage questions go to GitHub Discussions or Stack Overflow, general discussion to Discussions, and contribution and development talk happens in a dev-chat channel on Discord, with meet-ups on Fridays at 13 UTC. Governance sits elsewhere: pyproject.toml notes that sktime is governed by a Community Council, points at docs/source/get_involved/governance, and lists maintainers including Franz Király, Marc Rovira, Felix Hirwa Nshuti and Ugochukwu Onyeka, with GOVERNANCE.md and CODE_OF_CONDUCT.md at the root. The release cadence is real: v1.2.0 shipped on 2026-09-22 and the last push was on 2026-11-01.
Editorial conclusion
Use sktime when your problem spans more than one time series task, or when you want scikit-learn style tooling for pipelines, tuning and cross-validation on temporal data, and accept detection as the module that may still move under you. Stay on scikit-learn or statsmodels when the task is a single forecasting run. Before you commit, check three things: whether the module your pipeline depends on is one of the stable rows or one of the maturing ones, whether the optional library you intend to call through an interface is installed in your environment, and whether your Python version falls inside the 3.10 to 3.15 window the manifest declares. If you write your own estimator, budget for the TestAll contract suite rather than assuming a quick merge.
Frequently asked questions
How do you install sktime?
The README points at the PyPI project and the conda-forge channel for the released package. For a source checkout the Makefile install target runs python3 -m pip install -e . --user, an editable install into the active Python environment of the user.
Is sktime a replacement for statsmodels?
The README lists statsmodels among the related libraries sktime provides interfaces to, alongside scikit-learn, tsfresh, PyOD and fbprophet. sktime is positioned as a unified interface across forecasting, classification, regression, transformations and detection tasks rather than as a replacement for any single one of them.
How does sktime relate to Prophet?
fbprophet is one of the related libraries sktime provides interfaces to, so a Prophet model can be used inside sktime pipeline and tuning tools.
Do I need scikit-learn if I use sktime?
sktime ships scikit-learn compatible tools to build, tune and validate models and provides interfaces to scikit-learn itself, with a notebook at examples/01a_forecasting_sklearn.ipynb covering that path.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/sktime-sktime)Star history chart for your README
[](https://hysenlabs.com/projects/sktime-sktime)Was this useful?