OpenClaw hardening guide: prohibitions first, and an enforcement model that cannot check itself
This guide is designed for OpenClaw itself (Agent-facing), not as a traditional human-only hardening checklist.
At a glance
- What is it?
- A defensive practice guide for high-privilege autonomous agents, structured as a three-tier matrix of pre-action, in-action and post-action controls, with thirteen nightly metrics and a cron job deliberately isolated from the workspace it audits. Its most striking feature is that the guide is written to be executed by the model it protects, and its own authors tie its validity to a repository last updated in April 2026.
- Who is it for?
- Read this as a design document rather than a checklist, and take its refusals before its features: it says outright that it cannot make an agent secure, that it assumes injection and supply-chain poisoning are always possible, and that the last judgment stays with a human. Two things to verify.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 7 months ago.
- What is it written in?
- Mainly Shell, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
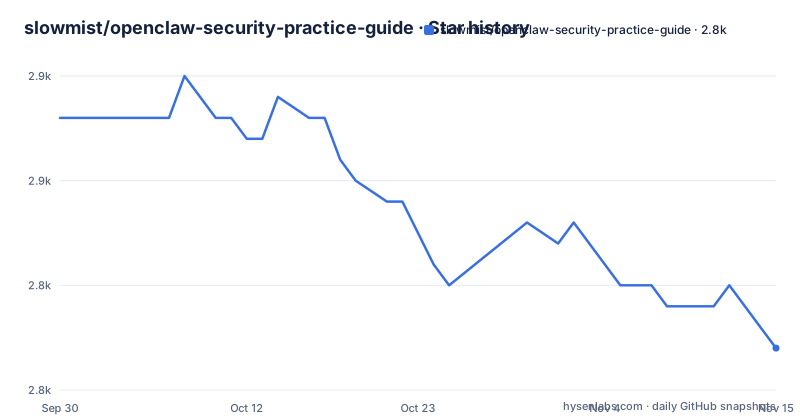
- slowmist/openclaw-security-practice-guide2,842 ★ · -11
| Repository | 2026-09-30 | 2026-11-15 |
|---|---|---|
| slowmist/openclaw-security-practice-guide | 2.9k | 2.8k |
-11 Stars in the last 46 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The document leads with what it cannot promise
The prohibitions come first, and they are unusually specific for a hardening guide.
The boundary statement says the guide does not make OpenClaw fully secure. It says absolute security does not exist, that security is a complex systems engineering problem, that the guide is built for a specific threat model, scenario and set of operating assumptions, and that final responsibility and last-resort judgment remain with the human operator.
That last clause is the operative one. Everything else in the document is bounded by it.
The most prominent line near the top is a request to read the disclaimer and the FAQ at the bottom, and that line appears three times in a row, the first two carrying a line break tag and the third without it. The duplication reads as an editing slip rather than emphasis, which is worth noting because it is the one place the document's own care is visibly imperfect.
For a reader deciding whether to follow this, the right takeaway is the red lines rather than the capabilities. A guide that tells you up front what it does not cover is giving you more usable information than one that lists what it does.
The target scenario is a root-capable agent that installs code continuously
Three bullets define the situation the guide is written for.
OpenClaw runs with high privileges in a terminal or root-capable environment. It continuously installs and uses Skills, MCPs, scripts and tools. And the stated objective is capability maximization with controllable risk and explicit auditability.
That third bullet is the design stance, and it is the one most likely to surprise a reader arriving from conventional hardening. This is not a document about reducing what an agent may do. It accepts that the agent will be given broad power and asks instead for the risk to be bounded and the behaviour to be inspectable after the fact.
Four core principles follow from that stance. Operations stay frictionless, meaning no manual security setup burden, except when a guideline-defined red line is hit. Anything irreversible or sensitive pauses for human approval. Nightly auditing is explicit, with all core metrics reported including healthy ones and no silent pass. And trust is zero by default, meaning prompt injection, supply chain poisoning and business-logic abuse are assumed to be always possible.
That last principle is the load-bearing one. The document is not built around preventing injection. It is built around what you can still detect afterwards.
Host controls are declared insufficient before anything is proposed
The argument for a new approach is made in one paragraph, and it makes two separate claims.
Traditional security measures, giving `chattr +i` and firewalls as the examples, are described as either incompatible with agentic workflows or insufficient against LLM-specific attacks like prompt injection.
The two failure modes are different and both worth separating. Incompatibility is the mechanical problem: an agent that is expected to write to its own workspace cannot do so if that workspace is made immutable, so the control has to be removed rather than configured. Insufficiency is the harder claim: a firewall filters network traffic and has nothing to say about an instruction that arrives inside a prompt.
The three-tier matrix that follows is the response. Pre-action covers behaviour blacklists and strict Skill installation audit protocols, which the page labels anti-supply-chain poisoning. In-action covers permission narrowing and cross-Skill pre-flight checks, labelled business risk control. Post-action covers nightly automated explicit audits over thirteen core metrics, plus what the page calls Brain Git disaster recovery.
Of the three tiers, only the confirmation principle actually interrupts anything, and it is the only one that needs a person awake.
The guide is written to be executed by the model it protects
This is the structural fact to hold onto, and the document is direct about it.
The scope section says the guide is designed for OpenClaw itself, agent-facing, not as a traditional human-only hardening checklist, and that in practice you can send it directly to OpenClaw in chat, let it evaluate reliability, and deploy the defense matrix with minimal manual setup. The flow it describes is: download a markdown file, drop it into a chat, ask the agent to read it and flag conflicts with the current setup, then have the agent deploy.
Reliability is then made contingent rather than claimed. The page recommends a strong, latest-generation reasoning model, giving current top-tier families as examples, and says higher-quality models generally perform better at three specific things: understanding long-context security constraints, detecting hidden instruction patterns and injection attempts, and executing deployment steps consistently with fewer mistakes.
The circularity is worth naming plainly. A document enforced by the same class of system it defends, whose reliability is asserted by asking you to supply a stronger model, cannot verify its own controls. Nothing in the text claims otherwise, and the admission sits in the model recommendation rather than being buried.
That is precisely why the human-confirmation principle and the statement that final judgment remains with the operator carry the weight, and why they should be the first thing you check are actually in place.
The scripts directory is explicitly not meant to be executed
The repository's note on its own shell scripts is unambiguous:
> The `scripts/` directory in this repository is strictly for open-source transparency and human reference. You do NOT need to manually copy or run it. The Agent will automatically extract the logic from the guide and handle the deployment for you.
So the primary language is Shell while the deliverable is prose, and the scripts exist to be read. That also explains how thin the repository is: a licence, two README files, a `docs/` directory and a `scripts/` directory. There is no CI configuration, no issue templates, no test directory and no release history.
The audit scripting guidelines listed among the improvements confirm the intention, since they are review criteria rather than build steps: `set -uo pipefail` so a pipeline failure is not swallowed, boundary anchors, explicit healthy-state output, and a summary line.
There is a consequence here that follows from the model rather than from the prose. If the deployment is re-derived from the markdown by an agent instead of running the reviewed scripts, then the scripts are not the artefact under audit. Anyone auditing this repository should read the guide documents, not the shell.
And if you do run anything here, it belongs in a disposable environment first, because the target scenario is explicitly an agent with root access.
Two guide versions target two engine generations, and the beta says so
The repository ships parallel guides and states plainly which engine each one was built against.
Version 2.7 is described as having undergone extensive production validation on OpenClaw version 2026.3 and earlier, and as now archived as a classic legacy version suitable for users still running older engines.
Version 2.8 is labelled beta and described as targeting OpenClaw version 2026.4 and later, carrying the latest automated workflows and anti-hijacking strategies.
So the recommended path is the one the authors label a beta, and the one described as validated is the archived one. That is a deliberate trade and it is disclosed rather than buried.
The risk warning attached to both is the most useful paragraph on the page. It says that because of OpenClaw's fast iteration cycles and the instability of its evolving engine, some practices may become incompatible or ineffective after official updates. It says testing only covers OpenClaw versions up to the date of the latest repository update, and it recommends thoroughly testing and validating against your current version before deploying in production.
That validity window is anchored to a real date. The last push to the main branch was 2026-04-06, and the repository has no GitHub releases. So the currency of the guidance is a fact you can check rather than a claim you have to take on trust.
The audit reports when nothing is wrong, and runs out of context to do it
One design decision is worth borrowing regardless of whether you adopt the rest of the guide.
The third core principle is explicit nightly auditing, described as all core metrics being reported, including healthy ones, with no silent pass. The post-action tier repeats it as nightly automated explicit audits across thirteen core metrics. The stated reason is not convenience: a report that only appears when something fails cannot distinguish a healthy system from one that stopped running.
The v2.8 improvements add the sharper half. A flag called `--light-context` is described as cron protection that prevents workspace context from hijacking isolated audit sessions.
Read that carefully, because it is the most technically pointed claim in the visible text. An audit job that inherits the agent's full workspace context is reading the same material an attacker would be trying to influence. If the audit runs with that context, whatever is in the workspace can influence the audit. Isolating the session is what makes the report worth reading.
The coding guidelines reinforce the same instinct from the output side: explicit healthy-state output and a required summary line, so a reader can always tell checked-and-fine from never-ran.
That is the piece with the widest application, because most monitoring systems share the failure mode it fixes.
Editorial conclusion
Read this as a design document rather than a checklist, and take its refusals before its features: it says outright that it cannot make an agent secure, that it assumes injection and supply-chain poisoning are always possible, and that the last judgment stays with a human. Two things to verify. The guide is meant to be carried out by the agent it protects, which means the prose is the artefact under audit and the shell scripts in the repository are reference material only. And its own disclaimer ties validation to the date of the last repository update, so check that the engine version you run is one the document claims to have been tested against, and validate before deploying anything in production.
Frequently asked questions
What is the OpenClaw Security Practice Guide for?
It is a security practice guide written for high-privilege autonomous AI agents. It moves away from host-based static defense toward what it calls agentic zero-trust architecture, addressing destructive operations, prompt injection, supply chain poisoning and high-risk business logic execution.
Does the guide claim it can make an OpenClaw agent fully secure?
No, and it says so explicitly. It states that it does not make OpenClaw fully secure, that absolute security does not exist, that it is built for a specific threat model, scenario and operating assumptions, and that final responsibility and last-resort judgment remain with the human operator.
What are the three tiers in the OpenClaw defense matrix?
Pre-action with behaviour blacklists and strict Skill installation audit protocols, in-action with permission narrowing and cross-Skill pre-flight checks, and post-action with nightly automated explicit audits over 13 core metrics plus disaster recovery.
Which OpenClaw version is the v2.8 guide written for?
OpenClaw version 2026.4 and later, while v2.7 was validated on 2026.3 and earlier and is archived as a classic legacy version. The page warns that testing only covers versions up to the date of the latest repository update and recommends validating against your current version before production use.
Do I need to run the scripts in the openclaw security practice guide repository?
No. The page states the scripts directory is strictly for open-source transparency and human reference, that you do not need to manually copy or run it, and that the agent extracts the logic from the guide and handles the deployment itself.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/slowmist-openclaw-security-practice-guide)Star history chart for your README
[](https://hysenlabs.com/projects/slowmist-openclaw-security-practice-guide)Was this useful?