Statewave compiles memory once so the same query returns the same bytes
Open-source memory runtime for AI agents — reproducible, provenance-tagged context bundles instead of query-time retrieval. Apache-2.0, self-hosted on Postgres + pgvector, Python + TypeScript SDKs.
At a glance
- What is it?
- An Apache-2.0 memory runtime on Postgres and pgvector that replaces query-time retrieval with compiled, provenance-tagged context bundles, at the cost of a compile step, a receipt for every assembly, and a demo mode whose retrieval has no semantic similarity.
- Who is it for?
- Statewave suits applications where a wrong answer has to be traced to a source episode, where tenancy has to be enforced at query scope, and where a regulated reviewer needs to replay the rules in force when a bundle was assembled. It does not suit a chat prototype that wants semantic search on day one, because demo mode retrieves by keyword and text only.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
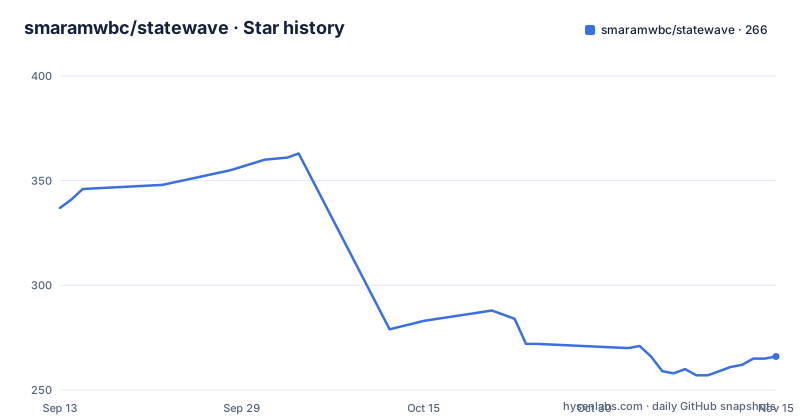
Star history
- smaramwbc/statewave266 ★ · -71
| Repository | 2026-09-13 | 2026-11-15 |
|---|---|---|
| smaramwbc/statewave | 337 | 266 |
-71 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Compile once, assemble on demand, same bytes every time
The design decision here is a rejection of query-time retrieval. Statewave reads raw events, compiles them once per subject change into typed memories, and assembles a token-bounded context bundle on demand. Each bundle carries provenance back to the source episodes, and the same query against the same subject at the same point in time produces the same bytes.
That determinism is the whole pitch, and it is a real difference in approach rather than a tuning knob. A vector store plus chat-log stuffing re-decides at query time what is relevant, so sampling noise enters the answer and two identical questions can produce different context. Here the ranking happened at compile time, the token budget is applied deterministically, and re-running the assembly for the same task returns the same bytes. The project also states idempotency at every step: recompiling a subject produces no duplicates.
What it is not is worth stating in the project's own terms, since misreading this is the common mistake. It is not a chatbot framework, not a vector database, not a RAG pipeline and not a hosted service. It is infrastructure you run beside your application, with episodes and compiled memories living in your own Postgres.
Ingest, compile, retrieve, govern, all keyed by subject
The data lifecycle is four verbs. Ingest records raw events as episodes, append-only. Compile extracts typed, summarised memories with confidence scores and provenance. Retrieve assembles ranked, token-bounded context bundles ready for your prompts. Govern covers inspection of subject timelines, tracing every memory back to its source, and deletion by subject.
Everything hangs off the subject, which can be a user, an account, an agent, a repository or any entity you choose to track, addressed with a prefix such as `user:`, `repo:` or `account:`. That choice does more work than it looks. It is the unit of isolation, the unit of deletion when someone asks you to forget them, and the unit the compile step keys on.
The loop fits in six lines of Python, and it is the shape of every integration:
from statewave import StatewaveClient

with StatewaveClient("http://localhost:8100") as sw:
    sw.create_episode(subject_id="user-42", source="chat", type="message",
                      payload={"text": "Alice asked about pricing tiers"})
    sw.compile_memories("user-42")
    print(sw.get_context("user-42", task="answer pricing", max_tokens=1000).assembled_context)
Note that compile is explicit. Nothing is compiled on read, and if you forget the call after an ingest your context simply will not contain the new episode.
Receipts are ULID-addressable and replayable
Every state assembly leaves a receipt: an immutable, ULID-addressable record of which memories influenced the bundle. Since v0.9 a receipt carries an HMAC-SHA256 signature and an embedded policy snapshot, so the record cannot be edited after the fact and carries the rules that were in force rather than the rules in force now.
Then there is the replay endpoint, `POST /v1/receipts/{id}/replay`, framed as answering what today's code would say with the original rules. That is a capability worth pausing on, because it is the one that makes a memory system auditable rather than merely inspectable. When a customer disputes what the agent was told, the question is not what the database contains now but what the assembly contained then, under which policy, with which token budget. A snapshot and a signature are what make that answerable rather than approximate.
Receipts are also content-hashed, so the same assembly produces the same receipt identity. The cost is storage and an obligation: every assembly is now a record you keep, and deletion by subject has to account for that.
Policy YAML decides deny or redact, and labels start as suggestions
Sensitivity handling is a declarative layer rather than application code. Policies are YAML with `deny` and `redact` decisions, evaluated over per-memory tags such as `pii`, `financial` and `secret`, and they run in `log_only` or `enforce` mode. Running in log_only first is the sensible default for a system whose decisions affect what a model sees.
The interesting part is where labels come from. Since v0.9 the heuristic detectors propose `suggested_labels`, covering cases like `pii.email`, `pii.phone`, `financial.card` and `secret.token`, and those proposals are advisory only. An operator reviews them and promotes them explicitly through the admin app. So detection is automatic and enforcement is not, which is the right way round for a false positive that would otherwise hide a memory a model needed.
The cost of that design is a queue of unreviewed suggestions that does not enforce anything until someone works through it. If nobody reviews, the tags stay advisory and the policy engine has nothing to act on.
Demo mode retrieves by keyword, and a missing key compiles nothing
The default configuration runs without an API key, and the two lines that decide what that means are in the example environment file:
STATEWAVE_COMPILER_TYPE=heuristic
STATEWAVE_EMBEDDING_PROVIDER=stub
Heuristic means a regex compiler running fully locally, and stub means hash-based embeddings. The file is explicit that retrieval in this mode is keyword and text only, with no semantic similarity. So the first-run experience is: memory extraction works, determinism works, provenance works, and semantic search does not. For an evaluation that is a fair trade, and for anyone judging the retrieval quality from a first impression it is misleading.
The opt-in path replaces those two lines with an LLM compiler and real embeddings through LiteLLM, which dispatches to whichever provider the model identifier names. One behaviour is documented sharply enough to deserve repeating: with the LLM compiler selected but no key reachable, compilation produces zero memories and does not fall back to the regex compiler. A misconfigured key does not degrade, it empties the store silently.
The container installs twice, on purpose
The Dockerfile is python:3.11-slim and does something that looks redundant:
RUN pip install --no-cache-dir ".[llm]"
RUN pip install --no-cache-dir --no-deps . && chmod +x start.sh
The first line runs before any application code is copied, so the dependency layer stays cached when only code changes. The second is not redundant at all: without it `server/` never lands in site-packages, and because `start.sh` runs `alembic upgrade head` while the alembic console script does not put the working directory on the path, the container exits with a ModuleNotFoundError before uvicorn ever starts. The comments say so explicitly.
Compose runs `pgvector/pgvector:pg16` for the database with the credentials statewave on all three fields and the port mapped from `STATEWAVE_DB_HOST_PORT`, defaulting to 5432, and pulls `statewavedev/statewave` for the API on port 8100. That default database credential pair is published in the repository, so it is a local-development value and needs replacing before any shared deployment.
Tenancy is a header, and region pinning is a 403
Multi-tenancy is implemented as query-scoped isolation through an `X-Tenant-ID` header, with per-tenant configuration and per-tenant policies. That design keeps the data model simple, and it puts the burden of isolation on every caller: a client that omits the header does not get another tenant's data by accident, it gets the untenanted view, which is a different kind of bug to catch.
Since v0.9 there is also per-tenant region pinning for data residency. A tenant pinned to `eu` receives a 403 from any process running in another region, enforced at request time rather than by configuration discipline. This is the part of the feature set that suggests the project has been taken seriously by people with compliance obligations, and it is also the part that constrains deployment: a multi-region setup now has tenants that cannot be served everywhere.
On upkeep the repository is not archived, the last push was on 2026-10-01, and releases moved v1.3.0 in June, v1.4.0 in July and v1.5.0 on 2026-08-30. Licence is Apache-2.0, with separate `LICENSING.md`, `NOTICE.md` and `TRADEMARKS.md` files at the root.
Editorial conclusion
Statewave suits applications where a wrong answer has to be traced to a source episode, where tenancy has to be enforced at query scope, and where a regulated reviewer needs to replay the rules in force when a bundle was assembled. It does not suit a chat prototype that wants semantic search on day one, because demo mode retrieves by keyword and text only. Verify first that your subjects map cleanly onto something like a user or a repository, that you accept compiling after ingest rather than embedding at query time, and that the per-memory promotion step for suggested labels fits how your team reviews data.
Frequently asked questions
What is Statewave and how is it different from a vector database?
It is an open-source memory runtime for agents, self-hosted on Postgres and pgvector, that compiles typed memories once per subject change and assembles deterministic, token-bounded context bundles with provenance. A vector database re-ranks at query time, which is where Statewave's sampling-noise argument comes from.
How do I run Statewave locally?
Copy `.env.example` to `.env` and run `docker compose up -d`, which needs no API key and starts in demo mode with a heuristic compiler and stub embeddings on port 8100. A Helm chart and a Docker guide are in the repository, and the Python package requires 3.11 or newer.
Does Statewave do semantic search out of the box?
No. The default demo mode uses hash-based embeddings and keyword and text retrieval with no semantic similarity. Real semantic search needs the LLM compiler path through LiteLLM, and with that compiler selected but no reachable key, compilation produces zero memories rather than falling back to the regex compiler.
What is a Statewave receipt and can I replay one?
Every state assembly writes an immutable, ULID-addressable record of which memories influenced the bundle, content-hashed, with an HMAC-SHA256 signature and an embedded policy snapshot since v0.9. `POST /v1/receipts/{id}/replay` answers what today's code would produce using the original rules.
How does Statewave handle multiple tenants and data residency?
Isolation is query-scoped through an `X-Tenant-ID` header, with per-tenant configuration and policies, and since v0.9 per-tenant region pinning returns a 403 to a tenant pinned to one region when a request reaches a process in another.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/smaramwbc-statewave)Star history chart for your README
[](https://hysenlabs.com/projects/smaramwbc-statewave)Was this useful?