SMG routes inference requests, and the routing policy is the interesting part
Engine-agnostic LLM gateway in Rust. Full OpenAI & Anthropic API compatibility across vLLM, TRT-LLM, TokenSpeed, SGLang, OpenAI, Gemini & more. Industry-first gRPC pipeline, KV cache-aware routing, chat history, tokenization caching, Responses API, embeddings, WASM plugins, MCP, and multi-tenant auth.
At a glance
- What is it?
- A Rust gateway that sits between your application and a fleet of inference workers, or between your application and a cloud model provider. The reason it exists is not the API compatibility, which many projects offer, but the radix tree it keeps of every worker's cache state.
- Who is it for?
- Judge this one on whether you have more than one worker. A single worker behind a gateway is a gateway you added problems to, and the routing, the mesh, the admission scheduling and the ninety-odd metrics are all solving a problem you do not have yet.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
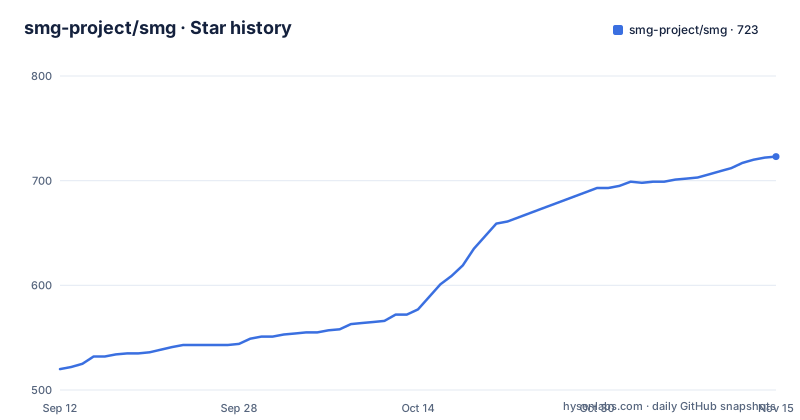
- smg-project/smg723 ★ · +203
| Repository | 2026-09-12 | 2026-11-15 |
|---|---|---|
| smg-project/smg | 520 | 723 |
203 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Ten routing policies, and one of them is doing the real work
The gateway exposes ten routing policies and lists them by name, which is worth reading as a menu of tradeoffs rather than a feature list: cache awareness, least load, power of two, consistent hashing, prefix hash, bucket, round robin, random, manual, and pass through.
Cache-aware is the one the project leads with, and the mechanism is specific enough to be interesting on its own. Each worker's key-value cache state is tracked in radix trees, which lets the gateway know which cached prefixes already exist on which machine. When a request arrives whose prefix has been seen, it goes to the worker that already holds it, and the prefix is reused instead of recomputed. The same idea is applied across several engines, so the optimisation is not tied to one runtime.
The load model behind that choice is what separates it from a naive least-connections balancer. It accounts for queued token work and key-value cache pressure, not just how many requests are in flight. Two workers can both be at ten concurrent requests and be in completely different states, and a balancer that only counts connections will send the next one to the wrong one. The other nine policies exist for when you do not want this behaviour, including pass through, which is effectively a way to disable routing.
One endpoint, self-hosted engines on one side and cloud APIs on the other
The compatibility claim is broad and specific at once. Self-hosted engines named are vLLM, SGLang, TokenSpeed, TensorRT-LLM, MLX for Apple Silicon, and any OpenAI-compatible server. Cloud providers named are OpenAI, Anthropic, Google Gemini, xAI, OCI Generative AI, AWS Bedrock, Azure OpenAI, plus any compatible provider, with two named as examples.
What that gets you is a single endpoint rather than two architectures. An application written against one interface can send traffic to a local GPU or to a hosted frontier model without the application changing, which is the property that makes gateway adoption survivable inside an organisation. Teams that cannot agree on a model provider can at least agree on the URL.
The surface area is unusually wide for something described as compatible. The listed coverage includes OpenAI chat completions, completions, embeddings, rerank and classify; the responses and conversations endpoints aimed at agents; Anthropic messages; Gemini interactions; realtime over two transports; audio transcription; tokenize and detokenize; and tool execution with approval policies. Each of those is a separate dialect to keep working, which is also the reason the parsers below exist.
Twenty-one tool parsers and sixteen reasoning parsers
The compatibility problem in practice is not the HTTP shape, it is that every model family encodes tool calls and reasoning differently on the wire. The project counts its answer to that: twenty-one tool-call parsers and sixteen reasoning parsers, with automatic model detection.
The families named include DeepSeek, Qwen, Kimi, GLM, Llama, Mistral, Command, and Nemotron. Each of those ships tool calls in a format that no other one uses, and a gateway that forwards bytes unconverted produces requests the model will reject or silently ignore. Detection matters as much as the parsers themselves, because the same deployment sees whichever model a client happens to ask for and has no configuration telling it which parser to apply.
This is the least glamorous feature in the document and the one that decides whether the gateway works. The alternative for every team is writing the same conversion layer per provider in their own application, which is exactly the duplication a gateway exists to remove.
The gRPC pipeline and the split between prefill and decode
The performance story rests on native Rust with a streaming gRPC pipeline to the engines, cached tokenization with zero-copy cache hits, and prefill and decode disaggregation, including a separate encode stage for vision. Routing is described as data-parallel aware for engines that shard that way.
Prefill and decode disaggregation is the industry term for letting a prompt go to one set of machines and the generated tokens to another. It helps because the two halves have different bottlenecks, and running them on separate pools means neither is waiting on the other's shape. The encode stage is the same idea applied to images, which is a separate cost centre from text processing.
Tokenization is cached for a less obvious reason: every request that crosses the gateway has to be turned into tokens at least once for the router to reason about it at all, so caching that work stops being an optimisation and becomes part of the baseline. Note the counterweight to all of this: the gRPC path only helps engines that speak it, so the same deployment is faster on some backends than on others, and the mixed-mode install instructions below reflect that.
Four install paths, and a mesh flag that changes the topology
Installation is offered four ways, and the choice is not only about packaging preference:
# Docker
docker pull lightseekorg/smg:latest

# Kubernetes (Helm)
helm install smg oci://ghcr.io/smg-project/charts/smg

# Python
pip install smg

# Rust (needs protoc)
cargo install smg
The Helm chart and the Kubernetes discovery support in the documentation point at the same conclusion, which is that the intended serious deployment is in a cluster with native pod watchers, label selectors, and separate selectors per role for prefill, decode and encode. Nothing about that is optional in practice once you have more than one node, because manually listing worker URLs does not survive a pod restart.
Launching is where the topology becomes explicit:
# Multiple workers with cache-aware routing
smg launch --worker-urls http://gpu1:8000 http://gpu2:8000 --policy cache_aware
The mesh flags on a later example turn on high availability networking, with a host to advertise and peer URLs to join. Underneath that is a gossip protocol with conflict-free replicated state, which is a heavier design choice than a static config list and the reason the resilience section can promise circuit breakers, retries with backoff and jitter, rate limiting, and priority admission scheduling with preemption.
Twenty-four crates, a Python binding, and an OpenAPI generator
The workspace file is the clearest statement of scope, because it lists every member. Alongside the main gateway crate there are separate crates for protocols, the reasoning parser, the tool parser, a workflow crate, the tokenizer, authentication, MCP, an external router, a key-value index, a data connector, multimodal handling, a remote direct memory access piece, the WebAssembly plugin host, the mesh, a gRPC client, a queue-based client for one engine, a mock worker, a reinforcement learning crate, and a radix tree. Bindings for Python and Go, a Rust client, and an OpenAPI generator client sit alongside.
Two of those entries say more than the feature table does. The mock worker is what makes the gateway testable without a GPU, which for a project this size is not a convenience. The radix tree is a standalone crate rather than a module, which suggests the cache index is meant to be usable, and testable, on its own.
The Makefile fills in the working practices. It caps parallelism based on detected cores to avoid thread exhaustion, uses a compilation cache when one is installed on the machine and prints an install hint when it is not, and pins the OpenAPI generator version explicitly for reproducibility. There are separate targets for building, testing and generating client bindings in several languages. Small details, but they are the ones that distinguish a project that is built often from one that is built once.
Multi-tenancy, history storage, plugins, and the open issue count
Control features are grouped together in the document, and they are the part most relevant to anyone running this for other people rather than for themselves: API-key authentication with OpenID Connect on the control plane, per-tenant controls, priority admission scheduling with preemption, chat history stored pluggably across four backends with schema migrations, and WebAssembly plugins for custom request and response handling.
Storing history is the one with the sharpest edge. The claim that history never leaves your infrastructure is only as true as the backend you choose, and the four options on offer range from in-memory to three databases you would run yourself. An in-memory backend and a shared database are very different privacy postures for the same gateway, and the documentation does not pretend they are equivalent.
One number in the repository is worth reading alongside the features. Against a community of several hundred stars, the open issue count is close to a hundred. That is what a fast-moving infrastructure project with this much surface area looks like, and it is a better signal of where the rough edges are than any feature table: the parsers, the mesh, and the disaggregation paths are where the reports will be.
Editorial conclusion
Judge this one on whether you have more than one worker. A single worker behind a gateway is a gateway you added problems to, and the routing, the mesh, the admission scheduling and the ninety-odd metrics are all solving a problem you do not have yet. With a fleet, the trade is legible: you give up a little latency inside your own network and get back cache reuse, worker lifecycle management, and one endpoint that speaks every API dialect your application might need. Read the policy list before you deploy, pick the one that matches your traffic shape rather than the one with the best-sounding name, and remember that the same binary will happily route to a cloud provider, which is a different reliability and cost conversation from the one you had when you started.
Frequently asked questions
What is SMG?
It is an engine-agnostic model-routing gateway written in Rust, named Shepherd Model Gateway. It centralises worker lifecycle management, balances traffic across self-hosted engines and cloud providers, and puts multi-tenancy, chat-history storage, MCP tooling and observability behind one unified endpoint.
What makes the cache-aware routing policy different from least-load balancing?
The gateway tracks each worker's key-value cache state in radix trees, so it knows which cached prefixes exist on which machine and can route a request to the worker that already holds the prefix. Its load model accounts for queued token work and cache pressure rather than counting connections, and the same prefix reuse is applied across several engines.
Which inference backends does SMG support?
Self-hosted engines named are vLLM, SGLang, TokenSpeed, TensorRT-LLM, MLX for Apple Silicon, and any OpenAI-compatible server such as Ollama. Cloud providers named are OpenAI, Anthropic, Google Gemini, xAI, OCI Generative AI, AWS Bedrock, Azure OpenAI, and any OpenAI-compatible provider.
How do I install SMG?
Four ways are documented: pull the container image, install the Helm chart from the published registry, install the Python package, or install the Rust crate, which needs the protocol buffer compiler. Launching takes a list of worker URLs, and a policy flag selects the routing behaviour.
Does SMG work with agent tools and reasoning models?
Yes. Tool discovery and execution work over three transports with approval policies and audit logging, and the gateway carries twenty-one tool-call parsers and sixteen reasoning parsers with automatic model detection, covering families including DeepSeek, Qwen, Kimi, GLM, Llama, Mistral, Command and Nemotron.
Where is chat history stored, and what observability is included?
Chat history uses pluggable storage with schema migrations, with PostgreSQL, Oracle, Redis and in-memory listed as backends, so the history stays inside your own infrastructure. Observability is more than ninety Prometheus metrics, plus OpenTelemetry tracing with W3C trace context propagated into the engines, and structured JSON logs with request correlation.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/smg-project-smg)Star history chart for your README
[](https://hysenlabs.com/projects/smg-project-smg)Was this useful?