SMT ships compiled Cython extensions and three dependency lists that disagree
SMT: The Surrogate Modeling Toolbox
At a glance
- What is it?
- SMT is a BSD licensed Python package of surrogate models, sampling methods, and benchmark functions, built by a research group and installed with a single pip command. Behind that one line sit three Cython extensions, a version number derived from git tags, and three separate declarations of what the package needs, none of which match.
- Who is it for?
- SMT fits research and engineering work where gradients of the surrogate matter, hierarchical or mixed variables are in play, and a compiler is available at install time. It does not fit a locked-down production environment that installs from wheels only, or a team that needs to know which libraries a release pulls in without reading three files.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
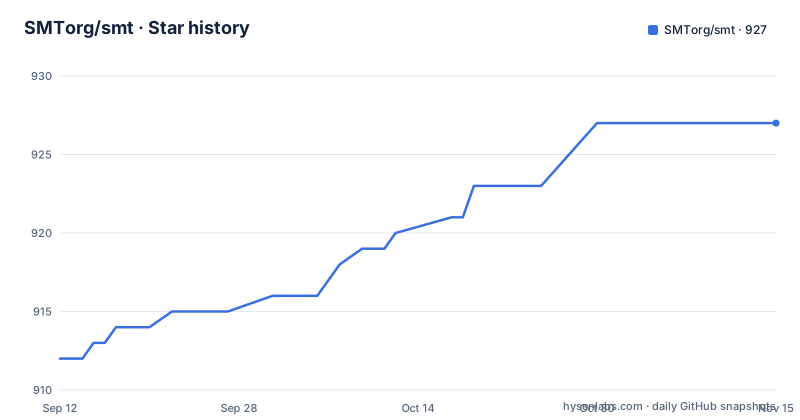
- SMTorg/smt927 ★ · +15
| Repository | 2026-09-12 | 2026-11-15 |
|---|---|---|
| SMTorg/smt | 912 | 927 |
15 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three files declare the dependencies and none of them match
The installation section names the requirements as numpy, scipy, scikit-learn, pydoe and Cython. The packaging metadata lists something different:
dependencies = [
    "packaging",
    "scikit-learn",
    "pydoe>=1.0.0,<2.0",
    "scipy",
    "jenn>=2.0.0,<3.0",
]
numpy is absent from that runtime list and appears only in the build requirements, alongside setuptools, setuptools-scm and wheel. Cython is in the same category: needed to compile, not needed afterwards. Two runtime libraries, packaging and jenn, appear in the metadata and never in the prose. The third declaration is a development file that carries all of it plus test tooling:
pydoe >= 1.0.0, <2.0
jenn >= 2.0.0, <3.0
egobox >= 0.36, <1.0
torch >= 2.4.1
Anyone auditing what a release pulls into an environment has to reconcile all three.
There is a fourth place to look. A conda environment file sits at the root of the tree alongside the packaging metadata, the setup script, and the requirements file, which makes four separate answers to the question of what this project needs to build and run. Each was written at a different time and each carries a different level of constraint, from the loose lower bounds in the requirements file to the exact ranges in the extras.
Windows compiles the extensions without the C++ standard flag
What pip installs is not pure Python. A minimal setup script cythonizes three extensions: an RBF library, an inverse distance weighting library, and an RMT set whose sources are four separate C++ files plus one Cython wrapper. The compile flag is set by platform:
extra_compile_args = []
if not sys.platform.startswith("win"):
    extra_compile_args.append("-std=c++11")
So Linux and macOS builds are told to target the C++11 standard and Windows builds are told nothing, which leaves the compiler default in charge. The RMT extension alone compiles from four C++ files named utils, rmts, rmtb and rmtc plus its Cython wrapper, and each extension is handed the NumPy include directory explicitly because the C++ side reaches into NumPy's headers. The metadata advertises C++ as a programming language alongside Python, and lists Windows, Unix and macOS as supported operating systems, and the requirement is CPython 3.10 or newer. In other words a source install on any of the three supported systems runs a real compilation step, and one of them runs it with a different flag set.
The version string is computed from git tags at build time
The project table declares no version at all. It marks the field dynamic and delegates to setuptools-scm, configured with a guess-next-dev version scheme and a node-and-date local scheme. That is why the release numbers look the way they do, and it has two consequences for anyone installing. A tagged install produces the released number, while a checkout of the master branch produces a development version assembled from the commit and the date, so two people installing from source on different days get different version strings for the same code. The same mechanism means a build from an exported source tree with no git history has no tag to read. Package discovery is narrowed to the smt package prefix, and the declared package data ships py.typed alongside the Cython and header sources, so type information and the extension sources travel inside the distribution.
The legacy citation block uses field names no bibliography style reads
Two citation blocks are offered, one for the current release and one for the legacy framework. The legacy block is the problem. Its fields are capitalised, Author, Journal, Title, Year, where the surrounding conventions in the same file use lower case, and most styles will ignore them, which means a copied legacy entry can render without an author or a year. The current block is spelled correctly but carries a typo that survives into any generated bibliography: the journal name is written Advances in Engineering Sofware inside the BibTeX while the sentence introducing it spells it Software. The author list also differs between that sentence and the block beneath it. If you cite this work, treat the entry as text to correct rather than something to paste.
The surrounding publication list has the same problem in milder form. It mixes journal articles, a preprint, and two conference papers, and several of the listed works come from authors who are not on the current release paper at all. A few entries are typeset with an en dash inside a title and inside a page range, which is invisible in a rendered page and fatal to a plain text bibliography pipeline. The most recent item is dated 2026, so the list is being maintained rather than left as a historical note.
Optional extras reach for a JIT compiler and for PyTorch
Three optional groups are declared, and each one pulls in a different large dependency:
numba = ["numba~=0.64"]
gpx = ["egobox~=0.36"]
rbfgen = ["torch>=2.4.1"]
The Gaussian process path is therefore not self contained, it borrows from another Gaussian process library, while the RBF generation path requires a deep learning framework. That is a large install for an optional feature, and the version constraints are stated twice with different meanings: the extra asks for egobox at roughly 0.36, while the development requirements file allows anything from 0.36 up to but not including 1.0. The same duplication applies to torch, which is bounded only from below in both places. Anyone assembling a reproducible environment needs to decide which of the two statements to honour.
The development requirements file also annotates its own entries, which is where the intent becomes clearest. numba is labelled a JIT compiler, matplotlib is labelled as used in examples and tests, pytest-xdist is labelled as allowing parallel testing with a worker count flag, and ruff is labelled as the formatter and linter. So the same project that presents a small scientific library also expects a plotting stack, a test runner, a coverage tool, and a linter in the development environment, none of which reach a user who installs from the packaged release.
The test configuration silences the non-interactive figure warning
One line in the pytest configuration decides what the suite tolerates:
filterwarnings = ["ignore:FigureCanvasAgg is non-interactive:UserWarning"]That suppresses the warning matplotlib raises when a figure is created on a non-interactive canvas, which is exactly what happens on a headless test worker. The effect is that plotting mistakes surface as a file on disk instead of as a warning in the log. Around it sit the other quality gates: a coverage configuration file at the root and a coverage badge in the header, a pre-commit configuration, and a lint configuration that selects the E, F and W rule sets at a maximum line length of 120. Documentation is generated by custom tooling that embeds tested code and dynamically produced plots, which is the stated reason contributors do not have to maintain examples by hand. The build side of that arrangement is a readthedocs configuration file and a single doc directory at the root, and the coverage gate is what makes the embedding claim testable, since a snippet in the guide and a snippet in the suite can be the same object.
Stable, latest, and plain http are all used for the same documentation
Four references to the same site use three different targets. The project metadata points at the stable documentation. The documentation section of the readme points at the same stable page over plain http. The badge in the header points at latest. The contributing link points into a developer page under the latest tree. Default branch is master, which is also what the source install targets:
pip install smtpip install git+https://github.com/SMTOrg/smt.git@masterThe two commands are the whole installation story, and the second one moves as master moves, so the two do not install the same code on the same day. Learning material lives in a tutorial notebook tree and an examples folder inside the package, which is also why the project presents itself as notebook shaped rather than as a compiled library. Releases are frequent by comparison with that branch: 2.14.0 in May 2026, 2.14.1 in June, and 2.15.0 in September, with the last push to master landing days after the September tag.
Editorial conclusion
SMT fits research and engineering work where gradients of the surrogate matter, hierarchical or mixed variables are in play, and a compiler is available at install time. It does not fit a locked-down production environment that installs from wheels only, or a team that needs to know which libraries a release pulls in without reading three files. Before adopting a version, check that the build toolchain matches your platform, because Windows compiles the extensions without the C++ standard flag the other platforms get. Check which optional extra you actually need, since the reranker path can pull in PyTorch. And check the version string, because a checkout rather than a tagged install produces a development build whose number nobody chose.
Frequently asked questions
Does installing SMT require a compiler?
A source install does. The build requirements list numpy and Cython alongside setuptools, and a setup script cythonizes three extensions from C++ and Cython sources, so a platform without a working toolchain needs a prebuilt wheel instead.
What Python versions does SMT support?
Python 3.10 and newer on CPython, with Windows, Unix and macOS all listed as supported operating systems. The classifiers name 3.10 explicitly.
How do I install the development version of SMT?
Install straight from the default branch with `pip install git+https://github.com/SMTOrg/smt.git@master`. Because the version is derived from git tags by setuptools-scm, that build reports a development version rather than a release number.
What extra dependencies can SMT pull in?
Three optional groups exist: numba pinned to roughly 0.64, egobox pinned to roughly 0.36 for the gpx path, and torch at 2.4.1 or newer for the rbfgen path. None of them are installed by default.
What does SMT do that other surrogate modeling libraries do not?
It emphasizes derivatives, covering training derivatives used for gradient enhanced modeling, prediction derivatives, and derivatives with respect to the training data. It also ships models described as unavailable elsewhere, namely kriging by partial least squares reduction and energy minimizing spline interpolation.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/smtorg-smt)Star history chart for your README
[](https://hysenlabs.com/projects/smtorg-smt)Was this useful?