Biomni makes you build a conda environment before pip sees it, and the data lake arrives on its own
Biomni: a general-purpose biomedical AI agent
At a glance
- What is it?
- snap-stanford/Biomni is a general-purpose biomedical agent you drive with natural-language tasks, combining language-model reasoning with retrieval-augmented planning and code execution. Installing it means setting up a separate environment directory first, then installing the package, and the first agent you construct downloads roughly eleven gigabytes of data lake unless you tell it not to.
- Who is it for?
- Biomni fits a specific situation: a computational biology group that wants a single agent entry point across many tool families rather than a library they wire together themselves, and that already has a conda workflow and API keys for a frontier model.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 5 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
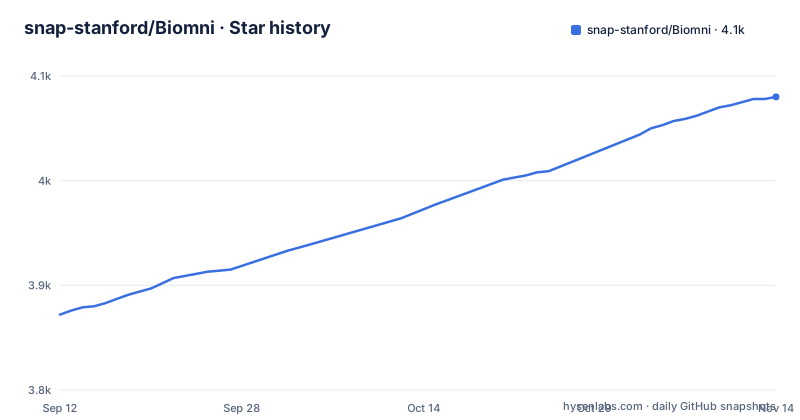
- snap-stanford/Biomni4,080 ★ · +208
| Repository | 2026-09-12 | 2026-11-14 |
|---|---|---|
| snap-stanford/Biomni | 3.9k | 4.1k |
208 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Installation is two stages, and the first one is not pip
The package is not the whole installation, and the readme is direct about why: the software environment is described as massive, and a separate setup script is provided to create it, with a linked environment readme you follow first. Only after that do you activate the environment:
conda activate biomni_e1and only then install the official package:
pip install biomni --upgradeThere is a third path for the newest code, straight from the default branch:
pip install git+https://github.com/snap-stanford/Biomni.git@mainSo a working install is a conda environment named biomni_e1, created by a script that lives in the repository's own biomni_env directory, plus a pip install on top of it. The project version is not written in the packaging manifest at all: it is declared dynamic and read from the biomni version module, which is why the release tags and the installed version can be checked against the same source rather than a duplicated literal.
The first agent you build downloads about eleven gigabytes
Constructing the agent is what triggers the data download, not an explicit setup step. The constructor takes a data path and a model, and the comment on the first example notes that the data lake is downloaded automatically on first run at roughly eleven gigabytes. That behaviour is switchable, and the switch is passed to the same constructor:
from biomni.agent import A1

# Skip automatic datalake download (faster initialization)
agent = A1(path='./data', llm='claude-sonnet-4-20250514', expected_data_lake_files = [])
Three cases are named for using it this way: faster testing and development, environments with limited storage or bandwidth, and cases where you only need specific tools that do not require data lake files. The default is left as the download, which is a reasonable choice for research work and a bad surprise on a laptop with a metered connection, since the eleven gigabytes arrive at object creation rather than at a moment you chose. The third parameter name is worth reading closely, because it describes expected files rather than a boolean, so the switch is about declaring an empty expectation.
The model is a constructor argument, and the agent is called A1
There is no house model here, which is the first thing to understand about the design. The agent class is A1, and it takes the model as a string, with a dated Anthropic identifier in the examples and a plain gpt-4 elsewhere. Everything else follows from that choice being free. Provider keys documented across the readme include an Anthropic key described as required for Claude models, an OpenAI key, Azure OpenAI with its own endpoint variable, an AI Studio Gemini key, a Groq key, an AWS Bedrock bearer token paired with a region that defaults to us-east-1, and a commented custom model base URL with its own key in the environment template. One rule catches people out: if you plan to use Azure, the model name must be prefixed with azure-, for example azure-gpt-4o. So the failure mode is silent, a prefix you forget and a model the code cannot resolve.
The environment template and the readme snippets list different providers
Two documented ways to set keys are given, a .env file copied from the example, or exports in your bash profile. The interesting part is that they do not agree, and the repository's own example file is the more trustworthy of the two. The readme's .env snippet shows ANTHROPIC_API_KEY as required, then offers OpenAI, then offers Azure OpenAI by writing OPENAI_API_KEY a second time with a different comment and a different value, which means following that snippet literally leaves you with one of the two keys missing. The shell export list is broader still, adding the Bedrock token, the region, Groq and a variable named LLM_SOURCE. The example file in the repository root is narrower: Anthropic required, OpenAI optional, Bedrock token and region optional, and commented lines for a custom model base URL, a custom model API key, a data path and a timeout. Use that file as the list.
Some features are not installed because of dependency conflicts
The most consequential admission in the installation section is a short one: some Python packages are not installed by default in the Biomni environment because of dependency conflicts. If you need those features you must install the packages yourself, and you may need to uncomment relevant code in the codebase. Both halves matter. The first is a resolution decision by whoever built the environment, and the second is a change to source code, so the feature is not merely missing a dependency, it is switched off in the code as well. The current list and details live in a known conflicts document under docs. Combined with the package manifest, which declares only three runtime dependencies, pydantic, langchain and python-dotenv, and requires Python 3.11 or newer, the picture is a small library sitting on top of an environment that carries the weight, and the environment is where the version conflicts live.
Per-agent parameters do not reach the database queries
Configuration comes in three shapes, environment variables, runtime changes to a central config object, and direct constructor parameters, and they do not all reach the same code. The recommendation is to modify the global defaults rather than pass parameters:
from biomni.config import default_config
from biomni.agent import A1

# RECOMMENDED: Modify global defaults for consistency
default_config.llm = "gpt-4"
default_config.timeout_seconds = 1200
The note underneath is the part to remember: parameters passed directly to the constructor affect only that agent's reasoning, not database queries, so for consistent behaviour across all operations the config object or environment variables are the route. The timeout value is part of the same story, since a default of 1200 seconds is what every subsequent agent and query inherits. A configuration guide under docs is referenced for the full set of options, and the environment template carries matching commented entries for a data path and a timeout, so the two layers line up.
The Gradio interface is pinned below version 6
A browser interface is available through a launch method on the agent, and it comes with its own installation and version constraint. The extra to install is pinned:
pip install "gradio>=5.0,<6.0"The reason is given as an API change in Gradio 6.0, and the instruction for anyone who already has 6.x installed is to downgrade. The same pin appears in the packaging manifest, where Gradio is an optional dependency rather than a core one, so a plain install of the package does not bring the interface along. Three options are documented for the launch: a share argument that creates a public shareable link, a server name that defaults to 0.0.0.0 with localhost given as the alternative, and a verification flag that requires an access code, with the default code written in the documentation itself. That last detail matters if you expose the interface: the code that guards it is printed in the readme.
Releases stopped at 0.0.8 while commits kept arriving
The maintenance picture is worth reading before you pin anything. Three releases are visible: 0.0.8 on 2025-10-27, 0.0.7 on 2025-09-29 and 0.0.6 on 2025-08-20. The last push to the default branch is 2026-09-28, so roughly eleven months of commits have landed without a new release, and the recommended install for the newest code is the direct from main path rather than the package index. The 0.0.x numbering is the conventional signal that the interface is not settled, which is consistent with a project whose readme tells you it may ship code you have to uncomment. The repository layout supports that reading: the package sits in biomni, the environment files sit in biomni_env, and alongside them sit docs, tutorials, a figures directory, a licence information file and a details document. The contribution file is also named in the singular.
Editorial conclusion
Biomni fits a specific situation: a computational biology group that wants a single agent entry point across many tool families rather than a library they wire together themselves, and that already has a conda workflow and API keys for a frontier model. It does not fit a quick trial, because the setup is a two-stage environment build and the first run pulls about eleven gigabytes, and it does not fit a lab that needs one documented model, since the model is a parameter with at least seven provider paths and a prefix rule for Azure. Two things to check before you commit. That the model you pick is one of the keys the environment template documents, since the two configuration snippets in the readme and the example file in the repository do not list the same providers. And that you read the known conflicts list, because some features are deliberately not installed and need code uncommented, which changes what the agent can actually do. Releases stopped at 0.0.8 in October 2025 while commits continued.
Frequently asked questions
What is Biomni?
It is a general-purpose biomedical AI agent from Stanford that autonomously executes research tasks across biomedical subfields. It combines large language model reasoning with retrieval-augmented planning and code-based execution, is licensed Apache-2.0, requires Python 3.11 or newer, and is driven by natural-language task strings rather than a fixed API per tool.
What model does Biomni use?
Whichever one you name. The agent class is A1 and the model is a constructor string, with examples using a dated Claude identifier and a plain gpt-4. Documented provider keys cover Anthropic, OpenAI, Azure OpenAI, Gemini, Groq and AWS Bedrock, plus a custom base URL, and the readme warns that Azure models must have the model name prefixed with azure-.
How do I use Biomni?
You set up the conda environment from the scripts in the biomni_env directory, activate biomni_e1, then pip install biomni. After that you construct an agent with a data path and a model and call go with a natural-language task. Constructing the agent downloads roughly eleven gigabytes of data lake on first run unless you pass expected_data_lake_files as an empty list.
Is Biomni free?
The code is, under an Apache-2.0 licence, and installing it from the package index or from source costs nothing. What does cost is inference: an Anthropic key is the one required variable, and OpenAI, Azure OpenAI, Gemini, Groq, Bedrock and custom model endpoints are all optional and all paid. The repository documents no hosted service, no account and no subscription.
What does Biomni do?
It plans and executes biomedical research tasks with code execution behind the plan. The three examples given are planning a CRISPR screen to find genes regulating T cell exhaustion, annotating single-cell RNA sequencing data and generating a hypothesis from it, and predicting ADMET properties for a compound given as a SMILES string. It can also save a conversation trace as a PDF report.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/snap-stanford-biomni)Star history chart for your README
[](https://hysenlabs.com/projects/snap-stanford-biomni)Was this useful?