ColabFold says MIT, and then names a second set of licences
Making Protein folding accessible to all!
At a glance
- What is it?
- A notebook-driven front end to AlphaFold, RoseTTAFold, Boltz, BioEmu, OmegaFold and ESMFold, installable through Colab, conda, pip, a Docker image or a third-party installer script. Its manifest grants MIT to the code and states that the trained weights are separately licensed, every ColabFold notebook replaces jackhmmer with mmseqs2, and the b-factor column holds pLDDT rather than a real b-factor.
- Who is it for?
- Use ColabFold if you want AlphaFold, RoseTTAFold, Boltz or ESMFold reachable from a Colab notebook or from a pip install on your own machine, and you are willing to read the FAQ before feeding its output into other tools. Do not treat it as a drop-in AlphaFold: every ColabFold notebook substitutes mmseqs2 for jackhmmer, the b-factor column holds pLDDT rather than a real b-factor, and two different models are offered for complexes.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 7 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
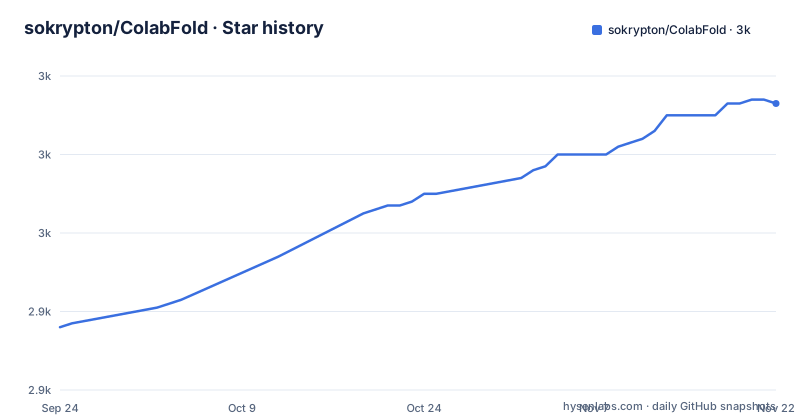
- sokrypton/ColabFold2,990 ★ · +54
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| sokrypton/ColabFold | 2.9k | 3k |
54 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
MIT for the code, and a second set of licences for the weights
The manifest's licence field is the shortest line in it and the most important:
`license = "MIT, but separate licenses for the trained weights"`
So the grant and the exception are in the same field. The code is MIT. The trained weights are not, and the project does not pretend otherwise in the field where a packaging tool will read it.
The repository metadata, separately, records a plain MIT with no qualification. That is the value a scanner or a dependency bot will see, and it is the one that omits the exception.
For anyone building on this, the practical consequence is that there are two questions to answer separately. Whether you may use the code is settled by MIT. Whether you may use a particular set of weights is not settled by anything on this page, and the answer varies by which notebook you run, since the table covers AlphaFold, RoseTTAFold, Boltz, BioEmu, OmegaFold and ESMFold and each of those models carries its own terms.
Nothing here is a warning against the project. It is a reminder that a single licence field with a clause after the semicolon is not the same as a single licence, and that the weight terms have to be looked up per model rather than read off the repository.
The authorship also deserves a note. Six authors are listed in the manifest, from four institutions, while the repository lives in a single personal namespace, `sokrypton`, which matches none of them.
Every ColabFold notebook swaps jackhmmer for mmseqs2
The notebook table has five capability columns, and the third and fourth of them are the interesting pair: mmseqs2 and jackhmmer.
Read the two method columns across every row. AlphaFold2_mmseqs2, AlphaFold2_batch, the OpenFold3 notebook, RoseTTAFold2, Boltz, BioEmu, OmegaFold and AlphaFold2_advanced_v2 all use mmseqs2 and none uses jackhmmer.
The single exception is DeepMind's own AlphaFold2 notebook, which is linked from the deepmind/alphafold repository rather than from this one. That row has mmseqs2 marked No and jackhmmer marked Yes, and templates marked No. Every row that has templates uses mmseqs2, so the template feature and the MSA server come as one decision in this table.
The matrix is not fully filled in, and that is visible rather than hidden. Two cells read Maybe rather than a decision: ESMFold and OmegaFold on complexes. One reads No: BioEmu on complexes, which is notable for a beta entry. And one reads WIP: RoseTTAFold2 on templates.
So a reader planning a complex prediction has to check three different qualifiers in that column, not just yes or no.
One more detail. The newest experimental notebook, AlphaFold2_advanced_v2, is not in this repository. Its link points at the ColabDesign repository, on a branch called gamma.
The b-factor column holds pLDDT, and it points the wrong way for Phenix
The FAQ contains the most consequential warning in the repository, and it is about using the output rather than producing it.
Asked whether the models can be used for molecular replacement, the answer is yes, but be CAREFUL: the bfactor column is populated with pLDDT confidence values, where higher is better. Phenix.phaser expects a real b-factor, where lower is better.
So a structure file from a ColabFold notebook is not directly usable by molecular replacement software, because the semantics of the column are inverted. The README links a third-party post from Claudia Millán on the subject.
The same column shows up in the rendering answer, and the two model families need different ranges. For AlphaFold structures the PyMOL command is a spectrum over the b column with `minimum=50` and `maximum=90`. For RoseTTAFold structures the same command uses `minimum=0.5` and `maximum=0.9`. Different scales, because the two models write different values into that column.
For the AlphaFold colour scheme specifically, the page gives four named colours and a thresholded rule, credited to Konstantin Korotkov:
    set_color n0, [0.051, 0.341, 0.827]
    set_color n1, [0.416, 0.796, 0.945]
    set_color n2, [0.996, 0.851, 0.212]
    set_color n3, [0.992, 0.490, 0.302]
    color n0, b < 100; color n1, b < 90
    color n2, b < 70;  color n3, b < 50
Note the thresholds there are 100, 90, 70 and 50, a wider range than the spectrum command's own 50 to 90.
Length limits come from a free Colab GPU, and the MSA server is shared
Two FAQ answers describe the constraints that are not the software's.
The first is maximum length. The answer is that limits depend on the free GPU provided by Google Colab, followed by the word `fingers-crossed`, and then a number: for GPUs with about 16G, the maximum length is about 2000.
So the length ceiling in the hosted path is a property of a free tier, not of the model, and the page does not give a figure for hardware you own.
The second is the shared MSA server. You can reach it from a local computer if your queries are serial and come from a single IP, and the instruction not to use multiple computers to query the server is stated plainly. The databases themselves are at colabfold.mmseqs.com, and their version history is on a wiki page.
The repository contains the server side of that arrangement. `MsaServer/` is a top-level directory, `setup_databases.sh` is the script that fetches the databases, and `colabfold_search.sh` is the query script. So the public service people are told to use serially is code in this tree, and the page keeps a version history for its contents because the contents change under the tools that depend on them.
Two ways to predict a complex, and they are different models
The FAQ answers a question that the notebook table does not: what is the difference between AlphaFold2_advanced and AlphaFold2_mmseqs2, and its _batch variant, for complex prediction.
The answer is that there are two different ways to predict protein complexes. The first uses the AlphaFold2 model with a residue index jump, and the second uses the AlphaFold2-multimer model. AlphaFold2_advanced supports the first, and AlphaFold2_mmseqs2 and _batch support the second.
So the two notebooks are not a basic and an advanced version of the same thing. They implement different models, and choosing between them is a modelling decision rather than a usability one.
The same distinction shows up in the complex column of the table, where ESMFold and OmegaFold are marked Maybe rather than a plain yes, which is the same hedge: the answer depends on which model you are running.
There is also a shortcut to the expensive part. Asked whether structures can be amber-relaxed without rerunning the prediction from scratch, the answer points at a notebook, `relax_amber.ipynb`, in the repository's `beta/` directory. So relaxation is separable from folding, which is the one piece of genuinely useful engineering in the list for anyone running this at volume.
Platform support is encoded as dependency markers
There is no platform table in the README, and the manifest is where the support matrix actually lives.
`colabfold-binaries` carries the marker `sys_platform == 'linux' or (sys_platform == 'darwin' and platform_machine == 'arm64')`. So it installs on Linux, and on macOS only when the machine is arm64.
`colabfold-legacy-kernels` carries a different one: `sys_platform == 'linux' and platform_machine == 'x86_64'`. So it installs only on x86_64 Linux.
Put together, that means an Apple Silicon Mac gets the binaries package and no legacy kernels, and an x86_64 Linux machine gets legacy kernels and no binaries. An x86_64 Mac gets neither, and nothing on the page says so in prose.
The version pins are similarly deliberate and similarly explained by comments. Python is `>=3.10` in the manifest, while the conda recipe in the README creates an environment at `python=3.13`. `biopython` carries an upper bound of `<1.86`. And `jax` is bounded above at `<0.12` with a comment saying that colabfold-legacy-kernels needs at least 0.6.2 and that it should be checked before the top is raised, so the ceiling is set by another dependency rather than by taste.
The mmseqs2 build is pinned twice, in two different forms. The conda line specifies `mmseqs2=18.8cc5c`, a build-specific version, and the Docker image pins the same build by hash in a build argument.
The Dockerfile chooses its MMseqs2 tarball from the target architecture
The container build is the clearest piece of engineering in the repository, and it starts with a trick.
Two stages are named from a build argument: `FROM scratch AS amd64_downloader` and `FROM scratch AS arm64_downloader`, each with an `ONBUILD ADD` that fetches an MMseqs2 GPU tarball from mmseqs.com, the amd64 one and the arm64 one respectively. Then a single line, `FROM $downloader AS downloader`, resolves to whichever of the two matches `TARGETARCH`. The download only runs for the stage that is used.
A builder stage on debian:trixie-slim untars whatever it received, moves everything under each archive's `bin/` into a `binaries/` directory and makes it executable. A final slim stage installs wget, git, python3 and python3-venv, creates a virtualenv at `/usr/local`, drops the binaries into `/usr/local/bin/`, copies the application to `/app` and installs the package with the alphafold and openmm extras.
Two details are worth knowing. The CUDA variant is a build argument defaulting to `cuda12`, and the install line interpolates it into both the jax and openmm extras. And the runtime declares `VOLUME cache` with `MPLBACKEND`, `MPLCONFIGDIR` and `XDG_CACHE_HOME` all pointed at it, so plotting output is non-interactive and its cache survives a rebuild.
Finally, the layout explains the repository's recorded primary language. The notebooks sit at the root, six of them, which is why this reads as a Jupyter Notebook project, while the actual package lives in `colabfold/`.
Editorial conclusion
Use ColabFold if you want AlphaFold, RoseTTAFold, Boltz or ESMFold reachable from a Colab notebook or from a pip install on your own machine, and you are willing to read the FAQ before feeding its output into other tools. Do not treat it as a drop-in AlphaFold: every ColabFold notebook substitutes mmseqs2 for jackhmmer, the b-factor column holds pLDDT rather than a real b-factor, and two different models are offered for complexes. Verify first what you are licensed to use, because the manifest grants MIT to the code and states that the trained weights carry separate licences, then check which platform you are on, since the binaries and legacy-kernel packages are gated to different architectures by dependency markers.
Frequently asked questions
What is ColabFold?
It is a set of Colab notebooks and a pip-installable package that make several structure prediction models accessible from a notebook or a local machine. The manifest describes it as making protein folding accessible to all and predicts protein structures both in Google Colab and on your own machine.
How do you install ColabFold?
Four ways are given. The notebooks run in Google Colab with no install. For a local machine, a one-step installer script supports Linux, macOS and Windows through WSL2. The conda and pip route creates a conda environment with python=3.13 and mmseqs2=18.8cc5c, then installs the colabfold package with the alphafold and openmm extras. A Dockerfile is also provided in the repository.
Is ColabFold free to use?
The code is MIT licensed, and the manifest's licence field says so while adding that the trained weights have separate licences. The repository's own metadata carries a plain MIT with no such qualification, so a scanner will not show you the exception.
What are the key differences between AlphaFold and ColabFold?
The notebook table shows the substitution. DeepMind's own AlphaFold2 notebook, linked from the deepmind/alphafold repository, uses jackhmmer for multiple sequence alignment and has no template support. Every ColabFold notebook uses mmseqs2 instead, and the ones that support templates use mmseqs2 as well, so the MSA server and the template feature come as one decision.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/sokrypton-colabfold)Star history chart for your README
[](https://hysenlabs.com/projects/sokrypton-colabfold)Was this useful?