MaidKit installs nothing on your server, except the one daemon its web build needs
The ultimate SSH toolkit for developers
At a glance
- What is it?
- A Flutter SSH server manager covering fourteen areas from terminals to databases, with an agent that can operate servers through tools, a local MCP server that exposes those servers to other agents, an encrypted credential vault, and an optional cloud layer reached over an outbound-only connection. The design keeps the server untouched by default and puts a daemon on it the moment you want anything off-workstation.
- Who is it for?
- MaidKit suits someone who wants a graphical console for servers they already reach over SSH and does not want an agent installed on any of them, which is the honest reading of its default posture. Before you enable the cloud layer, decide which daemon-backed features you actually need, keep review mode on for the agent, and read the credential vault notes, since conversation history is deliberately kept outside it and the packaged application is AGPL licensed.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Dart, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
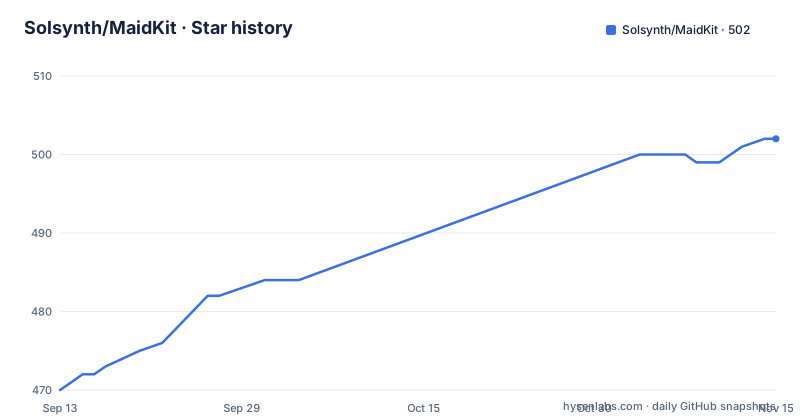
Star history
- Solsynth/MaidKit502 ★ · +32
| Repository | 2026-09-13 | 2026-11-15 |
|---|---|---|
| Solsynth/MaidKit | 470 | 502 |
32 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The default posture installs nothing on the server
The stated design goal is non-intrusive maintenance: day-to-day management is entirely SSH based, with nothing installed on the server. That constraint explains most of the feature list, because each item is something you can do over an existing session.
Terminals with split panes and a command palette, a dual-pane SFTP browser, systemd unit control, nginx and Caddy configuration, package management across several systems, four firewall front ends, local and remote tunnels, a jump host, database inspection and logical backups, a per-server CONNECT or SOCKS5 proxy, and an embedded Tailscale node that needs no client application on your laptop. All of that is reachable without a resident process.
The optional layer changes that. The cloud component adds a small daemon that connects outbound only, so no inbound ports are opened to the internet, and it installs itself in one flow: the client probes the server over SSH, installs the daemon, and registers it in a workspace automatically. The daemon then runs on its own, so the desktop application does not have to stay open.
Several features are explicitly better with the daemon rather than merely possible with it. Activity charts are backed by its history, process usage history is realtime through it, and the container, process, systemd and deployment views route through it when present with SSH as the fallback, which is what makes those views work from anywhere rather than only from a desktop session.
So the boundary is not really SSH versus cloud. It is what you can see versus what you can see without looking at the machine.
The browser build cannot work without the daemon
There is a web build, and it works by a completely different route from the desktop applications.
The desktop clients connect over SSH because they run on an operating system that can open an SSH connection. A browser cannot, so the web build renders its terminals with a terminal emulator library and reaches servers through MaidCafe daemons over WebSocket instead. A separate support document is pointed at for what runs there and what does not.
That is a clean architectural answer, and it has a consequence worth stating plainly. The feature the project leads with, that nothing is installed on your servers, is exactly what the browser build cannot deliver. Access from a browser requires having already installed the daemon on each server you want to reach.
So there are three postures in practice, not two. Desktop with SSH only, which installs nothing anywhere. Desktop with the daemon, which adds fleet visibility and background operation. Browser, which requires the daemon everywhere and therefore has no install-nothing mode at all.
The README is upfront that a browser build exists and points at a document rather than summarising the limitations itself, so the details are there to find, but the choice between the desktop and browser builds is effectively a choice about whether your servers will run a resident process.
An agent that can kill processes, gated by review mode
The agent surface deserves to be read carefully, because the tool list underneath it is not gentle.
You chat with an agent that operates your servers through tools, using your own AI provider or the vendor's hosted one, with models auto-discovered from whichever providers you configure. MCP servers and reusable skills extend what it can reach. Critically, proposed actions require approval in review mode before they run, and the same daemon-backed tools the interface offers are what the agent calls.
So the review-mode gate is the only thing standing between a language model and a tool set that includes killing processes and removing containers. That is a reasonable design, and it is worth noting that review mode is described as a mode rather than as mandatory, since the wording reads as something you turn on.
The compounding factor is the local MCP server. MaidKit can expose its own SSH servers, snippets and skills to other agents running on the same machine, and the documentation names Claude Desktop as one client. That creates a chain: another agent calls MaidKit, MaidKit opens an SSH session, the session runs a command. Each link is individually defensible and the combined path is the thing to reason about.
One deliberate boundary is documented. Conversation history with the agent is stored on the machine, outside the credential vault. That keeps transcripts out of the encrypted store, and it means the vault protects credentials rather than everything the application holds.
The vault is AES-GCM with 310,000 PBKDF2 iterations
The credential store is specified in enough detail to be useful rather than decorative. Encryption is AES-GCM with a 256-bit key. Key derivation is PBKDF2 at 310,000 iterations, which is a deliberately expensive figure chosen to make offline guessing of a weak passphrase expensive. Biometric unlock is supported. Cloud synchronisation is optional and operates per vault over encrypted blobs, so the cloud stores ciphertext it cannot read. Encrypted backup archives carry their own file extension, and GitHub access tokens are stored in the same vault.
That is a coherent security posture with one design decision you have to notice: the agent's conversation history lives outside this store. Transcripts of what an agent was asked and what it did are not covered by the vault's encryption, which is a deliberate trade for keeping transcripts out of backups and syncs, and is worth being deliberate about yourself.
The second observation is about scope. PBKDF2 is a password-based derivation, so its strength is bounded by the passphrase behind it. A 310,000-iteration figure raises the cost of an offline attack substantially and does nothing about a four-word passphrase that is in somebody's notes.
Biometric unlock changes that calculation in a useful direction on a machine with a secure enclave, since it removes the human-typed component from the path.
The settings list that would close this section is cut off mid-item in this copy of the documentation, at a single letter, so whatever host-key behaviour the application offers is not visible here.
The daemon exposes a patch API over its own configuration
Two capabilities make the daemon more than a metrics forwarder.
The first is hot reload. The daemon watches its configuration and its fragment files, answers a service reload signal, and exposes a redacted read plus a safe-subset patch endpoint on its configuration API, so a configuration save applies without restarting the service. Redacting the read while allowing a patch is the right asymmetry: an operator can see the shape without the read exposing secrets, and a change does not require a restart on a component that other things depend on.
The second is that the daemon performs native host operations directly: container lifecycle including start, stop, restart, pause, kill and remove, process kill, systemd unit actions and compose project actions. This is what makes the toolset work through the cloud relay rather than only from a workstation.
Around those sit the operational pieces. Alarm thresholds are evaluated locally by the daemon rather than in the cloud, so an alarm does not depend on the network path that the daemon uses. Scheduled jobs run on the daemon with either cron or interval syntax, targeting both action scripts and native operations, with failure notifications. There is an audit log carrying invocation provenance and captured output, and API credentials for continuous integration scoped separately to daemons, hosts and actions, with a relay that delivers invocations to daemons that poll.
The combination of a kill capability, a patch endpoint and a cloud relay is why the audit log and the scoped credentials are not optional extras in practice.
Log upload is opt-in and the alerts run where the logs are
Container logs get a dedicated path, and the design choices in it are conservative.
The daemon tails running containers to disk on the server and streams the delta over server-sent events, so logs become inspectable without opening an SSH session at all. That is the part that makes the remote views useful.
Cloud upload of those logs is opt-in, and the stated reason is that logs may contain sensitive data. When enabled, they are persisted in the workspace with a retention setting rather than kept indefinitely.
The alerting also runs where the data already is. Daemon-side regular expression log alerts produce notifications under an alert name, with cooldowns so a repeating pattern does not become a notification flood. Combined with locally evaluated alarm thresholds, the pattern is consistent: the server decides what is noteworthy and the cloud is told what to show you.
That has an operational consequence. If the daemon is not running, neither the log streaming, the log alerts, the local thresholds nor the scheduled jobs fire, and the SSH-only features are all that remain. The project is honest that the daemon is optional, but the optional part is where the automation lives.
Weekly builds across six platform targets under AGPL
The packaging tells you what kind of project this is. It is a Flutter application, so the repository carries all six platform directories: Android, iOS, Linux, macOS, web and Windows, alongside a library directory, a test directory and a tools directory. There is an Inno Setup script at the top level for a Windows installer, and a toolchain pinning file so the same Dart and Flutter versions are used by every contributor.
Releases are weekly and carry an incrementing build number appended to the version, with 2.2.0, 2.3.0 and 2.4.0 paired with build counters 39, 40 and 41 across three consecutive weeks in September 2026. The dual numbering suggests tags for human meaning and a counter for the build pipeline.
The licence is AGPL, which is an unusually strong choice for a distributed desktop application. It is the right call if you want network use of a modified version to trigger the same obligation, and it is a commitment that shapes who can host a fork of the cloud layer.
The documentation surface is bilingual, with English and Simplified Chinese readmes and a matching language setting, and there is a separate support document for the web build and a conduct document.
One small sign of the documentation being maintained by hand: the push notification line refers to an in-app feed with a name that appears to be a typo.
Editorial conclusion
MaidKit suits someone who wants a graphical console for servers they already reach over SSH and does not want an agent installed on any of them, which is the honest reading of its default posture. Before you enable the cloud layer, decide which daemon-backed features you actually need, keep review mode on for the agent, and read the credential vault notes, since conversation history is deliberately kept outside it and the packaged application is AGPL licensed.
Frequently asked questions
What does MaidKit install on my servers?
Nothing by default. Day-to-day management is entirely SSH based, and the optional cloud layer adds a small daemon that only connects outbound, so no inbound ports are opened. The daemon installs itself in one flow by probing over SSH, and it runs independently of the desktop application.
Can I use MaidKit from a browser?
Yes, there is a web build, but it reaches servers through MaidCafe daemons over WebSocket rather than over SSH, because a browser cannot open an SSH connection. Using the browser build therefore means installing the daemon on every server you want to reach.
How does the MaidKit agent get permission to act on a server?
Proposed actions require approval in review mode before they run, and the agent calls the same tools the interface offers, which include process kill and container lifecycle operations. You can bring your own AI provider or use the vendor's, and models are auto-discovered from configured providers.
How does MaidKit store credentials?
In an encrypted vault using AES-GCM with a 256-bit key and PBKDF2 key derivation at 310,000 iterations, with biometric unlock supported. GitHub access tokens go in the same vault, cloud sync is optional and stores encrypted blobs, and encrypted backup archives have their own file extension.
What can the MaidKit agent or another AI tool reach?
MaidKit includes a local Model Context Protocol server that exposes its SSH servers, snippets and skills to other agents on the same machine, with Claude Desktop named as a client. The agent itself also extends its toolset with MCP servers and reusable skills you configure.
What does MaidKit manage besides the terminal?
A dual-pane SFTP browser with an in-app editor, systemd units, nginx and Caddy configuration, package management, four firewall front ends including UFW, firewalld, nftables and iptables, port forwarding with saved presets, a per-server HTTP CONNECT or SOCKS5 proxy, jump hosts, PostgreSQL, MySQL and MariaDB with logical backups, and an embedded Tailscale node.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/solsynth-maidkit)Star history chart for your README
[](https://hysenlabs.com/projects/solsynth-maidkit)Was this useful?