sql.js: SQLite compiled to WebAssembly, with a database that lives only in memory
A javascript library to run SQLite on the web.
At a glance
- What is it?
- sql-js/sql.js compiles SQLite with Emscripten so a relational database can run entirely in a browser or in Node.js. Everything happens in an in-memory virtual file, so persistence is your job and large databases are limited by memory.
- Who is it for?
- sql.js is the right tool when you need real SQLite queries inside a browser tab or a small Node.js script and can live with an in-memory database that you save yourself. It is the wrong tool for a native Node or Electron application that works with large files, where the README itself points to a native binding.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 4 days ago.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
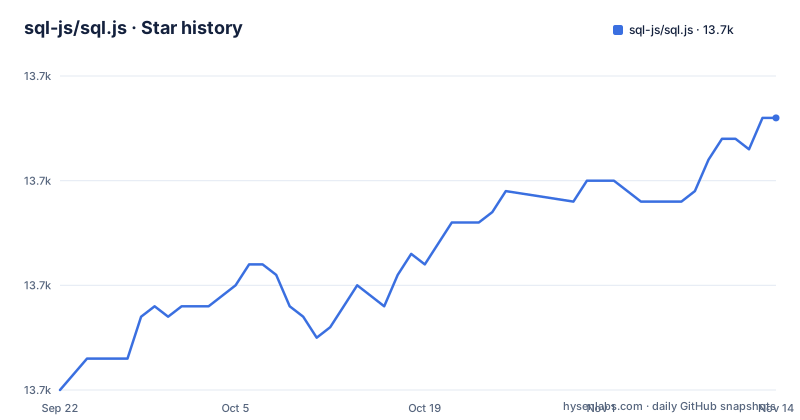
- sql-js/sql.js13,686 ★ · +26
| Repository | 2026-09-22 | 2026-11-14 |
|---|---|---|
| sql-js/sql.js | 13.7k | 13.7k |
26 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The database is a virtual file in memory, so nothing persists unless you export it
sql.js uses an Emscripten virtual database file stored in memory. The README puts it plainly: it does not persist the changes made to the database. Close the tab or end the process and the data is gone.
Two features make that workable. You can import any existing SQLite file by passing a Uint8Array to the SQL.Database constructor, and you can export the database you built as a JavaScript typed array. Saving, uploading or caching that array is your responsibility. The repository ships an examples/persistent.html file next to simple.html, repl.html and requireJS.html, so persistence has an example to read.
The consequence is that a user who edits data in your page loses it on reload unless your code writes the exported bytes somewhere. This is the first thing to design, before the schema.
Whole files must fit in memory, which is why the README sends Node and Electron users elsewhere
The README is direct about where sql.js is the wrong choice. If you are building a native application in JavaScript, for instance with Electron, or working in Node.js, it says you will probably prefer a native binding of SQLite, naming the sqlite3 package on npm.
Its reasons are concrete. A native binding runs native code and so is faster. It can also work on database files directly, instead of loading the entire database into memory, which avoids out of memory errors and further improves performance. With sql.js the entire file has to be loaded, so a database too large for the page's memory cannot be opened.
That makes the choice simple. Use sql.js where you have no native code available, such as a web page. Use a native binding for a desktop or server process with big files.
The default build needs a separate .wasm file, and locateFile is how you point to it
By default sql.js loads a .wasm file in addition to the JavaScript. After an npm install you find it at ./node_modules/sql.js/dist/sql-wasm.wasm. You then either have your bundler copy it into static assets or load it from a CDN, and tell initSqlJs where it is using the locateFile property of its configuration object.
In a browser, the README example uses a script tag for /dist/sql-wasm.js and a config whose locateFile returns the file name prefixed with /dist/. It explains that you must specify this function whenever the wasm file lives anywhere other than the current page's folder. In Node.js you can omit locateFile entirely. If you use webpack, a demo repository named react-sqljs-demo shows how to automate this.
Get this wrong and initialization fails because the binary cannot be fetched, which is the most common first problem. The default build keeps the binary separate for independent caching and streaming compilation.
sql-wasm-inline.js trades a larger file for one less asset to configure
For a single file setup, the README recommends sql-wasm-inline.js. It embeds the WebAssembly binary in the JavaScript, so there is no separate .wasm asset to serve and no locateFile configuration:
const initSqlJs = require('sql.js/dist/sql-wasm-inline.js');
const SQL = await initSqlJs();
const db = new SQL.Database();
In a browser you load it with a script tag pointing at /dist/sql-wasm-inline.js and call initSqlJs the same way. This build still requires WebAssembly support and uses the same asynchronous API as the default build. The cost is a larger JavaScript file, and you give up the independent caching and streaming compilation the default build allows.
The test scripts in package.json cover this variant separately, with test-wasm-inline and test-wasm-inline-debug, next to wasm, wasm-debug and wasm-browser. The package exports map sends browsers to ./dist/sql-wasm-browser.js and everything else to ./dist/sql-wasm.js.
Loading a database from a server needs the buffer and the library together
To open a database you host, fetch the file as an array buffer while the library initializes, then pass the bytes to the constructor:
const sqlPromise = initSqlJs({
  locateFile: file => `https://path/to/your/dist/folder/dist/${file}`
});
const dataPromise = fetch("/path/to/database.sqlite").then(res => res.arrayBuffer());
const [SQL, buf] = await Promise.all([sqlPromise, dataPromise])
const db = new SQL.Database(new Uint8Array(buf));
An XMLHttpRequest version with responseType set to arraybuffer is also given, and it returns query results shaped as columns and values arrays through db.exec. For a file the user picks, the README reads it with a FileReader and builds a Uint8Array from the result. Either route copies the whole file into memory, which ties back to the size limit above.
The compile flags decide which SQLite features exist in the build
The build is a Makefile that pins SQLite as an amalgamation, sqlite-amalgamation-3540000, with a SHA3 checksum recorded. The compiler version is pinned in .devcontainer/Dockerfile. The visible compile flags are -Oz, SQLITE_OMIT_LOAD_EXTENSION, SQLITE_DISABLE_LFS, SQLITE_ENABLE_FTS3, SQLITE_ENABLE_FTS3_PARENTHESIS, SQLITE_THREADSAFE=0 and SQLITE_ENABLE_NORMALIZE.
The practical readings are direct. Loadable extensions are omitted, so you cannot load a native SQLite extension at runtime. Full text search is enabled for FTS3. The build is single threaded. The README adds that contributed math and string extension functions are included, and the Makefile notes that extension-functions.c has not been updated since 2010-02-06. If you need a feature that needs a different compile flag, check the Makefile first, because a flag that is not set cannot be switched on at runtime.
Release cadence, Node requirements and a license field that disagrees with itself
Three releases landed in two weeks: v1.15.0 on 2026-10-14, v1.15.1 on 2026-10-19 and v1.15.2 on 2026-10-26, and the last push was the same day as the last release. The Emscripten 6 builds require Node.js 18.3 or newer when run in Node.js, while contributor tooling and CI use Node.js 24 LTS.
The repository metadata reports the license as NOASSERTION, but package.json and the README both state MIT, with SQLite itself public domain. Treat MIT as the working answer, and read the LICENSE file if compliance matters to you, since it also credits a makefile syntax source.
There is one open maintenance note in the Makefile: a TODO to create GitHub releases with the compiled assets rather than checking them in. So the dist/ folder is committed to the repository, and the compiled files you download are the checked in ones.
Editorial conclusion
sql.js is the right tool when you need real SQLite queries inside a browser tab or a small Node.js script and can live with an in-memory database that you save yourself. It is the wrong tool for a native Node or Electron application that works with large files, where the README itself points to a native binding. Decide how you will persist the exported typed array before you build on it.
Frequently asked questions
what is sql js
sql.js is a JavaScript SQL database that compiles SQLite to WebAssembly with Emscripten. It lets you create a relational database and query it entirely in the browser, keeping the data in memory.
how to install sql js
In Node.js you run npm install sql.js. You can also download sql-wasm.js and sql-wasm.wasm directly, or load the library from cdnjs in a browser.
sqlite3 vs sql js
The sql.js README says a native binding such as the sqlite3 npm package is faster because it runs native code and works on database files directly. sql.js must load the entire database in memory.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/sql-js-sql-js)Star history chart for your README
[](https://hysenlabs.com/projects/sql-js-sql-js)Was this useful?