SQLite Sync: A C Extension That Turns Tables Into CRDT Replicas, and the Backend It Still Needs
CRDT-based offline-first sync for SQLite. Syncs automatically with SQLite Cloud, PostgreSQL, and Supabase. No conflicts, no data loss, no backend to build. For offline-first apps and AI agents.
At a glance
- What is it?
- SQLite Sync (cloudsync) is an Apache-2.0 C extension that makes a SQLite table sync-aware with one function call and merges changes between devices through CRDTs. It still needs a sync target, either SQLite Cloud, PostgreSQL or Supabase, so it removes the sync protocol but not the server.
- Who is it for?
- SQLite Sync is a reasonable choice for mobile, desktop or agent apps that already keep state in SQLite and are willing to pair it with SQLite Cloud, PostgreSQL or Supabase as the hub. It is not a peer-to-peer or serverless solution despite the marketing, its Android snippet pins an old version, and merge semantics such as last-writer-wins at the line level mean concurrent edits to the same line still resolve to one winner.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 5 days ago.
- What is it written in?
- Mainly C, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
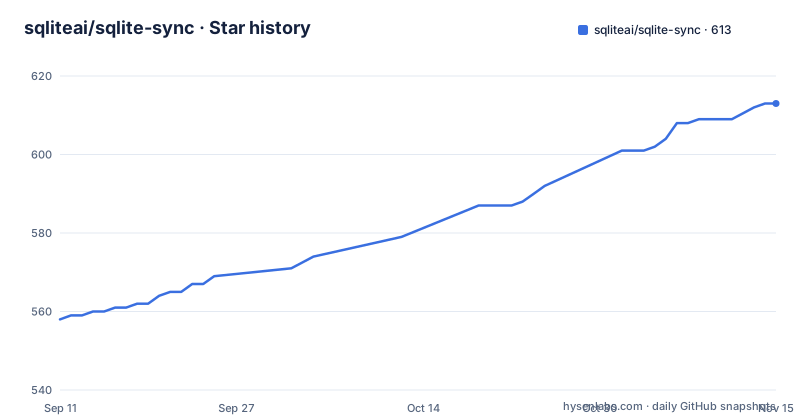
- sqliteai/sqlite-sync613 ★ · +55
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| sqliteai/sqlite-sync | 558 | 613 |
55 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Sync is switched on per table with one function after loading the extension
SQLite Sync is a multi-platform extension, loaded into SQLite like any other. In the SQLite CLI you run `.load ./cloudsync`, and from code `SELECT load_extension('./cloudsync');`. Once loaded, you create a table normally and then enable sync on it:
.load ./cloudsync

CREATE TABLE tasks (
    id TEXT PRIMARY KEY,
    title TEXT NOT NULL DEFAULT '',
    done INTEGER NOT NULL DEFAULT 0
);

-- Enable CRDT sync on the table
SELECT cloudsync_init('tasks');
After that you use the database as usual. The example inserts rows with `cloudsync_uuid()` as the identifier:
INSERT INTO tasks (id, title) VALUES (cloudsync_uuid(), 'Buy groceries');
INSERT INTO tasks (id, title) VALUES (cloudsync_uuid(), 'Review PR #42');

UPDATE tasks SET done = 1 WHERE title = 'Buy groceries';

SELECT * FROM tasks;
The detail to take from the example is the primary key. It is a text column filled with a generated UUID, not an auto-incrementing integer. Two offline devices that both count from 1 would collide, while UUIDs generated independently do not. When you adopt the extension on an existing schema, plan for how identifiers are produced on each device before you enable sync.
The no-backend claim has fine print: you still pick a hub for the data
The headline promises no backend to build and no central coordinator required, and the tagline says one function call is all it takes. Read the next lines too. SQLite Sync syncs automatically with SQLite Cloud nodes, PostgreSQL servers and Supabase instances. A boxed note asks whether you need a sync backend and offers three answers: plug into any PostgreSQL, plug into a self-hosted Supabase, or use SQLite Cloud CloudSync, which links to a pricing page.
So something always sits in the middle. The README describes a globally distributed network of CloudSync microservices that handle routing, packaging and delivery of changes between SQLite and other database nodes. That removes the work of writing a sync protocol, but it does not remove the infrastructure: you either run a PostgreSQL or Supabase target with the repository's quickstart guides, or use the managed service.
A free managed instance is offered through a dashboard sign-in link, and the page does not give limits for it. If your requirement is two phones syncing directly with no server of any kind, this design does not meet it. Decide on the hub early, because it determines cost, hosting and who can see your data.
Merging uses CRDT algorithms, and Block-Level LWW handles text line by line
The merge guarantees are stated as three points: no data loss, no conflicts and no extra infrastructure. Devices update independently, even offline, and changes merge automatically with a deterministic merge and no manual conflict resolution.
The feature table names the algorithms: Causal-Length Set, Delete-Wins, Add-Wins and Grow-Only Set. Alongside them sits Block-Level LWW, described as line-level merge for text and markdown columns, where concurrent edits to different lines are preserved. It was designed specifically to keep markdown files in sync, so that multiple agents editing different sections of the same document keep all their changes after sync.
The limits follow from the names. LWW stands for last writer wins, so if two devices edit the same line, one version wins and the other is dropped, even though nothing throws an error. Delete-Wins and Add-Wins are policy choices about what happens when one device deletes a row another edited, and you should check which applies to your table before relying on it. Conflict-free here means the merge always completes and converges, not that every intent survives. For data like a shared task list that is fine, and for edits that must not lose a single character it needs thought.
Row-Level Security is enforced on the server, not by the client
Multi-user apps need to control who sees which rows. The feature table lists Row-Level Security as server-enforced, so each client syncs only the rows it is authorised to see. The use cases include CRM systems that sync leads and clients per user with row-level access control, and SaaS platforms with row-level access for each user or team on a single shared database.
The server side matters because a client cannot be trusted to filter itself. If the extension merely hid rows locally, anyone could read the full database file. By enforcing the rule where the data is stored, a device only ever receives what it may see.
The consequence is that the policy lives in your backend configuration, not in the extension. Setting it up requires working knowledge of the PostgreSQL or Supabase policy system, or of the managed service's settings, and the quickstart guides for those live in the docs folder. A mistake there exposes rows to devices that should not hold them, and once a row has synced to a device, you cannot unsync it by changing a rule later.
Six platforms are covered, but the install snippets are not all current
The multi-platform claim covers Linux, macOS, Windows, iOS, Android and WASM, and the install table gives a route for each. On Swift you add the repository as a Swift Package dependency, follow two steps from the extensions guide, and load the extension with `CloudSync.path`. Android uses `implementation 'ai.sqlite:sync:1.0.0'` from Maven Central. Flutter uses `flutter pub add sqlite_sync`. Expo uses `npm install @sqliteai/sqlite-sync-expo` and React Native uses `npm install @sqliteai/sqlite-sync-react-native`. For WASM it is `npm install @sqliteai/sqlite-wasm`.
Look at the Android line. It pins version 1.0.0, while the repository's recent releases are 1.1.3, 1.1.4 and 1.2.0. The README does not say whether the Maven artifact tracks the same numbering, so check Maven Central for the current Android version instead of copying the example.
The network layer also differs by platform. It is an embedded layer using libcurl or a native implementation, and the Makefile sets Mac Catalyst to the Apple native NSURLSession path. A build for another platform uses libcurl, with the Makefile downloading and building curl 8.12.1 and OpenSSL 3.6.0 by default.
Agents and offline apps are the two named workloads
Two audiences are addressed. For offline-first apps on mobile, desktop, IoT and edge, devices work against a local SQLite database and sync when connectivity returns, with changes queued locally and merged on reconnect. Example apps in the repository include a simple to-do database, a sport tracker app, a Swift multiplatform app and a to-do app.
For AI agents, the pitch is shared state. Agents that keep memory, notes or shared state in SQLite can sync across instances without coordination. Listed uses include agent memory shared between instances, markdown knowledge bases edited by several agents in different sections, and distributed pipelines where agents on different nodes accumulate results locally and merge them into one dataset.
Treat the agent use case with care. Merging memory is only safe when agents write to different rows or different lines. Two agents rewriting the same note will end up with one winner under last-writer-wins, and the other agent will not be told. The README presents the capability but gives no measured results on correctness at scale, so test with your own concurrency pattern. The repository also has PERFORMANCE.md and API.md for details beyond the front page.
Version 1.2.0 landed in September 2026, and the project sits inside a wider family of extensions
The release list shows 1.2.0 on 2026-09-28, 1.1.4 on 2026-09-21 and 1.1.3 on 2026-09-11, with the last push on 2026-11-02. That is three releases in about seventeen days, which means the extension is changing quickly. Pin the release you test and read the CHANGELOG before upgrading, particularly if the database files sync across devices running different versions.
The code is C under the Apache-2.0 license, and the repository includes Swift package metadata, a Makefile, Docker and deploy folders, a devcontainer and a test directory. The README header links sibling extensions from the same organisation, grouped as data (Vector, Sync, Columnar, JS) and AI (AI, Agent, Memory, MCP).
One more caveat: the README badge shows a coverage figure, but the page text carries no benchmark or scale numbers for sync throughput. If you plan to sync large databases or many devices, run your own test with realistic volume. And if a platform you need is missing from the install table, the Makefile's build targets for Linux, macOS, Windows, Android and iOS are the place to start.
Editorial conclusion
SQLite Sync is a reasonable choice for mobile, desktop or agent apps that already keep state in SQLite and are willing to pair it with SQLite Cloud, PostgreSQL or Supabase as the hub. It is not a peer-to-peer or serverless solution despite the marketing, its Android snippet pins an old version, and merge semantics such as last-writer-wins at the line level mean concurrent edits to the same line still resolve to one winner.
Frequently asked questions
What is SQLite Sync?
SQLite Sync is a multi-platform C extension that turns a SQLite database into a CRDT-based, offline-first replica that syncs with SQLite Cloud, PostgreSQL and Supabase.
Does SQLite Sync need a server?
Yes. It syncs with SQLite Cloud nodes, PostgreSQL servers or Supabase instances, so you need one of them as the sync target even though you write no sync protocol yourself.
How do I enable sync on a table with SQLite Sync?
Load the extension with .load ./cloudsync, create your table, then run SELECT cloudsync_init('tasks'); with your table name. Use cloudsync_uuid() to generate row identifiers.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/sqliteai-sqlite-sync)Star history chart for your README
[](https://hysenlabs.com/projects/sqliteai-sqlite-sync)Was this useful?