toolhive: two authorization engines, five JWT libraries, and a sales funnel
ToolHive is an enterprise-grade platform for running and managing Model Context Protocol (MCP) servers.
At a glance
- What is it?
- An enterprise platform for running Model Context Protocol servers in containers, written in Go and split across four components, two of which live in other repositories. The architecture section is clean. The dependency list is where the interesting decisions are visible.
- Who is it for?
- The container-per-server model and the policy layer are the parts worth understanding before anything else, because they define what the platform actually controls. Two things to weigh.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
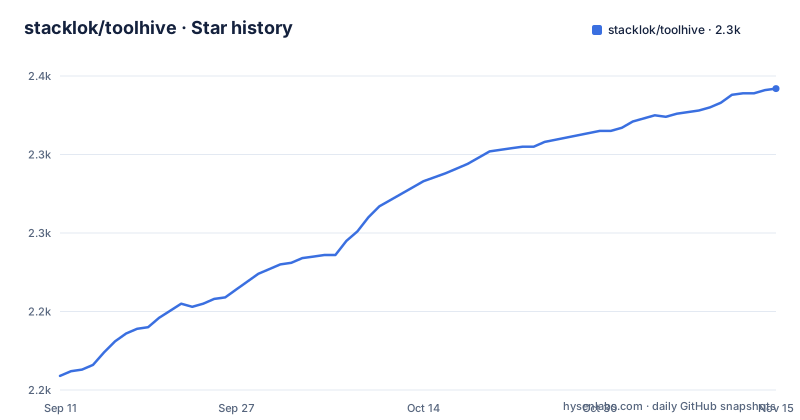
- stacklok/toolhive2,342 ★ · +183
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| stacklok/toolhive | 2.2k | 2.3k |
183 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Four named components, and two of them are other repositories
The architecture section names four parts: a gateway, a registry server, a runtime, and an interface layer.
Two of them are not in this repository. The registry server is linked to a separate repository under the same organisation, and the desktop interface is likewise a separate project. So the repository under discussion is the gateway and the runtime, plus the command-line tool that drives them.
That split is not unusual for a platform that wants a desktop application on a separate release cadence from a cluster operator. It does mean the README's component diagram describes an assembly rather than a single codebase, and a reader who counts the repositories behind the four boxes finds two.
The roles are drawn clearly enough. Admins curate servers in the registry and set policies. Users discover and run servers through the interface or the command line, and the platform orchestrates deployment. The runtime deploys and manages servers locally or in a cluster. The gateway handles all inbound traffic, secures context and credentials, optimises tool selection, and applies organisational policy.
The ordering in that description puts the gateway last and it is the security boundary, since everything a client can reach arrives through it. The interface components never see credentials directly.
Two authorization engines are linked into the same binary
The dependency list contains two general-purpose policy engines, and they come from different authors.
One is a Common Expression Language implementation, which is Google's language for expressing constraints and is widely embedded in systems that need a small evaluable expression. The other is an implementation of Cedar, the policy language AWS published and now maintains openly. Both are first-class direct dependencies rather than things behind an interface.
The example directory corroborates that this is deliberate rather than accidental. There are three authorisation configuration examples, one as a general configuration file, one adding entity definitions, and one specific to a particular API version. Three files for one subsystem is a sign of a feature with surface area, not of a leftover.
Having two engines available is a defensible choice and an expensive one. It means an operator can write policy in whichever language their organisation already has tooling for, which is a real advantage when the alternative is translating an existing Cedar or expression-based policy into something else. It also means the gateway embeds two evaluators, so the question of which one is authoritative for a given policy has to be answered somewhere outside the dependency file.
Five token libraries and two major versions of the same one
The same problem, larger, appears in the token-handling dependencies. There are five separate libraries in the direct requires that all do JWT or JOSE work.
There is the de facto JWT signing library. There are two major versions of a JOSE implementation present simultaneously, one at a version 3 line and one at a version 4 line, which is the shape a codebase takes when one module has not finished migrating off the old major. There is a key-fetching library for pulling keys from a remote set. And there is a second JOSE implementation with its own companion for caching, under a different author's namespace.
So the platform that advertises single sign-on integration and centralised credential handling has five overlapping token stacks linked in. Some of that is normal, because a library that verifies tokens and a library that fetches keys are different jobs and frequently different authors. But two live majors of one implementation in the same require block is a migration that stalled, and it is visible in the dependency list rather than buried.
The practical effect is that the gateway's token handling is not one auditable code path. A security review of the authentication story has to account for all five, and a vulnerability advisory against any one of them lands on the same binary.
Test doubles and a BDD framework sit in the production require block
Several entries in the direct dependency list exist only so that tests can run, and they are in the block that ships.
There is an in-memory Redis implementation, which substitutes for a real server during tests. There is a mock identity provider built as a stand-in for an OAuth proxy, pinned to a pseudo-version derived from a commit rather than a release. And the full behaviour-driven testing framework and its matching assertion library are both direct dependencies.
None of these is harmful to include, and having them declared rather than pulled in ad hoc is arguably better organisation than the alternative. The cost is that a production build of this project links an in-memory server and a mock identity provider, and a dependency scanner will report vulnerabilities in test doubles that can never run in production.
The pseudo-version on the mock provider is the more interesting detail. It means the version of that component is a specific commit on a branch, not a tagged release, so it can move under a later resolution and there is no version to point at when auditing what was built.
This is the usual state of a large Go project that grew quickly and centralised its dependencies late. It is worth knowing about before reading a scanner report as a list of real risks.
An 85% token reduction claim with a mechanism named and no measurement attached
The developer-facing column of the README makes the most quantitative claim in the document: semantic tool search reduces token usage by up to eighty-five per cent.
The mechanism is named twice. The gateway is described as customising and filtering tools and their descriptions to improve performance and reduce token usage, and the deployment section lists an optimiser as a named tool for improving token usage and tool execution.
So the claim is at least mechanistically grounded rather than magic, which puts it above most percentage claims in a README. What is absent is any measurement: no model, no server count, no tool-count threshold, no baseline definition. An eighty-five per cent reduction only means something once you know how many tools were offered and what the comparison is against, and a gateway that filters a list of two tools cannot reduce anything by eighty-five per cent.
The hedged phrase is doing real work. Whether the number is achievable depends entirely on how large the catalogue is, which is exactly the variable the claim omits, and a deployment with fifty tools would plausibly hit figures a deployment with ten would not.
Version 0.51 with weekly patch tags and an enterprise-grade label
The version scheme is worth reading before the marketing.
The project is at a version in the zero-five series, which is a pre-release number by any conventional reading, and the visible tags are three consecutive patch releases on three consecutive days near the end of September. The most recent commit to the default branch is dated the day this article was written.
So the cadence is close to weekly patch releases on a branch that has not reached a first major version, roughly two years into what the description calls an enterprise-grade platform.
Those two facts are not contradictory, but they describe different relationships with the consumer. A patch-level bump implies the maintainers do not expect breakage between versions. A zero-series version implies the interface may still move. A large dependency surface with five token libraries and two policy engines makes the second implication the one to plan around, and the version number is the signal that the project itself is signalling it.
The release practice is otherwise careful. There is a release automation configuration at the root, a version file, a commit-signature requirement document, a maintainers file, a security policy, and a codespell dictionary.
Four agent instruction files, a skills directory, and a README that sells
The root of the repository carries more contributor infrastructure than most projects of this size.
There are two agent instruction files in the open, a hidden directory with a matching name, a coding-assistant instructions file, and a skills directory. Four places telling an automated agent how to work in this repository, none of them referenced from the README.
Alongside those: a maintainers file, a contributor code of conduct, a contributor guide, a commit-signature requirement, a security policy, a linting configuration, a pre-commit configuration, a task runner file, a dependency-update configuration, two coverage configurations, a spelling dictionary, and a supply-chain attestation configuration. There is also a single top-level file named as a project document, with no extension and no explanation of what it contains.
The supply-chain attestation configuration is the one that matters most for this particular project. The registry is described as verifying provenance and signing servers with built-in controls, and the signature library is a direct dependency. So the repository carries the tooling to attest what it distributes, which is the same commitment the registry makes to the servers it catalogues.
Against all of that, the README's structure is a sales table. Three columns addressed to developers, platform engineers, and enterprises, each ending in a call to action, with links to a download page, to documentation, and to a page comparing the open-source project with the vendor's commercial product.
Editorial conclusion
The container-per-server model and the policy layer are the parts worth understanding before anything else, because they define what the platform actually controls. Two things to weigh. The dependency list shows a project that has accumulated rather than converged: two authorization engines and several overlapping token libraries means a large surface where a vulnerability in any one of them is a vulnerability in the gateway, so check what your identity provider actually needs and whether you are paying for both policy engines to get it. And the README is partly a route to a commercial product, so read the open-source documentation rather than the pitch table when you are deciding whether the features listed are in the version you can install.
Frequently asked questions
What is stacklok/toolhive?
An Apache-2.0 licensed Go platform for running and managing Model Context Protocol servers. Each server runs in an isolated container with a minimal permission file, and the platform adds a gateway for access policy and identity, a registry for curating trusted servers, and a runtime that deploys locally or in a cluster.
Which parts of toolhive are in this repository?
Two of the four named components. The gateway and the runtime, with the command-line tool that drives them, are here. The registry server and the desktop interface are separate repositories under the same organisation.
Does toolhive support single sign-on?
The gateway is described as integrating with an identity provider for single sign-on over OIDC or OAuth, and as centralising security policy, authentication, authorization, and auditing. The dependency list carries a dedicated OIDC client library and several token-verification libraries.
How does toolhive run MCP servers?
The runtime deploys servers in a Kubernetes cluster for enterprise scale or locally through Docker or Podman, and proxies remote servers for unified management. There is also a Kubernetes operator for fleet management, plus OpenTelemetry and Prometheus integrations for monitoring and audit logging.
How much token usage does toolhive claim to save?
Up to eighty-five per cent, attributed to semantic tool search that customises and filters tools and their descriptions. The README attaches no measurement to the figure, giving no model, tool count, or baseline, and there is a separate named optimiser tool for the same purpose.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/stacklok-toolhive)Star history chart for your README
[](https://hysenlabs.com/projects/stacklok-toolhive)Was this useful?