stamparm ipsum is a sorted blacklist feed with no generator in the repository
Daily feed of bad IPs (with blacklist hit scores)
At a glance
- What is it?
- IPsum publishes one tab separated file of IP addresses, each with a count of how many public blacklists list it, refreshed every 24 hours. The repository ships the output and nothing that produces it, and the one-line filter the README recommends drops the highest scoring entries.
- Who is it for?
- Take the feed from levels/3.txt rather than re-running the README's grep filter, because that filter is written for single digit counts and discards entries whose count ends in 1 or 2, which on a descending sorted file means it drops some of the best addresses as well as the worst. Treat the whole thing as a blocklist for inbound traffic only, not as a verdict on a client IP, since an address landing on eight lists can still be a shared scanner host.
- Can I use it commercially?
- Yes. Unlicense is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- GitHub does not report a main language for this repository.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
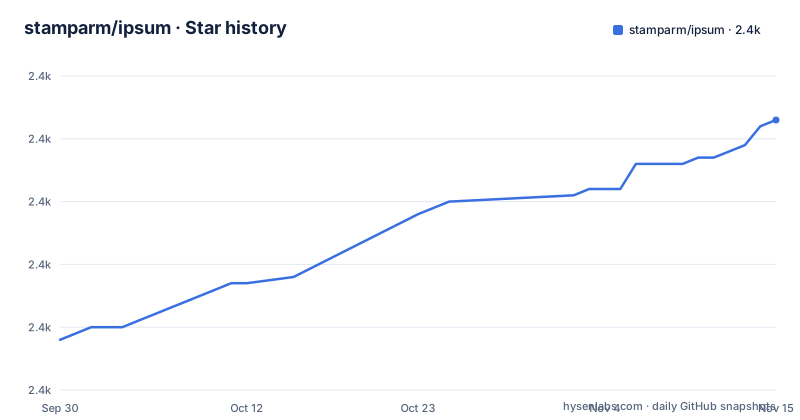
Star history
- stamparm/ipsum2,413 ★ · +35
| Repository | 2026-09-30 | 2026-11-15 |
|---|---|---|
| stamparm/ipsum | 2.4k | 2.4k |
35 Stars in the last 46 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The repository holds the output and nothing that makes it
Four entries sit at the root of the repository: a LICENSE file, the README, `ipsum.txt` and a `levels/` directory. There is no script, no workflow file and no source code of any kind, which is also why no primary language is recorded for the project. The pipeline that retrieves 30 or more public lists, parses them and merges the results runs somewhere else, and the result of that pipeline is what gets committed.
That split matters for anyone planning to depend on the feed. You can consume the file, but you cannot audit how an address came to be in it, and you cannot regenerate it if the daily job stops. The README does link to the author's other project, maltrail, as the home of the list ecosystem, and the project has a page of its own at `https://www.sekuripy.hr/labs/ipsum/`. The license is the Unlicense, the most permissive of the usual choices, and the repository publishes no GitHub releases at all.
One file, one count per address, sorted from confident to doubtful
The format is deliberately dull. Each line of `ipsum.txt` holds an IP address and an occurrence count, the number of source lists that address appears on, and the file is sorted by that count from highest to lowest. The reasoning the project gives is that higher counts mean higher confidence and fewer false positives when you block inbound traffic.
Every 24 hours the source lists are retrieved and parsed and the merged result is pushed back to the repository, so the file you fetch is at most a day behind the lists it summarises. The last push was on 2026-10-02, two days before the Wall of Shame table dated 2026-10-03 that sits at the end of the README.
The scoring is a popularity count, not a severity rating. An address on one list is a weak signal, an address on eight is a strong one, and nothing in the file records which lists agreed or what they claimed. If you need that distinction, the merged count is the only information the feed gives you.
The documented one-liner filters out the best entries
The README offers a single command for people who want a ready-to-deploy list of addresses appearing on at least three blacklists.
curl -fsSL https://raw.githubusercontent.com/stamparm/ipsum/master/ipsum.txt 2>/dev/null | grep -v "^#" | grep -Ev '[[:space:]]([12])$' | cut -f 1The intent is clear enough: skip comment lines, drop anything whose count is 1 or 2, keep the address field. The filter is the problem. It matches whitespace followed by a 1 or a 2 at the end of a line, with no anchor on the digit, so it discards a count of 12 just as readily as a count of 2. On a file sorted from highest to lowest, that means the first entries, the ones with the strongest agreement behind them, are thrown away before the count even reaches the threshold you asked for. Two-digit and three-digit counts ending in 1 or 2 go the same way. `cut -f 1` also assumes the separator really is a tab, which the file listing implies and nothing states outright.
The ipset recipe differs from the curl recipe in two small ways
The second block in the README installs the same feed into an ipset and hangs an iptables rule off it.
sudo -i
apt-get update && apt-get install -y iptables ipset
ipset -q flush ipsum
ipset -q create ipsum hash:ip
for ip in $(curl https://raw.githubusercontent.com/stamparm/ipsum/master/ipsum.txt 2>/dev/null | grep -v "#" | grep -Ev '[[:space:]]([12])$' | cut -f 1); do ipset add ipsum $ip; done
iptables -D INPUT -m set --match-set ipsum src -j DROP 2>/dev/null
iptables -I INPUT -m set --match-set ipsum src -j DROP
It asks for root, and it wants `iptables` and `ipset` from the package manager. The comment filter here is `grep -v "#"` rather than `grep -v "^#"`, so a line carrying a hash anywhere is dropped rather than only a line that starts with one. The rest is the same filter as the curl recipe, with the same weakness against counts ending in 1 or 2.
The rule handling is the tidiest part: the DELETE runs first with errors silenced, then the INSERT puts the rule back at the top of the chain, so re-running the recipe replaces the drop rule instead of stacking a second copy. The set is created as a hash of addresses and flushed before it is rebuilt, which means the block list is empty for the moment the loop takes.
levels/ already contains the slices the one-liner tries to build
The `levels/` directory holds preprocessed raw lists grouped by occurrence count, and `levels/3.txt` is the one to know: it contains the addresses that appear on 3 or more blacklists. The same slicing logic exists for the other thresholds, and the files are plain IP lists rather than the scored format used by `ipsum.txt`.
That makes the directory the better starting point for a firewall rule, and it sidesteps the filter problem in the README's command without reimplementing anything. Fetch the file, feed it to `ipset add`, and the threshold you want is a filename rather than a regular expression.
The gap is that the README does not say how often `levels/` is regenerated relative to `ipsum.txt`, whether every threshold file is written on every run, or what the full set of filenames is. A daily push to the repository tells you the pipeline ran, not which artifacts it produced that day.
The Wall of Shame is a scanner directory, dated one day before the last push
The README ends with a table headed Wall of Shame, dated 2026-10-03, with columns for the IP address, its DNS lookup and the number of lists it appears on. The rows run well past the end of the file.
Read down the DNS column and a pattern appears: `censys-scanner.com` appears against many addresses in the 66.132 and 167.94 ranges, `census.shodan.io` names hosts like hat, soda, sky and dojo, and `scanner.modat.io` shows up as a numbered series from o001 upward inside 85.217.149.0/24. Also present are `internet-census.org` nodes and a `scan.f6.security` host. Plenty of rows show a dash instead of a name, which is simply an address with no reverse record.
So the highest-scoring entries are mostly internet-wide scanning infrastructure rather than one attacker. Blocking them removes noise, which is worth having, and it also explains why a count of eight is not the same as a confirmed malicious host: a scanning range gets listed by many sources at once.
Editorial conclusion
Take the feed from levels/3.txt rather than re-running the README's grep filter, because that filter is written for single digit counts and discards entries whose count ends in 1 or 2, which on a descending sorted file means it drops some of the best addresses as well as the worst. Treat the whole thing as a blocklist for inbound traffic only, not as a verdict on a client IP, since an address landing on eight lists can still be a shared scanner host. And remember that nothing in the repository shows how the file is produced, so if the daily refresh ever stops, the last push date is the only signal you get.
Frequently asked questions
What is the stamparm ipsum feed?
A daily threat intelligence feed of IP addresses that appear on 30 or more publicly available lists of suspicious or malicious addresses, one of which is IPnoise. Each line of ipsum.txt holds an address and the number of source lists it appears on, sorted from the highest count down.
How do I get only the IPs that appear on at least 3 blacklists?
The levels directory already holds those slices, and levels/3.txt contains addresses found on 3 or more lists. The README also gives a curl command with a grep filter, though that filter drops any count ending in 1 or 2 rather than only the counts below 3.
How often is the ipsum feed refreshed?
The source lists are retrieved and parsed every 24 hours and the merged result is pushed to the repository. The last push was on 2026-10-02, and the repository publishes no GitHub releases.
How many IP addresses are in the ipsum feed?
The README states no total. It names 30 or more source lists, gives a count per address, and offers the levels/ slices by threshold, but no figure for the size of the file or of any slice.
Is stamparm ipsum related to the placeholder text used in design tools?
No. The repository is a feed of IP addresses for firewall blocking, published by stamparm under the Unlicense, and it contains ipsum.txt plus the levels/ directory. Nothing in it concerns filler text for layouts.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/stamparm-ipsum)Star history chart for your README
[](https://hysenlabs.com/projects/stamparm-ipsum)Was this useful?