Stanford CoreNLP: one pipeline for parsing and coreference, and three separate jars you have to assemble by hand
CoreNLP: A Java suite of core NLP tools for tokenization, sentence segmentation, NER, parsing, coreference, sentiment analysis, etc.
At a glance
- What is it?
- CoreNLP is a Java suite that takes raw text and returns base forms, parts of speech, named entities, normalized dates, phrase and dependency parses and coreference links from one integrated pipeline. The ergonomics end where the classpath begins: models live outside the main jar, the Ant and Maven paths name different English model files, and the GPL rules out shipping it inside proprietary software.
- Who is it for?
- Stanford CoreNLP suits teams that want one integrated pipeline over text and want the constituent parse, the dependency structure and the coreference links in the same output rather than stitching three libraries together.
- Can I use it commercially?
- Yes, with conditions. GPL-3.0 is a copyleft licence: if you distribute software that includes it, you must release that software's source code under the same licence. Running it internally without distributing it does not trigger that obligation.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 12, 2026, and from our analysis. They are not legal advice.
Star history
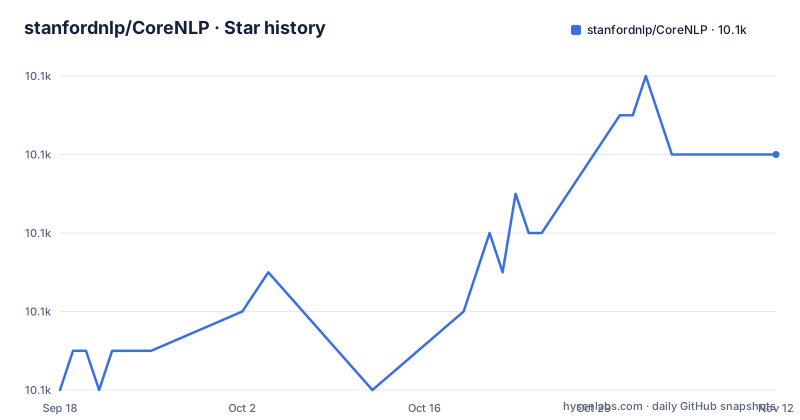
- stanfordnlp/CoreNLP10,126 ★ · +6
| Repository | 2026-09-18 | 2026-11-12 |
|---|---|---|
| stanfordnlp/CoreNLP | 10.1k | 10.1k |
6 Stars in the last 55 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two lines of code return parses, entities and coreference together
CoreNLP is one integrated Java framework rather than a bag of separate analyzers, and the pitch is that you can run all the tools from plain text with two lines of code. The output is wide. You get the base forms of words, their parts of speech, and whether names are companies or people, so entity recognition is part of the same output. Dates, times and numeric quantities come back normalized and interpreted. Sentence structure is marked up as syntactic phrases or as dependencies depending on which annotators you enable, and the pipeline states which noun phrases refer to the same entities. Underneath, the components deliberately mix three techniques rather than betting on one: rule-based logic, probabilistic machine learning, and deep learning models. The stated user base spans academia, industry and government.
Nine languages, each with a varying level of support and its own models jar
The suite was built for English and then widened, but the widening is explicitly uneven. Support is claimed for Modern Standard Arabic, mainland Chinese, French, German, Hungarian, Italian and Spanish on top of English, described as varying levels of support rather than parity. That hedge matters more than it sounds, because resources for any language other than English require the corresponding models jar, so switching language is a download decision rather than a configuration flag. The model table currently lists Arabic, Chinese, English extra, English KBP and French entries all stamped 4.6.0, which lines up with the current release. There is no single artifact that covers every language.
The shift-reduce parser and WikiDict are missing from the default models jar
Here is the trap that catches people on their first real pipeline. The default models jar is not complete, and the documentation says so plainly: some of the larger English models, including the shift-reduce parser and WikiDict, are not distributed with the default models jar at all. Those require the English extra and English KBP jars to be downloaded and placed on the classpath. So the annotators you reach for first when you want a proper constituent parse are the ones gated behind two extra downloads. The consequence for a working pipeline is that adding a shift-reduce annotator to your properties is not a code change, it is a classpath change, and until those two jars are present the pipeline you configured is not runnable with the default download alone.
The Ant and Maven instructions name different English model jars
Two build paths are documented and they do not agree on filenames. The Ant path tells you to download the latest versions of the corenlp models, the english models, and the english models kbp jars. The Maven path, two paragraphs later, tells you to download the corenlp models, the english extra models, and the english kbp models. The model table underneath names the same two English artifacts as English extra and English KBP, matching Maven rather than Ant. Worth noting which of the two instruction sets you copy from before you conclude the download itself failed.
The Ant build is three hand-run commands and a manually assembled classpath
The Ant route is deliberately manual and has no dependency resolution. With Ant installed, compilation is one command:
cd CoreNLP ; antProducing a jar from the result is a second:
cd CoreNLP/classes ; jar -cf ../stanford-corenlp.jar eduThat writes stanford-corenlp.jar into the CoreNLP folder containing the latest code. Everything else is on you: the dependencies that work with the latest code live in CoreNLP/lib and CoreNLP/liblocal, and both must be on your CLASSPATH, as must the models jars you chose. There is no manifest with a classpath, no transitive model download, and nothing that checks you got it right. The payoff is that HEAD is reachable at all between releases, since a new version is only distributed several times a year and corresponds to a stable commit, and HEAD is what the build instructions are for.
Maven runs the tests and names the jar, but models stay outside the dependency graph
The Maven path is shorter for the code itself. In the CoreNLP directory:
mvn packageThat runs the tests and builds CoreNLP/target/stanford-corenlp-4.6.0.jar, so the version in the filename is pinned by the build rather than by whatever you downloaded. The models are a different story, because they are not transitive dependencies and must be installed into your local Maven repository by hand before your project can resolve them. For a language other than English the sample command for Spanish shows the shape, with a classifier that differs per artifact, and the default models jar needs its own classifier set:
mvn install:install-file -Dfile=/location/of/stanford-spanish-corenlp-models-current.jar -DgroupId=edu.stanford.nlp -DartifactId=stanford-corenlp -Dversion=4.6.0 -Dclassifier=models-spanish -Dpackaging=jarEvery additional language means another command with the language name changed and the classifier matched..
Between releases you are running unreleased code, and the release gap is wide
The versioning story is the one to read before pinning anything. Releases are described as happening several times a year, each corresponding to a stable commit, with the under development version available from HEAD in between. The actual dates are less frequent than that phrasing suggests: v4.5.9 shipped 2025-04-07, v4.5.10 on 2025-06-07, and v4.6.0 only on 2026-09-25, a gap of about fifteen months between the last two, with the repository last pushed on 2026-11-02. So choosing HEAD buys you unreleased code over a long stretch, and choosing a tag means v4.6.0 carries the security fixes, enhanced graph Semgrex queries, SemgrexStats, SUTime bug fixes and dependency upgrades named in its own release note. The tree also offers several entry points at once, with build.xml, build.gradle, pom.xml, pom-java-17.xml and commonbuildjsp.xml side by side, which means picking a build is the first decision rather than an implementation detail.
Editorial conclusion
Stanford CoreNLP suits teams that want one integrated pipeline over text and want the constituent parse, the dependency structure and the coreference links in the same output rather than stitching three libraries together. Before committing, settle the three questions the documentation leaves to you: which English model jars you actually need, since the shift-reduce parser and WikiDict sit outside the default download; whether GPL v2 or later fits your distribution model, because the build notes rule out using it in proprietary software you distribute to others; and whether you want a tagged release or HEAD, since the gap between v4.5.10 in June 2025 and v4.6.0 in September 2026 is much wider than the advertised several times a year.
Frequently asked questions
what is stanford corenlp
A Java suite of natural language analysis tools, GPL licensed, that takes raw text and returns base forms of words, parts of speech, named entities such as companies and people, normalized dates and quantities, syntactic phrase and dependency parses, and coreference between noun phrases. It covers English plus varying levels of support for Arabic, Chinese, French, German, Hungarian, Italian and Spanish.
Can Stanford CoreNLP be used inside a proprietary product?
Not if you distribute it to others. The build notes state that this is the full GPL, which allows many free uses but not its use in proprietary software that you distribute to others. That restriction is the deciding factor for closed source distribution.
Which Stanford CoreNLP models jar holds the shift-reduce parser?
Not the default one. The shift-reduce parser and WikiDict are among the larger English models that are not distributed with the default models jar, and they require the English extra and English KBP jars instead, both of which have to be on the classpath.
How do I build Stanford CoreNLP from source with Maven?
Run mvn package in the CoreNLP directory. It runs the tests and builds CoreNLP/target/stanford-corenlp-4.6.0.jar. You then download the corenlp models, English extra and English KBP jars and put them on the CLASSPATH yourself, since they are not resolved as dependencies.
How do I fetch the Stanford CoreNLP models for another language?
The recommended route is git-lfs from the Hugging Face Hub. Install git-lfs, then clone the repository for your language, for example git clone https://huggingface.co/stanfordnlp/corenlp-french. The jars can also be downloaded directly from the links in the models table.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/stanfordnlp-corenlp)Star history chart for your README
[](https://hysenlabs.com/projects/stanfordnlp-corenlp)Was this useful?