OpenMonoAgent: a 12-step pipeline with ten steps written down
(BETA) AI shouldn't have a meter. Unlimited tokens. Forever. Your machine. Your agent. Use it from anywhere. Terminal-native coding agent powered by local LLMs — 100% open source, free forever, and installed with a single command. Proudly built on C#/.NET, because AI tooling should be infrastructure, not a subscription.
At a glance
- What is it?
- StartupHakk/OpenMonoAgent.ai is a .NET coding agent that bundles llama.cpp in Docker, sandboxes the project to one mount, and advertises zero cloud. The feature cards and the summary line disagree with each other in two places worth knowing before you install it.
- Who is it for?
- OpenMonoAgent is interesting as an architecture reference even if you never install it, because it states its limits in public: one mount is the whole blast radius, sub-agents get locked tool sets and hard turn budgets, and every tool call passes a fixed pipeline. Three things to weigh first.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 9 days ago.
- What is it written in?
- Mainly C#, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
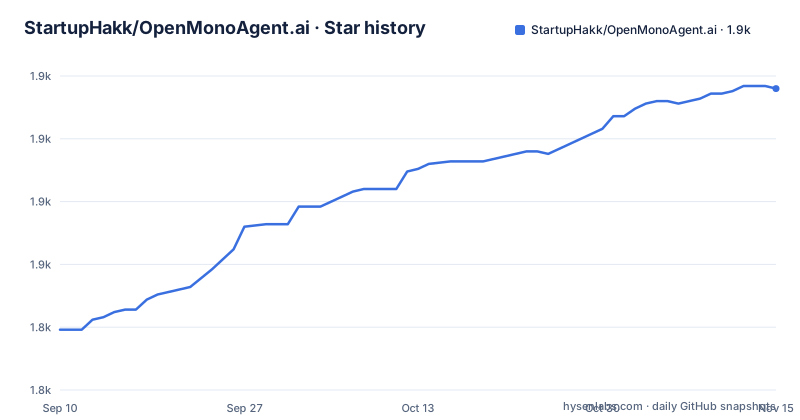
Star history
- StartupHakk/OpenMonoAgent.ai1,920 ★ · +96
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| StartupHakk/OpenMonoAgent.ai | 1.8k | 1.9k |
96 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The install pipes a script from main into a shell
The quickstart is one line:
bash <(curl -fsSL https://raw.githubusercontent.com/StartupHakk/OpenMonoAgent.ai/refs/heads/main/get-openmono.sh)The URL points at a branch reference rather than at a tag or a release, so the script that executes is whatever the default branch holds at that moment, with no version pin and no checksum in the command. The text says the installer detects the hardware and installs the model, the runtime and the Docker containers. The repository also carries a PowerShell installer alongside the shell one, though the quickstart only shows the shell path. Afterwards the agent runs from any project, in a full-screen interface by default or in a scrolling one on request:
openmono agent            # TUI mode (default)
openmono agent --classic  # classic scrolling terminal
A separate setup document is pointed at for the full command reference, including daily commands, setup flags and the processor options.
GPU throughput is quoted twice at two different rates
The summary line says the agent runs at about 45 tokens per second on a GPU and about 20 on a CPU. The bundled inference card says something else for the same hardware: a dense 27B model on a GPU at about 60 tokens per second, a mixture-of-experts 35B with 3B active on a CPU at about 20, and the same mixture-of-experts model on a Mac through Metal at about 45 to 48. The Mac figure and the summary line agree; the GPU figures do not. The two model labels are given as Qwen3.8-27B for the GPU and Qwen3.6-35B-A3B for the CPU and Mac, and a badge in the header links to a models document with a section explaining why those pairings. Neither rate carries the conditions that would make it comparable: no processor, no quantisation level, no context length, no batch size. A throughput number without those four is a claim about a setup rather than a property of the software.
The pipeline is called twelve steps and ten are written down
The tool card announces a 12-step pipeline and then enumerates it: every call is parsed, schema validated, path checked for sanity, run through a plan-mode guard, capability checked, looked up in a cache, passed through a pre-hook, executed, passed through a post-hook, and stored as an artifact. That is ten named stages against a label of twelve, and the sentence closes by saying nothing bypasses the pipeline and that read-only tools run in parallel. The count is a small thing, but the ordering is the useful part, and two stages in it are the ones that matter for safety. Path sanity and the plan-mode guard run before execution, and the capability check runs after them, so a tool cannot act outside what it was granted. The cache sits after validation and before the hooks, which means a cache hit skips the hook pair.
Sub-agent turn budgets add up to exactly a hundred
Five specialist sub-agents run in isolated sessions with locked tool sets and hard turn budgets. Explore is read-only discovery with fifteen turns. Plan does architecture with no writes and ten. Coder gets full file access and thirty. Verify runs adversarial checks with the C# compiler and gets twenty. A general-purpose agent has everything and gets twenty-five. Those five numbers total a hundred turns, which reads as deliberate budgeting rather than coincidence, and it pairs with the main loop's own ceiling of twenty-five iterations per turn. Two more numbers describe how a long turn is kept finite: a checkpoint at sixty-five percent context fill, compaction at eighty, and doom-loop detection that aborts when the same tool sequence repeats three times. A stuck agent is stopped by pattern, not by a timeout.
One mount is the entire blast radius
The sandbox card is unusually blunt about what the agent can touch. The project directory is mounted as /workspace, and the text says in as many words that the agent reads and writes your real files, that this is the blast radius, and that nothing outside that mount is visible or reachable. So the security model is the mount list, and everything else follows from it. The code intelligence layer is narrower than the sandbox. Deep analysis comes from Roslyn: type hierarchy, blast-radius queries, cross-file symbol search, callers and diagnostics, with a five-minute compilation cache. That depth is C# only. TypeScript, Python, Go and Rust get a language server, lazily started on first use. Two optional extras are auto-detected if they happen to be installed, a semantic concept graph covering 25 or more languages and a structural call graph served over MCP with about 22 tools, and neither needs configuration.
Zero cloud, three cloud providers, and a free relay
The pitch is that after a one-time setup inference costs nothing and no code leaves the machine. The provider card keeps that mostly true and partly not: local llama.cpp is the default and described as fully supported, while OpenAI, Anthropic and Ollama are listed as available but work in progress. Distributed inference then adds a hosted component to a local-first story. You can run the agent on a laptop and inference on a separate GPU machine, with no port forwarding because the tunnel is established outbound from the inference box, and a free relay is offered for that path. Search stays local through a self-hosted SearXNG instance so queries do not leave the machine, while the scraping half of the same card ships a real browser with a Cloudflare bypass for anti-bot targets, behind a single Caddy gateway whose description stops mid-sentence.
Vision is off until an environment variable is set
Multimodal input is gated rather than default. You enable it with a single environment variable, and at setup the multimodal projector is downloaded automatically. Images are attached in chat with a mention of the filename or handed to the agent as a path, four formats are listed as supported, and anything large is resized to fit a VRAM budget. That last point is worth noting on its own: the resize decision is made against a hardware budget rather than a resolution target, so the same image can arrive at the model differently on two machines. The shipping line is broader still. Alongside the command-line entry point, the README advertises an app store listing, a Google Play listing, a Visual Studio Marketplace extension, and a setup search command, while the visible top-level tree holds a solution file, a props file, a global settings file, a version file and directories for docker, docs, scripts, setup and source, with no mobile or extension project among them.
No releases, and a license field that does not match
The repository has no GitHub releases at all, which sits oddly beside a section about what is shipping across four distribution channels. There is a version file at the root instead, along with a global settings file that pins the SDK and a solution file, so versioning lives in the tree rather than in tags, and there is no release to pin. Licensing is the other loose end. The repository's recorded license field is an assertion of nothing, while the top level carries a license file. Both facts can be stated and neither settles the other: the file in the repository is not identified by the metadata, and the metadata names no license for the file. Anyone planning to depend on this should read the file itself rather than the field.
Editorial conclusion
OpenMonoAgent is interesting as an architecture reference even if you never install it, because it states its limits in public: one mount is the whole blast radius, sub-agents get locked tool sets and hard turn budgets, and every tool call passes a fixed pipeline. Three things to weigh first. The installer pipes a script fetched from the default branch straight into a shell, so the thing you run is whatever that branch currently holds. The advertised throughput does not agree with itself, a summary line and a feature card give two different GPU rates, and no hardware or quantisation conditions are attached to either. And the licensing metadata does not match the repository, which ships a license file the metadata does not name.
Frequently asked questions
How do I install OpenMonoAgent?
With one command that pipes a shell script fetched from the default branch into bash, which installs the model, the runtime and the Docker containers while detecting GPU, CPU or Apple Silicon. The repository also carries a PowerShell installer that the quickstart does not show.
What hardware does OpenMonoAgent support?
NVIDIA GPU, CPU or Apple Silicon with Metal, selected automatically at install. The listed rates are about 60 tokens per second on a GPU with a dense 27B model, about 20 on a CPU, and 45 to 48 on a Mac with a mixture-of-experts model, though a summary line elsewhere gives a different GPU rate.
What is the blast radius of the OpenMonoAgent sandbox?
The project directory, mounted as /workspace. The documentation says the agent reads and writes your real files there, calls that the blast radius, and states that nothing outside that mount is visible or reachable.
Which model providers does OpenMonoAgent support?
Four. Local llama.cpp is the default and described as fully supported, while OpenAI, Anthropic and Ollama are listed as available but still work in progress.
How does OpenMonoAgent do distributed inference?
The agent runs on your machine and inference on a separate GPU machine, with the tunnel established outbound from the inference box so no port forwarding is needed. A free relay is offered for that case, and a dual-box guide is referenced in the setup document.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/startuphakk-openmonoagent-ai)Star history chart for your README
[](https://hysenlabs.com/projects/startuphakk-openmonoagent-ai)Was this useful?