steel-browser wraps Chrome in an API and calls the result beta
🔥 Open Source Browser API for AI Agents & Apps. Steel Browser is a batteries-included browser sandbox that lets you automate the web without worrying about infrastructure.
At a glance
- What is it?
- An Apache-2.0 browser sandbox for agents that keeps sessions, cookies and local storage between requests, exposes Puppeteer and CDP to any driver, and converts pages to markdown, readability, screenshots or PDFs. The feature list is generous; every release tag still carries a beta suffix.
- Who is it for?
- steel-browser fits teams that want browser automation they host themselves and drive from an agent, and that need sessions to survive across requests instead of restarting a browser per call. Walk away if you need a stable interface contract, because the releases are all beta and the manifest version trails the newest tag.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
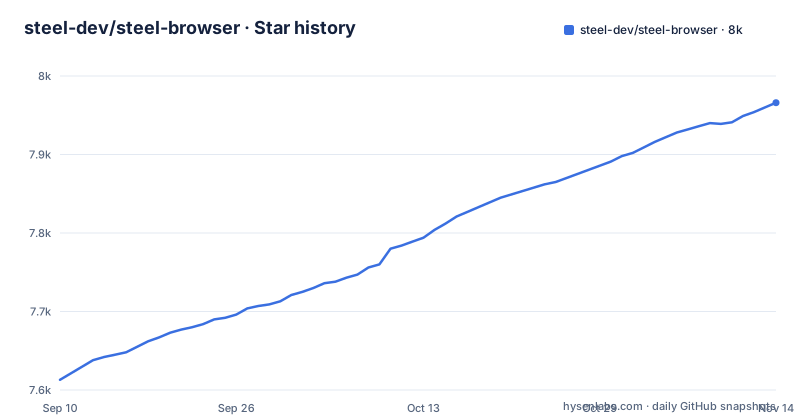
- steel-dev/steel-browser7,966 ★ · +353
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| steel-dev/steel-browser | 7.6k | 8k |
353 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Puppeteer and CDP underneath, so any driver can attach
The control layer is standard rather than proprietary. Steel manages sessions, pages and browser processes, and gives complete control over Chrome instances through Puppeteer and the Chrome DevTools Protocol. Because the surface is CDP, you can connect with Puppeteer, Playwright or Selenium rather than being locked to one client library.
That choice shows in the container as well. The image puts a Selenium driver directory on PATH and installs Chromium, with CHROME_BIN and CHROME_PATH both pointing at /usr/bin/chromium. Node 22 is the floor: the root manifest declares engines.node as >=22 and the Dockerfile defaults its base image to node 22.23.4. Quick actions on top of the raw protocol return markdown, readability extractions, screenshots or PDFs, which is the shortcut most callers use instead of driving CDP by hand.
Port 3000 serves the API, 9223 opens the debugger
The single-image path publishes two ports and a UI under the API port:
# Pull and run the Docker image
docker run -p 3000:3000 -p 9223:9223 ghcr.io/steel-dev/steel-browser
Port 3000 carries the server, the UI lives at the /ui path on that same port, and 9223 is the console debugger, which is what you attach to when a session misbehaves. The compose file splits the same thing into two services with published images: an api service on 3000 and 9223 with volumes for logs and exports, and a ui service published as 5173:80 that points at http://api:3000 by default. Log storage is switched on with a DuckDB path under /data/logs.
docker-compose.dev.yml exists so your edits show up
Contributors are told to run a different compose file than users. docker-compose.dev.yml builds the images from the api and ui directories so local changes are reflected, instead of pulling the published ones, and it runs the server on 3000 with the UI on 5173. The readme also insists on the build flag, because without it the images are reused:
docker compose -f docker-compose.dev.yml up --buildTwo platform details are called out. Mac Silicon hosts need DOCKER_DEFAULT_PLATFORM=linux/arm64 docker compose up to get images built for the right architecture. Anyone running on a custom host is told to copy .env.example to .env and set DOMAIN and CDP_DOMAIN to that host; Docker Compose reads the .env file automatically. The committed .env.example holds DOMAIN, CDP_DOMAIN and API_URL.
Running without Docker means supplying Chrome yourself
If you have Node and Chrome, the workspace starts with npm install and npm run dev, which launches the API and the UI together through concurrently and puts the UI on 5173. The catch is that Chrome has to exist at a path the server recognises, and the readme lists the expected locations for Linux, macOS and both Windows install prefixes.
When your Chrome lives somewhere else, the escape hatch is an environment variable rather than a config file:
export CHROME_EXECUTABLE_PATH=/path/to/your/chrome
npm run dev
The check itself lives in api/src/utils/browser.ts, which is the file to read when detection fails on an unusual layout. Inside Docker none of this applies, because the image already resolves Chromium for you. Note that the root test script only runs the api workspace, so a change in the UI is not covered by npm test.
What the sandbox manages so your agent does not have to
The value is in the bookkeeping around a browser. Session management keeps browser state, cookies and local storage across requests, which is what lets an agent log in once and keep the session. Resource management handles automatic cleanup and the browser lifecycle, so abandoned sessions do not accumulate live Chrome processes.
Around that sit the parts that normally need infrastructure work. Proxy support is built-in proxy chain management for IP rotation. Extension support loads custom Chrome extensions. Anti-detection adds stealth plugins and fingerprint management. Debugging tools provide request logging plus a UI for viewing sessions. Each of these is a feature you would otherwise assemble around a raw Puppeteer script, and each is also a policy decision about how your automation presents itself to the sites it visits.
Two ways in: sessions or quick actions
The API is entered in one of two ways. The first is sessions, for anything that needs state to persist. The second is the quick actions endpoints, for one-shot conversions where a page only has to become markdown, readability content, a screenshot or a PDF. Both are reachable over plain REST, with the OpenAPI reference hosted at docs.steel.dev and served from your own instance at the /documentation path.
If you would rather not write HTTP by hand, there is a steel-sdk package for Node and Python. The readme describes these as built on top of the REST API and fully typed, so they are a convenience layer rather than a second interface. There is also a REPL package in the workspace for poking at a live instance from a terminal, and a separate cookbook repository with worked examples.
Every tag says beta, and the manifest trails the newest one
The release naming is the first thing to notice. The three most recent tags are v0.5.5-beta from 31 October 2026, v0.5.4-beta from 25 August 2026, and v0.5.3-beta from 24 April 2026. The root package.json carries version 0.5.4 with private set to true, which is the workspace root rather than a publishable artefact. The readme states plainly that Steel is in public beta and evolving every day, and points to Discord and GitHub issues for feedback.
The last push is dated 31 October 2026, the same day as the v0.5.5-beta tag. For deployment, treat the compose default of :latest as a moving target and pin a tag or a digest, because a browser sandbox that changes fingerprint or proxy behaviour between restarts is hard to debug. Two smaller signals of an active repository: lint-staged running prettier through a husky hook, and an overrides entry forcing tar-fs to 3.1.1 or newer.
Editorial conclusion
steel-browser fits teams that want browser automation they host themselves and drive from an agent, and that need sessions to survive across requests instead of restarting a browser per call. Walk away if you need a stable interface contract, because the releases are all beta and the manifest version trails the newest tag. Before deploying, pin an image tag rather than latest, decide whether you need the proxy and fingerprint features at all, and check that Node 22 and a Chromium path are available in whatever runtime you build.
Frequently asked questions
How does steel-browser compare with browser use?
Its own claims are a self-hostable browser API that keeps session state, cookies and local storage across requests, manages proxy chains for IP rotation, loads custom Chrome extensions, ships stealth plugins with fingerprint management, and returns markdown, readability, screenshots or PDFs from quick actions.
Is there a steel-browser alternative?
What the readme offers is a choice of hosting: a Steel Cloud account, the pre-built image combining API and UI, one-click Railway or Render deploys, docker compose, or npm install with npm run dev against your own Chrome.
Do I need Chrome installed to run steel-browser?
Not in Docker, where the image installs Chromium and sets CHROME_BIN and CHROME_PATH to /usr/bin/chromium. Running from Node with npm run dev does need a Chrome executable at one of the listed Linux, macOS or Windows paths, or you set the CHROME_EXECUTABLE_PATH environment variable.
What Node version does steel-browser require?
Node 22 or newer. The root package.json sets engines.node to >=22, the Dockerfile builds from a node image defaulting to 22.23.4, and the API build stage also installs build-essential, pkg-config and xvfb.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/steel-dev-steel-browser)Star history chart for your README
[](https://hysenlabs.com/projects/steel-dev-steel-browser)Was this useful?