Machine Learning for Trading: 27 chapters in Docker, pinned to Python 3.14
Code for Machine Learning for Trading, 3rd edition, from data sourcing to live execution.
At a glance
- What is it?
- Stefan Jansen's third edition code is 27 chapter notebooks and nine case studies that you run in Docker, not a library you install. The interesting constraints are the Python 3.14 pin, the scipy ceiling kept for PyPortfolioOpt, and an Apple Silicon gap on six chapters.
- Who is it for?
- Machine Learning for Trading fits a reader who wants the whole path from data sourcing to live execution, has Docker plus about 12 GB of disk on amd64 or 3 GB on arm64, and accepts pinning notebooks to a commit instead of a version number. It does not fit Python 3.13, an Intel Mac that needs GPU services, or an Apple Silicon user who wants Ch05 NB01/03/07, Ch09 NB06/12, Ch10 NB01-03, Ch12 NB10, Ch14 NB06 and Ch15 NB06 without Rosetta emulation.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
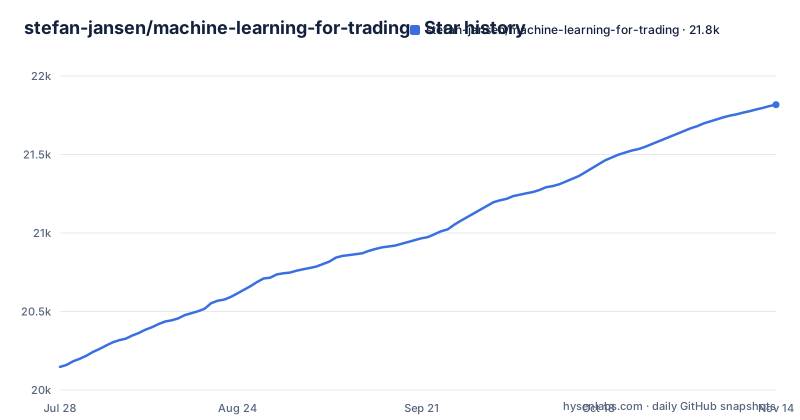
- stefan-jansen/machine-learning-for-trading21,817 ★ · +1,670
| Repository | 2026-07-28 | 2026-11-14 |
|---|---|---|
| stefan-jansen/machine-learning-for-trading | 20.1k | 21.8k |
1,670 Stars in the last 109 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The third edition is on main, the finished second edition is one checkout away
Two editions share this repository and the split is a branch. Main holds the third edition: 27 chapters and nine case studies, described as running one end-to-end path from data sourcing to live execution. The second edition is called complete and stable on the second-edition branch, and one command puts the tree back where that book describes it:
git checkout second-editionWhat you cannot do is pin a version. The release tags are not library releases. v3.0.0-alpha.3 covers Part II, Research Design and Feature Engineering and shipped on 2026-06-29, and the two newer tags, v3.0.0-artifacts on 2026-07-24 and v3.1.0-artifacts on 2026-09-20, are labelled pre-computed case study artifacts. For anyone building on top of this, the consequence is that your dependency is a notebook commit rather than a released package, and the last push to main is dated 2026-10-29.
Apple Silicon readers get an amd64 image for six chapters, or Rosetta
The platform triage lives in comments at the top of docker-compose.yml. Most readers need one image and two commands:
docker compose pull ml4t
docker compose up ml4t
Jupyter Lab then listens on http://localhost:8888. Three images are listed on Docker Hub under docker.io/ml4t/, and compose adds a rapids service: ml4t:latest covers every chapter on Python 3.14 with PyTorch CUDA 12.8 for amd64 and arm64, ml4t-benchmark:latest carries the storage benchmarks for DuckDB, HDF5 and database clients, and a rapids service covers the chapter 12 GBM GPU benchmark. The Python 3.12 image exists for four packages, signatory, esig, gensim and tfcausalimpact, and the chapters that need it are named: Ch05 NB01/03/07, Ch09 NB06/12, Ch10 NB01-03, Ch12 NB10, Ch14 NB06 and Ch15 NB06. That image is amd64 only, so on Apple Silicon the project tells you to read the committed .ipynb outputs or set DOCKER_DEFAULT_PLATFORM=linux/amd64 and run under Rosetta emulation.
Pull 12 GB on amd64 or build for 45 minutes, then Jupyter Lab on 8888
There are two routes into the same notebook server, and the cost difference is large. The compose file names pre-built images as the quick start, where the pull is roughly 12 GB on amd64 and roughly 3 GB on arm64, and calls the local build slow at about 45 minutes:
docker compose build ml4tPlatform support is spelled out the same way. Linux x86_64 runs all services with GPU optional, Windows goes through Docker Desktop on WSL2 with GPU work needing the WSL2 nvidia toolkit, macOS Intel runs everything except GPU services, and Apple Silicon gets native arm64 for ml4t and the benchmark image. Whichever route you take, the data question is handled the same way: the repository is mounted at /app read-write and ML4T_DATA_PATH points every downloader at /data, so the in-container workflow data/download_all.py can populate it. Decide between pull and build before you start the download, not after.
requires-python is >=3.14,<3.15 and scipy stops below 1.18 for chapter 17
The dependency file is where the project is most specific about its own limits:
requires-python = ">=3.14,<3.15"
"scipy>=1.12,<1.18",
A single minor version of Python, so 3.13 will not work. The scipy ceiling carries its reason in a comment: 1.18 removed the private scipy.cluster.hierarchy._LINKAGE_METHODS that PyPortfolioOpt 1.6.0 still references for HRP linkage validation, compared in the chapter 17 library comparison, and the cap should lift once PyPortfolioOpt ships a fix. Other pins are equally deliberate. kaleido is held at 1.3 or newer because the default renderer is plotly_mimetype+png, which turns every fig.show() into a kaleido call rather than only a figure export; utils/__init__ drops the +png half where no Chrome can be resolved, and envs/ml4t/Dockerfile installs Chrome for Testing so the image does resolve one.
Data lands in your checkout, and your UID decides who owns it
The .env.example template is longer than the work it asks of you. Copy it once:
cp .env.example .envThe defaults run the early chapters unedited. Only two entries are free and need no account: EDGAR_IDENTITY, your own name and email for the SEC, and UID and GID, and those only if `id -u` or `id -g` prints something other than 1000. Everything else on the list is an API key. ML4T_PATH is auto-detected and rarely needs setting, and ML4T_DATA_PATH is deliberately left commented out because the default is the repository's own data folder, identical whichever directory you start from. Two consequences are worth knowing in advance. Your datasets end up inside your checkout rather than beside it, and the container runs as ${UID:-1000}:${GID:-1000} for exactly that reason, so if your user id is not 1000 and you skip the edit, files the container writes come back owned by the wrong user.
Nine case studies differ mostly in clock, from monthly to 15 minutes
The case_studies directory is the structural centre of this edition, and all nine run the same pipeline: raw data and labels, features, models, backtests, costs, risk overlays, then a deployment assessment. What changes between them is the asset class and the frequency. US Firm Characteristics is monthly and works on a firm-level panel of size, value, momentum and quality. Crypto Perps is 8-hourly and is funding-rate arbitrage on perpetual futures. NASDAQ-100 is 15-min and reads order flow and the limit order book. ETFs runs cross-asset momentum and mean reversion across 100 ETFs daily, FX pairs covers carry and momentum across major currency pairs, CME futures covers term structure and roll yield, and the two options studies cover implied-volatility enhanced equity selection and options-only strategies such as straddles and delta-hedged positions. The argument for doing it nine ways is that one process applied to very different markets shows where it works and where it breaks. The limit is that what you get is a demonstration of method, not a set of strategies to trade.
The evidence boundary sits between tuning and evaluation
The methodological spine is one drawn line: an evidence boundary that separates tuning from evaluation, with walk-forward cross-validation used throughout instead of a random split. Around it sit the tools most backtests skip, the Deflated Sharpe Ratio, the Rademacher Anti-Serum and White's Reality Check for multiple testing, plus conformal prediction for uncertainty intervals you can defend. Transaction costs and risk management became full chapters in this edition rather than a postscript, joining portfolio construction and strategy synthesis so a raw signal is carried to a sized, cost-aware portfolio. What that machinery cannot do is validate your setup. It presumes the data you feed it and the costs you configure resemble the ones you will face, and the two artifact releases ship pre-computed case study outputs, so a reader who downloads those has checked someone else's numbers instead of running their own pipeline.
Twenty-seven chapters of model breadth, with four packages in a second image
The model list is wide on purpose. Gradient boosting comes as XGBoost, LightGBM and CatBoost, deep time-series work as PatchTST, iTransformer, TSMixer, TCN and Mamba, and newer tabular models as TabPFN, TabM plus conditional and supervised autoencoders. Alongside sit causal estimation with Double ML, Bayesian structural time series and causal discovery, reinforcement learning for optimal execution, market making with inventory and deep hedging, synthetic generators including TimeGAN, Tail-GAN, Sig-CWGAN and diffusion models, and a generative AI track of retrieval-augmented generation over SEC filings with knowledge graphs and Graph RAG. Breadth across 27 chapters has a price: each topic gets a chapter's depth rather than a maintained reference implementation, and four libraries, signatory, esig, gensim and tfcausalimpact, are confined to the amd64-only Python 3.12 image.
Editorial conclusion
Machine Learning for Trading fits a reader who wants the whole path from data sourcing to live execution, has Docker plus about 12 GB of disk on amd64 or 3 GB on arm64, and accepts pinning notebooks to a commit instead of a version number. It does not fit Python 3.13, an Intel Mac that needs GPU services, or an Apple Silicon user who wants Ch05 NB01/03/07, Ch09 NB06/12, Ch10 NB01-03, Ch12 NB10, Ch14 NB06 and Ch15 NB06 without Rosetta emulation. Before you start, read the platform comments in docker-compose.yml to choose ml4t or ml4t-py312, put EDGAR_IDENTITY in .env, and decide whether you will run the notebooks or settle for the pre-computed case study artifacts.
Frequently asked questions
Can machine learning be used for trading?
This repository takes that as its premise and answers it with code: 27 chapters and nine case studies carry ETFs, crypto perpetuals, intraday equities, options, FX, futures and equity panels through the same pipeline, from raw data and labels to a deployment assessment. The tooling it teaches, walk-forward cross-validation, the Deflated Sharpe Ratio and White's Reality Check, is aimed at the overfitting problem rather than at any promised return.
How do I use machine learning for trading with this code?
The path runs through the whole repository: data infrastructure and strategy research, an evidence boundary that separates tuning from evaluation, then deployment and monitoring, with a feedback loop that retrains, pauses or retires a strategy as its edge decays. To see it, pull the image and start the notebook server with docker compose pull ml4t and docker compose up ml4t, which serves Jupyter Lab at http://localhost:8888.
What is machine learning for trading in this repository?
It is machine learning applied to the whole trading lifecycle rather than to one model. The chapters cover data sourcing, feature engineering, models, backtesting, portfolio construction, transaction costs, risk management and live execution through Interactive Brokers, Alpaca and QuantConnect, plus MLOps concerns such as drift detection, safe rollout, circuit breakers, feature stores and experiment tracking.
Which AI and ML models does machine-learning-for-trading cover?
Gradient boosting with XGBoost, LightGBM and CatBoost, deep time-series models including PatchTST, iTransformer, TSMixer, TCN and Mamba, and TabPFN, TabM with conditional and supervised autoencoders. It also covers Double ML and Bayesian structural time series for causal work, reinforcement learning for optimal execution, market making and deep hedging, and synthetic data from TimeGAN, Tail-GAN, Sig-CWGAN and diffusion generators.
Can I use AI to run my trading end to end?
The production track covers live trading systems through Interactive Brokers, Alpaca and QuantConnect, along with MLOps and governance: drift detection, safe rollout, circuit breakers, feature stores and experiment tracking. The workflow it teaches ends in a feedback loop that retrains, pauses or retires a strategy as its edge decays, rather than in a one-off model.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/stefan-jansen-machine-learning-for-trading)Star history chart for your README
[](https://hysenlabs.com/projects/stefan-jansen-machine-learning-for-trading)Was this useful?