linkedin-mcp-server: your session, your machine, one confirmation prompt
Open-source MCP server for LinkedIn. Give Claude and any MCP-compatible AI agent access to profiles, companies, jobs, and messages.
At a glance
- What is it?
- An open-source server that lets an AI assistant act on a professional network by driving the site through a browser you are already signed in to. The design puts the session on your machine, which is both its selling point and the source of most of its sharp edges.
- Who is it for?
- This server fits someone who wants an assistant to read profiles, look up companies, and search jobs without handing credentials to a third party, and who is comfortable debugging a browser automation stack. Two things to check before you wire it into an agent.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
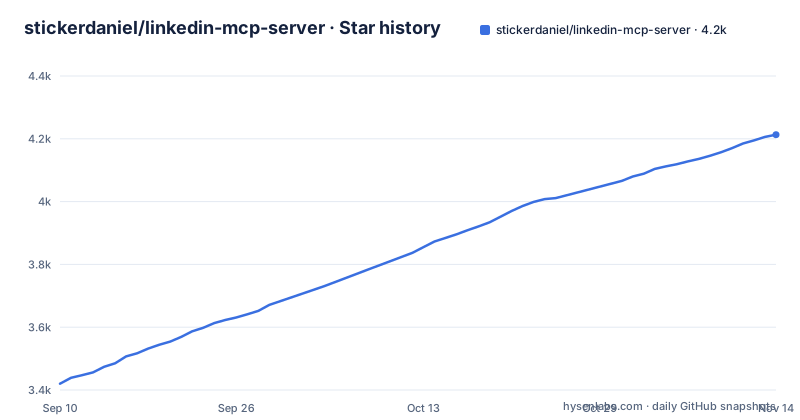
- stickerdaniel/linkedin-mcp-server4,213 ★ · +793
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| stickerdaniel/linkedin-mcp-server | 3.4k | 4.2k |
793 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
It acts through a session you already have
The mechanism is the whole design. Rather than talking to an official interface, the server drives the site's own web interface through a browser on your machine, using a session taken from a browser you are already signed in to, and falling back to opening a login window when it cannot find one. Every action happens locally, and the documentation says so in one line. The legal notice underneath is equally direct: this is an independent project, not affiliated with, authorised by, endorsed by, or sponsored by the platform or its parent company, and the trademark is used only to identify the service being automated. That is the right framing for a tool of this kind, and it is also the framing any organisation adopting it will need to make its own position on.
The section titled Installation Methods lists the tools
The readme has a structural mistake worth mentioning because it is the first thing a reader meets. The heading above the tool table says Installation Methods, and the anchors for the installation subsections sit immediately above it, but what follows is a table of about twenty tools. The table is the better part of the file. It covers reading profile sections, reading your own profile, sending or accepting connection requests, listing a person's sidebar recommendations, reading and searching your inbox, reading a conversation by username or thread, sending a message, company profiles, company posts, company searches, company employees, and a cluster of job tools covering search, saved jobs, details, and how a posting takes applications. Two entries carry warnings. Sending requires confirmation before it acts, and the note on targeting a profile admits that it may start a separate direct message instead of replying in the thread, with an issue link. A final tool closes the session and releases its resources.
Automatic updates are how it survives markup changes
The recommended installation runs the package by its latest tag, and the documentation explains why in a sentence that should be read as a warning as much as a feature: automatic updates keep the server working with the platform's current page structure. In other words, an automation built by scraping a web interface is coupled to that interface, and the coupling is refreshed by reinstalling. The configuration block sets a generous network timeout for that fetch, which is a hint about how large those downloads are.
"args": ["mcp-server-linkedin@latest"]Two adjacent details matter. The browser binaries are prepared in the background on first start, under a directory in your home folder, so the first tool call can be slow. And the early calls may return a setup or authentication-in-progress error until that finishes, which is the kind of thing an agent will retry forever unless you tell it otherwise. There is an explicit login command for people who would rather create the session themselves.
Twelve browser names, and auto means the newest
Session import is the feature that makes the local-session story work, and its option list is a small time capsule of the browser market: Chrome, Chromium, Brave, Edge, Arc, Vivaldi, a couple of regional browsers, Opera in two variants, and an auto mode. Auto is described as picking the most recently used browser that has a live session, which is a heuristic rather than a rule, and on a machine signed into several browsers it will pick for you. Auto import is on by default but deliberately skips itself in three situations: inside a container, behind a proxy, and when the server is bound to something other than loopback. Those three exclusions are the security-relevant part of the option, since each one describes a context where reusing a desktop session is a worse idea. On one desktop system the keychain may prompt once.
Two timeouts that mean different things
The example environment file is the most informative document in the repository, because each setting comes with a comment explaining the failure it prevents. There is a browser timeout measured in milliseconds, which is how long a page operation may take. There is a separate per-tool execution timeout measured in seconds, and the comment distinguishes it explicitly from the first, because they fail with different errors and confusing the two costs an afternoon. There is a third for the manual login flow, in minutes, with a generous default and an option for no limit, covering the two-factor and captcha prompts that only a person can satisfy. The same file carries the headless switch, which the container overrides, a transport setting that triggers a chooser prompt in an interactive terminal, and a persistent profile directory whose non-default path is only honoured once a claim marker exists in it, because clearing a session deletes the directory.
The image is pinned by digest and labelled for the registry
The container build is the most carefully commented file in the project and explains three decisions that would otherwise look like over-engineering. Both base images are pinned by digest rather than by tag, including the one the package manager is copied from. The project itself is installed in a second step, with a long comment explaining that installing it invokes the build backend, that the sync command cannot constrain that build, and that the published distributions pin the backend against a constraints file, so a single job holding the registry credentials does not resolve a fresh build tool from the network. A no-dependencies flag on that second install keeps the runtime exactly as the frozen lock left it. Then a label instruction on the runtime stage, with a comment explaining that the registry proves ownership by comparing that label against a manifest file, and that it has to be on the shipped stage because builder labels never travel. The final image runs as an unprivileged user.
Compose warns against 127.0.0.1 inside a container
The compose file is short and each line carries a comment that prevents a support ticket. The image tag is pinned to the exact version rather than to latest, which is the least you want when the tool tracks a moving web interface. One volume persists your data directory into the unprivileged user's home, so sessions survive a container restart. The proxy settings are optional and passed through, with a warning that a relay running on the host must be addressed by the host gateway name rather than by loopback, because inside the container loopback is the container itself. Standard input and a terminal are both opened, which the file does not explain but which any interactive session will need. The repository root shows the same attention to detail in the tooling: a changelog directory for news fragments, a skills lock file, an example environment file that is really documentation, and three directories of assistant configuration.
Editorial conclusion
This server fits someone who wants an assistant to read profiles, look up companies, and search jobs without handing credentials to a third party, and who is comfortable debugging a browser automation stack. Two things to check before you wire it into an agent. Decide how automatic updates behave, because the recommended install tracks the latest release specifically so the automation survives changes to the site's markup, and an agent should ask before enabling that. And decide whether session import is acceptable in your environment, since it is disabled in containers, behind a proxy, and on non-loopback binds.
Frequently asked questions
is there a linkedin mcp server
Yes, this one. It is an open-source server that connects AI assistants to LinkedIn through your own logged-in browser session, with all browser actions running locally on your machine. It offers tools for profiles, companies, job postings, and messages, and the project states it is independent and unaffiliated with the platform.
How do I install the LinkedIn MCP server?
Install the uv tool, then add an entry to your MCP client configuration whose command is uv and whose arguments name the package at its latest tag, with a generous HTTP timeout set in the environment for that fetch. Install methods are also listed for a desktop bundle, a plugin, and Docker.
Why does the LinkedIn MCP server need my browser session?
It drives the site's own web interface rather than an official API, so it needs a signed-in session. It will reuse one from a locally signed-in browser, picking the most recently used browser in automatic mode, or open a login window if it cannot find one. Automatic import is skipped in containers, behind a proxy, and on non-loopback binds.
What are the timeout settings in the LinkedIn MCP server for?
Three different things. One is the browser page-operation timeout in milliseconds, another is the per-tool execution timeout in seconds, which the documentation says is deliberately distinct because the two produce different errors, and the third is the wait time for the manual login window in minutes, which has to accommodate two-factor prompts and captchas.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/stickerdaniel-linkedin-mcp-server)Star history chart for your README
[](https://hysenlabs.com/projects/stickerdaniel-linkedin-mcp-server)Was this useful?