PGMCP points an agent at your database and blocks every write
An MCP server to query any Postgres database in natural language.
At a glance
- What is it?
- A Go MCP server that answers questions about an existing PostgreSQL database in plain English and returns structured results, with automatic streaming and read-only enforcement. The bundled sample schemas are deliberately adversarial, including a mixed-case table name and a composite key chosen to break model assumptions.
- Who is it for?
- PGMCP suits someone who already has a database and wants to interrogate it conversationally without writing SQL by hand, since it attaches to the schema you have rather than asking you to model anything. It is the wrong tool for a database you cannot expose, because authentication is opt-in while the default bind address is all interfaces.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 173 days ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
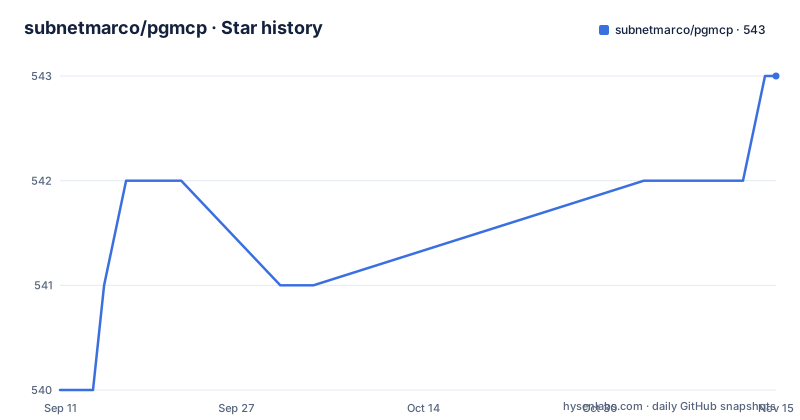
- subnetmarco/pgmcp543 ★ · +3
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| subnetmarco/pgmcp | 540 | 543 |
3 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
It attaches to a database you already have
There is no schema modelling step and no migration, because the server connects to a database that already exists with its own schema.
One required environment variable does the work, a PostgreSQL connection string. Everything else has a default:
# Set up environment variables
export DATABASE_URL="postgres://user:password@localhost:5432/your-existing-db"
export OPENAI_API_KEY="your-api-key"  # Optional

# Run server (using pre-compiled binary)
./pgmcp-server
The model used for query generation defaults to a small one and can be overridden, so the cost of the natural language layer is tunable.
Two binaries ship. The server does the work; the client is what you point at it, and it takes a question and an output format:
./pgmcp-client -ask "What tables do I have?" -format table
./pgmcp-client -search "john" -format table
Output can be a rendered table, JSON, or CSV, and there is a row cap for exports. Several questions can be asked in a single invocation rather than one process per question.
The feature list is short and each item is load bearing: streaming that handles large result sets without the client giving up, read-only enforcement that prevents writes, text search across every text column, and mixed-case table name handling, which is a real problem in PostgreSQL rather than a hypothetical one.
The bind address defaults wide and authentication defaults off
Two defaults deserve attention before this runs anywhere a network can reach it.
The server address defaults to a bare port with no host specified, which binds all interfaces. The endpoint path defaults to a fixed route.
Authentication is configured by a bearer token variable that is listed as optional. So out of the box the server listens on every interface with no token required.
That combination is not unusual for a developer tool and is not safe for a shared machine or a hosted instance. The connection string already carries a database username and password, so anyone who can reach the endpoint can attempt queries against your database with your credentials, and the read-only guarantee is enforced by the server's own logic rather than by anything the network enforces for you.
The read-only guarantee is still worth stating precisely, because it is the load-bearing safety property. Write operations are prevented by the server. If you want a second layer, the answer is the connection string: point it at a database role that cannot write in the first place, and the server's own check becomes defence in depth rather than the only thing standing between a question and a mutation.
The container and Kubernetes paths both take the connection string through environment configuration, and the Kubernetes example creates a secret for it rather than embedding it in a manifest.
The sample schema is built to make the model wrong
Two schemas ship for trying this out, and the differences between them are the point.
One is a full marketplace-style schema with more than five thousand records. The other is a minimal test schema whose distinguishing feature is a table with a mixed-case name.
That is deliberate. A quoted mixed-case identifier is one of the places a generated query reliably goes wrong, and it is listed as a feature of the server rather than of the fixture, meaning handling it is part of what the tool claims to do.
The other fixture choice is more pointed. The schema includes a composite primary key, and the documentation says this exists for testing AI assumptions.
That is the single most useful line in the repository for deciding whether to trust the output. A single-column primary key is what most models assume, and a composite key is a cheap way to find out whether the query being generated was reasoned about or pattern-matched.
The rest of the fixture is ordinary realistic data, with relationships and types chosen to look like a real application.
So the minimal schema is the one to load first. It is small enough to read, adversarial in the two places that matter, and it tells you quickly whether the tool needs work on your schemas rather than on these particular ones.
Bad generated SQL comes back as structured feedback
Natural language to SQL fails regularly, so the interesting question is what happens when it does.
The answer is a structured error rather than a crash. The response carries an error description, a suggestion, and the SQL that was actually generated:
{
  "error": "Column not found in generated query",
  "suggestion": "Try rephrasing your question or ask about specific tables",
  "original_sql": "SELECT non_existent_column FROM table..."
}
Three things are worth noting about that shape.
The generated SQL is echoed back. That turns an opaque failure into something you can inspect, which is the difference between a tool you debug and one you abandon.
The suggestion is actionable and conservative: rephrase, or ask about specific tables. It does not attempt a silent retry with a different guess.
And the framing is that the system continues operating. A failed query is a normal outcome rather than an exception, which matters for a client that may be asking many questions in sequence.
The server itself is written in Go and exposes its surface over the protocol rather than over HTTP routes of its own design, so clients see a small tool set: a question tool returning SQL results with streaming, a free-text search tool spanning all text columns, and a streaming tool.
The container is built from scratch and carries only the server
The image is as small as a Go binary allows, and the consequences are visible in the build file.
It starts from an empty base and copies two binaries in from the build context, which the release tooling places there. One port is exposed and the server is the entrypoint.
Two things follow from a base of nothing. There is no shell in the image, so any troubleshooting has to happen from outside rather than by exec-ing in. And there are no certificate authorities bundled, which is worth knowing if you point it at a database requiring TLS verification.
The client binary is copied into the image but is not the entrypoint, so in practice the image is a server image with a spare file alongside. Running the documented container command gives you the server; testing it from inside the image is not the intended path.
The alternative install routes are a release archive per platform, a Homebrew tap, and building both binaries from source. The source route documents static stripped builds with linker flags, which is the version to use when you are producing something you intend to distribute.
The module manifest pins a modern Go release and four direct dependencies: the PostgreSQL driver, the official protocol SDK for Go, the OpenAI client, and a structured logger.
The module path in the manifest is still a placeholder
One detail in the source manifest is worth flagging because it will affect anyone building from a clone.
The declared module path is a generic placeholder naming a different account and repository than the one this project lives in. It does not match the repository it is published from.
What this means practically depends on what you are doing. Importing the module from your own code by its published path is unaffected, because consumers resolve the module path from the version control location. But building locally, vendoring by module path, or referencing the module by its declared name inside tooling will hit a mismatch, and the import rewrite tooling in Go will try to fetch that placeholder path and fail.
It is the kind of thing that survives from a project initialised from a template, and it costs an afternoon to diagnose if you have not seen it before.
Otherwise the repository is conventional: a server directory, a client directory, the two SQL schemas at the root, example manifests, a release configuration, and a release process document.
On project state, the repository is not archived, the last push is dated 2026-05-26, and there is a single published release, version 0.3.0 from September 2025. That gap between the last push and the only release is worth keeping in mind if you are deciding how much to depend on it.
Editorial conclusion
PGMCP suits someone who already has a database and wants to interrogate it conversationally without writing SQL by hand, since it attaches to the schema you have rather than asking you to model anything. It is the wrong tool for a database you cannot expose, because authentication is opt-in while the default bind address is all interfaces. Before pointing an assistant at anything real, set a bearer token, load the minimal schema rather than the five thousand record marketplace one, and remember that a natural language question is not a permission model.
Frequently asked questions
Does PGMCP let an assistant write to my database?
No. Safe read-only access is a stated feature: write operations are prevented by the server. If you want a second layer, point the connection string at a database role that cannot write at all.
How do I connect PGMCP to an existing database?
Set a DATABASE_URL connection string and run the server. That is the only required variable. The model, the listen address, the endpoint path and a bearer token all have defaults or are optional.
Which clients can talk to PGMCP?
Any MCP-compatible client. The documentation gives configuration for Cursor and for Claude Desktop, both pointing at an HTTP transport on the server's endpoint, and it also lists VS Code extensions.
What happens when the model generates SQL that does not work?
You get a structured response rather than a crash, carrying an error description, a suggestion to rephrase or ask about specific tables, and the original generated SQL so you can inspect what was attempted.
Which sample schema should I use to try PGMCP?
The minimal one first. It contains a mixed-case table name for testing case handling and a composite primary key that exists specifically to test model assumptions, whereas the other schema is a marketplace dataset with thousands of records.
Is authentication required to run PGMCP?
No, a bearer token variable is optional, and the listen address defaults to binding all interfaces. Set a token before running it anywhere reachable, since the database credentials travel in the connection string.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/subnetmarco-pgmcp)Star history chart for your README
[](https://hysenlabs.com/projects/subnetmarco-pgmcp)Was this useful?