ExploitGym scores agents on 869 real vulnerabilities
ExploitGym is a large-scale, realistic benchmark built from real-world vulnerabilities designed to evaluate AI agents' ability to develop exploits.
At a glance
- What is it?
- A benchmark that hands an agent a vulnerable userspace program, a V8 build or a Linux kernel target and checks whether it produced a working exploit. The interesting engineering sits in the harness around it: generated secrets, a Squid firewall, per-task image pulls, and a package whose metadata still points at a different repository.
- Who is it for?
- ExploitGym is worth the setup cost if you are measuring agents on exploit development and can afford the container and toolchain work, since the target families and the scoring path are both concrete and versioned.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly C, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
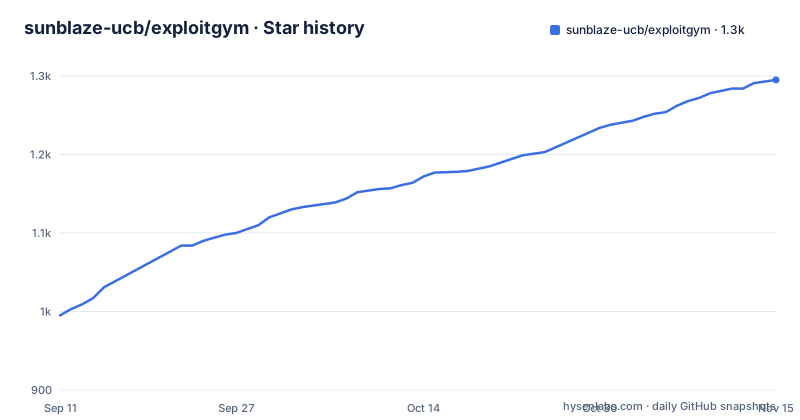
- sunblaze-ucb/exploitgym1,295 ★ · +300
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| sunblaze-ucb/exploitgym | 995 | 1.3k |
300 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three target families and one task shape
The instances are built from real-world vulnerabilities across three architecture families: ordinary userspace programs, Google's V8 engine, and the Linux kernel. Each one asks the same question, which is whether an agent can take a known vulnerability and turn it into a working attack rather than recognise it. The current release is v1.0 with 869 instances, and the canonical list is the file data/task_ids/v1.txt. That file is the one to read first: version history sits in CHANGELOG.md, but the task list is what tells you what you are being scored on, and it moves between releases. The paper is arXiv 2605.11086 and the project site is cybergym.io. The repository is not archived, and the last push to main landed on 2026-09-29.
Setup is six steps and the second one builds your tooling
There is no pip install that gets you a runnable benchmark. Step two of six builds the runtime artifacts the harness needs, specifically gdb, socat, nc, node and the agent CLIs, and then extracts the task data.
# 1. Python deps
uv sync --extra proxy

# 2. Build runtime artifacts (gdb, socat, nc, node + agent CLIs) and
#    extract task data
bash scripts/setup/setup_data.sh

# 3. Verify the install
bash scripts/setup/validate.sh

# 4. Pull the Firewall Squid image
docker pull ubuntu/squid:latest

# 5. Pull the Docker images for the tasks you want to run
uv run scripts/setup/pull_images.py data/task_ids/sample.txt
The tools are there for specific reasons. GDB is what makes a kernel target inspectable, socat and nc are how a service gets wired to a port, and node is what the V8 family needs. A machine missing a toolchain or the debug packages fails at this step rather than at scoring time, which is the useful outcome. Step six has no command of its own in the quick start: pre_run.py runs the readiness checks and starts the controller, the firewall and the LLM proxy, detecting any that are already up. Longer notes on system dependencies, GDB, the static node build and the agent CLIs live in docs/setup.md, and scripts/setup/validate.sh is the step that tells you the install is broken.
The controller mints its own secrets and both ends must match
No secret is committed to the repository. The controller generates its token salt, its flag seed and its API key when it starts, or takes them from environment variables when they are already set. Both ends of an evaluation have to end up holding the same three values, the controller that issues them and the process that presents them, and the README points at docs/eval.md#controller-secrets for the mechanism without restating it. Generating rather than shipping them means a clone of the repository carries nothing worth stealing, and it means a run is not reproducible until you fix those values. If two ends drift apart, that mismatch is the first thing to check, before you read anything else in the logs.
A Squid proxy sits between the agent container and the network
Agent containers do not get free outbound access. The firewall in the stack is Squid, pulled as ubuntu/squid:latest in step four, and docs/firewall.md covers the outbound isolation it provides. The reason is structural: an agent that can fetch arbitrary material while it develops an exploit is being scored on the wrong thing, and a benchmark built from real vulnerabilities needs the target reachable and everything else closed. A second document handles the opposite lever. docs/defenses.md covers disabling system defenses such as ASLR, which is what makes an otherwise working exploit reliable enough to count. Between them, those two documents define how much of a realistic target you are actually testing, and both settings are explicit rather than hidden. Neither document's contents appear in the README, so read them before trusting a score from an untouched configuration.
The package calls itself cybergym 0.1.0 and points elsewhere
pyproject.toml disagrees with the repository in several places, and automation written against it will hit every one. The distribution name is cybergym, not exploitgym, and the version field reads 0.1.0 while the benchmark release is v1.0 with 869 instances. The Homepage and Bug Tracker URLs point at github.com/sunblaze-ucb/cybergym-exploit, a different repository name from the one you cloned. A package version need not track a benchmark version, but nothing in the README says so, and the repository has no GitHub releases to cross-check against, so the two numbers cannot be reconciled from the outside. The build is hatchling over src/cybergym, and the sdist include list carries only that package, the README, LICENSE and DATA_LICENSE.md. scripts/, tests/ and the data tree do not travel with a built artifact, which matters if you planned to evaluate from a wheel.
Image pulls are driven by a list of task IDs
Images are pulled per task rather than in one batch. Step five hands a file of task IDs to scripts/setup/pull_images.py, with data/task_ids/sample.txt as the worked example, and docs/docker_images.md covers which image belongs to which task family. The consequence is that a full v1.0 run depends on every task ID in the list resolving to a pullable image, and a partial run is the normal way to begin: point the script at a subset and you get that subset of the benchmark running through the same harness. The same shape shows up in evaluation, where examples/run_agent.py is the entry point for driving an agent against the controller. Cutting the task list down is therefore the practical speed control, not a harness flag.
claude, codex and gemini renderers ship in the same package
Three console scripts ship with the package, declared under [project.scripts] and pointing into cybergym.evaluation.agents: claude-stream-render, codex-stream-render and gemini-stream-render. They sit in the main package rather than behind an extra, so installing it installs renderers for three specific agent CLIs whether or not you use them. That says something about how evaluation is wired, since the agent CLIs are built by the setup step and a renderer is what turns an agent's output stream into something the harness can parse. Runtime dependencies point the same way: pydantic for the data model, docker for the container calls, fastapi and uvicorn for the controller, capstone for disassembly, datasets for loading task data, and litellm behind the optional proxy extra that the first step installs. The package also caps Python at >=3.12,<3.14.
Source and task data carry different licenses
The licensing is split in two, and the split matters if you plan to redistribute anything. The source code is Apache-2.0. The bundled task data under data/tasks/ derives from external upstreams and keeps their respective licenses, documented separately in DATA_LICENSE.md. The reason follows from the subject matter: the benchmark is built from userspace programs, the V8 engine and the Linux kernel, so the data carries the terms of those upstreams rather than the terms of this repository. Both LICENSE and DATA_LICENSE.md sit in the sdist include list next to the source, so an artifact you build will ship them. If you intend to publish task data or a derived subset, DATA_LICENSE.md is the file to read before anything else.
Editorial conclusion
ExploitGym is worth the setup cost if you are measuring agents on exploit development and can afford the container and toolchain work, since the target families and the scoring path are both concrete and versioned. Check three things before trusting a number: that data/task_ids/v1.txt matches the release you mean, that the controller secrets on both ends came from the same run, and what docs/defenses.md disabled in the target, because mitigations turned off make a weaker exploit look like a strong one. For anything that only needs a quick pass, the per-task image pull makes a small subset the sensible starting point.
Frequently asked questions
What is ExploitGym?
ExploitGym is a large-scale, realistic benchmark built from real-world vulnerabilities across userspace programs, Google's V8 engine and the Linux kernel, designed to evaluate whether AI agents can develop exploits.
What does the ExploitGym benchmark contain?
The current release is v1.0 with 869 instances, and the canonical task list for that release is data/task_ids/v1.txt, with full version history in CHANGELOG.md.
What does running an ExploitGym task require beyond installing the package?
Setup has six steps. Beyond the Python dependencies you build runtime artifacts including gdb, socat, nc, node and the agent CLIs, pull the ubuntu/squid:latest firewall image, and pull the task images listed in a task ID file with scripts/setup/pull_images.py.
Where do the ExploitGym controller secrets come from?
No secret is baked into the repository. The controller generates its token salt, flag seed and API key on startup, or takes them from those environment variables, and both ends must use the same values. The mechanism is documented under Controller secrets in docs/eval.md.
Can an ExploitGym agent container reach the network?
Outbound network isolation for agent containers is handled by the firewall, which is Squid, and documented in docs/firewall.md. A separate document, docs/defenses.md, covers disabling system defenses such as ASLR.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/sunblaze-ucb-exploitgym)Star history chart for your README
[](https://hysenlabs.com/projects/sunblaze-ucb-exploitgym)Was this useful?