PyHealth 2.0: a handbook, two license files, and a version string nobody automates
A Deep Learning Python Toolkit for Healthcare Applications.
At a glance
- What is it?
- sunlabuiuc/PyHealth is a clinical deep learning toolkit whose own README opens by warning it may be out of date. Underneath that warning sit three separate license claims, a version number a comment says no tool updates, a Python range that splits 2.0 from 1.16, and a 3x faster than pandas bullet with no benchmark beside it.
- Who is it for?
- PyHealth suits teams that already have healthcare data in MIMIC, eICU or OMOP form and want the preprocessing, model and metric layers under one import. Before you build on it, settle three things yourself.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 22, 2026, and from our analysis. They are not legal advice.
Star history
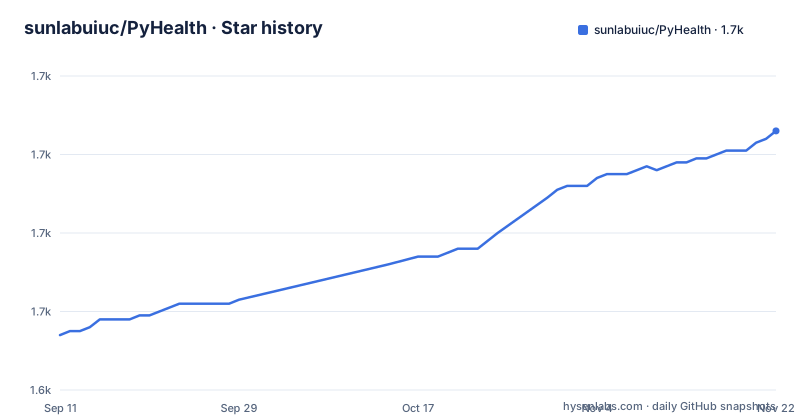
- sunlabuiuc/PyHealth1,706 ★ · +52
| Repository | 2026-09-11 | 2026-11-22 |
|---|---|---|
| sunlabuiuc/PyHealth | 1.7k | 1.7k |
52 Stars in the last 72 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three sources name three different licenses
Nothing in this repository settles which license applies. The metadata recorded against the repository says MIT. The build configuration says something else:
license = "BSD-3-Clause"
license-files = ["LICENSE.md"]
And the root of the tree carries two files, `LICENSE` and `LICENSE.md`, with the project configuration pointing only at the second one. That is three answers to one question, and none of the three sources explains the disagreement or says which governs when they conflict. The metadata answer and the build answer are not equivalent in practice, since the terms differ. Anyone planning to use PyHealth in a product should read both files and get the answer in writing rather than inferring it from whichever file their tooling happened to open. The keyword list in the same build file also carries a typo, `heathcare AI`, which suggests the metadata block is maintained by hand rather than generated.
The version string says no automation touches it
`pyproject.toml` pins the version with a comment that explains the whole risk in one line: it must be kept in sync with git tags and is not updated by any automation tools. The value sitting there is `2.0.2`, which matches the newest release tag, PyHealth 2.0.2, published on 2026-09-02. The two earlier tags sit at 2.0.0 on 2026-03-23 and 2.0.1 on 2026-04-01, so the line has moved three times in six months with the same manual step each time. The last push to the repository is dated 2026-09-27, twenty five days after that tag, so work has landed since the release without a version bump, which is normal, and the thing to watch is the window where the file and the tag disagree. For a package that reads its own version at install time, that window is where a wheel gets built under the wrong number.
Python 3.12 and 3.13 for 2.0, 3.9 and up for 1.16
The install section splits the package in two by interpreter. PyHealth 2.0 requires Python 3.12 or 3.13, declared in the build file as `requires-python = ">=3.12,<3.14"`, and the file gives the reason as parallel processing, memory management and dependency compatibility. The older stable version, 1.16, is still published and supports Python 3.9 and up. That leaves Python 3.9, 3.10 and 3.11 users with exactly one option, and the option is a different code line rather than an older patch of the same one. The three commands are:
pip install pyhealth
pip install pyhealth==1.16
git clone https://github.com/sunlabuiuc/PyHealth.git
The clone is the contributor path, followed by `cd PyHealth` and `pip install -e .`. One more fact about the default install: 2.0 pulls PyTorch and the other deep learning dependencies automatically, so a plain `pip install` is already a large download before you decide which models you need.
The default dependency set reaches chemistry, EEG and a linear attention transformer
The required dependency list is twenty three entries and reads like several projects merged into one. Clinical deep learning accounts for `torch>=2.10`, `torchvision`, `transformers>=4.53.2`, `peft`, `accelerate` and `ogb>=1.3.5`. Medical coding arrives as `icd-mappings~=0.6.2`. Chemistry is there through `rdkit`, and signal processing through `mne~=1.10.0`, which is an EEG library. The data layer is a stack of interchangeable fast readers: `polars~=1.35.2`, `pandas~=2.3.1`, `pyarrow>=23.0.1`, `dask[complete]>=2026.1.0`, `litdata~=0.2.59`, `orjson~=3.10` and `narwhals~=2.13.0`. Then `linear-attention-transformer>=0.19.1`, which is not a clinical package at all. Three optional groups narrow it: `graph` adds `torch-geometric>=2.6.0`, `nlp` adds rapidfuzz, rouge_score and nltk, and `lint` adds `ruff~=0.15`. The graph and nlp groups are gated; rdkit, mne and the attention package are not.
The citation block contradicts the citation block
The citing section offers two references, and the 1.0 entry disagrees with itself in two places. The prose names the venue as the 29th ACM SIGKDD Conference on Knowledge Discovery and Data Mining and gives pages 5788 to 5789, while the BibTeX entry below it names the 27th ACM SIGKDD International Conference, with no pages. The title also changes between the two: the prose calls it PyHealth: A Deep Learning Toolkit for Healthcare Applications, which matches the repository description, and the BibTeX calls it PyHealth: A Deep Learning Toolkit for Healthcare Predictive Modeling. Anyone copying the BibTeX gets different venue numbering and a different subtitle from the same block. The 2.0 entry points at arXiv preprint 2601.16414 with eighteen listed authors, and it is the reference the README asks you to use. A note above all of this says the file itself may be out of date and points to the hosted documentation instead.
The 3x faster than pandas bullet has nothing behind it
The feature list claims fast data processing at roughly three times pandas, with the speedup in parentheses and no table, no hardware line and no method anywhere near it. The same list claims a modular five stage pipeline for healthcare machine learning, healthcare first handling of medical codes with MIMIC, eICU and OMOP named as the datasets, 33 or more pre built models with a production ready trainer and metrics, and 10 or more supported tasks. The performance claim is the only one of those with a number attached, and it is also the only one that cannot be checked from the file. The repository does contain the places to check it: `examples/benchmark_perf/` as a directory, `examples/benchmark_pyhealth.ipynb`, and `examples/benchmark_ehrshot_xgboost.ipynb`. Related to them is `examples/dataset_cache_refresh.py`, which implies datasets are cached on disk between runs. The feature list also carries a hedge of its own elsewhere in the file, which says some modules are still being enriched.
Examples split across MIMIC-III and MIMIC-IV
The `examples/` directory is where the toolkit's real scope shows, and the versions disagree with each other. Four notebook families target MIMIC-III: `gamenet_mimic3.ipynb`, `gpt2_mimic3.py`, `halo_mimic3.py` and `event_timestamps_mimic3demo.py`. A larger group targets MIMIC-IV: `agent_mimic4.ipynb`, `cnn_mimic4.ipynb`, `deepr_mimic4.ipynb`, `ehrmamba_mimic4.ipynb`, `gat_mimic4.ipynb`, `gcn_mimic4.ipynb` and `concare_mimic4_example.ipynb`. Alongside them sit task folders for clinical tasks, drug recommendation, chest radiographs under `cxr/`, EEG under `eeg/`, conformal prediction under `conformal_eeg/`, and interpretability. Two entries do not fit a clinical framing at all: `cardiology_detection_isAR_SparcNet.py`, which is a specific detection model, and `graph_torchvision_model.ipynb`, a vision example sitting in a healthcare repository. The mixed dataset versions matter in practice, because an example written against MIMIC-III is not a drop in replacement for one on MIMIC-IV.
A master branch, a lowercase makefile, and a pixi lock file
The root of the repository shows two build systems and one spelling mistake. The default branch is `master` rather than `main`. The build file is a lowercase `makefile`, and beside it sits `pixi.lock`, which is a lock file for a different environment manager entirely, so there are two ways to pin an environment and no statement about which one the maintainers use. Documentation is hosted through `readthedocs.yml`, and the repository also carries `docs/`, `CHANGELOG.md`, `CONTRIBUTING.md`, `SECURITY.md` and `tools/`. Two directories do not belong to a library: `hackthon/`, spelled without the second a, and `leaderboard/`. The readme also points at `pyhealth.readthedocs.io` for current documentation while opening with a note that it may be out of date, which is an honest arrangement but leaves the repository file and the hosted site as two sources that can drift. The last push was 2026-09-27 and the repository is not archived.
Editorial conclusion
PyHealth suits teams that already have healthcare data in MIMIC, eICU or OMOP form and want the preprocessing, model and metric layers under one import. Before you build on it, settle three things yourself. Read both `LICENSE` and `LICENSE.md` and ask the authors which one governs, because the project files, the repository metadata and the file tree each name a different answer. Decide which Python you are on, because 3.12 and 3.13 mean 2.0 while 3.9 through 3.11 mean the 1.16 line and a different API. And treat the performance claim as unverified until you run the benchmark notebooks in `examples/benchmark_perf/` yourself, since the 3x figure arrives as a bullet with nothing behind it. Install the extras you need rather than the whole set, because the default dependency list already carries rdkit, mne and a linear attention transformer whether or not your task touches them.
Frequently asked questions
What is PyHealth and who is it built for?
A deep learning toolkit for clinical predictive modeling, written for ML researchers and medical practitioners. It offers a modular five stage pipeline, medical codes and datasets including MIMIC, eICU and OMOP, and 33 or more pre built models with a trainer and metrics.
Which Python versions does PyHealth 2.0 support?
Python 3.12 or 3.13, declared as >=3.12,<3.14, with the reason given as parallel processing and memory management. The legacy 1.16 release supports Python 3.9 and up.
How do you install PyHealth from source for development?
git clone https://github.com/sunlabuiuc/PyHealth.git, then cd PyHealth and run pip install -e . The 2.0 install also pulls PyTorch and the other deep learning dependencies automatically.
What optional dependency groups does PyHealth define?
Three: graph adds torch-geometric>=2.6.0, nlp adds rapidfuzz, rouge_score and nltk, and lint adds ruff~=0.15. Twenty three further packages, including rdkit and mne, are required rather than optional.
Which license governs PyHealth?
The repository is not consistent about it. The metadata records MIT, the build configuration declares BSD-3-Clause with LICENSE.md as the license file, and the tree holds both a LICENSE and a LICENSE.md.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/sunlabuiuc-pyhealth)Star history chart for your README
[](https://hysenlabs.com/projects/sunlabuiuc-pyhealth)Was this useful?