AI-Codereview-Gitlab posts LLM review comments, and its agent mode clones your repo
An LLM-based (DeepSeek, OpenAI, etc.) automated code review tool for GitLab; supports pushing notifications and generating daily reports via DingTalk/WeCom/Lark, Docker deployment, and a visual dashboard.
At a glance
- What is it?
- A Chinese language GitLab webhook reviewer for DeepSeek, ZhipuAI, OpenAI, Anthropic, Qwen and Ollama, with a Streamlit dashboard and a DingTalk, WeCom or Feishu push. The optional agentic mode gives the model a sandboxed shell, a 30 second timeout and a fallback to plain diff review when anything fails.
- Who is it for?
- This suits a team already on GitLab merge requests that wants a second reader on every diff and is comfortable giving an internal service a personal or project access token. Five things to check first.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 38 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
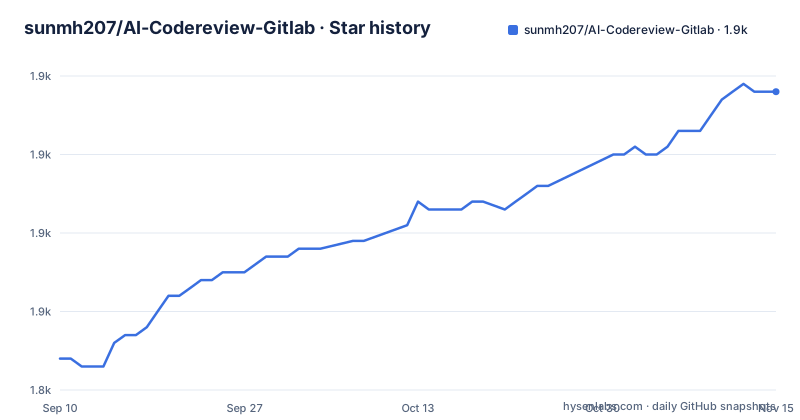
- sunmh207/AI-Codereview-Gitlab1,878 ★ · +34
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| sunmh207/AI-Codereview-Gitlab | 1.8k | 1.9k |
34 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The deployment notes tell you to expose it publicly if GitLab cannot reach it
The mechanism is a webhook and a Flask endpoint, and the network requirement is stated without much hedging. GitLab has to be able to reach this system, and if the internal network is restricted the notes recommend deploying on a public server. That sentence sits in the middle of otherwise ordinary setup instructions, and it is the one with consequences.
The webhook is configured on the GitLab project with the URL http://{your-server-ip}:5001/review/webhook, with Push Events and Merge Request Events ticked and an instruction not to tick the others. The secret token field is optional and is set to the same access token, and the token priority is spelled out: the system uses GITLAB_ACCESS_TOKEN from the environment file if it is set, and falls back to the webhook's secret token if it is not.
That fallback is worth noticing. If you do not put a token in the environment file, the review endpoint authenticates whoever GitLab sends, with no independent check of its own, and the notes point you at putting the service on a public server.
The dashboard is a second process on a second port. The compose file publishes both 5001 and 5002 to the host, and the local instructions start the interface with:
streamlit run ui.py --server.port=5002 --server.address=0.0.0.0Binding Streamlit to all interfaces is what makes it reachable from outside the box, and nothing on the page describes a login for either port. Verification is by visiting the address and looking for the string The code review server is running. on 5001 and a review log page on 5002.
The token itself is a GitLab personal access token or a project access token, and the page names both routes. A project scoped token is the narrower of the two.
Agentic mode gives the model a shell and a 30 second timeout
The optional mode is the interesting part of this project, and the project is unusually honest about what it costs.
A variable called REVIEW_STRATEGY switches between two strategies. diff_only is the default and reviews only the diff, behaving exactly as the earlier version did. agentic gives the language model tool calling, with read_file and a sandboxed run_command, and lets it explore a locally cloned copy of the repository on its own so the review can be more complete.
The sandbox is described in three layers: a command allowlist, a blacklist, a path boundary check, and a 30 second timeout. By default only read class commands are permitted, with ls, cat, grep, find and git log given as examples. Loosening it is done through AGENT_SHELL_ALLOWLIST and AGENT_SHELL_BLOCKLIST.
The fallback is the design decision that matters most. If any stage fails, whether the clone, the fetch, the model call or a tool call, the run degrades automatically back to diff_only so that at least a review identical to the original version comes back. A feature that can fail open into its own previous behaviour is much easier to leave switched on in a merge request hook than one that fails closed.
The cost is published as a table: disk of 50 GB or more recommended, about 500 MB peak memory per session, 5k to 50k tokens per review which is 3 to 10 times the diff only path, and 30 seconds to 5 minutes per review. The repository cache is configurable, defaults to data/repo_cache/ inside the project, and clones or updates the target repositories as needed at roughly 10 MB to 2 GB per project. The iteration count is configurable too, with AGENT_MAX_ITERATIONS defaulting to 20.
So the arithmetic is: full clones on local disk, a 50 GB floor, a latency budget measured in minutes on the merge request path, and a token bill that is an order of magnitude above the default path. That is a deliberate trade for reviews that look outside the diff.
Six providers in the feature list, four in the sample environment file
The provider story is the clearest example of the documentation drifting from the code.
The feature section says the tool is compatible with DeepSeek, ZhipuAI, OpenAI, Anthropic, Qwen and Ollama, with the phrase that you can use whichever you want. The dependency list backs five of those six directly: anthropic pinned at 0.39.0, openai at 1.59.3, ollama at 0.4.7, zhipuai at 2.1.5.20230904 and spark-ai-python at 0.4.5, which is the Qwen SDK. python-gitlab at 5.6.0 covers the GitLab side and tiktoken 0.9.0 covers token counting.
The sample environment file, though, carries a different comment. It says the supported providers are zhipuai, openai, deepseek and ollama, and then configures one of them:
#大模型供应商配置,支持 zhipuai , openai , deepseek 和 ollama
LLM_PROVIDER=deepseek

#DeepSeek
DEEPSEEK_API_KEY={YOUR_DEEPSEEK_API_KEY}
So Anthropic and Qwen are supported by the code and missing from the comment a new user copies. DeepSeek has no client library in the list at all, which suggests it is reached through the OpenAI compatible client rather than a vendor SDK.
One other line in that file decides what gets reviewed at all:
#支持review的文件类型(未配置的文件类型不会被审查)
SUPPORTED_EXTENSIONS=.java,.py,.php,.yml,.vue,.go,.c,.cpp,.h,.js,.css,.md,.sql
The comment states that file types which are not configured will not be reviewed. That is a silent skip rather than a warning, so a merge request touching only unlisted types produces a review with nothing in it, and markdown is in the list, which means documentation diffs go to the model too.
The notification settings sit in the same file, with DingTalk on by default disabled and a webhook URL placeholder, plus a GITLAB_ACCESS_TOKEN placeholder for the GitLab configuration.
The image runs as root and copies ripgrep and tree for the sandbox
The container is one service with two ports, and the build file shows what the runtime needs.
It starts from the Python 3.10 slim image, works in /app, installs supervisor along with git, ca-certificates, ripgrep, tree and file, installs the pinned requirements, creates log, data and conf, and copies four things in: the biz directory, the fonts directory, api.py and ui.py, plus two files from conf, the prompt templates as YAML and the supervisord configuration. The prompt text lives in a YAML file rather than in the Python source, which is the right place for it if you want to change the review voice.
The ripgrep and tree packages are there for the agentic sandbox. Those are the implementations behind grep and the directory listing commands in the allowlist, so the read only default is backed by two specific tools rather than by shell built ins.
Two details in the build are worth noting on their own. There is no USER instruction, so the container runs as root, and this is the image that clones repositories and executes model chosen shell commands. And the runtime is supervisord, which is how two long running processes share one container.
The compose file matches that shape: a single service built from the Dockerfile, tagged ghcr.io/sunmh207/ai-codereview-gitlab:1.5.1, publishing 5001 and 5002, mounting ./data and ./log from the host so review records and logs survive a rebuild, reading its configuration from ./conf/.env, and restarting unless stopped.
That image tag is the released version, and it tells you where the project stands. The three most recent releases are 1.4.2 on 15 March 2026, 1.4.3 on 20 May and 1.5.1 on 29 June, while the last commit on the default branch is dated 12 September 2026. So development has continued for more than two months past the newest tagged release, and anyone pinning the image is pinning code from June.
Two document directories and a duplicated Flask pin in one requirements file
The dependency file is small enough to read line by line, and it has the marks of a project that grew by adding rather than by pruning.
Flask 3.0.3 appears twice, on consecutive lines of the same list, with nothing between them but other entries. pip will install it once and say nothing, so the duplication is harmless at install time and mildly confusing when someone tries to change the version.
Almost everything else is pinned exactly, which is unusual and mostly a good thing for a service whose output depends on model SDK behaviour. anthropic 0.39.0, openai 1.59.3, ollama 0.4.7, zhipuai 2.1.5.20230904, spark-ai-python 0.4.5, streamlit 1.42.2, pandas 2.2.3, matplotlib 3.10.1, python-gitlab 5.6.0, tiktoken 0.9.0. The one entry with no version is httpx with the socks extra, which is the HTTP client that can route through a SOCKS proxy. For a tool that calls hosted model APIs and possibly a local Ollama instance, having that client behind a proxy is a deliberate capability rather than an accident.
The analysis stack is worth calling out as a group: lizard for complexity measurement, pandas for aggregation and matplotlib for plotting, with a fonts directory copied into the image to render charts. That is the dashboard's statistics, and it explains why the repository carries fonts at all.
Persistence goes through PyMySQL, so review records can live in MySQL rather than only on disk, and streamlit-cookies-manager handles the interface side. The test stack is pytest with pytest-mock and pytest-coverage, and a pytest.ini sits at the root next to a tests directory.
At the top level there are two documentation directories, doc/ and docs/. One of them holds the FAQ and the Pro version notes. Having both is a small navigational problem that every contributor will hit.
Four review styles, one of them deliberately sarcastic
The tone of the output is a setting, and the four presets are named after personalities rather than after severity levels.
The professional style is described as rigorous, detailed and formal. The sarcastic style is caustic and aimed at people who need convincing, with the example line asking whether the code was written with a foot. The gentleman style offers gentle suggestions like perhaps this part could be optimised a little further. The humorous style makes jokes about the code, with an example comparing a convoluted if-else chain to a dating history.
Each of those examples is written for a Chinese language audience, and the page itself is in Chinese throughout, with an English readme not listed among the top level files here. If you deploy this for a team that reads English, the style presets will produce Chinese output unless you rewrite the prompt templates, and the templates are a YAML file in conf/ rather than something buried in the source.
The same YAML file is where the tone is defined, which is the good news: you can see and change what the model is being told to sound like, rather than trying to reverse it from the output.
Beyond the review itself, three other features exist. Review results can be pushed straight to DingTalk, WeCom or Feishu; the DingTalk route is a custom robot in a group whose webhook URL goes into the environment file, and the page says the other two are configured the same way with details in the FAQ. A daily report is generated from commit records across GitLab, GitHub and Gitea, which is the one feature here that reads from more than the GitLab instance the tool is installed against. And the dashboard collects review records with project and developer statistics, described as making it hard to pass the buck.
The paid version installs from a curl pipe on the main branch
Three sibling projects are advertised at the bottom, and one of them is worth reading carefully.
Code Review Pro is the commercial version of this reviewer, with its own documentation page, and its quick install is:
curl -fsSL https://raw.githubusercontent.com/sunmh207/AI-Codereview-Gitlab/refs/heads/main/scripts/pro/install.sh | bashA script fetched from the main branch of a repository and piped straight into a shell runs whatever that branch contains at the moment you run it, with no version and no review. For an open source tool that asks for a GitLab access token, that is a sharper edge than the Docker Compose path, which at least pins an image tag.
The other two are separate open source projects by the same author. Site Watch is a site health checker built around detection items, monitoring availability, HTTP liveness and TLS certificate expiry with automatic alerts, described as lightweight and self-hosted with one command Compose deployment. Task Flow is task management for small teams, chaining task creation, progression, collaboration, a board and DingTalk daily or weekly reports, with AI written weekly reports and Docker deployment.
All three push notifications to DingTalk, which is a consistent choice across the author's work and the reason the notification layer in this reviewer exists at all.
The project itself shows 1858 stars, 408 forks and 59 open issues, with Apache-2.0 as the licence and the last commit on 12 September 2026. The community links are a WeChat group, issues and pull requests, and the maintainer asks for stars and forks rather than money.
Editorial conclusion
This suits a team already on GitLab merge requests that wants a second reader on every diff and is comfortable giving an internal service a personal or project access token. Five things to check first. Whether you can expose the service, because the deployment notes say that if GitLab cannot reach it inside your network you should put it on a public server, and neither the Flask API nor the Streamlit dashboard on port 5002 is described as having authentication. Whether the agentic mode is worth its cost, which the project states plainly: 5k to 50k tokens per review against 3 to 10 times the diff only path, 30 seconds to 5 minutes per review, a peak around 500 MB per session, and 50 GB of disk recommended for cloned repositories. Whether your provider is in the configuration, since the feature list names six providers and the sample environment file names four. Which files get reviewed at all, since SUPPORTED_EXTENSIONS decides that and unlisted types are skipped silently. And whether you want the tone control, since one of the four review styles is deliberately sarcastic.
Frequently asked questions
How does AI-Codereview-Gitlab work?
GitLab triggers a webhook event when someone pushes or opens a merge request, and the webhook calls this service, which sends the diff to a large language model and writes the review back as a note on the merge request or commit. Results can also be pushed to DingTalk, WeCom or Feishu, and a Streamlit dashboard collects the records.
Which AI providers can AI-Codereview-Gitlab use?
The feature list names DeepSeek, ZhipuAI, OpenAI, Anthropic, Qwen and Ollama, and the requirements file pins client libraries for all of them except DeepSeek. The sample environment file, however, comments that only zhipuai, openai, deepseek and ollama are supported, so the configuration example lists fewer providers than the tool can reach.
What does the agentic review mode cost?
It clones the repository locally and gives the model tool calling with a sandboxed shell. The stated overhead is 5k to 50k tokens per review against 3 to 10 times the diff only path, 30 seconds to 5 minutes per review, about 500 MB peak memory per session, and 50 GB of disk recommended, with 10 MB to 2 GB cached per project.
Does the sandboxed shell in agentic mode stay read-only?
By default. Only read class commands are permitted, with ls, cat, grep, find and git log given as examples, and the sandbox adds a blacklist, a path boundary check and a 30 second timeout. The allowlist and blocklist are adjusted through AGENT_SHELL_ALLOWLIST and AGENT_SHELL_BLOCKLIST if you need more. Any failure at clone, fetch, model or tool stage degrades back to diff_only.
How do I deploy AI-Codereview-Gitlab?
Copy conf/.env.dist to conf/.env, set the provider and token, then run docker-compose up -d, which publishes the API on 5001 and the dashboard on 5002. A local Python 3.10 or newer alternative starts the API with python api.py and the dashboard with streamlit run ui.py --server.port=5002 --server.address=0.0.0.0. Then add a webhook at /review/webhook with Push and Merge Request events.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/sunmh207-ai-codereview-gitlab)Star history chart for your README
[](https://hysenlabs.com/projects/sunmh207-ai-codereview-gitlab)Was this useful?