A pgvector workshop structured as git tags instead of a branch
Production-ready MVP for securely chatting with your documents using pgvector
At a glance
- What is it?
- Supabase community material that builds a document chat application in five checkpoints, from object storage through embeddings to chat, each step a separate git tag. It ships as a guided workshop with three sample documents and a local or cloud database path.
- Who is it for?
- This repository is worth your time if you learn by following a build rather than by reading finished code, because the checkpoint structure means you can stop at any step with something that runs and compare against the next tag instead of guessing at a diff.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Activity is slowing. The repository last received commits 6 months ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
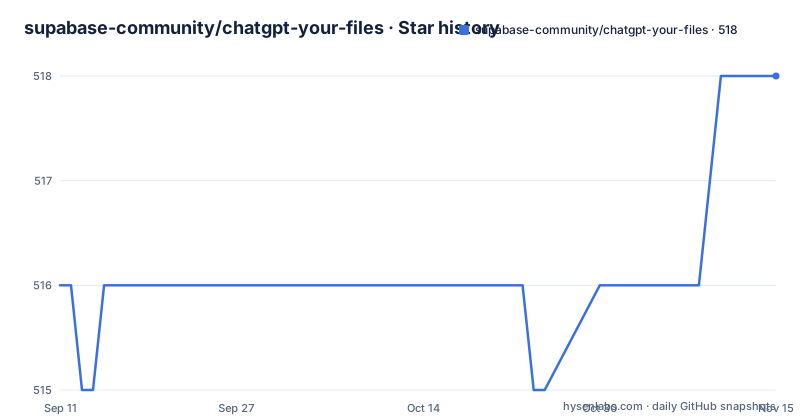
- supabase-community/chatgpt-your-files518 ★ · +2
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| supabase-community/chatgpt-your-files | 516 | 518 |
2 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Every feature is a git tag, and you start inside step one
The organising idea is that the workshop is a sequence of tags rather than a branch you clone and read. Each major feature gets its own tag, so the history is a set of diffs you can step through in either direction.
You do not clone the default branch. The instruction is to clone at the first tag directly:
git clone -b step-1 https://github.com/supabase-community/chatgpt-your-files.gitThat lands you at the storage checkpoint, which is the starting point, with the earlier setup available as step zero if you want it.
Moving between checkpoints is two commands. Stash your working directory so nothing is lost, then check out the tag you want:
git stash push -u # stash your working directory
git checkout step-X # jump to a checkpoint (replace X wit step #)
The five checkpoints are storage, documents, embeddings, chat and a bonus step for database types, followed by the finished state. Three sample markdown files about the Roman Empire ship with the repository and are what the later steps are tested against.
Step zero is an optional scaffold you can skip entirely
The setup step is marked optional and its stated purpose is to save typing rather than to teach anything. It is the equivalent of scaffolding a Next.js app from a Supabase template, and the additions layered on top are editor settings, interface components, styles and layouts.
If you do want it, Supabase is installed as a development dependency at a pinned version and the project is initialised. The optional editor configuration enables the Deno language server with linting, points it at the supabase directory, and gives it an import map path, which is what makes edge function code resolve inside the editor.
The interface layer uses shadcn/ui, initialised with TypeScript, the default style, a slate base colour, CSS variables for colour, and React Server components enabled. Three components are then added, buttons, inputs and toasts, which tells you what the finished application actually needs.
Dependencies installed afterwards are a query client for data fetching and a three-dot typing indicator, which is how the chat interface signals that a response is still arriving.
Storage is Postgres-native object storage, not a separate bucket
The first real checkpoint handles file uploads, and the architectural choice is that Supabase ships object storage backed by S3 that sits directly alongside the Postgres database rather than being bolted on beside it.
Setting up the database has two mutually exclusive paths, and picking one is the first real decision.
The local path runs Supabase inside Docker, which is why Docker is a prerequisite rather than a nicety. Once it is up, the URL and the public anonymous key are pulled out of the CLI's status output and written into the environment file Next.js expects, using override names to rename the keys on the way:
npx supabase status -o env \
  --override-name api.url=NEXT_PUBLIC_SUPABASE_URL \
  --override-name auth.anon_key=NEXT_PUBLIC_SUPABASE_ANON_KEY |
    grep NEXT_PUBLIC > .env.local
The pipe is doing real work: it renames the CLI's keys to the names the frontend expects, filters out the entries the browser should never see, and writes the result.
The cloud path replaces a config file with two CLI commands
The alternative is to run against a hosted project, and the workflow is four steps rather than a config file.
A project is created either through the web console or from the command line, with a name passed inline. Linking the CLI to it needs a project reference, which is not the same identifier as the organisation, and the distinction trips people up: the organisation identifier appears in the URL after selecting an organisation, while the project identifier comes from the project's general settings page.
npx supabase projects create -i "ChatGPT Your Files"
npx supabase link --project-ref=<project-id>
Environment variables are then written by hand rather than extracted, which is the main practical difference between the two paths. In both cases the frontend receives the project URL and the public anonymous key under names prefixed for client exposure.
That anonymous key being public is the point of the next step rather than an oversight: the application talks to the database directly from the browser, and row-level security is what keeps one user's documents invisible to another.
Deno imports are pinned hard while npm packages float
The edge function dependencies are declared in an import map rather than a package manifest, and they are pinned to specific versions from a standard library mirror and a module CDN: the Supabase JavaScript client at 2.21.0, the OpenAI client at 4.10.0, an AI SDK at 2.2.13, a tags utility, and several markdown AST utilities for parsing and re-serialising markdown.
That pinning is the interesting detail, because the package manifest does the opposite. The Supabase JavaScript client and the Next.js framework are both declared as latest rather than as fixed versions, and the CLI is only loosely constrained in development dependencies.
So the same project pins its edge runtime exactly and lets its frontend dependencies float. Anyone picking this up fresh should assume the floating side has moved, and that the pin set is the part which will still reproduce.
Embeddings do not go through a hosted service in the flow described here. A transformers library running in the JavaScript process handles the vector work, which is consistent with the pgvector framing and with keeping document text inside your own database.
The bonus step turns your local database into a TypeScript type
The fifth checkpoint is labelled a bonus, and it is the one most projects skip, which is a mistake for anyone planning to keep this.
A single package script generates types from the running local database and writes them straight into the edge functions library. It asks the Supabase CLI to generate TypeScript types against the local stack and redirects the output into a database types file inside the edge functions library.
Two details in that arrangement carry the value. The local flag means the source of truth is the database you are developing against rather than a hosted project, so the types track your migrations. And the redirect puts the generated file inside the shared library that edge functions import, so the same definitions are available to every function without each one fetching them.
Without this step, calls into the database from edge code are untyped. With it, a renamed column becomes a compile error instead of a runtime failure, and the optional step stops being optional.
A middleware file at the project root handles request interception, and an example environment file documents which variables the frontend needs.
Five steps, eighteen auth providers, and a production claim
The finished application is a chat interface over your own documents using OpenAI models with retrieval augmented generation, plus the plumbing to make it real: document upload and storage, a REST API, login through eighteen third-party providers alongside plain user and password, and row-level security applied to user data.
That list is the actual deliverable, and the row-level security item is the one that decides whether it is a demo or something you could put in front of users. Retrieval on its own is not the hard part; retrieval that cannot leak one user's rows to another is.
The workshop is also recorded as a video, so the written steps and the recorded walkthrough cover the same material.
On the state of the repository: the last push to main is dated 2026-05-12, there are no GitHub releases, and no licence file is identified. The project sits under the Supabase community organisation rather than the Supabase product itself, so treat it as community material with community maintenance rather than as a supported component.
Editorial conclusion
This repository is worth your time if you learn by following a build rather than by reading finished code, because the checkpoint structure means you can stop at any step with something that runs and compare against the next tag instead of guessing at a diff. It suits you less if you want a finished application to deploy, since the value is in the walkthrough rather than the end state, and the scaffold layer carries dated version pins that you would update before trusting in production. Before following along, check that Docker is running, because the local database path depends on it, and treat the row-level security claim as something you verify against your own policies rather than something inherited from the workshop.
Frequently asked questions
How do I move between steps in the ChatGPT Your Files workshop?
Each step is a git tag. Stash your working directory with a stash including untracked files, then check out the tag for the step you want. The clone command itself passes a tag to start at the storage step rather than the default branch.
What do I need installed before following the pgvector workshop?
A Unix-based operating system, or WSL2 on Windows, Docker, and Node.js 18 or newer. Docker matters because the local Supabase stack runs inside it.
How do I get the Supabase keys into the environment file when running locally?
The status command is piped with override names that rename the URL and anonymous key to the names the frontend expects, filtered to keep only client-exposed entries and written into the local environment file.
What is the difference between an organisation ID and a project ID?
The organisation identifier appears in the URL after selecting an organisation. The project identifier comes from the project's general settings page and is what the link command needs for the project reference flag.
Why is the database types step marked as a bonus?
It runs a script that generates typescript types from the local database and writes them into the shared edge functions library, so calls are type safe. Without it, edge code queries the database untyped and a renamed column becomes a runtime failure instead of a compile error.
Where do the embeddings run in this workshop?
A transformers library running inside the JavaScript process handles the vector work, with the vectors stored through pgvector, rather than going through a hosted embedding service.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/supabase-community-chatgpt-your-files)Star history chart for your README
[](https://hysenlabs.com/projects/supabase-community-chatgpt-your-files)Was this useful?