SuperTokens Core: open-core, with a GraalVM plan answering a memory objection
Open source alternative to Auth0 / Firebase Auth / AWS Cognito
At a glance
- What is it?
- The Java service behind the SuperTokens authentication stack, structured as three building blocks so that session verification never reaches the core. It describes itself as an open-core alternative to Auth0 and AWS Cognito, ships an ee/ directory, puts its feature list on a pricing page rather than in the repository, and answers the objection about Java memory usage partly with a plan to adopt GraalVM in the future.
- Who is it for?
- Adopt SuperTokens when you want self-hosted authentication with no user-count limit and full control of your own database, and when you can run a Java service alongside a thin backend SDK. Do not read it as fully open source, because the project calls itself open-core and ships an ee/ directory, so check which capabilities are commercial before committing.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 8 days ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
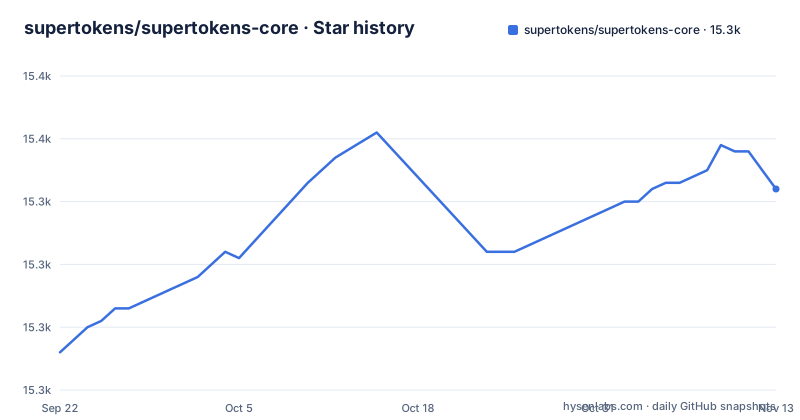
- supertokens/supertokens-core15,342 ★ · +26
| Repository | 2026-09-22 | 2026-11-13 |
|---|---|---|
| supertokens/supertokens-core | 15.3k | 15.3k |
26 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Open-core means there is an ee directory at the root
The What is SuperTokens section opens by describing the project as an open-core alternative to proprietary login providers like Auth0 or AWS Cognito. The phrase is precise and it is the single most important word in the README.
The claim that follows is that SuperTokens can be used for free, forever, with no limits on the number of users, and that an on-premises deployment lets you control 100% of your user data using your own database. Both of those are strong statements, and neither one contradicts the open-core framing.
The repository layout is what settles the question of where the boundary falls. At the top level there is an ee/ directory, sitting beside src/. Enterprise edition code is not something you find buried in a module; it has its own top-level home.
The feature list reinforces the point. Nine capabilities are named: passwordless login, social login, email password login, phone password login, session management, multi-factor authentication, multi-tenancy with organisation support, user roles, and microservice authentication. One of them carries an Enterprise SSO marker inline. And the README does not enumerate which features are in which tier; it tells you to visit the website to see the list of features.
So the practical consequence for an evaluator is that the feature list you can read is not the feature list you can get. One of the nine is visibly marked, the rest are not, and the definitive mapping lives on a pricing page rather than in the repository. GitHub also reports no recognised licence for this repository, and while a LICENSE.md file is present at the root, its terms are not something the repository metadata describes.
You are running a service, and the README says you rarely touch its Java code
The architecture is three building blocks, and the order matters.
The frontend SDK manages session tokens and renders login UI widgets. The backend SDK provides APIs for sign-up, sign-in, signout, session refreshing and the rest, and it is what your frontend talks to. SuperTokens Core is the HTTP service holding the core auth logic and database operations, and it is used by the backend SDK.
So there is a client, a server-side library in your language, and a service in Java. Your application code talks to the backend SDK, not to this repository.
The README makes that explicit in the last of its Why Java points. If you require modifications to the auth APIs, those would need to be done on the backend SDK level, for example Node, Golang or Python, and you would rarely need to directly modify or work with the Java code in this repository.
That is the single most useful operational fact here. A developer adopting this for an unusual requirement should look first at whether the backend SDK can express it, because the answer is usually yes, and forking the Java service should be the last resort rather than the first.
The same reasoning explains why the repository ships scripts rather than a library API. There is a cli/ directory, a downloader/, a jar/ directory, an install script, a Windows install.bat, and a runBuild script. This is a program that gets installed and started, not a dependency added to a build file.
Session verification never reaches the core, and that is the memory argument
The README answers the objection about Java memory usage with three points, and the first is an architectural fact rather than a promise.
The reasoning goes: the most frequent auth-related operation is session verification, and this happens within the backend SDK, in node, python or Go, without contacting the Java core. Therefore a single instance of the core can handle several tens of thousands of users fairly easily.
That is a genuinely different design from a system where every request is verified by the server. If the hot path is a token check your backend SDK does locally, then the Java service handles sign-up, sign-in and the writes, not the reads, and its load is a function of how often users authenticate rather than how often they make authenticated requests.
So the architecture is doing the work here rather than the implementation. The claim is a scaling estimate and not a benchmark; nothing in the repository states what it was measured on. But the shape of the argument is checkable, because you can verify whether your traffic is dominated by sign-ins or by session checks, and that determines whether the estimate is relevant to you.
The second memory point is a dependency choice: an embedded Tomcat server is used instead of a higher-level web framework. That is a smaller stack than a full framework, which is the kind of trade the rest of the Why Java list is making as well.
A future GraalVM plan is the third answer to the memory objection
The third of the three memory points is different in kind from the first two, and it is worth isolating.
The first two are statements about the present. The hot path avoids the core, and the dependency stack was chosen deliberately. The third reads: we also plan on using GraalVM in the future, and this can reduce memory usage by 95%.
Two things about that sentence. It is a plan rather than a shipped feature, so the 95% figure describes something not currently in the artefact you would install. And it is presented as one of three answers to a live objection about the runtime you are about to deploy, which means one third of the answer to that objection is prospective.
There is a fourth Why Java point that is honest in a similar way: the team is most comfortable with Java and hiring great Java developers is relatively easy. That is a statement about the maintainers rather than the technology, and it is the kind of reason that belongs in the list precisely because the other five are technical.
Taken together the six points are a fair summary of the choice. The ones that would affect you as an operator are the memory and dependency arguments. The rest explain why the project exists in Java at all, and the honest answer to that is partly that the team writes Java.
The newest tag is a canary and the newest stable is behind it
The three most recent releases are v12.4.1 on 2026-10-23, v12.4.0 on 2026-10-20, and v12.3.1 on 2026-10-16.
Read that sequence and the shape is clear. A patch, v12.3.1, then a minor, v12.4.0, four days later, and a patch on that minor, v12.4.1, three days after that.
That pace matters here more than it would in a small library, because this is a service that holds a database of users and sessions. Upgrading the core is a database-facing operation, not a dependency bump.
Two supporting details in the repository bear on that. There is a migration_scripts/ directory, which is where schema changes between versions would be expressed, and a CHANGELOG.md at the root. Between them they are the material you want to read before upgrading rather than after something fails.
The last push to the default branch master was on 2026-11-02, ten days after v12.4.1, so development has continued past the newest published build.
Three JSON files at the root declare which interfaces are supported
Three files at the top level are not documentation and not configuration, and their names say what they are:
coreDriverInterfaceSupported.json
pluginInterfaceSupported.json
implementationDependencies.json
A driver interface, a plugin interface, and a set of implementation dependencies. Each is a declaration of what is supported rather than what is implemented, which is the distinction that matters.
Because they are data files, an interface change is something you can find out about from a file.
The database layer is the other place where this matters. Alongside config.yaml and devConfig.yaml there is SCHEMA-REWORK.md, a top-level document whose title says the schema is being reworked. Migration scripts sit beside it. A schema rework in a service that stores user credentials, sessions and metadata is a substantial change, and the presence of a document about it at the root is at least a signal that it is known and tracked.
The practical reading for an adopter is that the storage layer in this project is in a transitional state. Read SCHEMA-REWORK.md and the migration scripts before you upgrade, and do not assume a minor version bump is schema-neutral.
Installing means a script that downloads the JDK, plus a batch file for Windows
The distribution is scripted rather than packaged, and the top-level entries show the pieces.
There is a downloader/ directory, an install script, install.bat for Windows, a jar/ directory and a runBuild script. Alongside them is a cli/ directory and a build.gradle with settings.gradle, so the build system is Gradle.
The Why Java section says the JDK is provided along with the binary or the Docker image, so running SuperTokens is like running any other HTTP microservice.
Building from source is delegated entirely to a wiki page, and the architecture diagram is also a link rather than an image in the repository. What you get from the README is the shape of the system and the reasoning behind it; the mechanical instructions live elsewhere.
That is not an unusual split, but it does mean the repository alone will not get you a running service. The wiki page named Building from source is the place to start, and the CHANGELOG and migration scripts are the place to look before you upgrade whatever it installs.
Least vendor lock-in is the argument, and it is a data-ownership argument
The stated philosophy is worth reading closely because it explains most of the design decisions.
The premise is that authentication directly affects the user experience, the developer experience and the security of an app, and that current solutions cannot optimise for all three at once, which is why many applications hand-roll their own authentication, leading both to security issues and to what the README calls a massive time drain.
The proposed answer is a solution at the right level of abstraction that gives maximum control, is secure and is simple to use, described as being like building it yourself from scratch minus the time to learn, build and maintain.
Then there is the lock-in principle, which is the load-bearing claim. By having full control of your users' data, you can switch away from SuperTokens without forcing existing users to log out, reset their passwords, or in the worst case sign up again.
That is a narrower and more concrete promise than interoperability, and it explains the on-premises deployment story with your own database. It also sets the bar for what would count as violating it: a migration path that requires your users to act.
One supporting design decision sits alongside. Features are meant to be decoupled, so you can use SuperTokens for just login, or just session management, or both, and the project says it also offers session management integrations with other login providers like Auth0. Being able to use the session layer against someone else's login is the clearest expression of that principle, because it is the case where leaving really is easy.
Editorial conclusion
Adopt SuperTokens when you want self-hosted authentication with no user-count limit and full control of your own database, and when you can run a Java service alongside a thin backend SDK. Do not read it as fully open source, because the project calls itself open-core and ships an ee/ directory, so check which capabilities are commercial before committing. Read SCHEMA-REWORK.md and the migration scripts before upgrading, because the storage layer is being reworked.
Frequently asked questions
What is SuperTokens?
An open-core alternative to proprietary login providers such as Auth0 and AWS Cognito, offering passwordless, social, email and phone password login, session management, multi-factor authentication, multi-tenancy and user roles. It can be deployed on-premises against your own database with no limit on the number of users, and SDKs exist for Node.js, Go, Python, React.js, React Native and Vanilla JS.
What are the three building blocks of SuperTokens?
A frontend SDK that manages session tokens and renders login UI widgets, a backend SDK that provides sign-up, sign-in, signout and session refreshing APIs, and SuperTokens Core, the Java HTTP service that holds the core auth logic and database operations and is used by the backend SDK.
Why is SuperTokens Core written in Java?
The stated reasons are that the JDK is distributed with the binary or Docker image, that the Java ecosystem is mature and battle-tested, that a strong type system reduces bugs when many people work on the project, and that the team hires Java developers easily. On memory usage it argues that session verification happens in the backend SDK without contacting the core, that dependencies were chosen carefully including an embedded Tomcat, and that GraalVM is planned for the future.
Is SuperTokens Core fully open source?
The project describes itself as open-core while also listing open source among its differentiators, and the repository contains an ee/ directory for enterprise edition code. GitHub reports no recognised licence while a LICENSE.md file is present at the root, so the terms of the commercial boundary should be read from that file and from the feature list on the project's website.
What is the newest SuperTokens Core release?
The newest release is v12.4.1, published 2026-10-23, after v12.4.0 from 2026-10-20 and v12.3.1 from 2026-10-16. Because the core holds a user and session database, upgrading is a schema-facing operation, and the repository ships migration_scripts/ and a CHANGELOG.md for that purpose.
Official sources
Where this project is recommended
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/supertokens-supertokens-core)Star history chart for your README
[](https://hysenlabs.com/projects/supertokens-supertokens-core)Was this useful?