GhidrAssistMCP serves Ghidra over HTTP, and its download step points elsewhere
An native MCP server extension for Ghidra
At a glance
- What is it?
- GhidrAssistMCP puts an MCP server inside Ghidra, exposing 49 analysis tools, six static resources and seven prompts over SSE or Streamable HTTP. It runs headless inside the analyzeHeadless JVM, shares one server across every CodeBrowser window, and its own installation section links to a releases page belonging to a different account.
- Who is it for?
- This is a serious reverse engineering bridge rather than a demo, and the parts that matter are documented precisely: the transports, the endpoints, the headless invocation and the program locking behaviour. Two things to settle before wiring it into a client.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
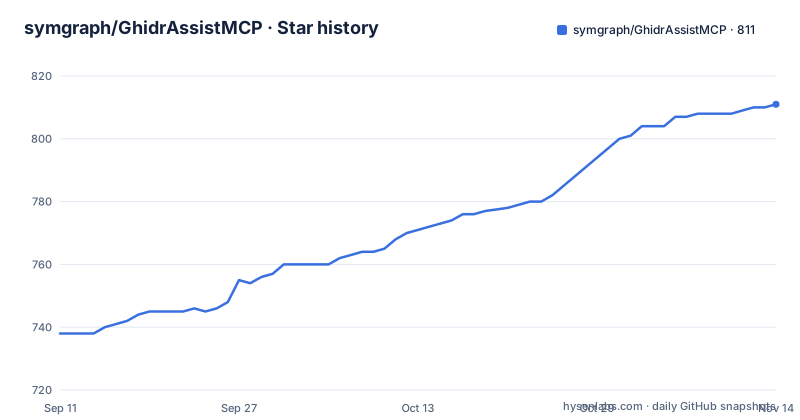
- symgraph/GhidrAssistMCP811 ★ · +73
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| symgraph/GhidrAssistMCP | 738 | 811 |
73 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The download step points at a different account
The recommended installation path starts with a link to the releases page at `github.com/jtang613/GhidrAssistMCP/releases`, and the client project the page recommends is `github.com/jtang613/GhidrAssist`. The repository this page describes is `symgraph/GhidrAssistMCP`, whose default branch is `master` and whose last push is dated 2026-08-03, the same day release 2.11.0 was published. A reader following the page literally ends up on someone else's release list, and nothing on the page explains the relationship between the two accounts.
The clone step has the same gap in a different form. It shows `git clone <repository-url>` and then `cd GhidrAssistMCP`, with the URL left as a placeholder. So the page never states where this repository lives, while three links point somewhere specific.
The example archive name compounds it. The download step asks for the latest `.zip` file and offers `GhidrAssistMCP-v1.0.0.zip` as the example, while the published releases are 2.9.0, 2.10.0 and 2.11.0. Those carry descriptive titles that say more than the number: Auto Analysis, Project Lifecycle and Reliable Multi-Binary Targeting, then Faster Function Lookup and GUI-Consistent Decompilation, then Hardened Headless Automation and Reliable Async Results. Anyone matching filenames against the example will conclude they have the wrong build.
The GUI install is three menu paths and a restart
Installing the packaged extension inside Ghidra takes three steps. Open File, then Install Extensions, then Add Extension; select the downloaded ZIP; restart when prompted. The plugin then has to be switched on separately through File, Configure, Configure Plugins, searching for `GhidrAssistMCP` and ticking the box.
The restart requirement is what makes this more than a copy operation. Ghidra loads extensions at startup, so the ZIP and the enabled flag are two separate states and both have to be right before the plugin appears. The page even anticipates the failure case, telling the reader that if the plugin does not appear, it can be enabled from the same Configure Plugins panel.
Prerequisites are short and specific: Ghidra 11.4 or newer, tested against Ghidra 12.1 Public, plus an MCP client. Nothing states which client versions work, and the client named as an option is the sibling project on the other account, so the compatibility claim on the page is limited to that pair.
A source build writes the extension into two directories
Building from source needs Java 25 or newer, and the page is explicit that the included Gradle wrapper pins the supported Gradle release and should be used instead of a system installation. The install location comes from `GHIDRA_INSTALL_DIR` as an environment variable or from `-PGHIDRA_INSTALL_DIR=<path>` passed to Gradle.
./gradlew installExtensionWhat that task does is worth knowing, because it writes twice. It copies the built ZIP into `[GHIDRA_INSTALL_DIR]/Extensions/Ghidra` and also extracts it into the Ghidra user Extensions folder, replacing any existing extracted copy there. So a source build leaves a packaged archive in the installation tree and an unpacked plugin in the user profile, and the second write silently overwrites whatever was there before. Ghidra must be closed for the task to run, and the user folder can be redirected with `-PGHIDRA_USER_EXTENSIONS_DIR=<path>`.
Two copies in two locations is a reasonable layout, since the install directory copy is what the extension manager sees and the profile copy is what the plugin loader reads, but it also means a stale copy in the profile will survive an upgrade of the archive until the next install replaces it.
The headless recipe mixes a desktop install with container paths
The headless path runs the server inside Ghidra's `analyzeHeadless` launcher, which is what makes MCP access possible without opening the CodeBrowser. The build step is the same install task, then three variables are exported: `GHIDRA_INSTALL_DIR`, `GHIDRA_USER_EXTENSIONS_DIR` pointing under `~/.config/ghidra/<ghidra_profile>/Extensions` on Linux, and `GHIDRASSISTMCP_EXT` pointing at the `GhidrAssistMCP` directory inside it.
A binary is imported with `-import` and the server started as a pre-script; an already imported binary uses `-process` instead. Keeping the session open after analysis needs a post-script with wait mode:
"$GHIDRA_INSTALL_DIR/support/analyzeHeadless" /tmp/ghidra-projects McpHeadless \
  -process binary_name \
  -scriptPath "$GHIDRASSISTMCP_EXT/ghidra_scripts" \
  -postScript GAMCPStartServerScript.java "host=127.0.0.1" "port=8080" "wait=true"
The mechanism detail here is the one that matters for correctness. The server runs in the analyzeHeadless JVM and works on the loaded `currentProgram`, and it holds a program consumer for as long as it runs so incoming MCP requests do not race the program database closing. A harness can also pass `completion_file=/workspace/control/session.complete`, and creating that file shuts the server down cleanly so Ghidra saves and exits normally. That absolute workspace path is the one place the page assumes a container layout rather than the desktop paths used everywhere else.
Two transports, three URLs, and no documented token
Clients are given three addresses: SSE at `http://127.0.0.1:8080/sse`, SSE messages at `http://127.0.0.1:8080/message`, and Streamable HTTP at `http://127.0.0.1:8080/mcp`. Supporting both SSE and Streamable HTTP is the compatibility choice here, since clients disagree about which they speak.
The control panel is reached through Window, then GhidrAssistMCP, or from a toolbar icon, and it exposes three server settings: host, default `localhost`, port, default `8080`, and a toggle to enable or disable the server. That is the entire configuration surface for access.
No token, credential, header or TLS option appears for either transport, on localhost or otherwise. The one restriction the page describes is not about access at all: disposable static analysis labs may pass `tool_profile=agent_lab`, which enables sandbox local program export while arbitrary path import and Ghidra scripts stay disabled, because those can reach outside the sandbox. That paragraph ends mid sentence, so the reason is given without its consequence. The distinction is worth keeping straight, since a tool profile limits what a client can ask for while saying nothing about who can connect.
The reverse engineering surface reachable through a plain HTTP port, with no documented authentication, is the reason this defaults matter more here than for most extensions.
One server is shared across every CodeBrowser window
Multi-window support is the design decision with the most consequences. A single MCP server is shared across all CodeBrowser windows, and the extension tracks which binary window has focus so it knows what the user is looking at. Context hints are then attached to tool responses.
Multi-program support works the same way from the caller's side. Every tool takes a `program_name`, and when two open programs share a filename the `list_binaries` tool returns Project Path values to disambiguate them. That is a reasonable answer to a problem that quietly causes wrong answers, where a tool call lands on the wrong binary because two imports share a name.
Together these mean the server is not scoped to a program. It sits beside several open programs, decides per request which one is meant, and adds a hint about the focused window to every response so the client can notice when the human and the agent are looking at different things. The cost is that program selection is part of the protocol surface rather than part of a session, so a client that omits `program_name` inherits whatever the fallback is, and the README does not say what that fallback is.
Forty-nine tools, seven prompts, six resources, all behind checkboxes
The tool surface is counted rather than described: 49 built-in tools, consolidated by action so that related operations share one entry, 6 static MCP resources covering program info, functions, strings, imports, exports and segments, and 7 prebuilt prompts for common reverse engineering tasks. Long running operations execute asynchronously with task management, and repeated queries are served from a caching layer.
Every tool can be switched off individually from the Configuration tab, and that choice is saved so it persists across sessions, with status visible in real time. There is also real-time logging of MCP requests and responses, which for a debugging session is the difference between tracing a wrong answer and guessing at one.
The combination worth noting is that tool availability is persistent while the server itself is a toggle. Turning the server off stops it; turning tools off changes what a connected client can ask for on the next start. For a shared analysis machine, that is the right order of operations, and it is also why the `agent_lab` profile exists, restricting the tool set rather than the network.
An empty screenshots section and no .github directory
The README has a Screenshots heading with nothing under it, which on a project at 2.11.0 with 49 tools means the interface is described only in prose. There is no image of the control panel, the context hints, the treemap of results or the log view.
The repository root is small and predictable for a Ghidra extension: `Module.manifest` and `extension.properties` as extension metadata, `build.gradle` and `settings.gradle`, a committed `gradlew` and `gradlew.bat` pair, and `src/`, `res/`, `gradle/` and `ghidra_scripts/` directories. That last one holds the Ghidra script sources, including the `GAMCPStartServerScript` class the headless recipe invokes by name.
What is absent is as informative. There is no `.github` directory, so no workflow definitions and no issue or pull request templates, and no `CONTRIBUTING.md` or `SECURITY.md` at the root. The only agent-facing file is `CLAUDE.md`. For an extension that opens an unauthenticated HTTP port into a reverse engineering tool, a published vulnerability reporting path is the missing piece, and the MIT `LICENSE` beside it is the one document that is present.
Editorial conclusion
This is a serious reverse engineering bridge rather than a demo, and the parts that matter are documented precisely: the transports, the endpoints, the headless invocation and the program locking behaviour. Two things to settle before wiring it into a client. Follow the install path yourself rather than the README's links, because the download step points at a different account's releases and the example archive name is from the 1.x line while current releases are 2.9 through 2.11. And decide how the HTTP server will be reachable, since host and port are configurable, no token or TLS option is documented, and the only restriction described is a tool profile for disposable labs. Bind it to loopback, keep it there, and treat any exposure beyond that as a decision you are making rather than one the extension makes for you.
Frequently asked questions
What does GhidrAssistMCP add to Ghidra?
It provides a Model Context Protocol server inside Ghidra, exposing 49 analysis tools consolidated by action, 6 static resources for program info, functions, strings, imports, exports and segments, and 7 prebuilt analysis prompts. It works over both SSE and Streamable HTTP transports.
What does GhidrAssistMCP need before it will run?
Ghidra 11.4 or newer, tested against Ghidra 12.1 Public, and an MCP client. Building from source additionally requires Java 25 or newer and the bundled Gradle wrapper rather than a system Gradle.
How do I run GhidrAssistMCP headlessly?
Install the extension first, then start the server with Ghidra's analyzeHeadless launcher using GAMCPStartServerScript.java as a pre-script, or as a post-script with wait=true to keep the session open after analysis. Clients then connect to /sse, /message or /mcp on port 8080.
Does the GhidrAssistMCP server need authentication?
The control panel exposes a host, default localhost, a port, default 8080, and an enable toggle. No token, credential or TLS option is documented for either transport; the only restriction described is the agent_lab tool profile, which limits tools for disposable labs rather than gating access.
Where can I download GhidrAssistMCP releases from?
The page's download step links to the releases page under the jtang613 account rather than to this repository, and gives GhidrAssistMCP-v1.0.0.zip as the example archive name while the published releases are 2.9.0, 2.10.0 and 2.11.0.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/symgraph-ghidrassistmcp)Star history chart for your README
[](https://hysenlabs.com/projects/symgraph-ghidrassistmcp)Was this useful?