sysstat's Ubuntu package installs the collector disabled, its clone line uses the git protocol, and it has dropped odd and even versioning
Performance monitoring tools for Linux
At a glance
- What is it?
- sysstat/sysstat is Sebastien GODARD's GPL-2.0 collection of Linux performance tools in C, last pushed to master on 2026-10-04 with no GitHub releases at all. The install sections are where the real differences live: the RHEL package enables the collector by default, the Ubuntu one does not, and the source route starts from a git:// clone.
- Who is it for?
- sysstat is the right answer when you need history rather than a snapshot, because sadf can turn a stored day into CSV, XML, JSON or an SVG graph without touching the original data. It is the wrong answer for a single question about one device, which iostat answers directly with no setup at all.
- Can I use it commercially?
- Yes, with conditions. GPL-2.0 is a copyleft licence: if you distribute software that includes it, you must release that software's source code under the same licence. Running it internally without distributing it does not trigger that obligation.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly C, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
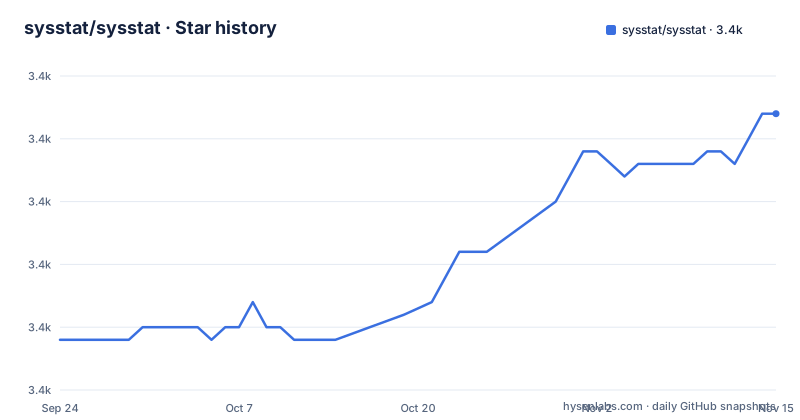
- sysstat/sysstat3,387 ★ · +18
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| sysstat/sysstat | 3.4k | 3.4k |
18 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Ubuntu installs the collector stopped and RHEL installs it running
The two distribution packages behave differently at the moment of installation, and that difference is the most common reason people find sysstat installed but producing nothing.
On RHEL, Fedora and CentOS the package runs one command:
$ sudo yum install sysstatThose systems call the collector process from a cron job in /etc/cron.d, and the README states it is enabled by default. On recent versions systemd is used instead of cron, in which case you may still need to turn it on:
$ sudo systemctl enable --now sysstatand, if your systemd version does not support `--now`, the enable and start pair separately.
On Ubuntu the package installs the same binaries and then asks you a question:
$ sudo apt-get install sysstatfollowed by `sudo dpkg-reconfigure sysstat` and selecting Yes. Without that answer the collector is installed and idle. So on a Debian-family system, verifying data collection is a second step, while on a Red Hat family system verifying it is a confirmation.
That asymmetry is the practical thing to remember, because in both cases the tools themselves are available immediately and will run on demand.
The source route starts from a git:// clone
Building from source begins with one command:
$ git clone git://github.com/sysstat/sysstatThe protocol is `git://`, not `https://`. That was the default transport GitHub once supported, and it is unencrypted and unauthenticated, so a clone over it is both unprotected and dependent on a protocol that other tools have dropped.
Nothing else in the install section is unusual. You move into the directory and run the configure script:
$ cd sysstat
$ ./configure
The README notes you can set variables and parameters on the command line, and gives one that matters, because without it nothing collects data:
$ ./configure --enable-automated-sar-reporting`--enable-automated-sar-reporting` is what wires up the scheduled collection, whether through cron or through systemd. `./configure --help` lists everything else.
The build itself is autotools: `configure`, `configure.ac` and `Makefile.in` are at the root of the tree, with the compiled output going through a generated Makefile. For a Linux system where a package exists, the package route is simpler; the source route exists for the cases where you want a different collection schedule than your distribution ships.
Odd and even version numbers no longer identify development and stable
One paragraph in the README exists purely to retract a convention:
Sysstat no longer uses odd and even version numbers to identify development and stable versions. The latest release should always be considered a stable version that can be used for distribution packaging.
That is worth pausing on, because for a project with decades of history the odd/even scheme was a well-known way to tell at a glance whether a number was something to package or something a developer built themselves. The change removes the signal, and it does so by statement rather than by any change in the tooling.
The replacement for asking which is which is stated in the same file: the latest version can always be found on the project web site at https://sysstat.github.io/, and the CHANGES file records the new features, improvements and bug fixes for each release.
That arrangement has a side effect worth naming. There are no GitHub releases for this repository, so there is no releases page to compare against, no download asset list, and no tag to pin a build to. Version discovery is a website and a text file, and the website is the one the README calls the authoritative source.
A 10 minute default interval, a 1 second floor, and no cap on history
The sampling interval is the setting that determines what sysstat is useful for, and the README gives both ends of the range. The default is 10 minutes. It can be changed, and it can be as small as 1 second.
Those two numbers describe very different systems. At 10 minutes you get a long history of a server whose load pattern is daily, cheap to store and useful for capacity questions. At 1 second you get an event trace, expensive to store, and the README is explicit that the history length has no limit other than the available space on your storage device.
That is the design: sysstat does not cap the history and does not tell you to, it collects into daily files and leaves retention to you. The consequence is that a misconfigured interval is a disk problem that shows up later, not a warning at configuration time.
The default is why the collection front ends exist in the shape they do. `sa1` collects and stores binary data in the system activity daily data file, and is a front end to sadc designed to be run from cron or systemd. `sa2` writes a summarized daily activity report, and is a front end to sar with the same scheduling. Both are templates in the source tree, sa1.in and sa2.in, substituted during configure, so the interval and the paths are build-time choices rather than runtime arguments.
iconfig asks yes or no questions where the answer is case sensitive
There is a second configuration path, and it is the more interesting one.
Instead of running configure with flags, you can run the Interactive Configuration script, `./iconfig`. It asks for the value of the main sysstat variables and parameters, and the README describes three interaction rules.
Pressing Return accepts the default, which it calls sane. Yes or no questions are answered with `y` or `n`, without quotes, and the file insists this is case sensitive. A question mark gives a help message explaining what the question means.
For someone building this for the first time, that is a better interface than reading `--help` output, and for someone scripting a build it is the wrong one. Both paths exist, and the README points at configure's help text as the alternative.
The description of the help message stops mid-sentence in this version of the file, at the point where it explains what the question means, so the extent of that help text is not something the README settles.
One detail to keep in mind when reading any of this: the variables iconfig sets are the same ones configure takes, so a value accepted interactively and a flag passed on the command line are two routes to the same configuration, not two different configurations.
The root is a flat autotools build with PCP-named modules the README never mentions
The top-level listing is unusually flat for a project of this size. The C sources sit directly at the root rather than under a directory: activity.c, cifsiostat.c, common.c, count.c, format.c, ioconf.c, iostat.c, json_stats.c, mpstat.c, pidstat.c, raw_stats.c, rd_sensors.c, rd_stats.c, rndr_stats.c and sa_common.c, each with its matching header where there is one.
So the name of a source file is the name of the command it implements, which is unusual and convenient for reading. The supporting directories are the conventional ones: man/ for the manual pages, nls/ for the translated strings, cron/ for the scheduled collection scripts, build/, contrib/ and images/.
Two entries are not explained anywhere in the README. There are three files named for PCP: pcp_def_metrics.c, pcp_def_metrics.h and pcp_stats.c, plus a header. Performance Co-Pilot is not mentioned once in the file, so whatever integration those modules provide is undocumented here. There is also a `do_test` entry at the root, sitting as a file rather than a directory, with no description of how to run it.
The rest of the root is project furniture: configure, configure.ac and Makefile.in for the build; COPYING, CREDITS, BUG_REPORT, FAQ.md, INSTALL and CHANGES for the paperwork; and three CI configurations, .travis.yml, .lgtm.yml and the .github directory, so the tree carries configuration for two CI services as well as for GitHub.
Five commands report and five more collect, and two of the ten are rarely named
The package is two families of programs, and the split is the first thing to understand.
Five report. `iostat` reports CPU statistics and input/output statistics for block devices and partitions. `mpstat` reports individual or combined processor statistics. `pidstat` reports statistics for Linux tasks, meaning processes, covering I/O, CPU and memory. `tapestat` reports statistics for tape drives. `cifsiostat` reports CIFS statistics.
Five collect and historize. `sar` collects, reports and saves system activity information. `sadc` is the collector underneath it. `sa1` and `sa2` are the schedulable front ends, one to store binary data in the daily file and one to write the summarized daily report. `sadf` is the one that gets data back out, displaying what sar collected in CSV, XML, JSON and other formats, and drawing graphs in SVG.
Of the ten, four are named constantly: iostat, mpstat, pidstat and sar. Two are not: tapestat and cifsiostat, which cover tape drives and CIFS specifically. And the two most useful for retrospective work are the least discussed in most introductions, since sadf is what lets you convert a month of stored binary data into something a spreadsheet or a script can read.
Editorial conclusion
sysstat is the right answer when you need history rather than a snapshot, because sadf can turn a stored day into CSV, XML, JSON or an SVG graph without touching the original data. It is the wrong answer for a single question about one device, which iostat answers directly with no setup at all. Two things to settle before relying on it: confirm the collector is actually running on your distribution, since Debian and Ubuntu install it stopped and RHEL does not, and decide your sampling interval, since the 10 minute default and the 1 second minimum produce data files very different in size and in usefulness.
Frequently asked questions
how to install sysstat
On RHEL, Fedora or CentOS run `sudo yum install sysstat` and the collector is enabled by default, via a cron job in /etc/cron.d or the sysstat systemd service. From source, clone the repository, run ./configure, and add --enable-automated-sar-reporting to switch on scheduled collection.
how to enable sysstat in linux
On recent RHEL-family systems run `sudo systemctl enable --now sysstat`, or enable and start separately if your systemd version does not support --now. Data collection depends on that service, or on the equivalent cron job, actually running.
Why is sysstat not collecting data on Ubuntu?
The Debian-family package installs the collector stopped. Run `sudo dpkg-reconfigure sysstat` and select Yes to enable data collecting. On RHEL, Fedora and CentOS the equivalent job is enabled by default.
What is the default sampling interval in sysstat?
Ten minutes, configurable down to one second. The history length has no upper limit in sysstat itself, so the available space on the storage device is the only bound.
How do I get sysstat data into CSV or a graph?
Use sadf, which displays what sar collected in several formats including CSV, XML and JSON, and can draw graphs in SVG. JSON output is also available for mpstat and iostat, and DTD and XML Schema documents ship with the package.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/sysstat-sysstat)Star history chart for your README
[](https://hysenlabs.com/projects/sysstat-sysstat)Was this useful?