predikit turns a fitted estimator into an LLM tool, and the column names must match
The missing bridge between your ML models and your AI agents. MCP tools use the same Pydantic input validation and model execution as direct invoke() calls.
At a glance
- What is it?
- predikit wraps a trained scikit-learn or XGBoost model as a callable tool with a Pydantic v2 schema, export to OpenAI or LangChain, ensembles, registry loaders and an MCP server. The hard rule is that your schema fields must be named exactly like the training columns, and predikit checks it at runtime.
- Who is it for?
- Adopt predikit if you have fitted estimators that need to become agent tools and you already have your feature column names pinned down, since the name matching it enforces will save you from positional mistakes at inference time. Do not adopt it for a deep learning model or anything outside scikit-learn and XGBoost, and treat the MCP and registry paths as beta until you have read the rest of the docs yourself.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 18 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
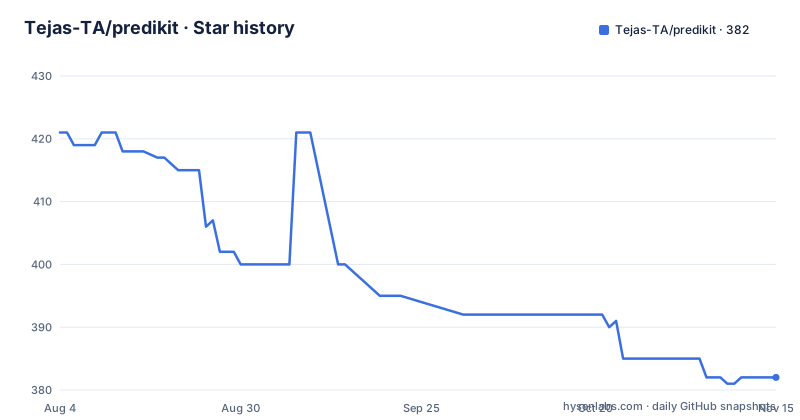
Star history
- Tejas-TA/predikit382 ★ · -39
| Repository | 2026-08-04 | 2026-11-15 |
|---|---|---|
| Tejas-TA/predikit | 421 | 382 |
-39 Stars in the last 103 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The name matching is positional-blind, and it is the whole design
predikit maps inputs to features by name, not by position, and it refuses to guess when they disagree. Your Pydantic schema fields must exactly match the column names the model was trained on. Train on `["sqft", "bedrooms"]` and your fields are `sqft` and `bedrooms`, not `sq_ft` and not `Sqft`.
The failure is loud rather than silent:
class BadInput(BaseModel):
    square_footage: float  # model expects "sqft"
    beds:           float  # model expects "bedrooms"
    baths:          float  # model expects "bathrooms"
The error text names the fields you got wrong, listing missing model features. That is the feature to know before anything else, because it is the one place where predikit refuses to be helpful. Everything else in the library is convenience layered over a fitted estimator, and this is the constraint that makes the convenience safe. Positional mapping would have let a reordered DataFrame silently produce nonsense predictions.
The trade-off is real: renaming columns to match your schema is now your problem. If your pipeline standardises feature names in one place and your schema in another, predikit surfaces that disagreement at the first invoke rather than at training.
Five exports off one ModelTool, and only one of them is a function
The constructor takes a fitted sklearn-compatible estimator plus the metadata an LLM needs to see and the metadata you need to get a typed answer back:
ModelTool(
    model,               # fitted sklearn-compatible estimator
    name: str,           # tool name the LLM sees
    description: str,    # tool description the LLM sees
    input_schema,        # Pydantic BaseModel describing inputs
    output_name: str,    # key for the prediction in the returned dict
    output_description: str,
)
From that one object you get five ways out. `.invoke(input_dict)` validates, predicts, and returns a dict keyed by `output_name`. `.ainvoke(input_dict)` is the async version, which is how a synchronous estimator avoids blocking an agent's event loop. `.to_openai()` returns an OpenAI function-calling schema, `.to_langchain()` returns a LangChain `StructuredTool`, and `.to_callable()` returns a plain Python function.
The short example at the top of the README shows the shape of the answer, where the output key is yours to choose rather than a fixed `prediction`:
tool = ModelTool(model=clf, name="classify_iris", ...)
tool.to_openai()              # OpenAI function schema, ready to pass to the API
tool.invoke({"sqft": 2200})   # → {"price_usd": 370730}
Ensemble strategies differ on how much they demand from you
`ModelEnsemble` runs several tools and reconciles them, and the reconciliation is where the design decisions live. It takes the tool list, a name, a description, a `strategy` string, and an optional `weights` list.
The five strategies are not interchangeable. `"collect"` merges every output into one dict and lets tools carry different `output_name` values, so it is the only one that tolerates heterogeneous models. `"mean"` averages numeric outputs and requires all tools to share `output_name`. `"vote"` takes a majority class and carries the same requirement. `"weighted_mean"` and `"weighted_vote"` need a `weights` list to go with them.
So the strategy you pick determines how carefully you have to harmonise your schemas first. A voting ensemble of two classifiers and one regressor is not expressible here, because vote requires a shared key and mean requires numeric outputs. The error surfaces when the ensemble runs rather than when it is constructed.
The upside is that `ModelEnsemble` exposes the same `.invoke()`, `.ainvoke()`, `.to_openai()` and `.to_langchain()` interface as `ModelTool`, so an agent cannot tell an ensemble from a single model at the tool boundary.
Extras decide what your agent can talk to
The base install is three dependencies: `pydantic>=2.0`, `scikit-learn>=1.2` and `numpy>=1.24`, on Python 3.10 or newer. Everything else is an extra, which is the right shape for a library that only needs Pydantic to do its main job.
pip install predikit

# Optional extras
pip install predikit[xgboost]    # XGBoost support
pip install predikit[langchain]  # LangChain StructuredTool export
pip install predikit[mlflow]     # MLflow Model Registry loader
pip install predikit[snowflake]  # Snowflake Model Registry loader
pip install predikit[cli]        # `predikit inspect` and `predikit serve`
pip install predikit[mcp,cli]    # serve a registry over MCP
The declared extras are `xgboost` for `xgboost>=1.7`, `langchain` for `langchain-core>=0.1`, `mcp` for `mcp>=1.28,<2`, `mlflow` for `mlflow>=2.0`, `snowflake` for `snowflake-ml-python>=1.0`, and `cli` for `click>=8.0` and `joblib>=1.2`. You can combine them in one specifier, and the README gives `pip install predikit[mcp,cli]` as the route to serving a registry over MCP.
Two details are worth noting. `mcp` is the only extra with an upper bound, pinned below 2, which suggests the MCP API is the one moving fastest. And `joblib` arrives with `cli` rather than with the base package, so model loading for the registry server is part of that surface.
Registries are loaders, and the shipped examples walk the whole range
There is no registry abstraction of predikit's own. Instead there are two loaders, `from_mlflow()` and `from_snowflake()`, and they need their respective extras installed. Both live behind the optional dependencies rather than in the base install, which keeps the core small and puts the cost of MLops integration on the project that already has MLops.
The `examples/` directory is numbered, which makes it a usable tour of the feature surface rather than a scatter of scripts. `01_basic_sklearn.py` and `02_xgboost_regression.py` cover the two supported estimator families and both regression and classification. `03_orlando_real_estate.py` is the price-prediction scenario the README's own example uses. `04_confidence_routing.py` covers the `confidence_threshold` and `on_low_confidence` pair, which is how the library answers the question of what to do when the model is unsure. `05_multi_model_ensemble.py` covers `ModelEnsemble`. `06_mlflow_loader.py` and `07_snowflake_loader.py` close out the registry routes.
Seven files, each mapped to one feature, means a new user can read the two they need rather than the whole package. It also means the library is small enough that the examples are close to a specification.
ToolRegistry is for bulk export, and confidence handling is separate
Two features are easy to conflate and worth separating. `ToolRegistry` exists purely for grouping:
registry = ToolRegistry([price_tool, risk_tool])
registry.to_openai()     # → list[dict], pass directly to OpenAI
registry.to_langchain()  # → list[StructuredTool]
registry.get("name")     # → ModelTool
It converts a list of `ModelTool` objects into a list the agent framework accepts directly, and it lets you fetch one back by name. It adds no behaviour of its own, no routing and no validation beyond what the individual tools already do.
Confidence handling is the separate mechanism, and it lives on the individual tool rather than in the registry. `confidence_threshold` plus `on_low_confidence` is what you use instead of writing your own threshold checks per project. Whether that fires a different template, refuses to answer, or routes to a human depends on what you pass as the callback, which the README does not spell out beyond naming the pair. Naming the output key `price_usd` instead of `result` matters as much: the key is what appears in the agent's transcript, and the agent reasons over it.
That matters for how you compose things. A registry full of low-confidence predictions still returns numbers unless each tool carries a threshold, so setting confidence policy per tool is the part worth doing deliberately rather than assuming the registry inherits it.
Beta status, no docs past the field naming rule, and a fast release line
The packaging tells you where the project sits. The version is 0.6.3, the licence is MIT, and the classifier is `Development Status :: 4 - Beta` rather than stable. Python classifiers run 3.10 through 3.13, with a `Typing :: Typed` marker.
Release cadence is quick. v0.6.3 shipped on 2026-09-17, v0.6.2 on 2026-08-22 and v0.6.1 on 2026-08-15, so three releases inside five weeks, and the last push to the default branch matches the newest tag. The author field names a single maintainer, Tejas Tumakuru Ashok.
The gap is the documentation, and it is worth being precise about where it stops. The table of contents promises a cookbook section, a command line section, an MCP server section and a roadmap section, and the published README cuts off partway through the error output for the field naming rule. So `predikit inspect` and `predikit serve` are named in an install comment but their flags and output are not in the text available here, and the MCP server contract is undocumented beyond the fact that the extra exists.
At beta with a moving MCP dependency and truncated docs, the sensible first step is the two-file path in `examples/`, not the MCP server.
Editorial conclusion
Adopt predikit if you have fitted estimators that need to become agent tools and you already have your feature column names pinned down, since the name matching it enforces will save you from positional mistakes at inference time. Do not adopt it for a deep learning model or anything outside scikit-learn and XGBoost, and treat the MCP and registry paths as beta until you have read the rest of the docs yourself. Verify first that your Pydantic schema field names equal your training column names, because a mismatch raises at invoke time rather than at install time.
Frequently asked questions
What does predikit do?
It wraps a fitted scikit-learn or XGBoost model as an LLM-callable tool. One `ModelTool` object exports to an OpenAI function schema, a LangChain `StructuredTool` or a plain Python function, with inputs validated by a Pydantic v2 model.
Why does predikit raise an error about missing model features?
predikit maps inputs to features by name rather than by position, so your Pydantic schema fields must exactly match the training column names. A mismatch raises a ValueError naming the fields that do not match.
Which model types can predikit wrap?
scikit-learn and XGBoost estimators, with XGBoost behind the `xgboost` extra. The base install depends on `pydantic>=2.0`, `scikit-learn>=1.2` and `numpy>=1.24`, and Python 3.10 or newer is required.
How do I load a model from MLflow or Snowflake with predikit?
Use the `from_mlflow()` or `from_snowflake()` loaders, which need the `mlflow` or `snowflake` extra installed respectively. The README's table of contents also promises a cookbook, a command line section and an MCP server section that are not present in the published text.
What do the predikit ensemble strategies require?
`"collect"` merges all outputs and lets tools differ, while `"mean"`, `"vote"`, `"weighted_mean"` and `"weighted_vote"` require all tools to share an `output_name`. The two weighted strategies additionally need a `weights` list.
How does predikit handle low confidence predictions?
Through a `confidence_threshold` and an `on_low_confidence` pair set on the individual tool, rather than through a registry-level policy. `ToolRegistry` only groups tools for bulk export and does not set confidence behaviour.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tejas-ta-predikit)Star history chart for your README
[](https://hysenlabs.com/projects/tejas-ta-predikit)Was this useful?