WCDB's build steps live in a wiki, and five languages spell the same query five ways
WCDB is a cross-platform database framework developed by WeChat.
At a glance
- What is it?
- WCDB is the SQLite and SQLCipher based database framework WeChat uses, wrapped in an ORM and a query layer called WINQ across C++, Java, Kotlin, Swift and Objective-C. Its code is well organised around one shared implementation, but the repository itself documents almost nothing: every build step is a wiki link, several features are asserted without specification, and encryption and migration details are left entirely elsewhere.
- Who is it for?
- WCDB suits a team that already has a wiki-driven build process and writes in more than one of its five languages, because the shared implementation and the cross-language error monitoring are real advantages over a bare SQLite wrapper.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 37 days ago.
- What is it written in?
- Mainly C, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
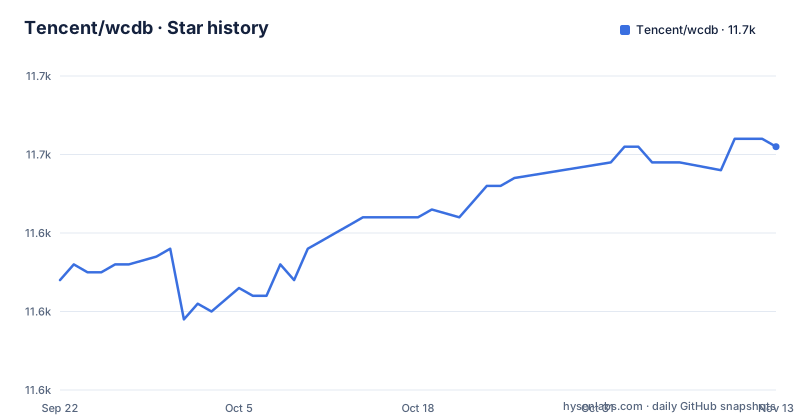
Star history
- Tencent/wcdb11,651 ★ · +17
| Repository | 2026-09-22 | 2026-11-13 |
|---|---|---|
| Tencent/wcdb | 11.6k | 11.7k |
17 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Every build step is a link out, and the README holds no command
Every build instruction in this repository is a link. The Build and Install section points at four wiki pages, one per language binding: WCDB C++, WCDB Java/Kotlin, WCDB Swift, and WCDB Objc. A parallel Tutorials section points at four more. Nothing in the README is a command line, a dependency list, a minimum compiler version, or a package name to add to a build file.
What the tree does carry is packaging metadata for several ecosystems at once: Package.swift and a .swift-version file for Swift Package Manager, and four podspec files named WCDB.podspec, WCDB.cpp.podspec, WCDB.objc.podspec and WCDB.swift.podspec for CocoaPods. A VERSION file and a CHANGELOG.md sit beside them.
The consequence for an adopter is that the first real hour of work happens outside version control. Four documents means four places to look, and a change to a build recipe lands in the wiki rather than next to the code it describes, so it is not covered by a review of the source tree. A reader who wants a reproducible setup has to copy the wiki page into their own notes on day one, because nothing in the repository pins it or tells you which of the four pages is current for a given release.
WINQ removes SQL string building, and the model is welded to the class
The central claim is that a query never has to be assembled as a string. Two pieces deliver that: an ORM for creating tables, indices and constraints along with CRUD over objects, and WINQ, described as a language integrated query capability that frees developers from writing glue code to concatenate SQL query strings. The same four operations then fit on one line, in C++:
// C++
database.insertObjects<Sample>(Sample(1, "text"), myTable);
database.updateRow("text2", WCDB_FIELD(Sample::content), myTable, WCDB_FIELD(Sample::id) == 1);
auto objects = database.getAllObjects<Sample>(myTable, WCDB_FIELD(Sample::id) > 0);
database.deleteObjects(myTable, WCDB_FIELD(Sample::id) == 1);
and in Swift, where the same four calls carry labels and `try`:
// Swift
try database.insert(Sample(id:1, content:"text"), intoTable: myTable)
try database.update(table: myTable,
                    on: Sample.Properties.content,
                    with: "text2"
                    where:Sample.Properties.id == 1)
let objects: [Sample] = try database.getObjects(fromTable: myTable,
                                                where: Sample.Properties.id > 0)
try database.delete(fromTable: myTable where: Sample.Properties.id == 1)
A built-in protection from SQL injection is listed as a feature of the same layer. Note what the binding costs. The database model is bound to the class definition, so that the addition, deletion and modification of database fields are consistent with the definition of class variables. A column therefore becomes a compile-time concern rather than a runtime one, and the class definition is where a schema change starts. The README does not describe what happens to rows already stored when a field is removed.
Java, Kotlin and Objective-C repeat the same four calls under different names
The naming is not stable across bindings, which matters as soon as a team spans two of them. Java uses insertObject, updateValue, getAllObjects and deleteObjects with a chained field accessor such as DBSample.id.eq(1):
// Java
database.insertObject(new Sample(1, "text"), DBSample.allFields(), myTable);
database.updateValue("text2", DBSample.content, myTable, DBSample.id.eq(1));
List<Sample> objects = database.getAllObjects(DBSample.allFields(), myTable, DBSample.id.gt(0));
database.deleteObjects(myTable, DBSample.id.eq(1));
Objective-C renames the same four operations and passes the class rather than a field list:
// Objc
[database insertObject:sample intoTable:myTable];
[database updateTable:myTable
          setProperty:Sample.content
              toValue:@"text2"
                where:Sample.id == 1];
NSArray* objects = [database getObjectsOfClass:Sample.class
                                     fromTable:myTable
                                         where:Sample.id > 0];
[database deleteFromTable:myTable where:Sample.id == 1];
Kotlin repeats the Java shape with the type arguments written out and no semicolons. Underneath, the project states that interfaces in different languages share the same underlying logic, so WCDB in different languages has the same interface structure and interface capabilities. The consequence for a mixed codebase is that the concept transfers but the spelling does not. Porting a query between bindings means translating names rather than translating behaviour, and global interfaces such as error monitoring can work on database logic in different languages at the same time, so one monitoring hook can cover code written in all of them.
Encryption is SQLCipher's work, and no key handling is described anywhere
Database encryption is not implemented by WCDB. It is supported via SQLCipher, and the project's opening description places it on both SQLite and SQLCipher rather than on a storage engine of its own. The top level lists sqlcipher, openssl and zstd entries and a .gitmodules file, but the README does not say how they are fetched or built.
The consequence for a reader is a decision that cannot be deferred. Encryption is a property of the database file, so a store that begins unencrypted does not become encrypted by enabling an option later, and the README documents no key management, no key rotation, and no path for opening an existing plaintext database in an encrypted one. For a mobile framework, which is the stated context, that means the key has to be designed into the app before the first row exists rather than bolted on after launch. The wiki links in the README cover building and installing each language binding, not key handling, so the security design has to come from somewhere other than this repository. Treat the encryption support line as a statement that an encrypted store is possible, not as a description of how it is keyed.
Zstd compression is scoped per field and rewrites rows you already wrote
Compression is scoped to chosen columns rather than to the whole file. Content can be compressed via Zstd within specific fields of a database table through a simple configuration, and once configured the details of compression and decompression become transparent to developers. The claim that reaches past a toggle is that WCDB can automatically compress existing data, which makes enabling the feature a write operation over rows that are already stored.
The consequence for a reader is that a configuration change is a data migration in disguise. Large text or blob columns that were cheap to write become expensive to rewrite,. Two details are left open in the README: how a caller distinguishes a compressed column from an uncompressed one at read time, and what happens to rows written by an older build once the option is on. The field level rewrite is the operation to plan for. The built-in repair kit for corruption recovery belongs to the same feature list, and it is better understood as the fallback for an interrupted write than as the plan for enabling compression on a populated table. Sequence the change deliberately, on a release where a long write is acceptable.
Data migration is designed to hide its own status and progress
Data migration is the feature described with the most deliberate omission. WCDB supports migrating data from one database to another with simple configuration, and developers do not need to care about the intermediate status and progress of the migration. There is no resumable transfer, no progress callback and no cancel path in that description.
For a mobile app that is a defensible default, because a schema bump during startup does not need a progress bar. The consequence is that the migration becomes something you watch rather than something you observe. The documented API gives you no intermediate state and no progress, so you cannot attach to a run, cannot report it in a settings screen, and cannot tell a stalled run from a slow one while it happens.
Two features in the same list sharpen the problem. Corruption recovery relies on a built-in repair kit, and full-text search relies on tokenizers. Neither is described as reporting progress either, so an upgrade path has to be timed and judged from outside the process: measure it on a real device with a real database before you promise anything about startup time.
Full-text search promises tokenizers for several languages and names none of them
Full-text search is offered as an easy-to-use interface that includes tokenizers for multiple languages, and that sentence is the entire claim. No language is named, no tokenizer identifier is given, and no configuration surface appears in the README. The sample code in the repository is insert, update, query and delete only, so a reader cannot tell from the top level whether a particular language is covered by a shipped tokenizer or whether one has to be supplied.
The consequence is an unknown on the critical path: search decides how indexes are designed, so confirm tokenizer coverage for your language before you model text storage around search.
Four podspecs and a deprecated/ directory decide which WCDB you depend on
The root carries packaging for several distribution channels at once, and one entry is explicitly historical. Top-level files include WCDB.podspec, WCDB.cpp.podspec, WCDB.objc.podspec and WCDB.swift.podspec for CocoaPods, Package.swift with a .swift-version file for Swift Package Manager, and a directory named deprecated. Four podspecs for one project mean four dependency identities, and the README does not say which one a given language binding is meant to use or whether the four are kept in step with each other.
The consequence is version drift inside your own manifest. A Swift app pinning the CocoaPods pod and a colleague on the same project using Package.swift can resolve to different WCDB releases without either being wrong, because nothing states that the podspec versions and the SPM manifest move together. VERSION and CHANGELOG.md sit at the root, but their contents are not described in the README.
For a framework whose default branch master was last pushed on 2026-10-08 and whose most recent listed releases are v2.1.16, v2.1.15 and v2.1.14, those two files are the first place to look before assuming two builds contain the same code.
Editorial conclusion
WCDB suits a team that already has a wiki-driven build process and writes in more than one of its five languages, because the shared implementation and the cross-language error monitoring are real advantages over a bare SQLite wrapper. It suits a team less well that expects the repository to be self-explanatory, and it is a poor choice if you cannot decide the SQLCipher key before the first row is written, since the README documents no key management and no way to encrypt later. Before adopting it, read the four build wiki pages for your language, confirm your full-text search language has a tokenizer, and decide whether enabling field compression on existing rows is acceptable to your release schedule.
Frequently asked questions
Is WCDB developed by a company in Shenzhen?
WCDB is developed by Tencent: the developer listed in the repository is 深圳市腾讯计算机系统有限公司, and the framework is described as being used in the WeChat application. Contributions run through the Tencent OpenSource Plan, and the project has joined the TDS Tencent end service product alliance.
Is WeChat owned by Tencent, and does that explain WCDB?
WCDB is described as a cross-platform database framework developed by WeChat and used in the WeChat application, so production use inside WeChat is the stated origin. The repository names 深圳市腾讯计算机系统有限公司 as the developer and links contributors to the Tencent OpenSource Plan.
Does the WCDB README contain build commands?
No. The Build and Install section links to four wiki pages, one each for C++, Java/Kotlin, Swift and Objc, and the Tutorials section links to four more. The README itself contains no build command, dependency list or minimum toolchain version.
Which languages can WCDB be called from?
Five: C++, Java, Kotlin, Swift and Objective-C. Interfaces in different languages share the same underlying logic, and there is a separate build and install wiki page and tutorial page for each binding, plus podspec files for WCDB, WCDB.cpp, WCDB.objc and WCDB.swift.
How does WCDB encrypt a database?
Encryption comes from SQLCipher rather than from WCDB code: the project is based on SQLite and SQLCipher and supports database encryption via SQLCipher, with sqlcipher, openssl and zstd listed as top-level entries. No key management or key rotation is described in the README.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tencent-wcdb)Star history chart for your README
[](https://hysenlabs.com/projects/tencent-wcdb)Was this useful?