CubeSandbox: one kernel per agent sandbox, and the S3 rule for resuming elsewhere
Instant, Concurrent, Secure & Lightweight Sandbox for AI Agents.
At a glance
- What is it?
- Tencent's Go control plane over RustVMM and KVM gives every agent sandbox a dedicated MicroVM kernel, with snapshot cloning behind the sub-60ms start claim. Cross-node resume, Kubernetes deployment, eBPF isolation and the credential vault each pull a separate piece of infrastructure along with them.
- Who is it for?
- Adopt CubeSandbox when your agents need a real OS kernel per sandbox and you can run KVM nodes, and add an S3 backend before you care about cross-node resume. Skip it when process-level isolation is enough, or when your machines are macOS laptops, since the project is built on KVM.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
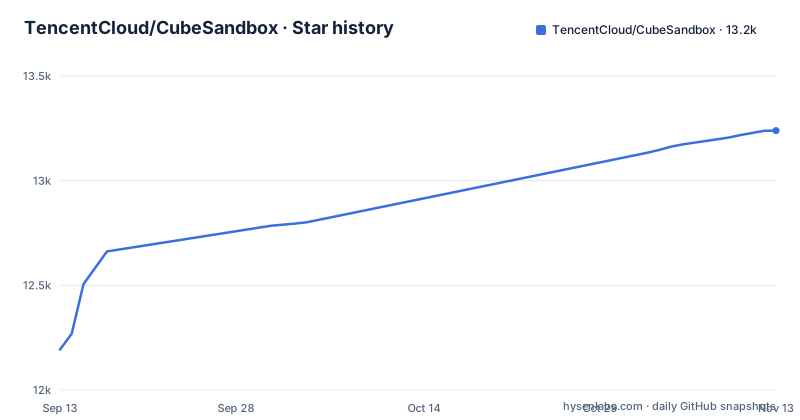
- TencentCloud/CubeSandbox13,239 ★ · +1,046
| Repository | 2026-09-13 | 2026-11-13 |
|---|---|---|
| TencentCloud/CubeSandbox | 12.2k | 13.2k |
1,046 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
A kernel per sandbox, and CoW paying for the density
CubeSandbox runs a dedicated OS kernel inside a MicroVM for every sandbox, and the density number it publishes, under 5MB of overhead per sandbox, holds only because of what stays outside that kernel. Sandboxes come from a pool of pre-allocated resources and from snapshots, which is why the README can claim an average cold start under 60ms, and the CubeCoW copy-on-write engine is what makes thousands of instances per server possible on one box. The README credits that density to kernel sharing and Copy-on-Write (CoW), and separately lists eBPF-based inter-sandbox isolation and egress filtering at kernel level.
S3 is the difference between resuming anywhere and resuming nearby
v0.3.0 brought the CubeCoW engine for event-level snapshots, instant cloning and rollback to any saved state. v0.7 stretched it: with an S3 backend you can suspend a sandbox on one node and resume it on another, and create sandboxes from snapshots, which the release table marks as preview. The dependency is written into that sentence, and it decides where your state sits. Without S3 configured, what CubeCoW writes stays on the node holding it, and cross-node resume has nothing to read. CubeS3lvol sits at the top level of the repository, so the object-store path is a shipped component rather than a stub. Treat the endpoint as part of the sandbox lifecycle, not as a backup target: if the store is unreachable, a paused sandbox is a paused sandbox.
The guest kernel is a separate build job from the service
The README points at ./docs/guide/quickstart.md for the fast path and ./docs/index.md for the rest, and a Python client is published on PyPI as cubesandbox. Building from the repository is a longer job, because the guest image is compiled inside a container. These are the Makefile defaults used to launch that builder, and it runs as your host user so bind-mounted output stays writable:
BUILDER_IMAGE ?= cube-sandbox-builder:ubuntu2004
BUILDER_DOCKERFILE ?= docker/Dockerfile.builder
BUILDER_CMD ?= bash
The guest kernel is its own target, and it needs a Linux source tree that you supply:
make kernel KERNEL_SRC=/path/to/linuxThat target compiles a vmlinux from the in-tree config at configs/kernel-oc9.<arch>.config inside the builder image, and the Makefile maps a host arm64 to aarch64 for the cross build. Binaries and release artifacts land under the paths below rather than anywhere on your PATH:
OUTPUT_DIR ?= $(ROOT_DIR)/_output/bin
RELEASE_DIR ?= $(ROOT_DIR)/_output/release
Consequence for a reader: building the guest kernel from a fresh clone waits on a Linux source tree you supply via KERNEL_SRC; the release list also carries separate kernel releases such as kernel-release-261012-1.
The E2B switch is one variable, and the README never names it
Compatibility is the adoption argument here: the project states it matches the E2B SDK interface, and that moving off E2B Cloud means changing one environment variable with no client code changes. The README's highlight does not name that variable, so check the docs before writing migration code. Coverage is the larger unknown. E2B is a hosted API with a wide surface, and neither the README nor the news table says which of its calls CubeSandbox implements, so that list cannot be read off the repository landing page. The examples directory is better evidence: examples/e2b-dev-sidecar/ covers the client contract, examples/run-code-env-inheritance/ covers variables passed into a sandbox, and examples/code-sandbox-quickstart/ is the shortest path in. Treat the switch as a contract test rather than a config edit. It proves the happy path on day one and says nothing about the calls your agent makes at three in the morning.
Egress is enforced twice, in the kernel and again in user space
Network control runs at two layers that you configure separately. At kernel level the project uses eBPF for inter-sandbox isolation and egress filtering, and v0.5 added per-sandbox traffic tokens and policy-routing egress. Above that sits an L7 security proxy enforcing per-domain, per-path and per-method policies, shipped as CubeProxy with a guide at ./docs/guide/security-proxy.md, with CubeEgress alongside it. The credential vault from v0.4 is what puts the proxy in the request path: agents call external APIs as usual while the keys never enter the sandbox. That takes a whole category of secret handling out of the VM. It also makes the proxy part of ordinary agent work instead of an optional guard, so a policy written too tightly breaks a tool call rather than stopping an attack. Two enforcement points means two things to get right, and the README does not describe how a rejection from the proxy surfaces in the agent's own output.
The eBPF tests need a privileged runner, not a normal CI container
The Makefile defaults the builder container to the host user so bind-mounted output stays writable, and its comment names the exceptions. Privileged test targets, cubevs-test among them, load eBPF and mount bpffs, so they override BUILDER_USER to 0:0 and add --privileged. That target is not optional coverage. eBPF is the mechanism the project names for both inter-sandbox isolation and egress filtering, so the test that loads those hooks is the closest thing available to a check on the isolation claim. Consequence: the isolation path cannot be exercised in an unprivileged container, and it cannot run on a hosted CI runner that refuses privileged mode. Since the project describes the filtering as working at kernel level, a node also has to permit eBPF loading at all. If your pipeline has no privileged runner class, this code reaches real hardware untested, and you learn about a broken hook from an incident instead of from a build.
v0.7 split operations out, so there are two control surfaces
v0.7 moved node management out of the main control plane and into CubeOps, with multi-replica deployment and a new cubeopscli, which means control and operations are now two things you run. CubeMaster, CubeAPI and the cube-lifecycle-manager remain in the tree beside it, so the repository holds both surfaces. The cost line for an adopter is concrete: two CLIs, two config sets, two upgrade steps, and the headline cross-node resume feature listed as preview in the same release. On cadence, the last push was on 2026-11-02 and v0.7.3 shipped on 2026-10-12, the same day as the v0.7.3-rc2 candidate and a separate kernel-release-261012-1 release. A release candidate that close to the tag is ordinary; a 0.x line with its headline feature in preview is not. The v0.4 dashboard exists partly to show whether templates need rebuilding after upgrades. One thing to settle before depending on it: the repository licence field reads NOASSERTION while the Makefile header carries SPDX-License-Identifier: Apache-2.0 and `Copyright (C) 2026 Tencent. All rights reserved.` Read ./LICENSE yourself before you ship on top of it.
Editorial conclusion
Adopt CubeSandbox when your agents need a real OS kernel per sandbox and you can run KVM nodes, and add an S3 backend before you care about cross-node resume. Skip it when process-level isolation is enough, or when your machines are macOS laptops, since the project is built on KVM. First move: run one node through ./docs/guide/quickstart.md and check which of the E2B calls your client makes are actually implemented, because the README does not say.
Frequently asked questions
What is an AI sandbox environment?
In CubeSandbox it is a MicroVM with its own OS kernel, created from a template through the E2B-compatible API. The project states an average cold start under 60ms and under 5MB of overhead per sandbox, and pools resources so sandboxes come from a clone rather than a cold boot.
Does CubeSandbox run on macOS, or does it need Linux hosts?
The project is built on RustVMM and KVM, and its Makefile maps a host arm64 architecture to aarch64 when building the guest kernel, so the targets it describes are Linux architectures. The visible README gives no macOS host path for compute nodes; it points to ./docs/guide/quickstart.md, a Kubernetes deploy guide and a Terraform deploy guide.
What does it take to resume a CubeSandbox sandbox on a different node?
An S3 backend. The v0.7 release notes state that with an S3 backend you can suspend a sandbox on one node and resume it on another, or create sandboxes from snapshots, which is marked preview. Without S3, state written by CubeCoW stays on the node that holds it.
How do I point an E2B client at CubeSandbox?
By changing one environment variable, according to the README, which claims compatibility with the E2B SDK interface and zero client code changes. The README's highlight does not name the variable, so the quickstart and examples/e2b-dev-sidecar/ are the references to read first.
How current is CubeSandbox?
The last push was on 2026-11-02, and v0.7.3 was tagged on 2026-10-12, the same day as the v0.7.3-rc2 candidate. The repository is not archived, and the version line is still 0.x with cross-node pause and resume shipped as a preview feature.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tencentcloud-cubesandbox)Star history chart for your README
[](https://hysenlabs.com/projects/tencentcloud-cubesandbox)Was this useful?