weread-omni renamed its command away from weread, then shipped a skill still called weread
An enhancement toolkit for WeRead (WeChat Reading) integrating an Agent, SDK and CLI with 40 built-in operations. Beyond the official features, it adds support for reading WeChat official account articles and fully unlocks bookshelf note read/write, book import and AI permissions.
At a glance
- What is it?
- An unofficial TypeScript SDK, CLI and agent skill for WeChat Reading, offering forty operations against the official skill's six read-only ones. The honesty about cached and partial content is better than the packaging hygiene.
- Who is it for?
- weread-omni is worth using if you want an agent to read and write your own WeChat Reading data, and the parts that make it credible are the negative results: readable never claims to be complete, a cache hit reports itself as a cache hit, and a captcha is recorded rather than circumvented. Two things to settle first.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 61 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
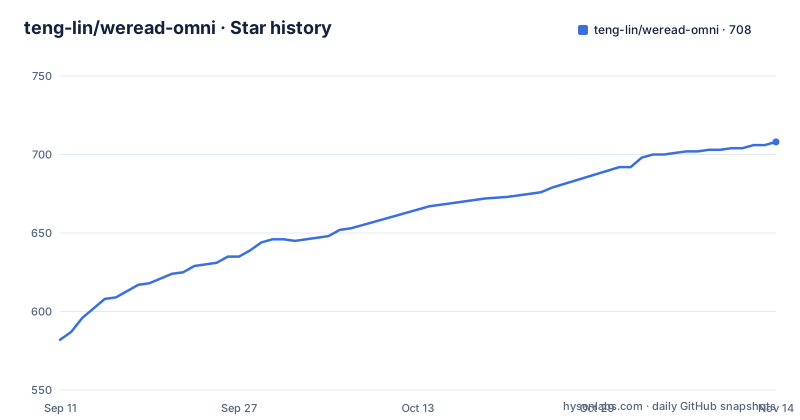
- teng-lin/weread-omni708 ★ · +126
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| teng-lin/weread-omni | 582 | 708 |
126 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
0.1.0 shipped a command called weread, and 0.1.1 shipped a skill called weread
The CLI was renamed once and the rename is documented in the quick start. Version `0.1.0` installed a command named `weread`, which collided with the official skill's command of the same name. From `0.1.1` onward the command is `weread-omni`.
Two caveats come with that. Upgrading does not remove the old `weread` binary, so anyone who installed `0.1.0` has to reinstall once to clear it. And a name collision that was serious enough to rename a command for turned out not to be serious enough to rename the skill, because the install command is:
npm install --global weread-omni
weread-omni login --json
weread-omni doctor --json
weread-omni search books "三体" --json
while the skill is installed as `npx skills add teng-lin/weread-omni --skill weread`. The skill is still called `weread`.
So a host that loads both this skill and the official one has two things called `weread` in its configuration again, in a different namespace this time but under the same name.
The skill itself is careful about scope. It tells an agent how to check login state, how to call the JSON CLI, how to page correctly, and to confirm with you before write operations. It explicitly does not install the `weread-omni` command, so the install and login steps have to happen first.
Forty operations against six, and four of the five gaps are writes
The official Agent Skill opened in May 2026 with an API key and six capabilities: browse your shelf, search books, reading statistics, book details, highlights and annotations, and book recommendations. All six are read-only.
The comparison table then lists what weread-omni does that the official one does not. Four rows, and it is worth being precise about them. Adding, editing and deleting your own highlights and reviews. Importing EPUB, PDF, MOBI, TXT and AZW3 files. Public accounts and their articles. And the service's own AI features.
Three of those four are writes against an account you own. That is the difference between the two projects in one sentence, and it is also the risk: read operations that fail are an inconvenience, and write operations that fail leave state behind.
The project states its status plainly in the second paragraph: it is unofficial, has no affiliation with Tencent or WeRead, and has neither their endorsement nor their support.
That sentence matters more here than it would elsewhere, because the whole surface is built on private e-ink API endpoints rather than a documented interface. The README says it was developed against the WeRead e-ink APIs, and the built-in client plugin is named `eink`.
readable does not mean complete, and a cache hit says so in the payload
Reading a public account article is the command an agent is most prone to misuse, and it is the one with the most careful output contract.
The `status` field takes three values. `readable` means a readable body was obtained and nothing more, and the payload carries `completeness: unverified` to say so explicitly. `partial` marks a paywalled preview. `unavailable` means it could not be read, and then the exit code is 1, the error goes to stderr as JSON, and `article.diagnostics` explains what happened.
The stated rule is that a summary is never passed off as the body. The project would rather fail loudly than hand a model a plausible-looking paraphrase of an article it could only read the abstract of.
Caching is reported the same way. A `fromCache` field says whether a local copy was used, and on a cache hit the payload returns `cachedAt` with `fetchedAt` set to null. The stated reason is that it does not pretend to have just fetched it. `--refresh` refetches and updates the copy, and `--no-library` skips the cache entirely for one invocation.
Two related commands carry an explicit warning in the other direction. `resolve-article` only parses the article identifier, and `review single` returns details; neither guarantees body text, and an agent that treats them as readers will get an empty result.
The library is plaintext, never pruned, and lives in a different root from your credentials
The CLI keeps a local copy of book metadata, tables of contents and downloaded public-account articles, and re-reads from it instead of fetching again.
Three things about that store are worth knowing. It is plaintext. It contains no login information, but the documentation says to treat it as sensitive data anyway. And it is never cleaned up: the same file is stored once, content is indexed per account, and old content is not removed automatically.
That last point turns into a growing directory rather than a bug. There is a `library status` command to count what is in there and a `library verify` to check the database against saved files, but no command to prune it.
The store is backed by SQLite in WAL mode. If the filesystem does not support WAL, the CLI warns and carries on, but stops using the library. There is an environment variable, `WEREAD_LIBRARY_ALLOW_UNSAFE=1`, that skips that check, offered for the case where you know only one process is writing.
The separation of roots is deliberate and explained. Credentials and account profiles live under `~/.config/weread/accounts/<alias>/` with the directory at mode 0700 and the files at 0600. The content library lives under a data directory, defaulting to `~/.local/share/weread/library` when `XDG_DATA_HOME` is unset. The stated reason for keeping them apart is that the content store grows without bound and holds book text rather than secrets.
The client layer is loaded from paths at startup, and the tarball ships the docs directory
The transport layer is pluggable at runtime rather than at build time. An environment variable takes a semicolon-separated list of ESM package names, `file:` URLs or absolute paths, and each module must default-export a client plugin descriptor compatible with plugin API version 1. The CLI loads that list at startup.
The built-in client is named `eink`, login creates the account on it with a QR scan, and a `--client <id>` flag selects another loaded provider. The package exports a `./plugin` entry point alongside the root and the CLI, so a plugin can be written in TypeScript against the same types as everything else.
That is a genuinely open design, and it is also an execution path that accepts arbitrary paths from an environment variable. Worth knowing before you run it somewhere with a populated `WEREAD_PLUGINS`.
The packaging is where the looseness shows. The published file list includes `dist`, `skills`, the two readmes, the changelog, the security policy and the licence, and it also includes `docs`, with two negations: `docs/plans` is excluded and `docs/api-design-review-*.md` is excluded.
So internal design review notes are kept out of the tarball while everything else under `docs/` is published. It is a narrow exclusion list where a broad one would have been simpler.
The publish configuration is better. Access is public and provenance is enabled, so the published artefact carries an attestation linking it to the build.
Captchas are recorded, not circumvented, and exports refuse to overwrite
The public-account feed and export commands have the clearest safety boundaries in the project.
Article bodies are downloaded only from validated HTTPS addresses on the article host. When the command meets a JavaScript verification step or a captcha, it records the situation in its diagnostics and does not attempt to work around it. Given that this is an unofficial client scraping content, that line is worth stating plainly.
Feeds default to 20 articles with a maximum of 100 via `--limit`, and the commands do not overwrite existing files or directories. Those two constraints together mean an export either produces a new path or fails, which is the right default for something writing into a directory you also keep other things in.
There is a feed format worth noting, since the package description advertises RSS, Atom and JSON: the documented examples use `--format json` for a single account and `--format rss` for the whole subscription list, written to an XML file.
Subscription itself needs an identifier you have verified first, in the form of a prefix followed by digits, and the documented way to get it is a search restricted with `--scope 2` rather than guessing at the identifier.
The import path has one explicit limit: a single file defaults to 200 MiB, adjustable with an environment variable, across the five formats.
Review stars accept 20, 40, 60, 80 or 100, and shelf state defaults to on
Two small details in the write commands cause more friction for an agent than anything else in the tool.
The first is the review rating. It accepts exactly five values: 20, 40, 60, 80 and 100, mapping to one through five stars. There is no zero, no half star, and no way to express three and a half.
The second is the polarity of the shelf flags. `shelf pin`, `shelf set-private`, `shelf mark-finished` and `shelf mark-reading` all set their state by default, so a plain invocation makes a book pinned, private, finished or marked as reading. Cancelling requires passing `--no-top`, `--no-secret`, `--no-finished` or `--no-reading` respectively.
A script that runs the bare command twice will not be idempotent in the way most people expect, because the default is the affirmative. That is a defensible choice for a human at a prompt and an annoying one for an agent looping over a shelf.
The rest of the command surface is mostly reads. `shelf sync` pages through a condensed view and returns the raw response with `--full`. `book chapters` returns the chapter identifier that every later highlight command needs, so a caller has to make that call first. `whoami` shows the account identifier, the device identifier and where the credentials came from, and no tokens.
928 forks against 645 stars, and no issues at all
The repository's shape is unusual in a way worth naming.
There are around 645 stars and 928 forks, so the fork count exceeds the star count. That ratio is the signature of a repository people copy rather than one they watch, which fits a tool whose main artefact is an agent skill plus a CLI that other agents invoke.
Open issues: zero. On a project with this much adoption and a documented unofficial-API surface, a zero issue count does not mean a clean project. It means the conversation is happening somewhere other than the tracker, and the README points at a changelog, a security policy and an endpoint list as the places to look.
Those three documents are worth your attention before anything else. An endpoint inventory is what tells you how much surface is in front of you, a changelog spanning a project still at version `0.1.2` tells you how fast it moves, and a security policy tells you what they consider worth reporting.
The version history is short: `0.1.1` on 2026-08-03 and `0.1.2` on 2026-09-14, roughly six weeks apart, with `0.1.0` before that. The last push to the default branch is 2026-09-14.
The repository root holds twenty-two entries, including two agent instruction files, a biome configuration, two TypeScript configurations with a separate one for tests, and a test directory that is named in the singular.
Editorial conclusion
weread-omni is worth using if you want an agent to read and write your own WeChat Reading data, and the parts that make it credible are the negative results: readable never claims to be complete, a cache hit reports itself as a cache hit, and a captcha is recorded rather than circumvented. Two things to settle first. This is an unofficial client against a service with no public API, so check the service terms for the account you would use, and expect endpoints to move. And read the credential handling for yourself: the tool stores a persistent per-account identifier and a plaintext local library that it never prunes.
Frequently asked questions
How do I install and log in to weread-omni?
Install it globally with npm, which needs Node.js 22.13 or newer, then run weread-omni login to scan a QR code with a WeChat account that has WeRead enabled. weread-omni doctor checks the install and login state and issues one read-only request to confirm the connection.
What can weread-omni do that the official WeRead skill cannot?
Four things: adding, editing and deleting your own highlights and reviews; importing EPUB, PDF, MOBI, TXT and AAZW3 files; reading public accounts and their articles; and using the service's AI features. The official skill exposes six read-only capabilities, all of which this project also covers.
Does weread-omni store my WeRead password or tokens?
No. The login output contains only the account alias, the client identifier, the vid and a device identifier, with no tokens, and whoami reports the same fields plus where the credentials came from. Credentials live under the config directory with 0700 and 0600 permissions.
Is the weread-omni local content library safe to keep?
It stores reading content in plaintext with no login information, but the documentation says to treat it as sensitive data. It is indexed per account, the same file is stored only once, and old content is never removed automatically. It needs a filesystem that supports SQLite WAL, with an environment override for the check.
What happens when weread-omni hits a captcha reading a public account article?
It records the situation in the article diagnostics and does not attempt to bypass it. Bodies are only downloaded from validated HTTPS article addresses, and a failure exits with code 1 and a JSON error on stderr rather than returning a summary in place of the body.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/teng-lin-weread-omni)Star history chart for your README
[](https://hysenlabs.com/projects/teng-lin-weread-omni)Was this useful?