TensorFlow Probability: distributions, bijectors and inference inside the TensorFlow graph
Probabilistic reasoning and statistical analysis in TensorFlow
At a glance
- What is it?
- TensorFlow Probability wraps a large distribution catalog, bijector transforms and MCMC and variational inference in TensorFlow tensors, with a JAX substrate behind the same API. The layer stack is well factored, but the boundary of what lives in the repository has moved and the release cadence lags the commits.
- Who is it for?
- Adopt TensorFlow Probability when the model must be differentiable end to end inside an existing TensorFlow training loop and you want inference to share those gradients. Do not adopt it for a pure posterior sampler, a quick conjugate analysis, or a team that needs a stable API contract.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 6 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
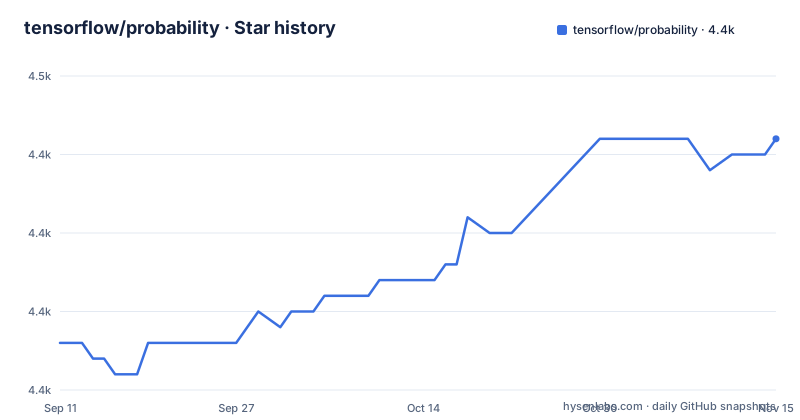
Star history
- tensorflow/probability4,446 ★ · +13
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| tensorflow/probability | 4.4k | 4.4k |
13 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Layer 0 left the repository and now lives in tf.linalg
The layering is the clearest thing about this project, and the clearest detail is the one that moved. The README describes four layers. Layer 0 is TensorFlow itself, and specifically the LinearOperator class that lets a matrix be expressed by structure such as diagonal or low-rank instead of materialized. That class is written and maintained by the TensorFlow Probability team, and it now lives in tf.linalg in core TensorFlow.
So the numerical foundation of Layer 0 is no longer in this repository. What remains is layers 1 through 3. Layer 1 holds distributions in tfp.distributions and bijectors in tfp.bijectors. Layer 2 holds model building: joint distributions and probabilistic layers. Layer 3 holds inference: tfp.mcmc, tfp.vi, tfp.optimizer and tfp.monte_carlo. The top-level entries match that division, with tensorflow_probability/python split into distributions, bijectors, mcmc, vi, optimizer, monte_carlo and layers directories.
That structure matters for a decision, because it tells you where your code will break. A change in how LinearOperator applies a matrix operation is a TensorFlow problem now, versioned with TensorFlow, not something you can pin inside a TFP requirements file.
Bijectors: reversible transforms that turn one distribution into a family
A bijector is a reversible, composable transformation of a random variable. Compose one with a distribution and you get a transformed distribution, which is how this library covers shapes that have no closed-form sampler of their own. The README runs the range from the log-normal distribution, which is a plain exponential bijector applied to a normal, to masked autoregressive flows, which chain many bijectors whose parameters come from a network.
The payoff is that a flow is a single object with sample, log_prob and gradient semantics, so an inference algorithm can treat it as one distribution. The cost is that every transform has an inverse, and the inverse is the part people forget.
Distribution objects in tfp.distributions carry batch and broadcasting semantics, so shapes propagate through these compositions under NumPy broadcasting rules. That is the whole point of the layer, and also the first thing to get wrong when you move from a scalar parameter to a per-example one.
Samples, batches and events: the shape contract that decides your bug
One notebook in the examples directory is dedicated to a single question, how to tell samples, batches and events apart, and the repository ships Understanding_TensorFlow_Distributions_Shapes.ipynb rather than burying the answer in prose. For arbitrary probabilistic computation this distinction is the contract. A distribution reports a sample shape, a batch shape and an event shape, and methods like log_prob reduce over some of them while leaving others.
Read that notebook before your first model. Nearly every confusing result in this library comes from a shape mismatch between what you meant and what the distribution inferred.
The examples directory also carries Gaussian Copula, Probabilistic Principal Components Analysis and a Bayesian Gaussian Mixture Model notebook, three cases where the event and batch structure is doing real modelling work rather than bookkeeping.
JointDistributionSequential describes the model before you sample it
Layer 2 is where a model stops being a pile of independent distributions. JointDistributionSequential builds a joint distribution over one or more interdependent distributions, declared in order, and the joint interface is what MCMC and variational inference consume.
The design point worth noting is that the model description and the inference code are separate objects. The README also lists a notebook comparing hierarchical linear models among TensorFlow Probability, R and Stan. If your team knows Stan, that notebook is the most direct answer to whether the library is a fit.
Probabilistic layers, in tfp.layers, carry the same idea into Keras: neural network layers with uncertainty over the functions they represent, extending TensorFlow Layers. That is the bridge for people who want a Bayesian layer inside an existing network rather than a separate inference script.
MCMC samples, variational inference optimizes, and the two live side by side
Layer 3 splits by computational method rather than by model. tfp.mcmc holds algorithms for approximating integrals via sampling, including Hamiltonian Monte Carlo and random-walk Metropolis-Hastings, plus the ability to build custom transition kernels. tfp.vi holds algorithms that approximate the same integrals via optimization instead. tfp.monte_carlo computes Monte Carlo expectations, and tfp.optimizer extends TensorFlow optimizers with stochastic methods such as Stochastic Gradient Langevin Dynamics.
Putting both mcmc and vi in the same namespace is the useful part. HMC gives you posterior samples with correct geometry when the model is small and you have time; variational inference gives you an approximate posterior as a trained object when the model is a deep network. Custom transition kernels mean a nonstandard geometry is a code contribution rather than a library request.
The failure mode is familiar and worth naming: variational inference returns an approximation with no built-in check on how wrong it is, and a well-mixed HMC chain over the same model will disagree with it. Treating the VI optimum as the answer is how a wrong posterior ships quietly.
Same API over JAX through the substrates namespace
Installation goes through the Python package index, and setup.py names the released distribution tensorflow-probability while the nightly build publishes under the separate name tfp-nightly, which also swaps tensorflow-datasets for tfds-nightly. The same file requires tensorflow >= 2.16 and tf-keras >= 2.16, so a TensorFlow older than that will not resolve.
The first use of the library is the import itself. You pick a substrate, and the same namespaces exist behind it:
from tensorflow_probability.substrates import jax as tfpThat line switches the whole stack to pure JAX while leaving tfp.distributions, tfp.bijectors and tfp.mcmc names unchanged, which is why a research codebase can prototype on JAX and keep a TensorFlow serving path. Substrates are documented separately in SUBSTRATES.md at the repository root, alongside pip_pkg.sh for packaging and BUILD and WORKSPACE for the Bazel build. The README also warns that interfaces may change at any time, which is the line to read twice if you pin a version.
Version churn in the commits without a matching release
Apache-2.0 covers the code and the notebooks, so reuse in commercial work is a matter of keeping the notice and checking the license text rather than a separate negotiation.
What deserves attention is the gap between the code and the packaging. The last release tag is v0.25.0 from 2024-11-08, yet the last push landed on 2026-10-27. Recent work is landing on main without being cut into a tagged release, so what you get from the index is close to two years behind the branch.
That matters most for the substrate work and for anything touching a TensorFlow upgrade, where the fix you need is the part left unreleased. Pin an explicit version and read the diff against main when a dependency forces an upgrade.
Editorial conclusion
Adopt TensorFlow Probability when the model must be differentiable end to end inside an existing TensorFlow training loop and you want inference to share those gradients. Do not adopt it for a pure posterior sampler, a quick conjugate analysis, or a team that needs a stable API contract. Before writing the first model, check that tfp.distributions, tfp.bijectors and tfp.mcmc expose the pieces you need on the exact TensorFlow version your runtime pins, because setup.py requires tensorflow >= 2.16 and the README states interfaces may change at any time.
Frequently asked questions
What is TensorFlow Probability used for?
It is a library for probabilistic reasoning and statistical analysis in TensorFlow, providing integration of probabilistic methods with deep networks, gradient-based inference via automatic differentiation, and scalability to large datasets via hardware acceleration and distributed computation.
Can TensorFlow Probability run on JAX?
Yes. The library also works as Tensor-friendly Probability in pure JAX, by importing the JAX substrate: from tensorflow_probability.substrates import jax as tfp. The same tfp namespaces are then available.
What version of TensorFlow does TensorFlow Probability require?
setup.py requires tensorflow >= 2.16 along with tf-keras >= 2.16 for the released package. Nightly builds publish under the name tfp-nightly instead.
What is the difference between tfp.mcmc and tfp.vi?
tfp.mcmc approximates integrals by sampling, including Hamiltonian Monte Carlo, random-walk Metropolis-Hastings and custom transition kernels, while tfp.vi approximates them by optimization. tfp.monte_carlo computes Monte Carlo expectations separately.
How do I build a model with interdependent distributions in TensorFlow Probability?
Use JointDistributionSequential, which builds a joint distribution over one or more interdependent distributions declared in order. For an introduction, the README points to the Modeling_with_JointDistribution.ipynb notebook under tensorflow_probability/examples/jupyter_notebooks.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tensorflow-probability)Star history chart for your README
[](https://hysenlabs.com/projects/tensorflow-probability)Was this useful?