libpcap: no releases, the version is a file, and Linux filters in user space
the LIBpcap interface to various kernel packet capture mechanism
At a glance
- What is it?
- libpcap is the portable C library nearly everything that sniffs packets is built on, and it has been in continuous use since a national laboratory handed it over in the early nineties. Its readme is short and unusually frank about one thing: on the platform where in-kernel filtering would matter most, the library does not use it, and the translation that would fix that is named as an ideal and then declared unimplemented.
- Who is it for?
- libpcap suits anyone writing a capture tool and expecting it to work on more than one operating system, because the entire reason the library exists is that vendors disagree about how to expose capture, and twenty-odd platform modules are the accumulated evidence of that.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 4 days ago.
- What is it written in?
- Mainly C, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
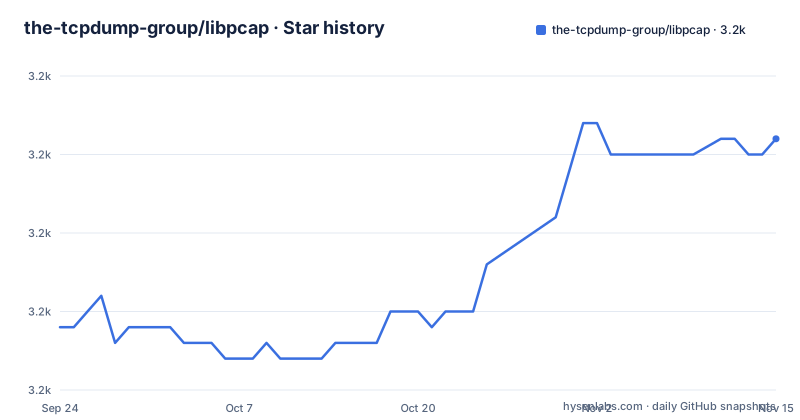
- the-tcpdump-group/libpcap3,186 ★ · +12
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| the-tcpdump-group/libpcap | 3.2k | 3.2k |
12 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Linux gets user-space filtering and the page admits the fix is not implemented
The readme's most useful paragraph is an admission. It says that although most packet capture interfaces support some in-kernel filtering, libpcap uses in-kernel filtering only for the interfaces that support BPF programs, naming three of them. In every other case it reads every packet into user space and evaluates the filter program there, which incurs added overhead, and the parenthetical is the sharp end of it: especially for selective filters. A selective filter is exactly the case where you would want the kernel to drop packets for you, and that is the case the library handles worst. The page then names the fix and says it is not done: ideally libpcap would translate BPF filters into a program compatible with the underlying kernel subsystem. So the architecture is known, the cost is documented, and the implementation is absent.
The shared library name has no minor or patch component in it
There is a section addressed to packagers, and it is a rule rather than a request. The soname of the shared library is set to libpcap.so.1. That is what it should be, and the page writes in capitals that it is not libpcap.so.1.x, not libpcap.so.1.x.y, and not something such as that. The reason follows: binary compatibility has been maintained between releases for a long time, and there is no reason to tie a binary linked against libpcap to a particular release of libpcap. So the soname is deliberately coarser than the version, which means the running library can be patched underneath a linked program indefinitely. It also means a packaging rule that appends the minor version out of habit breaks the contract, and the page knows it.
There are no releases and the version lives in a file
The hosting site lists no releases at all for this repository, and the readme's first line is a placeholder: the library, version one point something point something. The version is not resolved anywhere on the page, and the repository contains a file named VERSION at its top level alongside a changelog and a credits file, both with no extension. Releases for this library have therefore never been expressed through the forge the mirror sits on, which fits the rest of the readme: it names the forge's clone URL under the heading of anonymous Git, presents it as one option among the ways in rather than as the project's home, and gives the project website as the homepage. For a consumer pinning a dependency, the practical consequence is that the version has to be read out of the tree rather than looked up, and the changelog in the tree is the release history.
Three build systems and three build scripts share one directory
Look at the top of the tree and you find an autotools setup, a CMake setup and a set of shell scripts. For autotools there is a configure input, a macro file, a makefile input, the two configuration probes every autotools project carries, and a directory of missing helpers, which is the standard way of shipping scripts that autoconf expects but cannot find on the user's machine. For CMake there is the top-level file, a directory, an uninstall template and a hand-written configuration header, the last being a pattern from before CMake learned to generate configuration headers itself. Then there are three shell scripts, one of them named for a build matrix and one named for a Coverity static-analysis build, which together with a Windows CI configuration in the tree implies a fairly wide matrix of configurations tested on every change.
A directory and a file differ only by the case of their name
Two entries at the top of the tree are a directory and a file whose names differ only in the case of their first character: one capitalised, one not. On a case-sensitive filesystem they are separate entries with different meanings. On a case-insensitive one, which is the default on macOS and Windows and common on developer laptops mounted from elsewhere, they are the same path, so a checkout that contains both cannot be represented. For a project whose whole purpose is to work everywhere, that is a small irony, and it is the kind of artefact that survives because most contributors use the operating system where it happens to work. The same pattern of accumulated history shows in the interface decoders, which are still present as individual files at the root under prefixes for three different legacy network families, alongside a header for parsing wireless frames and a bison grammar from which the filter code generator is built.
The canonical home is not the forge and anonymous Git is the alternative
The readme gives a security contact, a contribution guide, and then a clone URL, under the heading of anonymous Git. That heading is the tell. The repository the readme describes is developed somewhere other than the forge, the forge copy is where you push when you do not have an account, and the project's own website is what the metadata points at as the homepage. This explains several other observations at once. There are no releases, because releases are cut wherever the canonical history lives. The documentation lives in a directory in the tree rather than on a separate site, with one readme file per operating system by convention, and the security contact is an address at the project's own domain rather than a security advisory process on the forge.
The provenance block still points at an FTP path for version 0.4a7
Near the top of the readme there is a plain-text block, and it is the oldest thing on the page. It says the code was formerly from a national laboratory's network research group, gives an electronic mail address at that laboratory's domain, and ends with a file transfer protocol URL pointing at a compressed archive named for version 0.4a7. That is the era when capture libraries were distributed as compressed tapes by mail or by bulletin board, and the page still prints the address. Read as history it explains the whole project: a portable capture layer extracted from tools that needed one, because vendors each exposed something different, and the interest in keeping binary compatibility measured in decades rather than releases. The archive itself is almost certainly gone, since that host has not served files in years, and nobody has edited the block out. The whole block is four lines:
formerly from	Lawrence Berkeley National Laboratory
		Network Research Group <[email protected]>
		ftp://ftp.ee.lbl.gov/old/libpcap-0.4a7.tar.Z
Three formats are offered for one paper from 1993
The filtering mechanism is credited to a paper from a winter USENIX conference in 1993, and the readme links it three times over: once as compressed PostScript, once as gzipped PostScript, and once as a PDF. Three formats for one document is not vanity; PostScript was how typesetting worked when the paper appeared, the compressed variant was how you mailed it, and the PDF is how you read it now, so the three links are a compressed timeline of how a technical paper travelled before the web settled on one format. The paper's title is given in full in the text, and the page describes the architecture as the basis of the filter interface, which is the sentence to point at if you want to know why the filter language looks the way it does.
Editorial conclusion
libpcap suits anyone writing a capture tool and expecting it to work on more than one operating system, because the entire reason the library exists is that vendors disagree about how to expose capture, and twenty-odd platform modules are the accumulated evidence of that. It is a poor fit if you are filtering a high-rate link on Linux and hoped the filter would run in the kernel, because on that platform every packet is read into user space and matched there, and the page says the fix is not implemented. Before you build on it, read the shared-library naming rule in the readme rather than assuming a conventional soname, because this project does not use one, and check the platform notes in the documentation directory for the system you actually target.
Frequently asked questions
What is libpcap used for?
It is a system-independent interface for user-level packet capture, providing a portable framework for low-level network monitoring. The readme names network statistics collection, security monitoring and network debugging as the applications, and gives the reason it exists: almost every system vendor provides a different interface for packet capture, so a single API removes the need for system-dependent capture modules in each application.
how to use libpcap
The readme does not contain usage code. It describes the filtering mechanism, which comes from the BSD packet filter architecture described in a 1993 conference paper, links that paper in three formats, and points at a documentation directory holding one readme file per operating system by convention. The clone URL it gives is under the heading of anonymous Git.
How do I install libpcap?
The readme contains no install commands. It points at an install document, a contribution guide and a documentation directory of per-operating-system files, and the repository carries an autotools setup, a CMake setup and three shell build scripts including one named for a build matrix. The version is not resolved on the page; it is a placeholder, with the real number in a file at the top of the tree.
Why does libpcap read every packet on Linux?
Because in-kernel filtering is used only on the interfaces that support BPF programs, and Linux's own mechanisms are the extended BPF ones, which the readme says are not supported. Everywhere else it reads every packet into user space and evaluates the filter there, at added overhead and especially for selective filters. The readme names the fix as translating filters into the kernel's own language and states that it is not implemented.
How do I install libpcap on Windows?
The page does not address Windows capture. It names a convention of one readme file per operating system and points at a Linux-specific one, and the list of systems where the filter architecture is standard is all Unix systems plus an older undocumented variant on one other Unix. The repository does carry a configuration file for a Windows build service.
Why is the libpcap shared library named .so.1 and not .so.1.x?
It is a stated rule for distributions. The soname is set to libpcap.so.1 with no minor or patch component, because binary compatibility has been maintained between releases for a long time and nothing should tie a linked binary to a particular release. The readme writes in capitals that it is not the longer form.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/the-tcpdump-group-libpcap)Star history chart for your README
[](https://hysenlabs.com/projects/the-tcpdump-group-libpcap)Was this useful?