agent-router renamed the product and nothing else, and its Go module path still points at the old organisation
Manages Unified Access to Generative AI Services built on Envoy Gateway
At a glance
- What is it?
- Agent Router is a Go control plane for model and tool traffic, built on Envoy Gateway and now an Agentic AI Foundation project after being renamed from Envoy AI Gateway. The page is explicit that nothing a machine reads was renamed, and the repository confirms it: the module path, the container namespace, the command name, the API group and the custom resource kinds all still carry the old name, and the module path no longer matches the repository that holds it.
- Who is it for?
- Agent Router fits a platform team that already runs Envoy Gateway and wants one OpenAI-compatible surface across hosted and self-hosted models, and it fits a team that wants a small local proxy less well, since the one command route downloads a data plane binary. Before adopting it, check four things.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 21, 2026, and from our analysis. They are not legal advice.
Star history
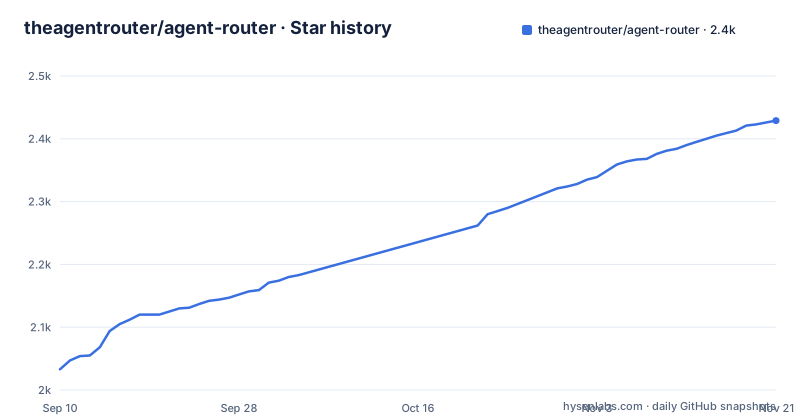
- theagentrouter/agent-router2,429 ★ · +396
| Repository | 2026-09-10 | 2026-11-21 |
|---|---|---|
| theagentrouter/agent-router | 2k | 2.4k |
396 Stars in the last 72 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The repository moved, the Go module path did not, and a redirect holds them together
The project was renamed and moved from one organisation to another. The page's position is that nothing anyone deploys was renamed, and it lists the names that survived.
The custom resource kinds kept their names. So did the API group, the command line tool, the namespace it installs into, the container images, the Helm charts, and the Go module path. The repository and the website are the two things that moved, and both old locations redirect.
That list is the interesting part, and one entry on it deserves more attention than the page gives it. The Go module path is the full path of the old organisation's repository. Go resolves an import path to a repository by convention, by stripping the host and the first two path elements as the organisation. A module path whose organisation no longer holds the repository is not something the toolchain handles natively; it works here only because the old location redirects.
So a dependency declared as a path under the old organisation resolves through a redirect rather than through a canonical location. That is a normal, cheap thing to arrange once, and it is the kind of thing that quietly becomes load bearing as the redirect ages.
The build file still calls itself the old product name in its help output
The page's claim is precise: same code, same maintainers, same release cadence, same licence, nothing you deploy renamed. That is true of every machine-facing identifier, and the build files mostly bear it out.
The container images still publish into a namespace named for the old product under the old organisation. The container file's own copyright header still names the old project as the author. The version string is injected into a package under the old module path. All of those are deliberate, and all of them are invisible to a reader.
One is not. The build file's help target, which is what a new contributor types to discover what to run, prints a description that begins by calling the project the old name. That line is the first thing a contributor reads after cloning, and it is the one place the rename did not reach.
The distinction is worth holding on to. A resource kind named with the old prefix is a compatibility guarantee. A help string named with the old prefix is an oversight, and it is the kind that tells a new contributor that they are in the wrong repository.
The data plane library is pinned to a commit, and two major versions of one SDK are in the build
The Go module file opens with a comment explaining an unusual choice: the Go patch version is specified explicitly, and the reason given is so the continuous integration cache can be purged correctly. Most projects accept a stale cache rather than pinning that precisely.
The dependency list has two things a reader will stop on. The control plane library is required in three separate modules, and none of the three is a tagged version. Each is a pseudo-version derived from a commit, and all three carry the same date. So the project builds against an untagged snapshot of the data plane library rather than a release, which is a defensible choice for a project that ships a data plane and a common source of breakage, and an inconvenient one for anyone auditing what is in their binary.
The second is the OpenAI client library, which appears twice at two different major versions in the same build. Two majors of one client in one binary is normally a sign of a migration in progress rather than a mistake, and it means the build carries two copies of the same generated surface.
The rest of the list explains the scope: a cloud provider client for four hosted model services, an identity library, a model context protocol library, a container client, an expression language, a metrics client, a test container library, and a JSON path library in both read and write forms.
The one command route downloads an Envoy binary and then runs it
The quick start is one line, and it is worth reading what it implies.
OPENAI_API_KEY=sk-your-key aigw runAn environment variable holding a placeholder key starts a local router, and any OpenAI-compatible client is then pointed at a port on localhost. Nothing needs installing first, which is the point.
Underneath, that command fetches a data plane binary. The container file shows the mechanism: a build step downloads the binary into a user data directory using a tool whose purpose is running the data plane locally, and only for this one command, not for the server image. A version preference file sits at the repository root.
The comment on that step gives the reason for doing it at image build time rather than at run time: it reduces latency, and it avoids needing a volume for the binary, which the author describes as tricky because volumes in a compose file end up owned by root. That is a real constraint and a real fix.
The consequence for a laptop user is that the first run pulls an executable from the network and then runs it. The page does not mention it, because the page is describing a convenience, not a trust decision.
The local command image is a different base from the server image
The container file takes a variant as an argument and defaults it to a fully static base, which is the right default for a server. The same argument then has an exception, stated in a comment: the local command image needs a different variant because it needs the system C library to run the data plane it downloads.
So the two distributions are not the same shape. The server image is a static base running as a non-root user with a fixed numeric identity and no shell. The local command image carries a full C runtime so the downloaded proxy can link against it. That is the correct engineering and it is also the difference between a container you can treat as opaque and one that runs code you fetched at build time.
The rest of the file is careful in ways worth noting. The build accepts a target operating system and architecture, so the same file can produce multi-platform images, though a build flag defaults that off. The runtime sets an identifier that pins file paths inside a container, and the comment above it maps out the resulting directory layout: a configuration directory, a data directory for downloaded binaries, and two state directories for run logs and generated configuration files, each one nested under a run number.
Pinning the run number so paths are predictable is what lets the same image behave identically in a compose file and on a laptop.
Sixteen providers are listed and one of them is a vendor's own hosted service
The provider table is a grid of sixteen names, five per row for three rows and a single entry alone on the last.
The list covers the major hosted model services across three clouds, a mix of model providers and inference hosts, and a small number of regional model families. The layout is the only place the shape of the list is visible, and a lone name in the final row is what a growing list looks like before someone restyles the table.
One entry is not a model provider. It is a managed service offered by a commercial vendor, listed in the same grid, in the same weight, next to the hosted providers it would sit in front of. The project's own governance changed hands recently, and that row is where the old and new arrangements are visible in one cell.
The routing model underneath is described as two tiers. The first tier is a centralised entry point handling authentication, top-level routing and global rate limiting. The second tier handles ingress to a self-hosted model serving cluster, with fine-grained control over self-hosted access and endpoint picker support for inference optimisation.
That split is the architecture in one sentence: one place holds credentials and quotas, and another sits in front of the models you run yourself.
Thirteen examples, and most of them are named after a failure mode
The examples directory has a readme and thirteen subdirectories, and the names describe behaviours rather than features.
A basic example and one for the local command. Then the ones that matter operationally: provider fallback, a token rate limit, a stream idle timeout, a cache, access logging, monitoring, an inference pool, and a gateway configuration. Two more are named for integration surfaces, one for a model context protocol setup and one for an external agent tool.
Read as a list, that is a statement of what breaks. A provider that stops answering, a client that exceeds a quota, a stream that stalls without closing, a cache that returns the wrong thing, a request that arrives with no log line. The examples exist for the situations where a gateway is most likely to be blamed for something else.
The two integration examples are the interesting ones for anyone evaluating scope. One is a model context protocol example, which is the current direction for tool access. The other is named after a specific third-party agent framework, which is a narrower statement about who the gateway is meant to sit in front of than the sixteen-provider table would suggest.
A committed environment file, a charter PDF, and three places to read release notes
The repository root is where the project's housekeeping lives, and it is worth reading as a list.
There is a committed environment file whose name carries a tool prefix, sitting at the root of a project whose quick start tells you to set a variable in your shell. There is a technical charter as a PDF, which is the document a foundation project is expected to publish and which nothing else in the repository summarises.
Release information is in three places: a version configuration file for a version derivation tool, a directory of release notes, and a releases document. Three locations is one more than a project needs, and the page links to a website release notes page as well, making four.
The rest is quality tooling with visible thresholds: a licence header checker, a coverage configuration, a linter configuration, a misspelling ignore list, a formatter ignore list, and a pre-commit shell script. Two agent configuration directories sit alongside them, one for each of two tools, which is the same courtesy this project's own ecosystem extends to others.
None of this is a problem on its own. It is a picture of a project that has accumulated the paperwork a foundation project needs, at a moment when the foundation is new.
Editorial conclusion
Agent Router fits a platform team that already runs Envoy Gateway and wants one OpenAI-compatible surface across hosted and self-hosted models, and it fits a team that wants a small local proxy less well, since the one command route downloads a data plane binary. Before adopting it, check four things. Decide whether you want the control plane on Kubernetes or the local command, because they share a name and not much else. Expect the old names in your manifests and your code: the resource kinds, the API group, the command and the module path are all unchanged, so a search for the current name will not find most of the documentation. Pin the framework dependency deliberately, because the control plane library is pinned to an untagged commit rather than a release. And read the local route's behaviour before running it, since it fetches an Envoy binary into a user directory and then executes it.
Frequently asked questions
how to use agent router
As a local proxy, with one command that takes an API key in the environment variable, after which any OpenAI-compatible client is pointed at a port on localhost. For Kubernetes, the project offers a getting started guide that deploys it on Envoy Gateway instead, and a separate guide covers installing the command line tool and provider auto-configuration.
how to use agent router api key
The quick start passes a provider key as a shell environment variable when starting the router, and the platform deployment path keeps credentials, routing, quotas, failover and usage attribution in the gateway rather than in each application. The page points to a command line guide for installation and provider auto-configuration.
Does renaming Envoy AI Gateway break existing deployments?
No, by design. The custom resource kinds, the API group, the command line tool name, the namespace, the container images, the Helm charts and the Go module path are all unchanged, and the page says manifests written yesterday still apply. The repository and the website moved, and the old locations redirect.
What is the two tier gateway pattern in agent-router?
The first tier is a centralised entry point handling authentication, top-level routing and global rate limiting. The second tier handles ingress traffic to a self-hosted model serving cluster, with fine-grained control over self-hosted model access and endpoint picker support for inference optimisation.
What does running aigw run actually do to my machine?
It starts a local router and downloads a data plane binary into a user data directory, using a tool built for running that proxy locally, then executes it. The container file does the same download at image build time, explaining that it reduces latency and avoids a volume that would be owned by root.
Which providers does agent-router support?
Sixteen are listed in a table, covering four major cloud provider model services, a set of model providers and inference hosts, some regional model families, and one commercial managed service offered by a vendor. The page also documents local model serving through a second tier gateway in front of a self-hosted cluster.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- 9 Best Agent Gatewaysdev.to · Nov 16, 2026 · 38 points · 4 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/theagentrouter-agent-router)Star history chart for your README
[](https://hysenlabs.com/projects/theagentrouter-agent-router)Was this useful?