Front-End Checklist: 386 rules, a hosted MCP server, and two categories doing the work
🗂 The essential checklist for modern web development, for humans and AI agents
At a glance
- What is it?
- The rule corpus is broad on paper and lopsided in practice, with Accessibility and SEO accounting for close to half of it. The agent integration is the interesting part, and the hosted endpoint is where the privacy decision lands.
- Who is it for?
- Front-End Checklist is a good fit for a team that wants a shared, citable definition of front-end quality and an agent that can be pointed at a component without being re-prompted. Two things narrow that.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 14 days ago.
- What is it written in?
- Mainly MDX, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
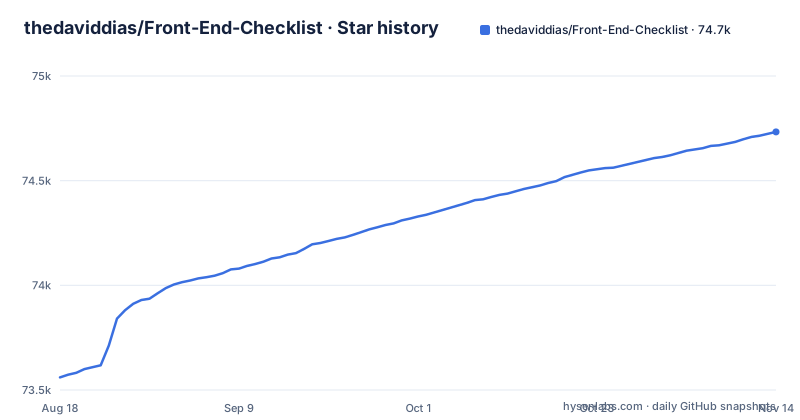
- thedaviddias/Front-End-Checklist74,733 ★ · +1,173
| Repository | 2026-08-18 | 2026-11-14 |
|---|---|---|
| thedaviddias/Front-End-Checklist | 73.6k | 74.7k |
1,173 Stars in the last 88 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two categories hold 189 of the 385 rules
The corpus is described as 386 English rules across 11 active categories, and the per-category counts in the generated catalog show how uneven that is. Accessibility carries 95 rules and SEO 94, which together account for 189 of the 386. Performance adds 44, CSS 32, JavaScript 26, HTML 25 and Images 25, Security 22 and Testing 13, while Privacy and Internationalization get 5 each.
The consequence is that "front-end quality" here means something specific rather than general. A team whose recurring defects are accessibility or metadata problems gets deep coverage, and a team whose defects are consent handling or translation gets five rules apiece. The headline number flatters the corpus, and the per-category table is the part worth reading before you decide the checklist represents your standards.
Four priority tiers, and only one of them orders your work
Every rule carries one of four priorities. Critical means site-breaking, compliance-sensitive or security-sensitive issues, and those should be fixed first. High covers issues with major impact on user experience, accessibility, performance or discoverability. Medium is described as strong best practices that belong in normal frontend quality review. Low is useful improvements that are situational or lower urgency.
Only the Critical tier carries an instruction about ordering. High, Medium and Low are adjectives on severity, not costs, and a rule marked Medium outranks nothing in particular. The consequence shows up the moment an agent runs the corpus over a component: teams that need a gate rather than a catalogue have to declare the cutoff themselves, since the Critical tier is the only boundary the README draws for you.
The README names which of the eleven MCP tools to call first
The hosted server exposes 11 MCP tools, and the agent guidance is specific about sequencing rather than leaving it to the model. Use `review_code` first for pasted HTML, CSS, JavaScript, React or Next.js code. Use `search_rules` before making frontend accessibility, performance, SEO, security or image recommendations, so the answer comes from the corpus rather than from the model's own recollection. Use `get_workflow` or `get_checklist_rules` for launch, accessibility, SEO, security and performance audits. Use `audit_url` for public https:// pages.
That ordering is the useful part, because it converts a vague instruction into a repeatable procedure. It also means tool choice is a decision with consequences: reaching for `audit_url` on something that is not a public page wastes the call, and skipping `search_rules` produces exactly the unsourced advice the corpus exists to replace. One operational note is worth keeping: some MCP clients discover installed tools lazily, so the README advises naming the server explicitly in the prompt rather than assuming the agent has noticed it.
The review surface stops at public https:// pages
Here is the boundary that matters most for anyone with private code. `audit_url` is scoped to public https:// pages, and the code review path takes pasted code or file contents. Nothing in the documented toolset reads your repository, your staging environment or an authenticated application, so a component that has never been published has to reach the reviewer by being pasted in.
The second boundary is where the code goes. The public endpoint is mcp.frontendchecklist.io, so a review of your component is a review performed against a server somebody else operates, and the README itself points out that the intended first use is pointing an agent at a real component, page or public URL. There is a local alternative, a stdio server at `packages/mcp/src/cli.ts`, and the tree also carries a `.mcp.json` file and a `.playwright-mcp/` directory. The consequence for a team with unreleased work is that the hosted path and the local path are not equivalent in privacy, and the choice has to be made before the first review rather than after.
The README catalog is a build artifact, maintained by a script
The checklist embedded in the README is generated. The block opens with a `rules-catalog:start` marker and carries a note saying it was generated from 386 English rules and is maintained by `pnpm generate:readme`. Editing that section by hand is pointless, because the next regeneration overwrites it, and the same applies to the skill files produced by `pnpm generate:skills`.
The contributor commands show how tightly the corpus is policed. `pnpm validate:rule-structure` checks structure, `pnpm score:rules` scores the corpus, and `skills:audit` runs a skills quality audit through a script under `scripts/audit/`. Behind the documentation sit a pnpm workspace over `apps/*`, `packages/*` and `configs/*`, turbo for build and test, biome for lint and format, commitlint, and lefthook installed by a prepare script. The consequence for a reader is that the rule set is a maintained product rather than a wiki page, and the generated header describes the corpus as English rules.
Three ways in, and the checklist verifies rather than decides
You can reach the same corpus three ways, and the README is explicit that they are not interchangeable. The website at frontendchecklist.io is for browsing and filtering, with all rules under frontendchecklist.io/rules and curated checklists under frontendchecklist.io/checklists. The MCP server is for agent workflows. The README itself is for reading the checklist in one place. What you get is the same in each case: rule pages with explanations, remediation guidance and verification steps.
The scope is verification, and the companion project makes that boundary explicit. UX Patterns for Devs is described as the place to go while you are still deciding what interface to build, comparing common patterns for forms, navigation, data display, feedback states, authentication and AI interfaces, before Front-End Checklist is used to check the result. The consequence for teams that reach for a rule corpus too early is that they end up auditing an interface they have not chosen yet, which produces findings about markup and metadata rather than about whether the interaction is right.
Installing every skill is one flag away from installing one
The skills route installs from npm with the skills CLI:
npx skills add frontendchecklist/skills
npx skills add frontendchecklist/skills --skill https
The first form brings in the whole collection; the second narrows it to a single concern, and the README points at two entry points that show the shape of both, a global audit skill at `skills/frontend-checklist-global/SKILL.md` and a focused rule skill at `skills/https/SKILL.md`. The repository root also contains a `skills-lock.json`.
The consequence is the usual one for skill collections: installing everything means every skill competes for your agent's attention before any of them runs, and a full install to review one page of HTTPS headers is a poor trade. Contributing to the corpus locally is a different exercise again, with `pnpm install` and `pnpm dev` for the site and the validation and scoring commands above. Pick the narrow install unless you genuinely intend to run broad audits.
Editorial conclusion
Front-End Checklist is a good fit for a team that wants a shared, citable definition of front-end quality and an agent that can be pointed at a component without being re-prompted. Two things narrow that. The corpus is weighted hard toward Accessibility and SEO, so treat the other nine categories as thinner than the headline number suggests, and the review surface reaches only public https:// pages unless you paste the code yourself. Before wiring an agent to it, decide where the code goes: the hosted server at mcp.frontendchecklist.io is a third party, and the local stdio entry point at packages/mcp/src/cli.ts is the alternative. Then confirm the priority tier you intend to enforce, since only Critical carries an implied ordering.
Frequently asked questions
What is Front-End Checklist and how do I use it?
It is an open-source front-end quality system published as 386 English rules across 11 categories, and you can read it on the website, query it through the MCP server, or work through it in the README. Each rule page carries an explanation, remediation guidance and verification steps.
Can I use Front-End Checklist with Claude Code or another coding agent?
The project publishes 11 MCP tools on a hosted endpoint at mcp.frontendchecklist.io, plus a local stdio server at `packages/mcp/src/cli.ts` for editor integration. Skills can also be installed with `npx skills add frontendchecklist/skills`, and the README notes that some clients discover MCP tools lazily, so naming the server in your prompt helps.
Does Front-End Checklist cover privacy and internationalization?
Barely, and that imbalance is worth knowing before you rely on it. Of the 386 rules, Privacy and Internationalization have 5 each, while Accessibility has 95 and SEO 94, so nearly half the corpus sits in those two categories.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/thedaviddias-front-end-checklist)Star history chart for your README
[](https://hysenlabs.com/projects/thedaviddias-front-end-checklist)Was this useful?