scArches maps query cells into a reference atlas instead of refitting the model
Reference mapping for single-cell genomics
At a glance
- What is it?
- A reference-based approach to single-cell data: query cells are projected into an atlas that somebody else built, so annotations, disease-state calls and imputed modalities come along with the projection. The repository is thin on documentation and keeps its install story in setup.py.
- Who is it for?
- Adopt scArches if you have an atlas you trust and a new batch you would rather project into it than fold into a fresh fit, because that is the case the package is built for and the one the annotation transfer assumes. Look elsewhere if your reference has to change every time a batch arrives, or if you need a quick read of the code, since the repository README is 205 words and pushes setup to a documentation site it does not explain.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 142 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
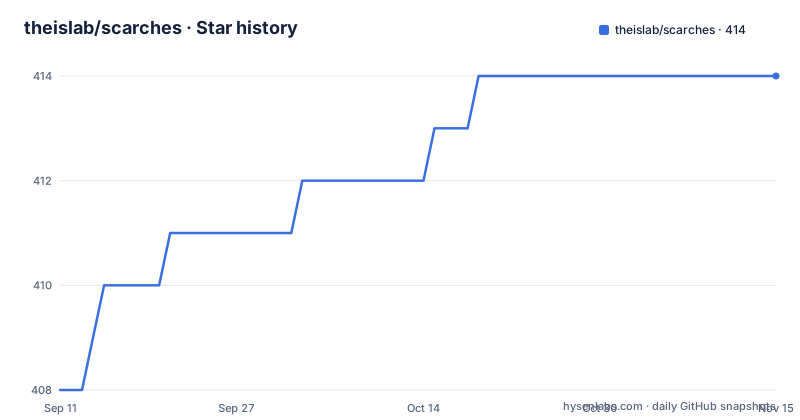
- theislab/scarches414 ★ · +6
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| theislab/scarches | 408 | 414 |
6 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Query cells get a projection into an atlas, not a second trained model
scArches is a package for reference-based analysis of single-cell data. The workflow it describes starts from a reference atlas that already exists and then integrates query data into it, rather than training one model over reference and query together.
Three outcomes follow from that arrangement, and the README names them. Cell-type annotation transfers from the reference to the query. Disease states can be identified by mapping a sample onto a healthy atlas. And more advanced applications come from the same projection, such as imputing missing data modalities or imputing missing spatial locations.
The method is published. The README asks users to cite `Mapping single-cell data to reference atlases by transfer learning`, a 2021 paper in Nature Biotechnology under the citation key `lotfollahi2021mapping`. That paper is the actual specification of what the package does, and the repository leaves it at that rather than restating the architecture.
Two documentation hosts, and no install command anywhere in the README
The README's usage and installation section is one line: it points at https://scarches.readthedocs.io/ for documentation and tutorials. There is no pip line, no conda line and no environment recipe in the repository root.
Even the destination is not settled. One link in the README points at scarches.readthedocs.io, while the project's homepage field points at https://docs.scarches.org/en/latest/, and the readthedocs badge targets scarches.readthedocs.io as well. A newcomer who types the homepage URL and a reader who follows the README can end up in two different documentation trees.
What the badges do settle is where the package is distributed. The README carries a PyPI badge targeting https://pypi.org/project/scarches and a download counter badge from pepy.tech, so the install route is the package index rather than a build from this repository.
setup.py sets a scikit-learn deprecation flag before anything is imported
The most interesting line in setup.py is not part of the package metadata. Before the setup call, the script sets an environment variable that does not exist for the reader's benefit:
os.environ["SKLEARN_ALLOW_DEPRECATED_SKLEARN_PACKAGE_INSTALL"] = "True"The comment above it explains why: Read the Docs fails otherwise, because somewhere in the dependency tree a deprecated scikit-learn package is being installed. Set at build time rather than shipped as configuration, that variable is not something a reader installing from PyPI ever sees execute.
That detail tells you how documentation gets built here. `.readthedocs.yml` at the root builds the `docs/` tree by running setup.py, and the scikit-learn escape hatch exists to keep that build alive rather than to keep the library working.
The dependency floor reaches torch and scvi-tools, not just scanpy
The install requirements are heavier than a single-cell package usually admits to:
install_requires=[
  "scanpy[leiden]>=1.6.0", # includes anndata
  "scHPL>=1.0.0",
  "numpy>=1.19.2",
  "scipy>=1.5.2",
  "scikit-learn>=0.23.2",
  "matplotlib>=3.3.1",
  "pandas>=1.1.2",
  "torch>=1.8.0",
  "scvi-tools>=0.12.1",
  "tqdm>=4.56.0",
  "requests",
  "gdown",
  "muon",
],
A probabilistic single-cell stack sits under this one, since scvi-tools is a direct requirement and muon is pulled in alongside it. `gdown` points at downloads from hosted storage, which fits a package whose examples start from a published atlas.
The floors are old. numpy 1.19.2, pandas 1.1.2 and torch 1.8.0 date from 2020, and the classifiers stop at Python 3.11. Nothing forbids a newer interpreter, but the file does not claim one.
The version reported to the index falls back to 0.6.1 when the package will not import
setup.py tries to read the version out of the package itself, and has a hardcoded fallback for when that fails:
try:
    from scarches import __author__, __email__, __version__
except ImportError:  # Deps not yet installed
    __author__ = __email__ = ''
    __version__ = '0.6.1'
The comment explains the intent: the dependencies are not installed yet when setup.py runs, so importing the package to read its version would fail. The fallback fills in the author and email as empty strings at the same time, which means a build that takes this branch publishes a distribution with no author attached.
The number in that fallback does not match the newest tag. The most recent GitHub release is v0.5.1 from 2023-06-27, with v0.5.0 in 2022 and v0.4.0 in 2021, so a fallback version above every published release is either a placeholder or work that never reached a tag. Anyone pinning scArches by version has to decide which of those two numbers to trust.
The license is declared twice and the two declarations disagree
The repository's license field reads BSD-3-Clause, and a LICENSE file sits at the root. setup.py passes a different answer to the packaging tools:
license='MIT',and the classifier list repeats it with `License :: OSI Approved :: MIT License`. So a user reading the GitHub sidebar and a user reading the package metadata on an index are being told two different things, with no note in the README reconciling them.
The rest of the classifier block is narrower than the code. Python 3.9 through 3.11 are declared, along with the Jupyter framework, the console environment, both developer and science research audiences, English, macOS and Windows. The file is cut off after the Windows line, so whatever else it declares is not visible here.
scarches/, tests/, notebooks/ and docs/ sit side by side at the root
The repository is laid out as a package plus three working directories: `scarches/` for the library, `tests/` beside it, then `notebooks/` and `docs/`. An `envs/` directory and a `setup.py` complete the picture, along with `README.rst` and `.travis.yml` for continuous integration.
GitHub classifies the repository's primary language as Jupyter Notebook rather than Python, which matches that layout. The tutorials the README sends you to are built out of those notebooks, and the citation request sits on the same page, so the intended route is read a notebook, then cite the paper.
Two details of the layout are easy to miss. `long_description` in setup.py is read from `README.rst` with `Path('README.rst').read_text('utf-8')`, so the file GitHub renders and the file the package index renders are the same source. And `packages=find_packages()` means the top level `notebooks` and `docs` directories are only packaged if they carry an `__init__.py`.
The reference stays fixed, and that fixedness is what the annotation transfer buys
The alternative to reference mapping is to fit one model across the reference and the new data. The two approaches differ in what happens when the next batch arrives.
A joint fit has to be recomputed, and the reference changes underneath every annotation attached to it. Reference mapping leaves the atlas alone and produces a projection for the new cells only, which is why annotation transfers at all and why a healthy atlas can be reused as a fixed yardstick for a disease sample.
The cost sits on the other side. Cells that the reference does not represent have nothing to be projected onto, and the README offers imputation of missing modalities and spatial locations as the answer rather than describing a fallback. Anything outside the reference's coverage is the case to test first, and the repository does not document how the package behaves there.
Editorial conclusion
Adopt scArches if you have an atlas you trust and a new batch you would rather project into it than fold into a fresh fit, because that is the case the package is built for and the one the annotation transfer assumes. Look elsewhere if your reference has to change every time a batch arrives, or if you need a quick read of the code, since the repository README is 205 words and pushes setup to a documentation site it does not explain. Before anything else, read the LICENSE file at the root rather than the `license` field in setup.py, because the two disagree, and confirm your scanpy, scvi-tools and torch versions sit above the floors listed there.
Frequently asked questions
What does scArches do with single-cell query data?
It integrates the query into an existing reference atlas. From that mapping you can transfer cell-type annotation from reference to query, identify disease states by mapping to a healthy atlas, and impute missing data modalities or spatial locations.
How do I install scArches?
The repository README gives no install command and points at https://scarches.readthedocs.io/ instead. The package is on PyPI as scArches, and setup.py pulls scanpy, scHPL, numpy, scipy, scikit-learn, matplotlib, pandas, torch, scvi-tools, tqdm, requests, gdown and muon.
Which license is scArches released under?
The two declarations conflict. The repository's license field reads BSD-3-Clause with a LICENSE file at the root, while setup.py passes license='MIT' and carries the MIT classifier.
Is the scArches repository still worked on?
The repository is not archived, and its last push was on 2026-06-26. The newest tagged release is v0.5.1 from 2023-06-27, after v0.5.0 in 2022 and v0.4.0 in 2021.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/theislab-scarches)Star history chart for your README
[](https://hysenlabs.com/projects/theislab-scarches)Was this useful?