TSLib's baselines still run, and its benchmark table stopped at March 2024
A Library for Advanced Deep Time Series Models for General Time Series Analysis.
At a glance
- What is it?
- TSLib is a Python code base for deep time series models across long- and short-term forecasting, imputation, anomaly detection and classification. Its maintainers announced in April 2026 that they will not be actively adding new features, its leaderboard is stamped March 2024, and its Docker build pins one CUDA and PyTorch combination to a wheel filename.
- Who is it for?
- TSLib remains the right way to run deep time series baselines against each other under a known protocol, and the wrong thing to cite as a current ranking. Use it for implementation correctness and look-back discipline, check newer work for whether a model still matters, and pin the commit, because the repository has no releases and the last push was 2026-04-18.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 7 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
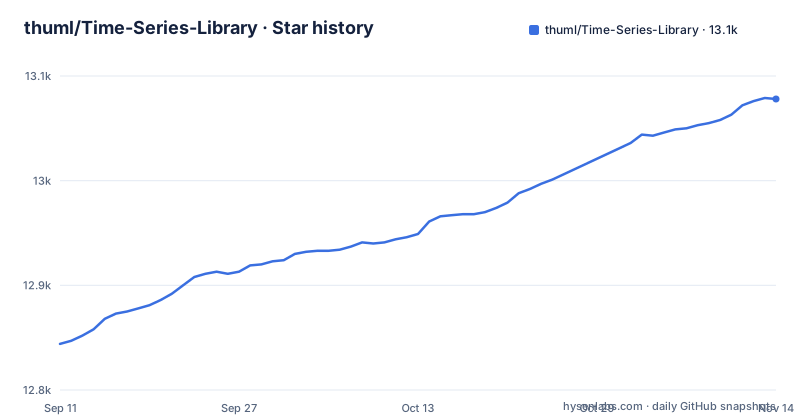
- thuml/Time-Series-Library13,078 ★ · +234
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| thuml/Time-Series-Library | 12.8k | 13.1k |
234 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The maintainers stopped adding features in April 2026, and wrote it down
The newest news entry governs everything else in this repository. Dated 2026.04, it states that due to the limited bandwidth of the current maintainers, they will not be actively adding new features to the library. It goes on to say that since the library was originally released three years ago, many of its benchmarks may no longer be meaningful for evaluating the effectiveness or progress of current research, while adding that the baseline implementations remain correct, and it recommends seeking out newer benchmarks.
The last push recorded for the repository is 2026-04-18, which agrees with that notice instead of contradicting it. Nothing is archived, so the code is not going anywhere. The distinction to hold onto is the one the maintainers draw themselves: implementations stay correct, conclusions do not stay current.
That rules out one specific use. Reproducing a table from TSLib as evidence that a new model does not beat an old one is exactly the inference being warned against, and so is calling a leaderboard position current. Use the library to run baselines against each other and look elsewhere for rankings.
The leaderboard is stamped March 2024 and names one protocol per column
The ranking table opens with the line Till March 2024, and its columns are not one task but several: long-term forecasting split into Look-Back-96 and Look-Back-Searching, short-term forecasting, imputation, classification, and anomaly detection. TimesNet takes first place in four of those six columns, with the Non-stationary Transformer second in three of them and FEDformer second in anomaly detection. The two long-term forecasting columns disagree at the top, with TimeXer leading Look-Back-96 and TimeMixer leading Look-Back-Searching.
Read those dates against the maintenance notice. The table describes early 2024, the branch last moved on 2026-04-18, and the maintainers say in the same page that their own benchmarks may no longer be meaningful. A reader who wants to know where a model sits today gets no answer from this table.
What the table still supports is protocol matching. It records which models were measured under which task split at that date, and the note underneath invites a paper or code link for new models, promising they will be added and the leaderboard updated as soon as possible. Treat it as a dated snapshot with named settings.
Look-Back-96 and Look-Back-Searching exist because papers disagree on input length
The split is not cosmetic. A news entry dated 2024.03 explains that, given the inconsistent look-back length of various papers, the long-term forecasting leaderboard was divided into Look-Back-96 and Look-Back-Searching, with a recommendation that researchers read TimeMixer, which includes both look-back length settings in its experiments for scientific rigor.
Look-back length is how many past steps a model is shown. Papers that feed a fixed 96 steps and papers that search for the best length are not solving the same problem, and their numbers do not compare even on an identical dataset. Keeping them in separate columns is the mechanism that stops the comparison from being made.
For a reader reproducing a result, the consequence is concrete: find out which protocol produced a number before setting it beside a TSLib result. A paper reporting only a fixed 96-step window belongs next to TimeXer and iTransformer in the first column, not beside TimeMixer and PatchTST in the second. Quoting a result against the wrong column is the specific error this split was created to prevent.
One wheel URL encodes cu12, torch2.5, cxx11abiFALSE, cp311 and linux_x86_64
Mamba entered the library in 2024.04, and that entry tells you that you need to install mamba_ssm with pip first. The Dockerfile does it by direct wheel URL instead of a package name, and the filename carries every condition the build has on itself:
RUN --mount=type=cache,target=/root/.cache/pip \
    pip install https://github.com/state-spaces/mamba/releases/download/v2.2.6.post3/mamba_ssm-2.2.6.post3+cu12torch2.5cxx11abiFALSE-cp311-cp311-linux_x86_64.whl
Parse it as a set of assertions. cu12 is CUDA 12, torch2.5 is the PyTorch series, cxx11abiFALSE is the C++ ABI setting, cp311 is CPython 3.11, and linux_x86_64 is the platform. The base image is pytorch/pytorch:2.5.1-cuda12.1-cudnn9-devel, which is what makes those assertions true at all.
The consequence is that this line is the least portable thing in the repository. Move the base image to a different CUDA or PyTorch version and the URL no longer describes a wheel built for it. On a host that is not linux_x86_64, this is among the first lines to fail, and the fix is not to edit the URL.
uni2ts installs with --no-deps, so its dependencies are pinned by hand
The model file for Moirai gets its dependency from a second line in the Dockerfile, and that line is unusual:
RUN --mount=type=cache,target=/root/.cache/pip \
    pip install uni2ts --no-deps
The --no-deps flag tells pip to install uni2ts and ignore whatever it declares it needs. The cost of that choice shows up elsewhere: requirements.txt carries a block marked uni2ts deps with gluonts==0.16.2, lightning==2.6.0, hydra-core==1.3.0, jax==0.8.1, jaxtyping==0.3.4, orjson==3.11.5, tensorboard==2.20.0 and python-dotenv==1.0.0 pinned by hand.
So the dependency graph for this model lives in two places that must agree. If uni2ts changes its own requirements, the hand-written block does not follow, because nothing reads the installed package metadata. Drift between the two produces import errors that surface inside the Moirai model file rather than at install time, which makes the cause harder to locate than an ordinary transitive failure.
This is also the argument for running the model inside the container. The Dockerfile applies both lines in a fixed order against a known base image, so the pinned block and the no-deps install stay in agreement there even though nothing enforces that agreement outside it.
requirements.txt installs a forecasting stack that a plain run never imports
Every version is pinned exactly, and the file is longer than any one experiment requires. Past the numeric and plotting stack of numpy==2.1.2, scipy==1.16.3, scikit-learn==1.7.2, pandas==2.3.3, matplotlib==3.10.8, sktime==0.40.1, sympy==1.13.1, PyWavelets==1.9.0 and datasets==4.5.0, it pulls in three pretrained time series forecasting packages:
transformers==4.57.3
huggingface_hub==0.36.0
chronos-forecasting==2.2.1
tirex-ts==1.3.0
timesfm==1.3.0
That is the price of one file serving every model in the library. A single baseline run inherits the whole install, jax==0.8.1 and lightning==2.6.0 included, whether or not the code path reaches them. Exact pins are the right call when a number has to be reproducible on a paper, and the wrong call when you want the library inside an environment that already has a working scientific stack.
For a reader, installing TSLib into an existing project is a conflict negotiation rather than an addition. Build the image from the Dockerfile instead of merging this file into your own environment.
docker-compose.yml hands you a named volume and publishes no port
The compose file defines one service, dev_tslib, built from the tslib target in the Dockerfile, with container_name tslib, a tty, restart always, and:
    shm_size: 8gb
    tty: true
    restart: always
It passes NVIDIA_VISIBLE_DEVICES=all and NVIDIA_DRIVER_CAPABILITIES=compute,utility so the container can see host GPUs, and mounts workspace_data:/workspace rather than your working tree. The ports section is commented out, both the 8888 and the 6006 entry, and the proxy variables are commented with a note to modify them to your own agent address. The CMD in the Dockerfile is bash, so what you get is a development shell, not a service.
The internal path is not arbitrary either. The Dockerfile puts /workspace/Time-Series-Library on PYTHONPATH while the compose file sets working_dir to /workspace and mounts the named volume there. The layout being pointed at is run.py alongside data_provider/, exp/, layers/, models/, scripts/, utils/, tutorial/ and pic/.
Three consequences follow: nothing is reachable from the host until you uncomment the ports, results written inside land in a Docker volume instead of on your disk, and the PYTHONPATH entry assumes a checkout directory named Time-Series-Library.
There are no GitHub releases, so there is no version number to pin
No GitHub releases are attached to this repository. The artifacts are code on the main branch and a container built from the Dockerfile, and the only version numbers in play belong to other projects: the base image tag pytorch/pytorch:2.5.1-cuda12.1-cudnn9-devel, the exact requirement versions, and the segments inside the mamba_ssm wheel filename.
The consequence is that you cannot write a dependency line for TSLib that names a released version. What you can pin is the surrounding build, meaning the base image tag plus requirements.txt, and record the commit you ran against, since the last push is dated 2026-04-18 and nothing after it carries a version.
This matters more here than it would for a library with releases, because the maintainers have said new features are not coming and benchmarks may be stale. A fixed pin is how a result stays reproducible once the baseline implementations sit still and the branch does not move again for a long stretch. Without a release, the commit hash is the only handle available.
Editorial conclusion
TSLib remains the right way to run deep time series baselines against each other under a known protocol, and the wrong thing to cite as a current ranking. Use it for implementation correctness and look-back discipline, check newer work for whether a model still matters, and pin the commit, because the repository has no releases and the last push was 2026-04-18.
Frequently asked questions
What Python library can I use for time series forecasting?
For deep time series models rather than classical methods, TSLib is a Python code base covering five tasks: long- and short-term forecasting, imputation, anomaly detection and classification. It provides implementations to evaluate and extend, plus scripts and a leaderboard, with its leaderboard stamped Till March 2024.
Is TSLib still getting new features?
The news entry dated 2026.04 states that due to the limited bandwidth of the current maintainers, no new features are being actively added. It also states that the baseline implementations remain correct, that many benchmarks may no longer be meaningful, and recommends seeking out newer benchmarks.
Which models lead the TSLib leaderboard?
As of March 2024, TimesNet is first in short-term forecasting, imputation, classification and anomaly detection. The two long-term forecasting columns have different winners, with TimeXer leading Look-Back-96 and TimeMixer leading Look-Back-Searching, because fixed and searched look-back lengths are kept apart.
What does the TSLib Dockerfile install?
It starts from pytorch/pytorch:2.5.1-cuda12.1-cudnn9-devel, installs requirements.txt, then installs a specific mamba_ssm wheel URL built for cu12, torch2.5, cxx11abiFALSE, cp311 and linux_x86_64, and then installs uni2ts with --no-deps.
Can I reach a TSLib container over the network?
Not as the compose file ships. The ports section is commented out, both 8888 and 6006, and the Dockerfile command is bash, so the compose setup gives you a development shell with a named volume mounted at /workspace rather than a service you can connect to.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/thuml-time-series-library)Star history chart for your README
[](https://hysenlabs.com/projects/thuml-time-series-library)Was this useful?