trickest/cve: one markdown file per CVE, one regex to vet their references
Gather and update all available and newest CVEs with their PoC.
At a glance
- What is it?
- This repository is a generated index of proof-of-concept links for public CVEs, organised as one directory per year and one markdown file per identifier. Almost everything in it is produced by a workflow the maintainers describe in seven steps, and the README's only claim about quality is one sentence about having designed the workflow carefully.
- Who is it for?
- Adopt trickest/cve if you want a searchable map of where public proof-of-concept code exists for a product you patch, and you treat every link as unverified. Do not adopt it as an authoritative feed, because the entries are machine-collected and the README claims accuracy as an intention rather than a measurement.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly HTML, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
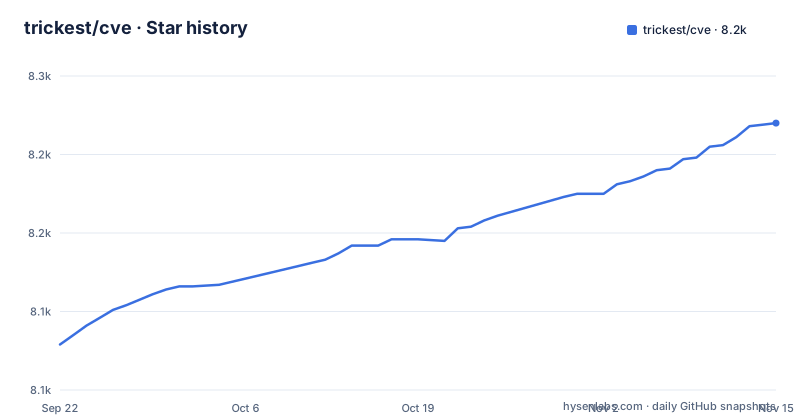
- trickest/cve8,220 ★ · +141
| Repository | 2026-09-22 | 2026-11-15 |
|---|---|---|
| trickest/cve | 8.1k | 8.2k |
141 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
A directory per year and a file per identifier
The layout is the data model. The repository root holds a directory for every year from 1999 through 2026, and inside each one is a markdown file named after the identifier, which the README links as `/trickest/cve/blob/main/2022/CVE-2022-0001.md` and similar.
So there is no index to query and no schema: browsing is a directory listing, and the file name is the CVE. Each file is written from the collected data, and the README says the workflow writes everything into easy-to-read markdown files.
The root also holds the workflow's inputs and outputs. `blacklist.txt` filters false positives, `references.txt`, `github.txt` and `config-template.yaml` sit alongside it, `hot_cves.csv` is described as the complete history behind the featured table, and `summary_html/` holds a template and a script.
GitHub reports the repository's primary language as HTML.
Two techniques, and they are different kinds of search
The How it works section describes the collection pipeline in seven steps. Details come from the CVE Project's cvelist repository, with a shout-out to the CVE Project, and the CVEs are then split up by year.
Finding proof-of-concept links is the part that has a real technique in it, and there are two. The first uses References. For each CVE, gather its References and check whether any of them points to a proof of concept, using ffuf against a list of keywords. The second uses GitHub: search for repositories with find-gh-poc that mention the CVE ID.
So one technique reads the vulnerability record the way a database stores references, and the other reads code hosting for a string. Neither one executes anything; both are text matching over things that already exist.
There is a third source folded into the first. HackerOne reports that reference a CVE are collected through AllVideoPocsFromHackerOne, credited to zeroc00I, so bug bounty disclosure becomes an input too.
One regex decides whether a reference counts as a PoC
The keyword check is a single regular expression, and it is the whole classifier:
(?i)[^a-z0-9]+(poc|proof of concept|proof[-_]of[-_]concept)[^a-z0-9]+Read it as three alternatives for the phrase, wrapped so that it must be delimited by non-alphanumeric characters on both sides, case-insensitively. It matches poc, the spelled-out phrase with spaces, and the same phrase hyphenated or underscored.
The surrounding boundary requirement is what stops the match running inside a longer word, and the alternation is what stops it requiring one exact spelling. It is credited to joohoi in the README, and the note beside it is that ffuf is awesome for more purposes than just content discovery.
Everything downstream inherits this classifier's judgement. A reference that says proof of concept but is a link to a discussion gets in, a reference that points at real exploit code without the phrase does not, and `blacklist.txt` exists to remove the first kind after the fact.
Manually committed data survives the generator
The merge step is the one that matters for anyone who wants to correct the data: the fresh results are merged into the repository without overwriting the data that was committed manually.
That is a deliberate asymmetry in a repository that is otherwise machine-written. So a correction you commit by hand is not overwritten by later runs.
The remaining steps are the mechanical ones. False positives are filtered using `blacklist.txt`, all of the found proof-of-concept links are merged, GitHub badges are generated for each affected software version using shields.io, and everything is written into the markdown files.
The badges are the part that pays off for a reader. A per-version badge means the markdown file for an identifier records which releases are affected, which is the question most people arrive at a CVE list with.
The accuracy claim is one sentence about the workflow
The README's note on quality is a blockquote: almost everything in this repository is generated automatically, and the workflow was carefully designed, and continues to be developed, to ensure the results are as accurate as possible.
Three things are absent from that sentence, and they are the ones a reader should hold. There is no measurement of how many entries were checked. There is no statement of what proportion of CVEs have a proof of concept at all, which is the difference between an index of exploits and an index of vulnerabilities. And the workflow's own vocabulary is about finding, not verifying.
So the honest reading is that this is a high-recall search over public sources with a hand-maintained false-positive list. A negative result, a CVE with no file here, means the two techniques did not find a link, not that no proof of concept exists.
The use cases in the README are written from the same direction. Browse around and find a proof of concept to test with; watch the repository for new entries; search for a specific product, and possibly version; monitor the atom feed. Every one of those starts from the index, not from the index being authoritative.
The featured table shows 2022 and the tree runs to 2026
The Current hottest CVEs table at the top of the README lists four identifiers: CVE-2022-0001, CVE-2022-25297, CVE-2022-1388 and CVE-2022-25451. Every one of them is from 2022, while the repository has directories for 2023, 2024, 2025 and 2026 and the default branch was pushed to on 2026-10-16.
So the first thing a visitor sees is four years behind the collection. Whether the table is a stale snapshot, a manually curated selection or a placeholder the workflow fills from `hot_cves.csv`, the README does not say, and the CSV is the only pointer to the complete history.
For anyone using this as a feed, the practical consequence is to ignore the table and use the directories, the product search, or the atom feed at `commits/main.atom`. The table is a header, not an index.
summary_html turns the year directories into one table
The last use case is a local search tool: create a searchable HTML table using the template and script in `summary_html`, with a published example linked from the README. That is the answer to the fact that the repository has no index of its own.
The two notification routes are the repository's Watch feature for new proof-of-concept links going public, and the atom feed for a specific product. Both are pushes rather than queries, which suits a dataset that grows by appending a file per identifier.
The commercial context is in the last section. The repository is described as a Trickest workflow, and the invitation is to sign up for a demo to customise this workflow, get access to more workflows or build your own from scratch, on the grounds that cookie-cutter solutions rarely cut it. So the open part is the output, a corpus of markdown files, and the workflow engine is the product at trickest.com.
Editorial conclusion
Adopt trickest/cve if you want a searchable map of where public proof-of-concept code exists for a product you patch, and you treat every link as unverified. Do not adopt it as an authoritative feed, because the entries are machine-collected and the README claims accuracy as an intention rather than a measurement. Before you use a hit, read the CVE record it links to, and check the year directories against the identifier: the featured table at the top of the page still shows 2022 entries.
Frequently asked questions
How does trickest/cve collect proof-of-concept links?
CVE details come from the CVE Project's cvelist repository and are split by year, then two techniques find proof-of-concept links: checking each CVE's References with ffuf and a keyword regex for poc or proof of concept, and searching GitHub with find-gh-poc for repositories mentioning the CVE ID. HackerOne reports are a third input through AllVideoPocsFromHackerOne.
How do I find exploits for a specific product or version?
The README's use cases are to search for a specific product, and possibly version, to find all public exploits related to it, to watch the repository for notifications about new proof-of-concept links, and to monitor the atom feed at commits/main.atom. For a single searchable table, it points at the template and script in the summary_html directory.
Is the trickest/cve data accurate?
The README says almost everything is generated automatically and that the workflow was carefully designed to ensure the results are as accurate as possible, without a measurement. False positives are filtered with blacklist.txt and manually committed data is never overwritten by a run, but nothing claims completeness, so a missing entry means the search found nothing.
How do I contribute a proof of concept to trickest/cve?
Create an issue on GitHub or tweet at the maintainer.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/trickest-cve)Star history chart for your README
[](https://hysenlabs.com/projects/trickest-cve)Was this useful?