Comp AI CRM: the agent is a deployment, not a chat box
Comp AI CRM is an open source, CRM designed for AI agents. Agentic-first CRM.
At a glance
- What is it?
- A TypeScript monorepo where an autonomous agent owns its own deployment, leases due work from a Postgres queue, and can only write to the record when the evidence is strong. Below is how the queue, the tools, the sandbox and the env file actually behave.
- Who is it for?
- Worth evaluating if you want an agent that keeps working after the browser closes and you are prepared to read its source before trusting it with customer records. Not a fit if you need graded confidence on stored facts, a shipped inference path, or a sandbox that can install its own packages.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 14 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
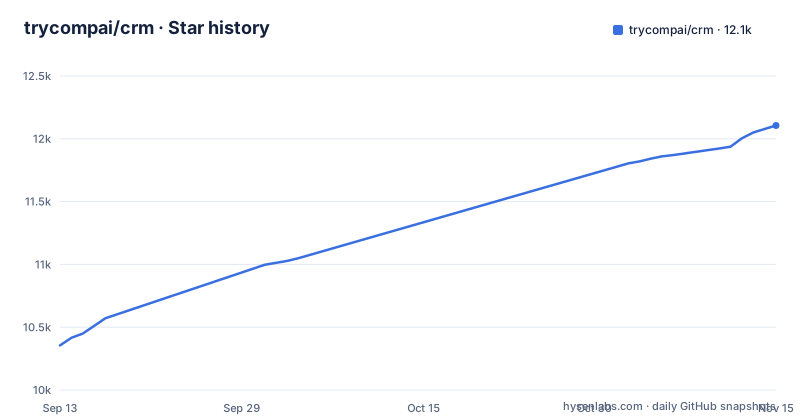
- trycompai/crm12,106 ★ · +1,751
| Repository | 2026-09-13 | 2026-11-15 |
|---|---|---|
| trycompai/crm | 10.4k | 12.1k |
1,751 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
apps/agent is a separate deployment built on the eve runtime
The agent lives in apps/agent and ships as its own deployment rather than as a panel inside the web app. It is built on eve, Vercel's filesystem-first framework for durable agents, and that choice sets the shape of everything else: a tool is a file, a skill is a markdown file, a schedule is a file. The runtime owns durability, so sessions survive a redeploy and interrupted work resumes where it stopped. The inventory is small enough to read in one sitting. There are 18 authored tools, including read_crm_history, search_crm, identify_contact, research_person, enrich_company, record_fact and schedule_recheck. There are four skills, all prose the agent reads and which are versioned like code: evidence.md, identity-matching.md, data-boundaries.md and writing-a-brief.md. There is one schedule file, dispatch.ts, whose entire job is to decide nothing, lease whatever is due, and start a session per row.
lib/tasks.ts leases rows with FOR UPDATE SKIP LOCKED instead of a cron expression
The work queue lives in lib/tasks.ts, and the leasing is done in SQL rather than in a timer. claimDue claims rows with FOR UPDATE SKIP LOCKED, which is what lets two dispatchers run at the same time and still take disjoint work, and it is what frees a row again when the process that held it dies, because the lease has an expiry rather than a lock that has to be cleaned up by hand. The design rule follows from that: anything that smells like every N minutes, take the oldest ten contacts belongs in a task's dueAt field, not in a cron expression. Re-entry is handled the same way. When the agent wants another look at somebody it calls schedule_recheck and has to say why, and that reason is shown to the rep, on the reasoning that an agent which cannot say why it will be back in fourteen days has a default, not a reason.
No tool accepts a confidence score, so the ledger has to price the evidence
The project states a goal of not guessing facts about people. Its listed tools do not accept a model-supplied confidence score, but that design alone cannot guarantee that observations or inferences are correct. The stated reason is that a model asked to grade its own certainty will do it, and will be wrong in the direction that makes itself look useful. Tools report what they observed, and two examples are named, crm.signature-block and github.account-identity. A ledger then prices that evidence. Strong evidence writes to the record; weak evidence becomes a suggestion that a human settles. The cost of that design is throughput. The project says weak evidence becomes a suggestion for a person to review. Check the actual ledger and review workflow before relying on it for accuracy or workload estimates.
Every external source is optional and startup prints which ones are off
The agent is designed to run with no outside source configured at all. The project says read_crm_history can use existing threads, meetings and signature blocks without external research or enrichment keys. The agent still needs a working model and infrastructure; the documented Vercel deployment can authenticate to AI Gateway using OIDC. Each key adds one more place to look, and rather than letting the model discover gaps one failed call at a time, the agent is told at the start of every session which sources this install has and plans around them. It also prints the list at startup, so an operator sees the degraded state immediately instead of inferring it later from a thinner record.
[agent] off  Web research (PERPLEXITY_API_KEY)
[agent] on   Company brand data (Settings → General)
[agent] on   LinkedIn (Settings → General)
The consequence for readers is direct: an install without optional enrichment keys can still use CRM history when its required services are configured, but identity resolution against a LinkedIn URL and domain-to-company lookups are simply absent.
The Context key is asked for in onboarding because an admin cannot redeploy
Company brand data and LinkedIn enrichment come from one provider, Context, and one key covers both, which is why the startup line shows two on entries for a single credential. The two are not interchangeable. Brand data returns the logo, the colours, the industry and the real name behind a domain, which is the difference between an account that arrives as itself and one that arrives as a grey square with initials in it. The LinkedIn tool reads a person back from a LinkedIn URL already on their record: real name, current title, employer and every earlier role, and that is what settles who an address belongs to. This key is handled differently from everything else because of who has to set it. It lives in a row, onboarding asks for it, and the General settings page changes it afterwards, since a self-hoster's admin cannot redeploy to edit an environment variable.
The sandbox gets bash, grep and glob, and never gets DATABASE_URL
Turning the sandbox on is what gives the model a shell, and the difference is between a tool caller and something that can keep a dossier, diff this month's profile against last month's, and grep a thread for a signature block. The sandbox has bash, grep, glob and a /workspace. It has no network, because egress is set to deny-all, and that costs nothing in practice: web_fetch runs in the app runtime and web_search runs at the model provider, neither of which the sandbox can reach. The deny-all rule is intended to block direct network egress from the sandbox. It does not establish that other application tools or integrations cannot transmit data; review their permissions and behavior separately. The other half of the same rule is an absence rather than a setting: the sandbox is never given DATABASE_URL, because a shell holding credentials plus egress is shaped like an exfiltration tool even inside an internal project. The practical limit is that the shell cannot query anything, so any work needing records has to go through a tool.
The Agent tab is a signed token, and it needs a shared secret in both processes
Every contact, company and deal carries an Agent tab, and what appears there is the reasoning rather than a summary: the steps as the agent took them, the leads it discarded and why, and its own questions answered in place when it cannot decide between two people. Conversations are durable and survive a reload, and the record travels in a signed token instead of being attached to the front of your message. Turning the feature on means setting AGENT_BRIDGE_SECRET to the same value in both processes. The failure mode is deliberately quiet: without the secret the tab reports that it is not configured, and the agent keeps running its own schedule. Nothing breaks, but the tab stays unavailable until the secret is set.
The env file has no default for who may sign in, and the tests refuse a shared database
Several values in the example env file are traps rather than placeholders. ALLOWED_SIGN_IN is described as the entire authorisation model and it ships empty, so an unconfigured install admits nobody; entries are comma-separated and each is either a whole email domain or a single address, and subdomains count, so acme.com also admits [email protected]. The Google pair must be set as a set, since half a pair is a sign-in button that fails at the provider, and with no Google, no Microsoft and no own identity provider on the SSO settings page the sign-in page says so instead of rendering nothing. The test database is the other sharp edge: TEST_DATABASE_URL must end in _test, the suite refuses to run without it, it will not touch DATABASE_URL, and the pre-push hook runs it because the tests are integration tests that write and delete rows.
openssl rand -base64 32
bun run db:test
The local database the tests and the app share is Postgres 17 on Alpine with a healthcheck on pg_isready.
services:
  postgres:
    image: postgres:17-alpine
    container_name: crm-postgres
    restart: unless-stopped
    environment:
      POSTGRES_USER: postgres
      POSTGRES_PASSWORD: postgres
      POSTGRES_DB: crm
    ports:
      - "5432:5432"
    volumes:
      - crm-postgres:/var/lib/postgresql/data
    healthcheck:
      test: ["CMD-SHELL", "pg_isready -U postgres -d crm"]
      interval: 3s
      timeout: 5s
      retries: 20
The toolchain is pinned just as tightly. package.json requires Node 22 or newer and names bun 1.4.0 in both packageManager and devEngines, with the workspace globs set to apps/* and packages/*. Version 1.16.0 in the manifest matches the v1.16.0 tag dated 22 October 2026, sitting ahead of v1.15.3 and v1.15.2 from August, and the default branch is release, which last took a push on 1 November 2026.
Editorial conclusion
Worth evaluating if you want an agent that keeps working after the browser closes and you are prepared to read its source before trusting it with customer records. Not a fit if you need graded confidence on stored facts, a shipped inference path, or a sandbox that can install its own packages. Before deploying, read the General settings page for the Context key, generate a real BETTER_AUTH_SECRET, set ALLOWED_SIGN_IN deliberately, and confirm which of the optional sources your install actually has.
Frequently asked questions
Is there an open source AI CRM available?
Yes. Comp AI CRM is an open source CRM designed for AI agents, released under the MIT license, where the agent is treated as the component the CRM is built around rather than a chat box attached to a form. The agent runs on its own deployment, on its own schedule, against its own work queue.
Which open-source CRM is available on GitHub?
This repository is one: Comp AI CRM, MIT licensed and written in TypeScript, with its default branch set to release and its homepage at trycrm.ai. Recent tags include v1.16.0 (October 2026), v1.15.3 and v1.15.2 (August 2026).
Does the Comp AI CRM agent need API keys to run?
The project says external research and enrichment sources are optional and that CRM history can still be used without their API keys. The agent still needs a configured model and working infrastructure; the project describes Vercel AI Gateway with OIDC on Vercel. Check authentication for your deployment.
What can the Comp AI CRM agent sandbox reach?
The documented sandbox has bash, grep, glob and a workspace, with deny-all egress and no DATABASE_URL. Web fetch and search are separate tools outside that sandbox boundary. Verify your deployed permissions and network policy; these settings alone do not prove that all data paths are blocked.
How do I control who can sign in to Comp AI CRM?
Set ALLOWED_SIGN_IN in the environment file as a comma-separated list, where each entry is either a whole email domain or a single address, and subdomains count so acme.com also admits [email protected]. It has no default value, because it is the entire authorisation model.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/trycompai-crm)Star history chart for your README
[](https://hysenlabs.com/projects/trycompai-crm)Was this useful?